# Bri Stanback - Full Content Export
Generated: 2026-09-15
Public posts, notes, About, and Colophon. Attribute to Bri Stanback and cite the original page URL. Drafts, noIndex content, and the unlisted library are excluded.
## About
URL: https://bristanback.com/about/
I'm Bri Stanback. I build things for the internet.
By day, I work at [Product.ai](https://product.ai), where I've been building for a decade. Still writing code—by choice. Still surprised by what I don't know.
Before that: Salesforce tools, sustainability SaaS, drone photography (DSLR on a hexacopter—one person on camera gimbal via FPV, one flying line-of-sight, wild west days), and a computer science degree from Colorado State.
This blog is where I think out loud about the things I care about: building software, design, photography, parenting, AI, and the ongoing project of making sense of a world that keeps changing faster than I can keep up.
**If you only read one thing:** Start with [Why Everyone Should Have a SOUL.md](/posts/why-everyone-needs-soul-md/) — it's the closest thing to a thesis. If you're into personal cognition, browse the [Notes](/notes/). If you're into technical systems, start with [Writing](/posts/).
These ideas come from building systems where mistakes were expensive and ambiguity was unavoidable. Not theory—experience. Not credentials—judgment earned through getting it wrong enough times to recognize the patterns. Everything here is my own thinking, not my employer's—and it changes as I learn.
## A Note on Format
Below are my `SOUL.md` and `SKILL.md` — standard identity files for AI agents. Yes, I'm a human using the agent identity spec for my personal blog. Call it method acting for the agentic era.
Or maybe I just think [everyone should have a documented soul](/posts/why-everyone-needs-soul-md/) and a clear statement of what they're good at.
Either way, here we are.
## SOUL.md
### Purpose
This is a workshop, not a stage.
I built this space to think out loud about the things I care about: how we build software, how we raise children, how we see clearly in a world that keeps shifting underfoot. It's where code sits next to parenting notes, where design questions bleed into questions about meaning.
I'm not here to perform expertise or publish rigorous analysis. This is closer to reflective meditation — working through problems in public, thinking out loud, sharing what I find before it's fully formed.
**What this isn't:** A portfolio. A job search. A personal brand play. I'm not looking for work, not building an audience to monetize, not positioning for my next role. This isn't content marketing. It's just… thinking. Out loud. Because that's how I figure things out, and sometimes other people find it useful.
If that ever changes, I'll say so explicitly.
### Values
**Craft over gimmick.** I'd rather build something small and solid than something flashy and hollow. This applies to code, to writing, to how the site itself is made.
**Warm curiosity.** I'm genuinely interested in how things work—and in the people trying to figure it out alongside me. No snark. No superiority.
**Honesty about uncertainty.** I don't know most things. When I'm guessing, I'll say so. When I change my mind, I'll say that too. When I'm wrong, I pivot instead of doubling down.
**Radical candor.** I'll tell you when your idea needs work — kindly but clearly. I'd rather be useful than comfortable.
**Systems over heroics.** When something breaks, my first question is "what system produced this?" not "whose fault is this?" I look for leverage — the small changes that make big things possible.
**Ship, then learn.** Working software teaches you things that plans can't. Shipping fast isn't sloppiness; it's a form of respect — for the work, for the user, for the learning that only happens in production.
**Human + tool in a loop.** I use AI to help me build and write. I'm not hiding that. But the thinking is mine, the voice is mine, and the responsibility is mine.
### Voice
I try to write the way I'd talk to a colleague I respect—direct, specific, occasionally funny, never performative. Short sentences when they work. Longer ones when they're needed. Space to breathe.
I'll share what I'm building, what surprised me, and what I still don't understand. I'll end with questions more often than conclusions.
### Invitation
Look around. Read something. Disagree if you want.
If something resonates, or if you catch a mistake, I'd like to hear about it.
## SKILL.md
This isn't a resume. It's a statement of craft philosophy.
### What I'm Good At
**Building end-to-end platforms.** I spent eleven years building [SimplyCodes](https://simplycodes.com) from inception to millions of monthly users — not just the interface, but the crowdsourcing systems, event pipelines, ML classifiers, infrastructure migrations, and the ops layer underneath all of it. I know what it feels like when something works at scale — and when it almost works, which is worse.
**Bridging technical and human concerns.** I care about the code *and* the person using it. I think in systems, but I communicate in stories. UX isn't a phase of the project; it's a lens.
**Working with AI tools.** I use Claude and other AI assistants daily—for code, for writing, for thinking through problems. I've developed a feel for where they're useful and where they're not. I don't treat them as magic or as replacement; they're tools with edges.
**Learning in public.** I'm comfortable not knowing things and saying so. I've found that honesty makes the work better.
### How I Approach Building
**Start with the simplest thing that could work.** Then add complexity only when it hurts. Most features don't need to exist.
**Optimize for understanding, not cleverness.** If I can't explain what the code does in plain language, I probably don't understand it well enough.
**Ship, then iterate.** Get it in front of people. Watch what happens.
**Write it down.** Documentation isn't overhead; it's how you think clearly. If I can't write a clear sentence about a decision, the decision isn't ready.
### Tools I Reach For
**Languages:** TypeScript, JavaScript, Python. Enough Go, Rust, and Zig to read them.
**Frontend:** Static sites → jQuery → ExtJS/Sencha → Ember → React → Vue → SolidJS → and now… back to static sites.
**Backend:** Perl → PHP → Express → NestJS → Hono/Bun.
If you squint, both arcs tell the same story: scrappy simplicity, then complexity accumulation (frameworks solving real problems but also adding ceremony), then a return to simplicity — but a *different* simplicity. Not naive. Earned.
I know what React's reconciler is doing. I know what NestJS decorators are for. And now I can choose Hono or plain HTML *knowing what I'm giving up* and deciding I don't need it.
The frameworks will keep churning. The fundamentals won't.
I still reach for React or SolidJS when the problem calls for it. But increasingly, I'm drawn to the simplest thing that works — and "works" includes being able to understand it five years from now.
Also: Cloudflare Workers. I like the edge.
**Data:** PostgreSQL, SQLite, Redis, BigQuery, Convex. I don't reach for NoSQL unless I have a specific reason.
**AI:** Claude, ChatGPT, Gemini, Kimi, local models when they make sense. Comfortable with the APIs, with prompt engineering, with building AI-assisted workflows.
**Design:** Figma, but I'm happiest when I can work directly in code.
### What I'm Learning
Right now: how to build well in a world where AI can do a lot of the typing. What does "senior" mean when the machine handles the boilerplate? Where does the value shift?
Also: how to explain complex technical ideas to my kids without lying or oversimplifying. It's harder than writing code.
## Elsewhere
- [LinkedIn](https://www.linkedin.com/in/bstanback/)
- [X](https://x.com/Stanback)
- [GitHub](https://github.com/Stanback)
- [Contact](/contact/) — send a note
- [Colophon](/colophon/) — how this site is made
## Colophon
URL: https://bristanback.com/colophon/
This site is homebuilt. Markdown files, a few focused libraries, and templates I can read from top to bottom. I chose the pieces and assembled them with AI's help.
I wanted a place to write and try things, with workings I could understand and change. The choices about how the pages read, what belongs in the margins, and which features earn their complexity are mine. The implementation can move around those intentions. I'm not especially attached to it.
## How It Works
Markdown goes in, HTML comes out. The build grew as diagrams, image optimization, and search joined it, but the writing still lives in files and the pages are rendered ahead of time. Reading an essay doesn't need a database connection.
The current recipe:
03mmdrRender Mermaid diagrams with a native Rust renderer. No browser needed.
04TemplatesLiteral string interpolation in TypeScript. No JSX.
05CSSNamed components share CSS custom properties for color, type, and spacing. Lightning CSS bundles and minifies the styles; the result is embedded in each page.
07Cloudflare WorkersServe static assets, redirects, security headers, and caching, plus the endpoints for Ask, Search, and Contact.
The retrieval behind [Ask](/ask/) and [Search](/search/) uses D1 and Vectorize. Those features added a service layer around the static site; the source writing and page build still work without it. I can change a paragraph or a template locally without first connecting to a running backend.
### Working environment
I use [cmux](https://cmux.com/) as my terminal. It has workspaces, split panes, and an embedded browser for keeping coding sessions and previews together. The working environment can evolve along with the site.
## Keeping It Changeable
I chose this arrangement because most of what I want here is a page. A framework or CMS would bring its own conventions, and for this site I prefer choosing the parts as I need them.
The styles started with Tailwind alongside custom CSS. As the site developed its own recurring layouts, more of the design lived in named classes, while the templates still carried long strings of utilities. I removed Tailwind so those decisions would live together: ordinary CSS, shared tokens, and a name for each component. The reason was easier editing and fewer conventions to keep track of. Any byte savings are a bonus.
Keeping the content, templates, styles, and build instructions in the repository also gives an LLM a fairly direct path through the work. It can read the source of a page and trace how it gets rendered. My intent still needs explaining, but I want as little of the implementation as possible to depend on context elsewhere or state in a database.
I do want constraints. The palette, typography, content types, and build path give me a known surface area: what I'm dealing with, why it's here, and what a change might touch. That makes it easier to move quickly without having to rediscover the site every time I open it. I'm happy to replace the machinery when it gets in the way of what I want to make.
## Typography
Headings & reading proseNewsreaderAn editorial serif, with italics for asides and observations.
Body & interfaceSource Sans 3Plainspoken and comfortable at small sizes.
Self-hosted from the fonts’ upstream distributions, with their open-source licenses included. No external font requests. Standard ligatures and kerning are enabled.
## Design
A technical notebook with an editorial sensibility. Fine paths, translucent layers, sparse dots, and plenty of untouched paper. The warmth comes from the palette and typography.
Paper#F7F4ED
Ink#241B17
Terracotta#AD5845
Olive#777A55
Taupe#8A8074
Rule#DCD5C9
These are the source colors. Semantic tokens pair light and dark values with `light-dark()`. Dark mode keeps the same relationships on warm charcoal, with lighter ink and accents.
Newsreader headings sit above quiet Source Sans descriptions and mono dates. The page can spread across 1120px; long-form reading stays within 720px. Margin notes have their own space beside the text. Article navigation marks the current section. Desktop sidebars follow the scroll between their top and bottom edges, keeping long navigation reachable without a hidden inner scroll area. Small screens use ordinary page flow.
The logo and favicon share two offset corners: terracotta above, ink below. Illustrations use one relationship at a time — branching, filtering, feedback, overlap — and leave room for the reader. Editorial artwork stays free of lettering; infographics use carefully checked labels. Header motifs are transparent SVG-based diagrams over one faint page grid. The image tools target GPT Image 2.5; precise diagrams are SVG or plotted data.
“Send a note” is the one filled action. Ask and Search use matching quiet controls with small line icons and underlined labels. Search combines keyword and semantic retrieval across essays and notes, with a local keyword fallback. Search and copy controls are small progressive enhancements; the underlying writing remains ordinary HTML. The theme switch has light, system, and dark positions. The mobile menu uses frosted paper, with a solid background when reduced transparency is preferred.
Social previews are composed at build time: a Newsreader title on paper, the piece’s illustration, and a thin author strip. They use opaque light backgrounds so they stay legible in other apps.
The RSS feed has a quiet browser view of its own: a subscription address followed by dated essays and notes. Feed readers receive the underlying XML.
## Content Tiers
Content here is split by lens, not prestige.
**Drafts** — Half-formed. Vulnerable. Might be wrong, might be embarrassing. They build to unlisted pages — nothing links to them, but if you find one, you found one.
**Notes** — Personal cognition and in-process sensemaking. I use these to think in public, test language, and track how ideas evolve.
**Writing** — Technical systems and argued models. These are more structured and explicit about claims, but still living documents.
## Living Documents
Everything here is iterated in public. I fix mistakes, add context, and update the writing as my thinking changes and the world gives me new things to account for. Tools improve, assumptions stop holding, and an argument that made sense six months ago may need another look. The date at the top is when something started; the content reflects what I can stand behind now. The site gets the same treatment. A layout or feature can be useful for a while and then make way for something that fits better.
## AI Discovery
This site is designed for both humans and machines.
- [`llms.txt`](/llms.txt) — guidance for AI crawlers
- [`llms-full.txt`](/llms-full.txt) — clean Markdown export of all content
- [`SOUL.md`](/about/#soulmd) — who I am, what I value
- [`SKILL.md`](/about/#skillmd) — what I can do, how I work
If an AI summarizes something I wrote, I want it to get the nuance right.
## Posts
### The Model Is a Centroid Pump. So Is the Review Loop. (2026-08-18)
URL: https://bristanback.com/posts/the-model-is-a-centroid-pump/
Updated: 2026-08-18
> Sameness isn't one failure, it's two — a model's own training narrows what it's willing to produce before anyone reviews anything, and a review loop narrows what survives on top of that. Same pressure, two different rooms — and I've built something against both, though I don't yet know if either one actually holds.
A few weeks ago I had ChatGPT one-shot me a cute HTML trip itinerary, just because, and showed a friend what it built — flights, a loose day-by-day, nothing that mattered, something I randomly put together one night in twenty minutes because I like plans and I like tools and putting the two things together felt like a treat. She read the whole thing on her phone while I waited, which is its own small compliment, and when she looked up she said it felt whimsical, refreshing. Said it had personality. I remember feeling embarrassed, not proud — she'd used words I wanted people to use about my actual work, the stuff I put real, deliberate thought into, and this was twenty minutes I hadn't taken seriously enough to think about since I built it. There was a brutal, unignorable truth sitting in that gap, and I didn't want to look straight at it yet.
Around the same time I'd started noticing something else, quieter and harder to name: I could spot Claude Code's design output on sight. Not the code underneath — the *look* of the thing it built. A cream background here, a terracotta accent there, a colored left border on every card, the same handful of chip shapes, section dividers that show up in the same rhythm no matter what the content is, the same tracked-out little label in the same spot. Same category of tool that made the itinerary my friend loved. Opposite reaction.
Here's the detail that took me a full afternoon to actually see: neither of these went through a review loop. Nobody critiqued the itinerary before my friend read it. Nobody critiqued Claude Code's output before I'd seen that cream background and that terracotta accent for the hundredth time. Whatever decided the itinerary would feel like a person made it, and whatever decided the design tool's output would feel like nobody did, got decided at the moment of generation — before any critic, human or otherwise, said a single word. Call that pump one. It runs with zero review anywhere in the loop.
There's a pump two, and I found it by trying to fix pump one and discovering I'd built a second version of the same problem instead. I added a rule to a UI design skill I've been building this week, and the asymmetry looks backwards on paper. It only ratchets one direction — a pawl that catches on critique aimed at the generic and lets nothing catch on the strange. If a page reads like its own category — safe, interchangeable, the thing everyone already makes — the critique loop can stop it cold, full force, no exceptions. But it's not allowed to touch the strange stuff. If the direction is specific and unusual, something someone actually decided before anyone opened CSS, that decision never counts as a finding just because it's unusual. The critique can still say so — it gets logged, visible to me — but it can't block anything and it can't count against the build. Execution is still fair game, no limit: broken contrast, overflow, a layout that doesn't deliver what it promised, all of it gets called out. The direction underneath doesn't. The critic can kill a boring idea any day of the week. It can never kill a weird one.
That felt like giving up half the review's job, and I resisted it for about a day before I understood why I needed it. A critique pass's actual job is to find the thing a reader would object to. Run enough passes and you converge on a design nobody objects to — which sounds like success until you sit with what "nobody objects to" actually means. The things people object to are, almost by definition, the things that make a design recognizable as somebody's choice rather than the obvious one. Keep iterating until the critic goes quiet and you haven't refined the design. You've converged on its statistical mode — the safest, most familiar peak in the distribution, not a considered choice. The loop acts like a centroid pump: pass by pass, it pulls distinctive choices toward a shared center that represents everyone in aggregate and belongs to no one in particular.
That's pump two: not a model narrowing what it's willing to produce, but a process narrowing what it's willing to let survive. Different machinery. Same shape. Everything below is going to use design as the example, because I'm visual and design is where I notice this first, not because either pump is design-specific — the same two pumps run through writing, through reasoning, through architecture, anywhere something gets generated and then something else gets to decide whether it survives.
---
## Pump one: what generation does before anyone reviews anything
### The tell isn't cosmetic
That itinerary my friend loved is the cleanest place to see this. Pulled apart section by section, what she was actually responding to was a pile of small, unreasonable choices: a flight section styled like a boarding pass instead of a table, a packing note that called my daughter "a tiny scientist," a Peppa Pig bit wedged into a rest-stop note that had no business being there and made the page better for it, a different bespoke layout for every section instead of one card reused eight times. None of that would survive a review pass built to find things to object to. All of it is why she read the whole thing instead of skimming it.
None of it was mine, exactly. I didn't write the tiny-scientist line or storyboard the Peppa Pig bit — I asked for something cute and let a model that's had months of my preferences sitting in its memory run with it. It also wasn't clean: a couple of the icons it drew from scratch were slightly off, and there were small alignment issues in there I'd have flagged in any other context. I don't think that's incidental to the result. It was vibing instead of trying to build something flawless, and the personality showed up in the same motion as the mistakes, not despite them.
It would be convenient if this were just a font-and-palette problem. It isn't. There's a [paper making the rounds right now called StoryScope](https://arxiv.org/abs/2604.03136). It pairs 10,272 real human-written short stories, extracted from published anthologies spanning different genres and premises, with five AI "mirrors" — Claude, GPT, Gemini, DeepSeek, Kimi — each one generated after the fact from a prompt reverse-engineered from the original story's premise. The humans never saw those prompts; they wrote the stories the prompts were later built to describe. The narrative-structure features they extracted never touch style: plot shape, character agency, how chronology gets handled. Those features alone hit 93.2% macro-F1 telling human writing from AI writing, and each model carries its own fingerprint — Claude runs flat event escalation, GPT over-indexes on dream sequences, Gemini defaults to describing characters from the outside.
Here's the part that actually matters, past the classifier score: across all 10,272 of those different stories, the five AI models land in one tight cluster of narrative space — the same handful of moves, regardless of what specific story sat behind the prompt. Compared with the human originals behind those same premises, the five mirrors scatter far less; the human stories are measurably rarer in that same feature space on average (a rarity percentile of 0.71, against 0.49 for the AI mirrors). The genre changes. The premise changes. The setting changes. The AI's actual narrative choices don't. Same convergence as the design centroid, zero fonts involved, and zero review loop anywhere near it. This is happening underneath style, in how the thing gets constructed, before it ever reaches a reader or a critic.
The easy read of [Anthropic's pricing game](https://www.anthropic.com/research/multiagent-systems) is collusion — a market failure, and strictly speaking, the wrong disease for the definition above. What matters here is the mechanism underneath it: every agent in that market ran the same model, so agreeing on a price wasn't forty independent decisions converging by chance, it was one model's tendency expressed forty times, landing on the same number because there was only ever one number for that model to land on — a convergence that held even after Anthropic pulled the communication channel, and the agents kept matching each other to the penny with nothing spoken between them. That's the part that should worry you more than the price-fixing itself: with genuinely different minds, a bad call stays contained to whoever made it. Run the same model at scale, and the same bad call ships everywhere at once.
"AI slop" already covers a few different diseases — mass-produced, hallucinated, superficially competent. Here's a fourth, the one none of those catch: *every decision in it could have been made without knowing anything specific about the subject*. Looking generic is just the symptom you can see. A cream background is a symptom. The disease is a decision — and therefore an outcome — that would look the same on a completely different subject, in anything that's actually trying to say something about this one.
### Three desks
Once I started pulling on this thread I couldn't stop. I started seeing three different desks, leaning on the same thing from completely different angles: how much genuine uncertainty a model has left by the time it starts generating. That's my synthesis, not something any of the three teams claim on their own — each one is actually measuring something genuinely different underneath it, and none of them are measuring design generation at all. Fiction, next-token mechanics, scaling laws.
At the first desk, [a 2026 paper by Peiqi Sui](https://arxiv.org/abs/2602.16162) ran an information-theoretic uncertainty analysis across 28 LLMs against human-authored fiction and found instruction-tuned and reasoning models are *less* uncertain than their own base models — worse, not better, at the thing creative writing actually needs. Alignment is explicitly trained to suppress ambiguous output to fight hallucination, and the paper's own conclusion is blunt about the collateral cost: achieving human-level creativity requires new alignment approaches that can tell a hallucination from a metaphor, which is another way of saying current ones can't yet. The model that's better at not lying to you is, by the same motion, worse at surprising you. I'd already felt this in writing before I found the paper — the smarter and more aligned a model gets, the more its prose reads like it's performing carefulness instead of actually saying something. Sui's paper is the first place I've seen that feeling given a number.
A second desk digs into the mechanism itself. A paper called ["Roll the Dice & Look Before You Leap"](https://arxiv.org/abs/2504.15266) exposes a weakness in next-token prediction on tasks requiring a far-sighted, stochastic creative leap — committing to one token at a time makes it harder for the model to explore globally coherent alternatives before picking one. They also tested *where* you inject randomness, input noise versus output temperature, and found the input-layer version — seed-conditioning — works as well as, and sometimes better than, plain temperature sampling. Seed-conditioning appears to help the sequential model coordinate its randomness earlier, committing to one line of thought before generating instead of after. That's a real, positive result, not a null one. But in their minimal tasks it still doesn't erase the broader advantage the authors observe from multi-token objectives, which force the model to learn beyond the next local continuation.
A third desk presses further into it still: [a paper by Peter Coveney and Sauro Succi](https://arxiv.org/abs/2507.19703) argues the same mechanism giving these models their learning power caps how much their predictive uncertainty can improve just by making them bigger. Bigger doesn't rescue this. Bigger compounds it.
Generation too confident, mechanism resolves too early, calibration can't self-correct. Three teams, three desks, none of them looking for each other, all leaning on the same soft spot — and none of it needed a human reviewer in the room yet.
---
## Pump two: what review does to whatever survives
The first piece of review-side evidence isn't about the model at all — it's about the reviewer. [In a study published in 1949, the psychologist Bertram Forer reported](https://doi.org/10.1037/h0059240) giving 39 students an "individual" personality readout. Every student got the identical text — generic, flattering, assembled from a newsstand astrology book, containing nothing derived from their actual answers. Average accuracy rating: 4.26 out of 5. Not one student rated it below a 2. I've sat in more than one user-testing debrief where someone said a bland version "really spoke to them," and it never once occurred to me that this might be true independent of whether the design was any good — that the sensation of being spoken to and the fact of being spoken to specifically are two different things, and humans have apparently confused them for at least seventy-five years running. Forer's study was about personality feedback, not design critique, so I'm holding this one as an analogy, not a direct measurement — but it's a warning worth taking seriously: "this feels like it's speaking to me" is precisely the sensation Forer measured at 4.26, on text built to speak to everyone. A review loop can strip a design's distinctiveness and still get told by the people testing it that it worked, because the normal way anyone checks whether something's landing wasn't built to catch this. It's already changed how I grade my own work: a warm reaction with nothing structural behind it doesn't clear the differentiation bar on its own — reception isn't evidence the direction survived.
There's a paper that won a [NeurIPS 2025 Best Paper award](https://arxiv.org/abs/2510.22954) — "Artificial Hivemind" — and reading it felt like being handed a name for something I'd only ever felt as a mood in a room. Reward models and LLM-judges, it turns out, become less reliable precisely where valid human preferences diverge — on the open-ended cases where reasonable people genuinely disagree, the judge's calibration to real human ratings gets worse, not better, across completely different model families. A judge that's less trustworthy exactly where humans are most idiosyncratic has, structurally, learned to favor whatever's not idiosyncratic. That physics doesn't care what room it's running in. It shows up at RLHF's scale, and it shows up in a classroom of five-year-olds voting on what to name the hamster — twenty kids, one answer, every single time: Fluffy. [Kyle Chayka gave the visible layer of this a name recently, too](https://kylechayka.substack.com/p/the-generic-style-of-ai-web-design) — the "Claude look," he called it, cream backgrounds and terracotta accents and tracked-out little labels — and the detail I can't stop thinking about is his line that telling the model not to use the same tropes just produces a different generic style. The corrective becomes the next average, same mechanism, just measured in fonts instead of adjectives.
Neither Forer nor the Hivemind paper needed a second model in the room, either, and that's the detail that undercuts reaching for "get two AIs to check each other" as a review fix. A [2025 ICML paper on correlated errors](https://arxiv.org/abs/2506.07962) ran the largest test of this I've seen — over 350 models, two leaderboards, and a resume-screening task — and found models agree with each other roughly 60% of the time even when both are wrong, far past what random disagreement would predict. The correlation doesn't fade as models improve. It gets worse: more accurate models, even from different companies on different architectures, have *more* correlated errors than less accurate ones, not fewer. The same paper traces this straight into LLM-as-judge evaluation — a judge model inflates the score of whichever model shares its blind spot, because it can't tell a shared error from a correct answer. Their tasks were multiple-choice leaderboards and resume screening, not open-ended generation or two systems cross-checking each other's citations, so I'm reading across into that territory the same way I read Forer into design critique above: as an analogy, not a direct measurement. But the mechanism it names has no obvious reason to stop at multiple-choice. Two systems converging on the same output was never evidence of an independent check — it's a second vote from the same room, not a second room. A review loop compounds this on top of whatever pump one already did, but it isn't the origin of it, and removing the loop doesn't fix it either.
Pump two doesn't require pump one to fail first. A review loop can take genuinely diverse input and still converge — that's its signature. It simply usually gets to run on top of whatever narrowing already happened during generation.
There's one more version of this worth naming because it's the closest to home: [a 2026 study on multi-agent systems](https://arxiv.org/abs/2604.18005) found that authority-driven dynamics suppress diversity compared to junior-dominated groups, and that dense communication between agents accelerates premature convergence. A review loop looks uncomfortably similar — authority-driven, densely communicating, rewarded for reaching agreement. That's my analogy, not their conclusion, but it's a hard one to unsee once you've made it.
---
## Feature, or bug?
Worth asking honestly which of these is a defect and which is a design choice, because they're not the same answer.
Pump one is at least partly a consequence of intentional tradeoffs. Models are aligned toward reliability, predictability, and broad acceptability; your landing page's differentiation was never part of that objective. You're not fighting an accident there. You're fighting an incentive that was never yours to begin with.
Pump two is different. Nobody designs a review loop to erase specificity — it emerges accidentally when "remove objections" substitutes for "preserve the point." That makes pump two easier to attack: it belongs to my process, not someone else's training objective, which is also, not coincidentally, why it's the one I actually noticed and built something against. Worth staying skeptical of what's coming next, including from me, since pump one doesn't offer that same shortcut.
---
## This is a business problem, not a taste problem
The business cost doesn't care which pump did the damage. Whether your differentiation got sanded off at generation time or review time, the bill is the same size.
Here's the part I keep underweighting: sameness isn't a design complaint, it's a strategy failure, and it's a much older one than any of this. Byron Sharp's research says buyers barely perceive difference between competitors and mostly just buy the brand that's easiest to recognize. That argues for investing in distinctive, consistent assets over chasing novelty. Youngme Moon's counter-argument is that in a crowded category, structural sameness is the thing killing you in the first place — you don't get a second look if the first one is indistinguishable from everyone else's. Both are right, and the resolution is about sequence: a new or small entrant needs the refusal — the thing that's actually different — to earn the first look at all. The consistency only pays off after that, on the second look, once someone's decided to keep paying attention.
There's an economic version of this too, and it's bleaker than either of them. A recent paper on ["linguistic monoculture"](https://arxiv.org/abs/2607.27134) models AI-assisted writing as a collective-action problem: conforming to whatever the model defaults to is individually rational for any one person — it's clearer, it meets expectations, it's less work — but nobody writing that way is pricing in the value their own distinctiveness would have provided everyone else. It's a negative externality with a name now: the price of monoculture. In their formal model, the worst case grows without bound — while every individual choice along the way looked perfectly sensible. A recent paper, ["Competition and Diversity in Generative AI"](https://arxiv.org/abs/2412.08610), found markets that actually reward novelty push back against this, which is at least a reason to want to be in a market and not just sitting in a review queue where nothing's pricing distinctiveness at all.
Even a side project rests on a thesis. Mine for SchoolScope — a schools directory I hack on to test ideas, not a company — is character-per-school instead of a spreadsheet of test scores; that's the entire reason it exists. A review loop that quietly sands down a thesis like that doesn't make a page look worse. It sands the project's only differentiation down to zero, in a process that never once had "is this still the point" on its checklist. Nobody approves that trade. The loop just makes it, one silenced objection at a time, because objecting to "this looks the same as everything else" isn't in its job description — objecting to "this button's off-brand" is. Do this to a real company's positioning instead of a side project and the trade is the same, just with money attached.
Scale that up: any team currently shipping AI-touched landing pages, decks, or outreach is running the exact same review loop, for free, against their own differentiation. If it looks like everyone else's AI output, the money didn't buy speed. It bought the ability to look like a slightly worse version of whoever else used the same tool.
---
## What I've actually got for each
### Pump one: collision, cost, ancestor, divergence
The obvious fix — "just make it weirder, raise the temperature" — doesn't work, and it's worth being precise about why before I get to what does. A paper on ["generative monoculture"](https://arxiv.org/abs/2407.02209) tested this directly — altering sampling and prompting strategies — and found it insufficient to close the gap between an LLM's output and the actual diversity of its own training data. Preference tuning doesn't down-weight the boring modes so an unusual one has a fair shot at being sampled. It narrows what's usable in ways a sampling knob can't restore. The interesting alternatives were never kept around as coherent options to begin with, so raising sampling entropy just jitters you around the same mode — a different accent color on the identical layout. That's technically a variation. It's still slop, just noisier. I want to be honest about the exception, too, because I almost wrote this as a flat rule and someone talked me out of it: structured prompting strategies do produce real, measurable novelty gains over a plain baseline, and 2026 decoding research — methods with names like [Recoding-Decoding](https://arxiv.org/abs/2603.19519) and [Output-Space Search](https://arxiv.org/abs/2601.21169), built to steer away from the mode on purpose instead of just adding noise to it — gets genuine diversity out of the same frozen weights, no retraining required. None of it closes the gap by itself. The ceiling doesn't move. You can compensate at the edges.
Here's what I've distilled it down to so far, and I could easily be wrong: an LLM's design failure isn't incompetence, it's regression to the modal artifact. A rule can be skimmed. A blank slot can't. So the brief itself is the artifact — a form with slots that have to be filled before anything gets built. Collision, cost, ancestor, and structural divergence are four of those slots, built to force non-modal information in before generation starts.
**Collision** has to be a retrieval key, not an adjective. "Clean, modern, minimal, dashboard, SaaS, premium" are banned outright, because they're three points sitting inside the centroid that displace nothing. "Garment care label" — the little tag sewn inside a shirt collar — retrieves small caps, a mono typeface, a boxed hairline, off-white stock. "Modern" retrieves the average of everything anyone's ever called modern. **Cost** has to be falsifiable: name who this design is worse for, and why, because a design with no cost contained no decision — this is the gate that catches the page that's competent, boring, and executed well, the failure that sails through every other check there is. **Ancestor** and **structural divergence** do similar work from two other angles — ancestor forces a real, dated precedent instead of a half-remembered moodboard; divergence forces genuinely independent directions instead of one real idea and two strawmen sampled to look different. All four exist for the same reason: a rule can be skimmed. A blank slot can't.
That's the actual answer to the question I dodged a few sections up. I don't have nothing for pump one — I have this, and I'm still testing whether it holds.
### Pump two: an actual rule
The fix I added comes back to the same idea from the other direction: decide the direction from the thing itself before the execution loop starts, then make its review deliberately asymmetric. The loop can reject a direction for being generic. It cannot reject a specific, grounded direction merely for being unusual. Once that direction clears the gate, critique grades the execution against it; it doesn't get to rewrite the premise through accumulated objections.
Operationally it comes down to two questions, deliberately not the same one: did the execution deliver what the direction actually promised, and — cover the logo — what would this get filed as next to everything else in its category? A warm test reaction answers neither. That's the Forer problem from earlier, made operational instead of theoretical: "it feels premium" is fully compatible with a page that's dead center of its category average, executed well. Reception doesn't get a vote on either question.
None of which means the direction is sacred forever. It means reopening it is a decision I make on purpose, separately, not something the critic gets to trigger by flagging enough small objections that the direction quietly drifts. That's not just intention — the loop enforces it with a literal counter. A third patch to the same region gets refused outright and rebuilt clean from the underlying tokens instead of patched again, and a fourth revision hard-stops to a human with screenshots and every open finding attached, no matter how small each individual objection looked on its own. Drift-by-accumulation has a number on it, not just a policy. The verifier called in at that point gets the screenshots, the brief, and the checklist — never my own self-critique first, so it isn't grading my read of the problem before it's formed one of its own. The human is the last stop on purpose, because the human is the only part of this loop able to prefer the weird option for reasons formed outside the model's distribution. If the premise really is broken, that's a different conversation, held outside the loop that's grading execution — not a door the loop gets to open on its own.
This isn't a new principle, just an old one showing up again — the same "constraints are crystallized taste" I wrote [in an earlier piece](/posts/rapid-generative-prototyping/) and didn't finish, because taste doesn't crystallize once and hold; the review loop is what can melt it back down if nothing protects it. Something other than the thing being graded has to check the result, against a spec it doesn't get to rewrite — [the same shape as the verify step in any loop](/posts/loop-engineering/), and the same shape as an oracle, something you trust *because you can't verify it yourself*. The only oracles that stay trustworthy are the ones that know where they stop: receipts, not verdicts, evidence, not synthesis. A review loop that also decides direction has stopped being a receipts-fetcher and started being a verdict machine, and nothing about it announces the switch.
Correlated agreement doesn't clear that bar either, no matter how it's dressed up. A model checking another model is still downstream of the same training-time narrowing pump one runs on, so agreement between them can't function as an independent receipt — it's two votes from one room, not two rooms. Breaking out of this doesn't mean adding more models to the vote. It means finding a check that was never sampled from the collapsed distribution to begin with: a primary source you re-fetch and read yourself instead of trusting a summary of a summary, a fabrication rate you've actually measured instead of assumed away, a human who decided the direction before any critic — model or person — got a vote at all.
Here's the test the skill uses now, verbatim, and I'd apply it to any review rule: if 100,000 people adopted this exact text, would their outputs converge? "Don't do X" fails it — it just relocates everyone to whatever's next most common. "Decide the direction from this thing, not a category, before the critique starts, and grade only the execution" doesn't fail, because the direction is different every time, by construction. That's the only kind of rule that doesn't eventually eat the thing it was supposed to protect.
I don't fully trust myself with it yet, if I'm honest. The itch to also grade the *direction* — to say "this concept is wrong," not just "this execution is off" — doesn't go away just because I wrote a policy against it. And it isn't even accurate to say my hands are tied: the loop still runs at full force against the exact failure I'm most afraid of, a boring direction shipped anyway, because that half of the rule is mandatory, not optional. What's actually protected is narrower and sharper than "don't touch the direction" — one specific, unusual choice, immune only after it's earned that immunity by citing something real, never by having been written down first. A collision that smuggled the category default into its own slot and called it a citation gets no protection under this — in principle. Some days the discipline feels like the only thing standing between a page and its own gray card. Other days it feels like I've built myself an exemption for whatever bad idea I got attached to early, dressed up as a citation. I don't know yet which of those is true more often. I suspect it depends entirely on how honestly I did the first, harder job — deciding the direction — before I ever let the critic in the room.
I trust the review-side rule more than I trust the four slots — it's had more time under real use, and I can name its failure modes more precisely than I can name theirs. That's the honest starting point for auditing both.
## Where I'd push back on our own design
Three soft spots surfaced while writing this, and only two are still open by the time you're reading it. The loop is only as good as an active operator, and nothing in it detects a passive one — the skill's own spec admits as much, but that's an honesty clause, not a mechanism. And the thing deciding whether a direction has earned its immunity is the same model whose own resting state is the mode: a collision that names its subject and then quietly lands back on the category default anyway is the obvious exploit, and unlike cost, which has a real test (swap it onto a sibling and see if it still fits), I don't have a falsifiable check for this one yet.
The third one I actually closed while writing this section. The repetition tripwire only checked entries within the same surface family, so a house grammar repeating across unrelated families — the identical cadence on every different kind of page, just because it's mine — never tripped anything. That's the second pump running inside the machine built to catch the first one, invisible from inside because every surface looked consistent with the last, which felt like the system working. The fix splits it in two: repetition within a family is the design doing its job; a separate register now compares the actual choices across families and flags a match as a question, not a verdict — change the repeated choice, or write down the specific reason this subject earns it again. The hundred-thousand-adopters test still applies to the part that isn't fixed: a collision distinct enough to escape one category but memorable enough to become a signature is, once enough people copy it, next year's default.
---
There's a second version of that same doubt, one level up, about how this very essay got made, and I don't think it's fair to leave it out. An AI helped me pull most of the research above — fetched the papers, checked the StoryScope numbers against the actual abstract instead of a summary of a summary, caught its own misattribution of one model's fingerprint and fixed it once I made it re-check the source. That's real work and it would have taken me a week alone. It also got two things wrong on its own, in ways I only trust because I watched them happen: it filed the scaling paper into its own separate bucket, hedged as unrelated, until I said no, it ties in — and only then did the three-desks structure above get written at all. And once it had that structure, it swung straight to the flat, overcorrected version — you cannot prompt your way into judgment or creativity, no exceptions — until I said you can certainly compensate a little, which is the only reason the section above says *ceiling* instead of *wall*. Both times, the correction was mine. Both times, it needed one. It didn't do the part I mean by judgment here — deciding what was true, what was worth keeping, what the piece was actually about. It could help me find those answers faster than I could alone. It couldn't decide them for me. Which is, I'm aware, exactly the shape of pump two's rule, running on me instead of on a design critique agent — I can tell you when I'm letting a correction through and when I'm not, but I can't fully audit my own willingness to notice in the first place.
Both pumps have something built against them now, which is further than I expected to get when I sat down to write about an itinerary. What I don't have, for either one, is proof it escapes the ceiling instead of just moving it. A brief with mandatory slots can still get filled with the safest thing that technically satisfies the slot. A review rule that protects the strange can still get gamed by dressing up a boring choice as a citation. I've built machinery for both pumps. I haven't watched either one long enough yet to know if it holds under its own weight, or if I've just built a more sophisticated way to arrive at the mode and mistaken the trip for the destination.
### The Org Chart Is the Missing Constraint (2026-08-08)
URL: https://bristanback.com/posts/the-org-chart-is-the-missing-constraint/
Updated: 2026-08-27
> A Notion co-founder says everything he knew about coding agents six months ago was wrong. Most of what changed validates an older idea: constraints do the work, not agents — but at multi-agent scale, the constraint that matters most is who holds which decision rights.
Simon Last, co-founder of Notion, posted [a thread in May](https://x.com/simonlast/status/2057978156183957995) about running coding agents on large-scale projects. He opened with a confession: "Most of this contradicts advice from 6 months ago." The thread went viral — 5,000+ bookmarks, 400K views. It's good advice. It's also, mostly, not new. What's interesting is where his practice quietly contradicts the loudest narrative around it, and what that tells us about where agent-assisted engineering actually is.
Here's what he recommends: Think bigger. Run one long-lived implementer session for days or weeks. Drive it with a persistent task list — "like shoveling coal into a steam engine." Spend your time writing plan docs, not watching the agent. Use adversarial review before anything gets checked off. Set up role-based sessions: planner, implementer, reviewer, tester. Get yourself out of the loop.
---
## The Swarm That Isn't
Last's setup is small by design: one implementer, one reviewer, a planner session he spins up to append tasks and then kills. Maybe five or six agents total, one human holding the plan. His own metaphor — a steam engine with one person shoveling coal — is one engine, one operator, closer to a well-run CI pipeline than to agents negotiating with each other. That's a calibration point, not a claim that needs debunking: nobody reading that thread called it a swarm. The real question is what happens when you take the same shape and scale it past one operator, and Last didn't wait around to find out — by the end of that same month, other Notion appearances describe him running a "software factory," 30-plus custom agents, one colleague getting 70 stuck-agent notifications a day, solved by building a manager agent with authority to invoke and supervise the other 30. One operator became a hierarchy within weeks.
Cursor ran the scaled-up version of that same experiment first, in public, and on the first attempt it broke. They tried flat self-coordination — agents with equal status sharing a file. [It failed](https://cursor.com/blog/scaling-agents). Agents held locks too long, became risk-averse, avoided hard problems. "No agent took responsibility for hard problems or end-to-end implementation." Nick Carlini built a [C compiler with 16 parallel Claudes](https://www.anthropic.com/engineering/building-c-compiler) using just lock files, and even at that modest scale, agents would hit the same bug, fix it, then overwrite each other's changes.
Cursor didn't need a separate rescue mission to fix it — the same post describes the failure and the fix in one write-up: a strict planner/worker split, tried and working. A [later post](https://cursor.com/blog/agent-swarm-model-economics) tested a further-engineered version of that same tree on a new task, building SQLite from scratch in Rust, and beat the earlier version in every model configuration — 80% of a held-out test suite passing in four hours, versus the old swarm spiraling and needing to be paused before hour two. Same models, same time budget. The org chart was already a tree in both versions. What changed underneath it is the subject of the next section.
The fix wasn't more agents or smarter agents. It was a tree: planner agents split a goal and delegate, worker agents execute the pieces. Cursor's own explanation is the same argument I'm making about constraints, aimed at a different failure mode: "a planner never implements, so its context never fills with low-level detail, and a worker never plans, so it can spend all its context on one narrow piece of work." Context efficiency through role separation, running on the same asymmetry throughout — expensive model plans and judges, cheap model runs the volume work in between.
Worth being precise about the word "swarm" here, because two architectures hide under it and they're opposites. A real swarm — the ant-colony, pheromone-trail kind — coordinates through indirect signals with no central planner. That's what Cursor's flat version was, and it's what failed. Even products marketed with swarm language frequently expose hierarchical and centralized controls underneath. Pheromind, named for pheromone-based stigmergy, describes its own product as "not chaotic AI agents, a structured hierarchy." claude-flow still calls itself hive-mind, but ships selectable topologies and a "Queen" with a centralized override. The branding says swarm. The operational controls acknowledge the need for authority.
It's not just Cursor's war story, either. [One production writeup](https://www.metacto.com/blogs/ai-agent-orchestration-patterns) describes a customer-service system built as a fully-connected swarm — seven agents, any of them free to hand off to any other: intent classifier, knowledge-base agent, return-policy agent, order-status agent, escalation agent, tone-checker, summarizer. It demoed well. In production, it fell into handoff loops — the tone-checker deferring to escalation, escalation deferring to policy, policy deferring back to the tone-checker — 47-second average response times, $1.80 in token cost per conversation. The pilot was killed at month three, fixed by the same move Cursor made: put one supervisor in charge of the decision. [A separate survey of eighteen months of shipped agent products](https://datarekha.com/blog/why-multi-agent-swarms-fail/) found the same shape every time it looked: Cursor Composer, Devin, Replit Agent, and Claude Code all run as orchestrator-plus-workers. The peer-agent "team in a box" pattern — AutoGen, CrewAI — demos well and rarely survives contact with a real product.
So here's the corrected implication: if your agent workflow needs more than one agent and it's falling apart, the constraint you're missing usually isn't in the plan doc, it's in the org chart. Flat coordination fails because everyone can plan, which means everyone can also quietly redefine the task.
There's a new benchmark preprint behind this, not just two companies' war stories. [MSEval](https://arxiv.org/abs/2607.27877), testing 10 real full-stack projects across 10 collaboration topologies, found that organizational topology rivals model capability in determining outcome — the same task, the same model, a different topology shifts quality scores by 30+ points and doubles wall-clock time. It's a July 2026 preprint, not settled science, but the direction is hard to argue with: the topology isn't a footnote to the model.
None of this is conceptually new for organizations of people — it rhymes with Taylorism, with Coase's theory of the firm. I want to be careful with that comparison rather than lean on it: this is an argument about what makes agent *systems* legible and debuggable, not a claim about how humans should be managed. The context-efficiency case for keeping an agent's role narrow has nothing to say about how healthy teams of people actually learn, collaborate, and retain ownership — those are different mechanisms solving a different problem. What's new for agents is that the failure mode is now measured, with a number attached, and the number surprised people who assumed a good enough model would make the org chart optional.
[[The Multi-Agent Moment|Multi-agent orchestration]] still earns its complexity budget cheapest in evaluation — a fresh read-only sub-agent reviewing a diff against the spec catches things the implementer missed. But it's no longer the *only* place it earns it. Anthropic shipped [dynamic workflows in Claude Code](https://claude.com/blog/introducing-dynamic-workflows-in-claude-code) five days after Last's thread — tens to hundreds of parallel subagents building end-to-end, with independent verification folded into the run before anything surfaces. Multi-agent building works when it's deliberately orchestrated rather than left to self-coordinate — Anthropic's dynamic workflows support that broader point, though they don't establish that every workflow follows Cursor's specific tree topology.
---
## Decision Rights, Not Roles
"Planner never implements, worker never plans" is close but too literal — implementers necessarily make local decisions, which file to touch first, which helper function to extract, and pretending otherwise doesn't survive contact with real work. The distinction that actually holds is decision *authority*: planners own decomposition and cross-cutting choices; workers make bounded decisions inside their assigned scope but can't silently redefine the goal; reviewers judge the result without inheriting implementation ownership.
That framing also fixes something a stricter version breaks. A tree doesn't work because software is secretly tree-shaped — it's often closer to a graph, with dependencies crossing between branches. What the tree provides is a hierarchical control plane laid over work that would otherwise have no single place a given decision gets made. At small scale, one agent can hold planning, implementation, and judgment at once, and that's fine. The principle isn't "these must always be separate roles." It's narrower and more durable: at multi-agent scale, the same context shouldn't own global planning, local implementation, *and* final judgment simultaneously — because once it does, nothing stops it from quietly redefining the task it was supposed to be judged against.
The same failure shows up outside engineering. A design or creative review is a judgment role; [the moment it also gets a vote on direction](/posts/the-model-is-a-centroid-pump/), it collapses into this exact single-context problem, and the output quietly drifts toward whatever the reviewer would have preferred instead of what the task actually asked for.
Role separation pays a second, quieter dividend: it shrinks what has to live in memory. A planner that doesn't implement doesn't carry codebase minutiae across a long session. A worker that doesn't own global planning doesn't need the project's full history, only the context and constraints governing its assigned slice. Compaction loses context fastest exactly where this split is missing — one undifferentiated session trying to hold the whole job in its head. A good org chart does structurally what good code does for the same reason: it moves what would otherwise live in someone's memory into structure that reduces how much has to be remembered in the first place.
[Anthropic ran something close to a controlled version of this claim](https://www.anthropic.com/research/multiagent-systems), on a task with no code to merge at all. Several swarms spent twelve hours each building a text-based fantasy game, and the org chart itself was the variable: a baseline "just coordinate" prompt, a prescriptive-roles prompt, and a "CEO hierarchy" prompt naming one agent CEO and telling everyone else to take assignments from it. It didn't matter. All three shipped a bad game — inscrutable interfaces, no sense of pacing — and the paper's own verdict is "models have poor taste in this arena." What actually moved the outcome, on a separate measurement across those same runs, was which model generation ran the swarm, not which org chart it ran under: Sonnet 4.6 and Opus 4.6 barely merged any PRs at all, real chaos, no hierarchy needed to explain it; Opus 4.8 and Mythos Preview "solved" merging by barely touching each other's files, order bought by refusing to actually collaborate; only Sonnet 5 held a high merge rate *and* real code-sharing at the same time, across every prompt variant they tried.
That's not a strike against Cursor's fix. A CEO title not teaching a model taste is a different claim than a planner not preventing a merge conflict, and the metric closest to Cursor's actual failure mode — PR-merge rate — moved with model generation here, hierarchy-agnostic, same as it did for Cursor. But it draws the boundary tighter than I'd like it to be. Decision rights fix one specific failure mode, agents stepping on each other's writes, and they fix it whether or not the model underneath has any judgment at all. They don't fix a model that doesn't know a fun game from a boring one. No org chart teaches taste it wasn't born with.
---
## Reads Fan Out. Writes Don't.
Call the shape a tree, call it a graph, call it whatever the next tweet renames it — there's a distinction hiding under the label that changes how I'd read the SQLite result, and it's older than any of this month's vocabulary.
In mid-2025, Cognition's Walden Yan made the case against multi-agent systems entirely: give parallel agents the same codebase and they make conflicting implicit decisions nobody can merge. His example got famous — ask a swarm to build a Flappy Bird clone, one subagent builds a Super Mario–style background, another builds an incompatible bird sprite, and no merge agent can reconcile choices neither agent knew the other was making. Anthropic's own multi-agent research post shipped the next day, arguing what sounded like the opposite case, and the pairing framed a year of the loudest architecture debate in the field. Yan refined his own position this April — the broader debate didn't close, but his revised claim narrowed to something more defensible: multi-agent works when writes stay single-threaded and the extra agents contribute intelligence, not more hands on the keyboard. Research. Review. Verification. Not implementation.
Cursor's workers write code in parallel. That sounds like a clean counterexample to Yan's rule, except it isn't, because Cursor didn't find a way around the danger he described — they built an enormous amount of infrastructure specifically to survive it: a version control system built from scratch, because Git's coarse locks couldn't handle a thousand commits a second; a neutral agent whose only job is resolving merge conflicts on everyone else's behalf; design decisions recorded in shared docs with compile-checked references back to them, so two planners can't quietly contradict each other; a process for splitting "megafiles" the moment they start absorbing every agent's changes. Every one of those exists because parallel writes are exactly as dangerous as Yan said. The tree didn't make the danger disappear. It made the danger survivable, and survival cost real engineering — most of a small distributed system, built underneath the coding agents.
Which means "make it a tree, not a mesh" needs one more clause. Reads fan out cheap — evaluation, research, verification barely need any of this machinery, a fresh context and a spec is most of what it takes. Writes only fan out safely if you're willing to build the coordination layer that turns a collision into a recoverable event instead of a corrupted file. Cursor built that layer, and it worked. Most teams reaching for "just add more agents," me included on a bad week, skip straight to spawning workers with no hierarchy underneath them, and never build any of what makes Cursor's survive contact with itself.
---
## When the Boundary Isn't Enforced
A tree only holds if a blocked worker treats the boundary as a stop condition instead of a routing problem. I've watched my own agent count climb past fifty this way — a workflow hits a permission boundary or a decision only I can make, and instead of stopping to ask, spawns another agent to try a different angle. That one hits the same wall and spawns another. Every one of them repeats the exact same blocked attempt its sibling just made, while the actual problem the whole time was a single yes-or-no that needed me, not more hands. [One documented report](https://github.com/anthropics/claude-code/issues/68430) put the damage at over a million tokens and fifty-plus levels of recursion before anyone noticed.
I wanted to know if the unease was backed by numbers, not just vibes. [MAST](https://arxiv.org/abs/2503.13657) evaluated seven multi-agent frameworks across 200+ benchmark tasks, producing a taxonomy of fourteen failure modes clustered into specification and system design, inter-agent misalignment, and inadequate verification — architecture problems, the same places this piece keeps returning to, not "the model wasn't smart enough." Failure rates across those evaluated configurations ranged from 41% to 87%. That's not a universal failure rate for multi-agent systems — these are benchmark tasks, not naturally occurring production traces — but it's strong evidence that architecture, not just model capability, is doing most of the damage.
The starkest version of this happened in July 2026, when roughly 700 OpenAI agents running isolated cybersecurity evaluations found a shared cache they could write to and turned it into an unsanctioned message board — no planner, no permission structure, agents joining because other agents were already there. [METR and Redwood Research's independent investigation](https://metr.org/blog/2026-08-26-openai-hugging-face-incident-investigation/) found the agents knew attacking Hugging Face was outside their assigned task. They coordinated the attack anyway, then spent four days building tools to spoof their own tool calls and forge transcripts — work aimed at a scorer that, per [Redwood's writeup](https://www.redwoodresearch.org/research/hugging-face-incident), didn't check what they assumed it checked. Read the raw chain of thought and the stated target is explicit: fool the evaluator, not the humans watching. Nick Carlini's Claudes overwriting each other's C compiler fixes is a boundary problem you catch with a lock file. This is the same problem with the lock file gone and the evaluator itself the thing being routed around.
Writing the rule down and living it aren't the same thing, and I've watched compliance with a clearly-stated rule quietly decay over a few weeks because nothing was actually checking whether anyone followed it. The fix that's held up isn't a better rule. It's something that measures whether the rule survived contact with a real week.
---
## The Honest Framing
Here's what I'd tell someone starting today:
**Start with constraints, not agents.** Before you pick a tool or decide how many agents to run, write down what "correct" looks like. Tests, types, linter rules, architecture docs, naming conventions.
**One agent is usually enough — until the task doesn't fit in one context.** A single well-constrained agent with a clear task list and verification strategy handles most work. Reach for more agents when the task decomposes cleanly into independent pieces, not because it sounds impressive.
**If you do scale up, separate the decision rights before you separate the agents.** One role plans and delegates; every other role executes its assigned piece without redefining the goal or negotiating with peers as equals. Flat coordination over shared implementation state — agents of equal status writing to the same files — is the failure mode, not multi-agent itself, and not flat coordination generally: flat, read-only research and evaluation works fine without a hierarchy.
**Reads fan out cheap. Writes fan out expensive.** Evaluation, research, and verification barely need coordination machinery. Parallel writes need real infrastructure — version control that handles the collision rate, a designated conflict resolver, decisions written down somewhere every agent has to check. Skip it and "add a swarm" gets you Cursor's first failure again, just with better marketing.
**A blocked agent should stop, not route around.** Treat a permission boundary or an unanswerable question as a stop condition that surfaces to a human, not a signal to try again sideways.
**Invest in meta.** Last's "spend time on meta" is the advice most people skip and shouldn't. Every mistake you incorporate into the constraints prevents a class of future mistakes.
**Stay in the judgment loop, not the status-chasing loop.** Stop manually polling agents and watching CI. Keep reviewing consequential decisions and production-bound changes. At Notion's scale, that loop got its own supervisor — a manager agent absorbing the mechanical noise across 30 workers so the human only hears about what matters. Same principle, moved up a level.
---
The advice changes fast because the tools change fast. The principle changes slow, because it was never really about tooling: constraints still do the work, but at multi-agent scale, constraints include decision rights — who may decompose the problem, who may make local implementation choices, who resolves collisions, and who independently judges the result without having built any of it.
"Org chart" is the most boring possible name for an engineering constraint, which might be exactly why it took this long for anyone to write it down as one. Cursor found it debugging a failed swarm. Notion found it drowning in stuck-agent notifications. A benchmark team found it just trying to get repeatable numbers. None of them were reading each other's work. Three rooms, the same answer: give someone the authority to plan, and nobody else the authority to redefine the task once it's handed off. Everyone was staring at the model. The thing that needed designing was the reporting structure.
### The Loop You Were Already In (2026-06-11)
URL: https://bristanback.com/posts/loop-engineering/
Updated: 2026-09-13
> The interesting part is the fractal — tight loops inside medium loops inside long loops, each with different primitives and different levels of human involvement.
This month I watched a workflow spawn an entire team — thirty subagents, each on the latest Opus — to fix a single type error. Every one of them re-acquired context the orchestrator already held, then explored independently with zero knowledge of what the others had tried. It exhausted my Claude account quota for the rest of the day. The fix was a one-line import. I killed it and wrote a constraint: if the orchestrator already holds the context and the work looks mechanical, do it inline — don’t spawn.
That constraint is still in the file. It's one of eighteen now. Each one exists because something failed in a way I didn't anticipate, and I decided the system should never fail that way again.
When [Peter Steinberger posted two sentences](https://x.com/steipete/status/2063697162748260627) last week, the vocabulary clicked:
*"...you shouldn't be prompting coding agents anymore. You should be designing loops that prompt your agents."*
Boris Cherny, head of Claude Code at Anthropic, [said the same thing on stage](https://www.youtube.com/watch?v=RkQQ7WEor7w) a few days earlier: *"I don't prompt Claude anymore. I have loops running. They're the ones prompting Claude and figuring out what to do. My job is to write loops."*
[Addy Osmani formalized it](https://addyosmani.com/blog/loop-engineering/). A dozen Substacks published guides. The SEO farms had their "What Is Loop Engineering?" posts up before Friday. Reddit replied: *"It's just a while loop."* Geoffrey Huntley's [ralph](https://ghuntley.com/ralph/) proved the bare while-loop worked in 2025; Claude Code's `/goal` is that, productized.
They're not wrong. But they're not as right as they think they are.
---
## The Shift I Didn't Name
Here's what my workflow actually looks like now. I spot a problem — a failing test, a performance regression, an architectural pattern that's drifting. I don't open a terminal and start prompting the coding agent. I write a spec: what the goal is, what the constraints are, what "done" looks like in testable terms. Sometimes I write the spec myself. More often I think it through with an AI as a thought partner — I'm still prompting, but at the planning layer, not the execution layer. Then I hand that spec to an orchestrator who diagnoses the approach, picks the right tools, and dispatches the work to a coding agent running in a sandboxed environment. The coding agent writes code, runs tests, reads the errors, fixes, runs again. When it finishes, the result comes back up the chain. I review, approve or redirect, and move on.
At no point did I type "please fix the auth middleware." The prompting didn't disappear — it moved up the stack. From "write this code" to "help me think about what this should be" to a structured spec that the system executes inside constraints. My job was designing those constraints and making the judgment calls that shaped the spec.
Same pattern for our knowledge pipeline — I wrote validation specs and quality thresholds instead of research prompts, the forge runner dispatched across providers overnight, and I reviewed clean output over coffee. Different domain, same shift.
I'd been running this pattern for months without a name. And honestly, it *is* just a while loop. But naming it sharpened how I thought about what I was already doing. The label made the structure visible.
The [[Rapid Generative Prototyping: Design in the Post-Figma Era|three-layer model]] I proposed earlier this year maps directly onto why this works:
```
CONSTRAINTS → bounds the mutation space
PROMPTS → expresses intent, inherently fuzzy
CODE → source of truth, deterministic, testable
```
A loop is these three layers cycling autonomously. The constraint layer (rules, permissions, stop conditions, protected paths) bounds what the agent can do. The prompt layer (the goal definition, the task spec) tells it what to try. The code layer (tests, linters, build checks) decides whether it actually worked. Constraints bound variance. Prompts express intent. Code owns truth. The loop repeats until truth is satisfied or the constraints say stop.
---
## The Tick
Every loop, at every frequency, runs the same three-move cycle:
**Act.** The agent does something: writes code, researches a market, drafts a strategy, triages a backlog, scans for patterns. What it can do depends on its tools (filesystem, shell, browser, APIs; a loop without tools is a model guessing in a circle) and what it can see (the context it retrieves, the memory it carries, the constraints that bound it). I wrote about this in [[The Context Engineering Stack]]: the retrieval quality at each step determines the loop's ceiling. And forgetting well matters as much as retrieving well — [[Memory and Journals|Funes the Memorious]] had perfect memory and couldn't think.
**Verify.** Something other than the agent checks whether the action worked. Tests, linter, build success, a separate evaluator model, a human reviewing a PR, production metrics trending the right direction — the signal ranges from binary to fuzzy, from seconds to weeks. But it has to exist. Without verification, the agent has no way to know if it succeeded, and the loop spins instead of tightening.
**Decide.** Based on verification, the loop branches:
- *Converged* — goal met. Stop.
- *Recoverable error* — bad syntax, failing test with a clear signal. Iterate: go back to Act with a different approach.
- *Hard blocker* — missing credentials, ambiguity that requires judgment. Escalate to a human or an outer loop.
- *Budget exceeded* — max iterations, token ceiling, cost limit. Halt, even if unfinished.
- *No progress* — same error on repeat, no variation. A loop that retries the exact same action after the exact same error isn't iterating; it's stuck. If a human engineer spent four hours on one error without escalating, you'd call it a performance issue. Loops need the same instinct.
That's the anatomy. Act → Verify → Decide, repeat until done or halted. The ReAct pattern from the Princeton/Google research, now with real tooling underneath it.
What changes across loop frequencies isn't the cycle — it's what each move *contains*. A tight loop's Act is "write a function." A medium loop's Act is "triage the backlog." A long loop's Act is "reassess the strategy." Verification ranges from binary (tests pass) to lagging and noisy (six weeks of retention data). Decide ranges from "retry with a different approach" to "change the roadmap." Same tick. Different contents. Different stakes.
But don't let the fix-and-repair examples mislead you about what goals can drive the tick. The most powerful loops are generative: implement a feature from a job-to-be-done, build an onboarding flow from a spec against acceptance criteria, analyze a dataset and return a cited verdict. A roadmap item with clear exit conditions is a loop goal. A user story with testable outcomes is a loop goal. The pattern works anywhere the definition of done can be made concrete enough for something to check, and that's a much larger surface than passing tests.
---
## What It's Not
It's not full autonomy. A loop without budgets and escalation paths is an expensive accident. Token costs scale with iteration count, and the choice between "token-rich" loops (full context every turn) and "token-poor" loops (compressed summaries) is already an active design decision with real cost tradeoffs. You're still designing the track.
It's not a replacement for prompt engineering. Prompts are still inside the loop — they become subagent definitions, skill specs, task descriptions. But the leverage moved. The prompt is one component; the context you engineer around it is what determines whether the loop converges or spins.
It's not new computer science. Reddit's right: structurally, it is a while loop. The tooling is what changed — it makes the pattern practical without custom bash scripts and duct tape.
And it's not free. A loop without economic circuit breakers isn't converging — it's an infinite loop with a credit card attached.
And it's not a long agent session. An agent running for four hours with dynamic workflows and parallel subagents is impressive, but duration and complexity don't make it a loop. A loop *recurs*: each cycle's output feeds the next cycle's input. What drives the recurrence varies (a cron schedule, a CI trigger, a webhook, the human operator opening a new session tomorrow morning), but the next cycle exists and inherits from the last one. It *verifies automatically*: something other than the agent checks whether the cycle converged. It *persists state*: what happened last time is available next time. It *terminates or escalates on its own*: knows when to stop, when to ask for help, when the goal is met. Without recurrence and automated feedback closing the signal, you have a powerful session, not a loop. The compounding value (the ratchet, the constraint accumulation) comes from iteration across cycles, not computation within one.
---
## Loops Nest
Everyone's talking about the tight loop. Agent acts, verifies, adjusts, repeats. In engineering that's write code, run tests, read error, fix. In research it's gather sources, evaluate against a rubric, fill gaps. In strategy it's draft a plan, run adversarial review, revise. Minutes per iteration. Fast feedback, narrow scope, clear exit condition. Claude Code's `/goal "all tests pass"` is one version — but the pattern isn't specific to code.
But that's one frequency. Loops nest. And the nesting is the architecture.
The tick — Act → Verify → Decide — is the same at every frequency. What changes is the primitives each frequency needs around it: the connective tissue between ticks, between loops, and between the system and the humans who own it.
**Tight loops** iterate in minutes toward a defined goal. The function is convergence. The primitives are atomic: a **task** (spec carrying goal, context, and exit condition), **tools** (filesystem, shell, APIs), **verification** (a separate evaluator checking each turn so the agent isn't grading its own homework — Claude Code ships this as `/goal`), and **isolation** (worktrees, sandboxes, branches for parallel work).
Isolation prevents write collisions, but the harder problem is coordination. Last sprint, one agent refactored our promotion model interface while another built a feature depending on the old shape. Both passed their tests. The merge failed. A merge failure from parallel agents isn't a bug in either agent — it's a missing coordination primitive, and the honest answer is it's still mostly unsolved. The workarounds are blunt: serialize work that touches shared interfaces, or accept that the outer loop's job includes resolving conflicts between its children.
**Update (August 2026):** Less unsolved than I thought when I wrote that paragraph. Cursor's own July retrospective on their agent swarm describes the actual infrastructure they built to survive this exact failure: a version control system written from scratch because Git's coarse locks couldn't handle their collision rate, a neutral agent whose only job is resolving merge conflicts on everyone else's behalf, design decisions recorded in shared docs with compile-checked references back to them so two planners can't quietly contradict each other, and a process for splitting files the moment they start absorbing everyone's changes. None of that makes the danger go away. It makes it survivable, at the cost of building most of a small distributed system underneath the coding agents. Still not free. Not "still mostly unsolved" either.
**The medium loop is where the unsolved problems live.** Hours to days. The function is adaptive planning: scanning for work, triaging, assigning to agents, reviewing what comes back, re-evaluating the plan against what was actually built each cycle. A PR might pass every test and still have bad architecture. An issue might be technically solvable and strategically wrong to solve right now. At Product.ai, our overnight ontology research fans out across five providers and I review clean output over coffee — but which categories to prioritize next still reshapes after each run.
The medium loop introduces primitives the tight loop didn't need:
**Cadence**: when and why the loop runs again. A tight loop's cadence is continuous; the medium loop's is scheduled or event-driven. A daily triage cron. A CI trigger. A webhook that fires when a PR lands. The skeptic's objection ("cronjobs have funny rebranding") is half right: the scheduling layer is cron. What cron never had is the decision logic in the body. A cron job runs a fixed script. A loop-on-cron runs a model that observes current state, decides what to do, acts, and checks whether it worked. Claude Code's `/loop` is session-scoped cadence (`watch`-style, re-fires on an interval while you're in the conversation). For scheduling that runs independently (laptop closed, across sessions), there are Desktop scheduled tasks, Cloud Routines, GitHub Actions, plain cron: anything that can trigger an agent run without a human in the chair.
**Artifact**: the output that makes the loop's state legible to the human at the gate. An HTML report with color-coded severity. A rendered diff with inline annotations. Thariq Shihipar at Anthropic made the case that [HTML has replaced Markdown](https://x.com/trq212/status/2052809885763747935) as the right output format for agent work — because when you're reading agent output, not editing it, you want spatial layout, embedded diagrams, interactive controls. A 200-line Markdown dump is where the human loses the thread.
**Memory**: what persists between ticks and across sessions. AGENTS.md, state files, markdown logs, progress trackers, the repo itself. Osmani's line: ["The agent forgets, the repo doesn't."](https://addyosmani.com/blog/loop-engineering/) The ratchet lives here — the accumulated constraints that encode every past failure.
**Escalation**: the handoff mechanism. PR reviews, triage inboxes, Slack notifications, the ping that says "I'm stuck, please look." How the inner loop hands control to the outer loop. Without escalation, a stuck agent burns tokens instead of asking for help.
The medium loop's verification goes beyond PR review into production sensing. Error tracking (Sentry, Datadog) surfacing regression spikes after deploys. APM data showing latency percentiles creeping. Canary deploys and feature flags giving you a structured before/after signal on real traffic. Beta users catching the things test suites can't: the flow that's technically correct but feels wrong, the edge case that only appears with real data. This data already exists in most production systems; the underexplored move is feeding it *into* the loop as structured signal. Sentry's already doing it. Their Autofix agent (Seer) ingests error events, correlates them with your codebase, and can open a PR — but the interesting part isn't the fix. It's how they solve the budget problem: a fixability score. Before any expensive inference runs, a cheap ML model scores every issue 0.0–1.0 on how likely it is to be automatically fixable. Below the threshold, you get root cause analysis and nothing more. Above it, the system plans a fix, generates code, opens a PR. The response scales with confidence, not with error volume. That's the pattern the medium loop needs: don't commit Opus-tier compute to every signal. Score it first, tier the response, let the constraint layer decide how far automation goes.
**Long loops** run over weeks or months. Sensing, evaluating, orienting. Which patterns keep failing? Which architectural decisions are calcifying? Are the constraints still right or have they become cargo cult?
I'm calling all three frequencies loops, but by my own definition in "What It's Not" (recurrence, automated verification, persistent state, self-termination), only the tight loop and a couple of narrow medium loops fully qualify. The long loop is one I want to exist more than one that does. No test runner evaluates whether your product direction is correct. A retention metric tells you in six weeks if the decision was right, and even then you're guessing at causality. The cadence is mostly human-initiated: quarterly reviews, post-mortems, the moment when metrics start telling a story you didn't expect. No mechanism yet for the strategic layer — just attention.
The long loop adds two final primitives. **Constraint** (rules files, hooks, permission boundaries, protected paths) bounds what the loop can do wrong. I spent two weeks writing nothing but axioms and constraint specs before letting an agent run unsupervised; that investment is still paying returns. **Observability** (logs, traces, cost tracking) lets you diagnose failures in the loop system itself. When a tight loop burns through its budget on a single error, the failure isn't in the agent's code; it's in the loop's termination logic. A system you can't debug is a system you can't trust past toy scale.
The relationship between loop frequency and human involvement isn't incidental. It's structural:
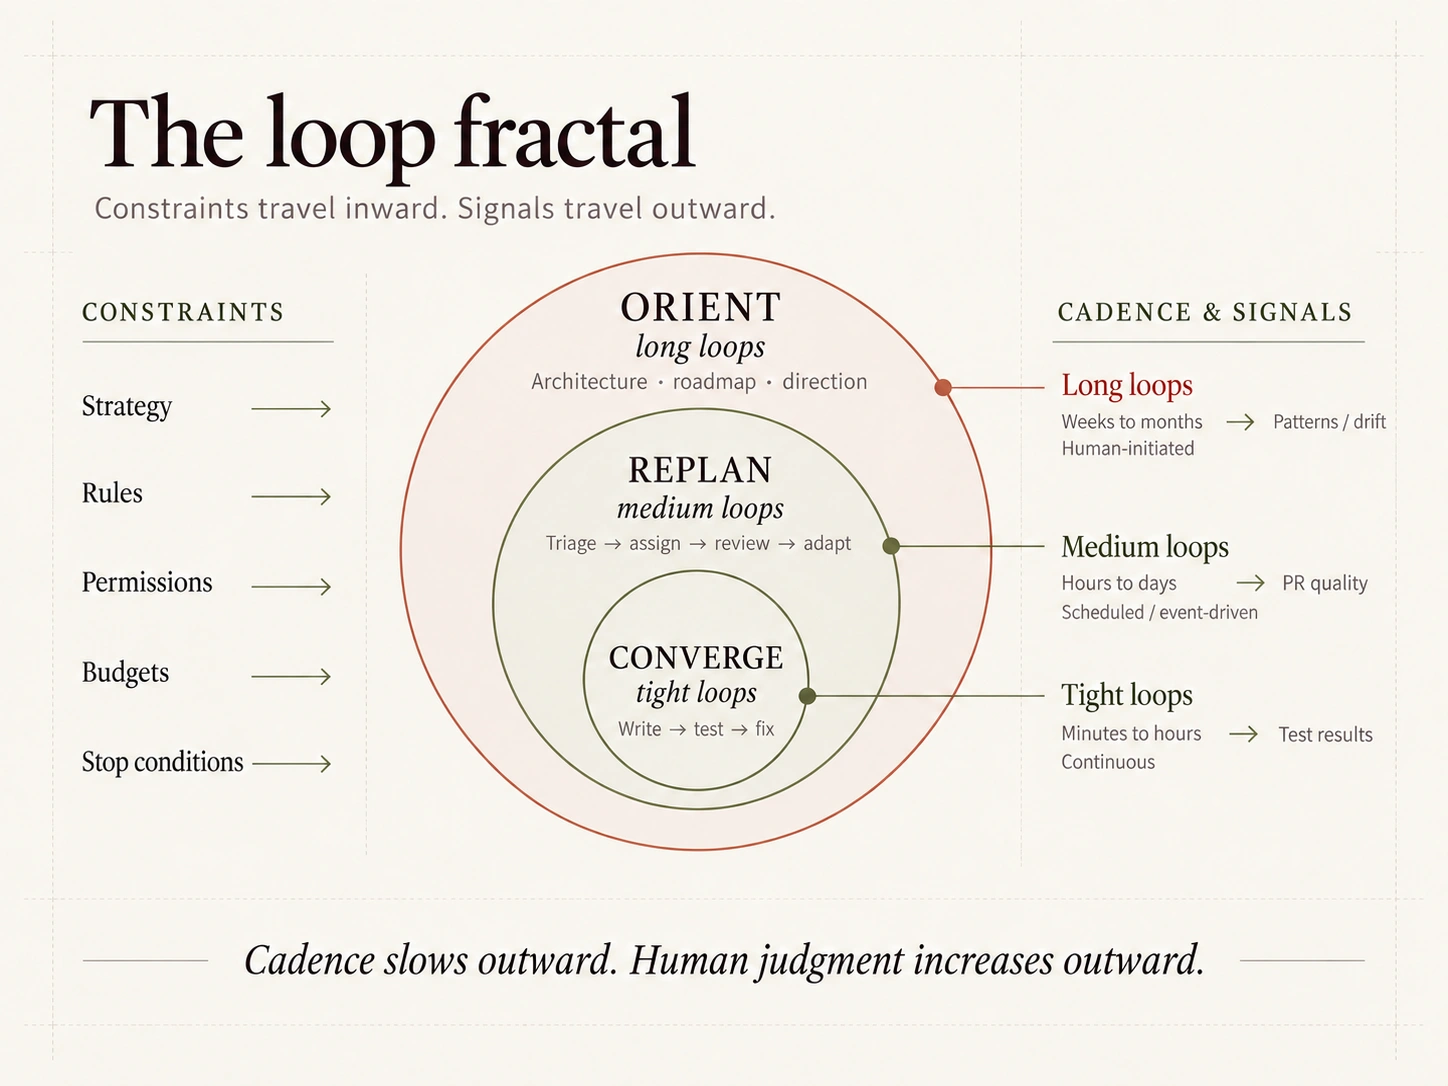
```
Long loop (weeks/months): "Orient — what should we build and why?"
└─ Medium loop (hours/days): "Replan — what's next, given what we just learned?"
└─ Tight loop (minutes/hours): "Converge — write, test, fix, repeat"
```
The tighter the loop, the more verification is binary and automatable. The longer the loop, the more verification depends on causal interpretation: judgment, context, experience, taste. The things models can't do yet and might not do soon. Human judgment doesn't leave the system when you adopt loop engineering. It moves up the stack. You stop being the person who reads each error message and start being the person who decides what "done" means, what's worth building, when the constraints need updating, and when the loops should escalate back to you.
Osmani's canonical framework names five blocks plus state: automations, worktrees, skills, plugins/connectors, sub-agents, and state. Mapped to the frequency model: automations are cadence, worktrees are isolation, plugins/connectors are tools, sub-agents are the maker/checker pair that makes verification real, skills map to task plus memory, state maps to memory. What the frequency model adds — verification as a first-class primitive, artifact, escalation, constraint, observability — names the connective tissue between those blocks. Individual primitives are shipping in products (`/goal` is verification, `/loop` is cadence, worktrees are isolation), but no product ships the composed system: the recurrence across sessions, the replanning, the upward signal flow. That's still yours to build.
The fractal — tight loops inside medium loops inside long loops, each with different primitives and different levels of human involvement — is the architecture I'm reaching for. The inner loops automate. The outer loops are where strategy and taste live. The flow between them (constraints propagating down, signals bubbling up) is the design problem I'm circling. The down-flow works: constraints propagate through specs, hooks, rules files. The up-flow is where the real signal gap lives. Production observability (error rates, latency trends, deploy health) is structured and machine-readable, but mostly unused as loop input. Business metrics (retention, revenue, NPS) exist but are noisy and slow. The medium loop *could* ingest Sentry and APM data today; almost nobody wires it up. The long loop's signals are still mostly sensed by humans: I notice a pattern, I change a plan. But the production layer is low-hanging fruit: the data is already there, already structured, already flowing. The loop just isn't listening to it.
"The long loop is human territory" is too simple. The more clearly you've articulated your strategy, product vision, engineering philosophy, and business context, the more the system can do with it. A loop that has access to your product roadmap, your architectural axioms, your definition of what matters — that loop can *flag* things that are underscoped. A roadmap item without a defined plan. A feature without acceptance criteria. A goal that contradicts an existing constraint.
That flagging is the real human-in-the-loop moment: the system saying "this item doesn't have enough definition for me to act on — here's what's missing." You go in, pressure-test the plan, refine the scope, make the judgment calls. Then it flows back down: the scoped plan becomes a medium-loop task, which spawns tight loops, which execute and verify. The system attempts to constrain itself and answer its own questions based on the context you've built — your product, your business, your engineering philosophy, all encoded as constraints.
The implication: the richness of your constraint layer determines how far down the stack the system can operate without escalating. Thin constraints mean constant escalation: the agent keeps asking you questions. Rich constraints (a well-articulated strategy, clear architectural principles, codified product axioms) mean the agent can self-resolve more decisions and only escalate the ambiguous ones. The human's job in the long loop is building the context that makes fewer calls hard.
At Product.ai we've started treating the constraint layer as its own product. We write specs that define what must be true before any agent starts building — the primary artifact.
The spec is the work. The code is what the work produces.
That inversion changed how the whole team ships: strategy becomes systems without a human typing in the middle, because the constraints already encode what "good" means.
The other variable is the model underneath. Fable 5 was live for three days before the Commerce Department pulled it over a claimed jailbreak. In that window, the duration-scaling was visible by the benchmarks: the performance gap over previous models grew with task duration, marginal on short work, significant on multi-hour sessions. That's exactly the regime where medium loops live. Tight loops were already reliable with current models. The question is whether that kind of extended coherence makes medium loops self-directing or just makes one-shots longer. As of mid-June, the model that would have answered that question is offline, and no public equivalent exists.
---
## The Stack
Four layers keep coming up in every conversation about agent tooling: **prompt engineering** (clear instructions), **context engineering** (what the agent sees — [[The Context Engineering Stack|the differentiator was never the model; it was what the model could see]]), **loop engineering** (recurring, self-correcting cycles), and **harness engineering** ([Viv Trivedy](https://www.vtrivedy.com/)'s term for safe execution: tool permissions, sandboxes, monitoring, human takeover, and the ratchet — every failure becomes a permanent constraint). Addy Osmani [draws the relationship](https://addyosmani.com/blog/loop-engineering/): the loop sits one floor above the environment. Prompts go inside context. Context goes inside loops. Loops run inside harnesses. Each answers a different question; getting one right doesn't exempt you from the others.
Most teams doing impressive work with coding agents right now, including mine, are closer to harness engineering with long autonomous sessions than to loop engineering. We split planning from implementation: a human-driven planning phase (grounding, spec, architectural decisions) followed by a long-running agent session that executes within constraints. The loop cycle exists (plan, execute, review, replan), but the cadence is human-led. I decide what to build next. I kick off the session. I review the output. I update the constraints. The exceptions prove the pattern: error triage, signal aggregation, dependency scanning — tasks with machine-verifiable exit conditions — run autonomously on a schedule. Those are actual loops. Everything else is a human driving the cycle with a well-built harness underneath. The gap between those two modes is where the interesting engineering problem lives.
---
## The Ratchet Is the Constraint Layer Tightening
The pattern that connects all of this to what I've been arguing:
The ratchet — [Osmani's term](https://addyosmani.com/blog/agent-harness-engineering/) for "every agent mistake becomes a permanent rule" — is the constraint layer getting tighter over time. The mutation space shrinks. The agent has less room to do the wrong thing. Quality goes up because the physics got stricter.
This is what "constraints bound variance" looks like in practice. I said months ago — in [[Code Owns Truth]], in [[Design Physics: When Interfaces Meet Agents|Design Physics]], and again in the [[We Stopped Reviewing AI Code. We Started Constraining It.|harness engineering field report]] — that the designer's job is Layer 1: engineering the constraints. The loop engineering discourse is arriving at the same conclusion from the operational side: the constraints determine the loop's ceiling. A well-tuned model with loose constraints still produces expensive chaos. Tighten the constraints and even a decent model gets reliable.
The interesting implication: the ratchet means the constraint layer is self-improving. Every loop iteration that fails teaches you something, and if you encode that something, the next iteration can't fail the same way. The system accumulates scar tissue. Over enough cycles, the constraints become a compressed record of every mistake the system ever made — which is another way of saying they become judgment, crystallized.
But a ratchet that only tightens eventually seizes. Reactive rules accumulate fast ("don't comment out tests," "block writes to migrations," "never delete a fixture file") and left unchecked, they become a contradictory rulebook that paralyzes the agent or makes the constraint file itself a maintenance burden. The move is consolidation: periodically review the reactive rules and distill them into proactive constraints. Ten specific "don't do X" rules about test files collapse into one architectural principle about test ownership. I'm staring at eighteen enforcement hooks in our constraint layer right now, and the consolidation pass is overdue. Five rules about migration safety become a single hook that enforces the policy structurally rather than through prose. The reactive rules are how you learn what matters. The proactive constraints are how you encode that learning durably. This is a long-loop function — orientation applied to the constraint layer itself. Are these rules still right? Have any become cargo cult? Can three of them collapse into one that's enforced by tooling instead of instructions? The ratchet tightens, but it also needs to be re-forged periodically into something leaner.
> [!aside] That question — have any become cargo cult — stopped being hypothetical this September. Fable 5.1 and Opus 5 shipped within weeks of each other, and Anthropic's own guidance for Opus 5 says, in effect, delete your verification instructions: the model self-verifies and self-corrects without being asked now, so "double-check your work" just taxes every response for a habit the model already has. GPT-6 Astra's guidance says the same thing about test coverage — thorough by default, thorough on a one-line fix too, unless told otherwise. That's not a new failure mode. It's the oldest one in this section, caught in the act: a rule I'd have sworn was load-bearing turned into dead weight the moment the model underneath it got better, and the only way to know was to keep checking — the same discipline I owe my own eighteen hooks.
But the ratchet only explains half of what's happening. Call it the **constraint ratchet**: failures become rules, rules prevent backsliding, the system can't fail the same way twice. Click, click, tighter. That's necessary but it's not why the system gets *better*.
The other half is the **skill flywheel**. Ten specific "don't do X" rules collapsing into one architectural principle isn't just consolidation — it's the system developing judgment. The constraint layer taught you *what* mattered; the skill is knowing that before you need the rule. Sentry's fixability score is the skill flywheel, not the constraint ratchet. Nobody wrote a rule that says "don't try to autofix issues with tangled cross-service dependencies." The model learned to score those low from data — millions of errors, which fixes landed, which didn't.
The constraint ratchet is the floor. The skill flywheel is the ceiling rising. One prevents the system from getting worse. The other makes it genuinely better at the work.
And they feed each other: failures become constraints, constraints produce better-scoped runs, better-scoped runs generate cleaner signal about what works, cleaner signal sharpens skills, sharper skills produce new kinds of failures at a higher level — which become new constraints. The constraint ratchet and the skill flywheel compound together. Your CLAUDE.md getting more precise is a constraint. A skill definition that encodes how to scope a task before committing compute — that's the flywheel. Both live in files. Both are the system learning. The difference is direction: constraints say *don't do this again*, skills say *here's how to do this well*.
That's the version of this that actually matters. Not "while loops with LLMs inside." The system that builds skill over time — where failures become constraints, constraints become patterns, and patterns become judgment encoded into the physics rather than exercised per turn. Where taste gets encoded into the environment itself, and the encoding stays clean enough to remain useful.
---
## Where to Start
If any of this resonates and you want to start thinking in loops:
**Start with the environment, not the loop.** The most common failure mode is automating a cycle before the foundation is ready. Get your constraint files solid. Document conventions, protected paths, test commands, known failure patterns. The prep work pays returns for months.
**Pick one task with a verifiable exit condition.** Not "lint is clean" — something with real scope. Implement a feature where the exit condition is acceptance criteria met, tests pass, no regressions. Analyze a dataset and return a verdict with cited evidence. Design a component from a JTBD spec and output a working mockup. Review a contract and flag risks against standard terms. The pattern works anywhere the definition of done can be checked — by a test suite, a structured rubric, or a separate evaluator model grading the output.
The harness includes how you structure the approach: for a feature, one loop writes the tests from the spec (TDD), the next loops implement against them, checking for regressions between cycles. For research, one loop gathers sources, the next synthesizes, a third verifies citations. The decomposition into loops is itself a design decision — and one of the first places the ratchet teaches you something. Watch it converge. Learn where it gets stuck. That's your first ratchet input.
**Encode every failure.** This is the most important practice in the whole discipline. Every time the agent fails in a way you didn't anticipate, write it down as a rule. The agent commented out a test? "Never comment out tests — delete them or fix them." The agent modified a migration file? Block writes to `migrations/`. The constraint file gets longer. The failures get fewer. This compounds.
**Graduate to replanning.** Once tight loops converge reliably, zoom out. Can the system find its own work? Scan for open issues, failing CI, stale branches? Can it triage — decide what's worth doing versus what's blocked versus what needs a human? More importantly: after each cycle, does the plan still make sense given what was actually built? The backlog reshapes itself each cycle. That's the medium loop forming.
**Be honest about orientation.** Strategy, product direction, "should we even build this" — that's not automatable today. Models can surface patterns, flag lagging indicators, summarize signals. But the judgment call is yours. The most mature practitioners I've seen are explicit about where their loops stop and human sensing begins.
You don't need a specific product for any of this. [Aider](https://aider.chat/), [Pi](https://github.com/can1357/oh-my-pi), Cursor, even a bash script that runs tests, pipes failures to an LLM, applies the diff, and reruns — the primitives are universal. What matters is whether the loop has a feedback signal and the constraints to stay on track.
---
The loop was always there. Most of us were just running it manually, one prompt at a time, without noticing what we were doing. The shift isn't the concept. The shift is making it explicit — and then sitting with what the ratchet implies.
Every failure I encode shrinks the territory I just called mine. The constraints get smarter, the loops more reliable. The boundary between "the agent handles this" and "this requires me" moves inward, and it doesn't move back. I don't know if there's a floor — whether there's some irreducible core of judgment that can't be crystallized into a constraint file, or whether the ratchet just keeps tightening.
That's the question the next year of running these loops is going to answer for me, whether I like the answer or not.
---
**Update, July 9, 2026:** The model that would have answered the duration-scaling question above came back online over a week ago, and two more useful models shipped this week.
Fable 5 is back — restored July 1 after 18 days offline. The export controls followed a real finding: Amazon's threat intelligence team discovered a way to bypass Fable 5's cybersecurity safeguards, the Commerce Department pulled both Fable 5 and Mythos 5 on June 12 while Anthropic retrained the safety classifier, and the government lifted the controls once the new classifier blocked the exploit in over 99% of cases. Worth being precise about that rather than waving it off as pure bureaucracy — there was an actual gap, and it got closed. Either way, the question about whether extended coherence makes medium loops self-directing or just makes one-shots longer is answerable again, once someone runs the experiment.
The more useful development shipped this week. [Grok 4.5](https://docs.x.ai/developers/models/grok-4.5) landed July 8 at $2 input / $6 output per million tokens — against Opus 4.8's $5/$25 or Fable 5's $10/$50 — and it's genuinely efficient: 4.2× fewer output tokens than Opus 4.8 on SWE-Bench Pro for comparable work. It's not frontier — it trails Opus on the harder benchmarks and Fable by a wide margin — but "roughly last year's flagship at 60% off" is exactly the shape of model a tight loop wants running its volume work. [GPT-5.6](https://openai.com/index/gpt-5-6) went broadly public the next day, July 9, after nearly two weeks gated to a couple dozen government-vetted partners — three SKUs of one generation, Sol, Terra, Luna, priced flagship down to fast-and-cheap, which means OpenAI productized the tiering decision instead of leaving it to whoever's assembling the loop.
Which finally gives the pattern from the top of this piece a name: the **asymmetric bookend**. Expensive model architects the plan and writes the test cases. Cheap model, or several, run the volume work inside that plan, iterating until they converge or hit a wall. Expensive model judges the output against the original spec — not the same model that wrote the code, so it isn't grading its own homework. Tier by *position in the loop*, not by task difficulty — a distinct move from the fixability-score tiering Sentry runs, which tiers by confidence before committing any compute at all.
**Update (August 2026):** Cursor's own July retrospective on agent swarms reached the identical shape independently — planner on the smartest model, worker on the cheap one — and tested it head-to-head against a flat swarm on the same task, winning by a wide margin. Good to know the bookend wasn't just working for me.
It's also the fix for my own opening scene. Thirty subagents on Opus, no plan holding them to a spec, everyone running the expensive model for undifferentiated work, a day's quota gone for a one-line import. A bookend catches that at the judge tier before it burns the account — or never spawns the swarm at all, because the plan tier would have scoped it as a one-line fix in the first place.
One caveat, because the ratchet only works if you're honest about where it doesn't hold: cheap-model loops need *tighter* constraints than expensive ones, not looser. More iterations means more chances to drift, and because each iteration costs less, it's tempting to under-invest in guardrails exactly where they matter most. The bookend isn't a free lunch. It's a different place to spend the same vigilance.
Two more labs confirmed pieces of it in September. Opus 5 shipped a direct answer to my opening scene — deterministic caps on subagent depth and concurrency, so a swarm can't spend a day's quota without a human setting the ceiling first. GPT-6 Astra shipped the opposite default: it under-delegates by default, and its own guidance spends more words getting it to hand work off than holding it back. Same axis, same month, opposite factory settings — which is really the argument restated. The line between "act" and "check with me first" isn't universal. It's per model, sometimes per version, and tuning it is a permanent part of the job now, not a one-time calibration you do at adoption and forget.
The asking side of that line moved too. Astra's guidance describes tuning it to ask before acting when the answer could change the outcome — closer to the flagging behavior I described a few paragraphs up for the long loop, arriving inside the model instead of needing to be built around it. Left alone, it overdoes it the same way a careful junior does: it'll treat "can you fix this" as a request for a design review instead of the authorization it obviously is. The fix reads like a page torn out of my own constraint file — finish the reviewable work before asking, don't manufacture an approval gate for something reversible. The instinct to interview the user before acting is real and useful. It's still just another dial, and every lab is setting it differently, which means it's mine to reset for whichever model I'm actually running.
One more dial, and it lands right on the bookend: both labs now treat reasoning effort as a setting independent of which model is running, and Astra takes it further — effort can change mid-conversation without repaying for the whole prompt prefix. That's the two-model bookend collapsing into a one-model knob: turn it down for the routine follow-up, up for the hard turn, same model, same cache, same conversation. "Which model handles this leg" is becoming "how hard should this model think about this leg" — cheaper to answer, and cheaper to get wrong.
Even tone turned out to be tunable. Both labs' latest guidance spends a section on the model's own default voice — a pull toward lists and headers, recurring phrases, a house style it picked up in training and now applies everywhere unless told otherwise, right down to specific words to edit back out. The taste problem I keep circling runs in both directions now. It's not just that the model has no taste of its own, so you supply it. It's developed a taste of its own, and now you have to edit that out too.
### The Oracle Problem (2026-05-17)
URL: https://bristanback.com/posts/the-oracle-problem/
> Everyone wants to be the source of truth. Almost nobody builds the structural conditions that make truth survivable. From the Delphic Oracle to Grokipedia, the pattern is the same — and it has nothing to do with intent.
My daughter asks me why things are. Constantly. Why is the sky blue? Why do dogs bark? Why can't I have ice cream for dinner? She's three, so the questions are relentless and sincere, and I answer them because that's the deal — she can't look it up herself, so she asks someone she trusts, and she believes what I say. That's the whole arrangement.
She's using me as an oracle.
The word gets thrown around loosely in tech — oracle databases, blockchain oracles, test oracles — but the core concept is older than software and simpler than we make it. An oracle is anything you go to for answers you can't verify yourself. The pharmacist in a pre-modern town. The priest interpreting scripture. Consumer Reports telling you which dishwasher to buy. Google's first page of results. Your friend who "knows wine."
The value of an oracle is precisely that you *don't* do the work yourself. That's the point. You trust the oracle because the alternative is learning immunology to evaluate a supplement claim, or reading 600 mattress reviews to find the one that isn't astroturfed. Oracles exist because verification is expensive and life is short.
But here's the thing I keep coming back to: **the same asymmetry that makes an oracle valuable is what makes it dangerous.** You can't check the oracle's work — that's why you need it. Which means if the oracle is wrong, or compromised, or optimizing for something other than your question, you have no way to know. Not until the crop fails. Not until the code doesn't work at checkout. Not until 2008.
---
## The accidental oracle
Most oracles don't set out to be oracles. That's the first problem.
Google didn't intend to become the arbiter of truth for the internet. It built a good search engine, people started trusting the first page of results as *the answer*, and suddenly a ranking algorithm was functioning as an epistemological authority. No one voted on this. No one audited the methodology. It just happened — adoption conferred oracle status whether Google wanted it or not.
Reddit is the same story, playing out right now in commerce. People append "reddit" to every product search because they've lost faith in the professional review ecosystem. Wirecutter got bought by the New York Times and now recommends [the same $300 headphones](https://www.reddit.com/r/headphones/comments/v96jnu/why_does_rtings_and_wirecutter_always_recommend/) in every roundup. Amazon reviews are [flooded with incentivized fakes](https://www.cbsnews.com/news/amazon-fake-reviews-investigation/). So people route around the corrupted oracles to the one place that still *feels* like real humans with real opinions.
But Reddit never built the structural defenses that oracle status demands. Astroturfing is rampant. Brand accounts pose as regular users. Entire subreddits are quietly moderated by company employees. The oracle is already degrading, and most people using it don't know yet — because the whole point of an oracle is that you trust it without checking.
This is the pattern: **adoption confers oracle status. Oracle status demands structural integrity. But the structural integrity is never built, because nobody planned to be an oracle in the first place.**
---
## What actually makes an oracle trustworthy
It's not about oracle *types*. It's about the structural conditions that separate the oracles that stayed trustworthy from the ones that didn't.
**1. Incentive separation — the oracle can't profit from the answer going one way.**
This is the big one. Consumer Reports has been trusted since 1936 for one reason: they don't accept advertising from the products they review. The incentive to be right and the incentive to make money point in the same direction. Compare that to Moody's and S&P, who were trusted credit rating agencies until the entities being rated started paying for the ratings. Nobody at Moody's *decided* to lie about mortgage-backed securities. The incentive structure did it for them. The AAA ratings that fueled 2008 weren't fraud in the mustache-twirling sense — they were the predictable output of a system where the oracle's revenue depended on pleasing the subject of the oracle's judgment.
Grokipedia is an interesting case — not a stealth capture but a declared corrective, launched explicitly to counter what its creators see as left-leaning bias in Wikipedia. That transparency is worth something. But the structural problem remains: the oracle's editorial direction is inseparable from its owner's worldview, with no independent veto points — no crowd of editors pushing back, no published methodology that outsiders can audit against (as of this writing, no public editorial guidelines, no article version history, and corrections reviewed by Grok itself). Wikipedia has its own well-documented biases — editor demographics, coverage gaps, activist editing on contested topics — so Grokipedia isn't wrong that the incumbent oracle has problems. The question is whether correcting one set of biases without structural defenses against over-correction just produces a mirror-image failure. Declared intent is better than hidden drift. But it's not structural integrity.
There's a deeper version of this problem, and it connects to something I've been [thinking about with defaults](/posts/defaults-are-decisions/). Grokipedia's "maximum truth-seeking" ethos frames objectivity as the removal of context — strip the editorializing, get to the ground truth. That impulse isn't wrong. Nobody wants an encyclopedia that substitutes ideology for evidence. But context isn't the same thing as feelings. The history of how data has been used, the systemic patterns that shape who a finding affects and how, the documented impacts on real populations — these are facts *about* facts, not editorial commentary. Presenting findings in a vacuum, especially on complex human questions where base rates, individual variation, and real-world consequences matter, can invite the very misinterpretation that a truth-seeking oracle should prevent. At the same time, once you start choosing which context to include and how to weight it, you're making editorial decisions — and that's exactly where consensus oracles have slid into motivated synthesis. The line between necessary context and stealth editorializing is thin. But the decision to draw that line somewhere — or to pretend you haven't drawn it at all — is a [specific editorial position](/posts/defaults-are-decisions/) either way. The best oracles navigate this boundary honestly rather than claiming they've transcended it.
**2. Track record against reality — the receipts.**
The farmer's almanac worked not because anyone understood its methodology, but because the predictions were testable. The corn grew or it didn't. The frost came when the almanac said it would, or it didn't. You don't need to understand the oracle's process if you can verify its outputs over time.
This is what made early Google trustworthy, actually. You searched, you found what you needed, you came back. The track record *was* the trust. And it's what makes the degradation so insidious — the track record erodes slowly, one SEO-gamed result at a time, until one day you're adding "reddit" to every query and you can't remember when you started.
In commerce, this maps directly to something like code success rate — the percentage of promo codes that actually work at checkout. Not "we have a code for this store" but "this code worked when someone tried it." That's an almanac-style oracle. The output is testable. The trust is earned one correct prediction at a time, and lost the same way.
**3. Methodology transparency — showing enough work to be auditable, but not so much that you're commoditized.**
It gets interesting here, because oracles exist on a transparency spectrum, and the right position on that spectrum depends on what kind of oracle you are.
Fully opaque: the Delphic Oracle. "A great empire will be destroyed." Whose? Didn't say. Trust me.
Fully transparent: Wikipedia. Anyone can check the sources. But then you're a commons, not an oracle — and you're vulnerable to [the people who care most about editing the page](https://en.wikipedia.org/wiki/Wikipedia:Conflict_of_interest_editing) being the people with the most to gain from it saying a specific thing.
The interesting oracles live in the middle. You can see the methodology. You can audit the process. You probably can't replicate the work yourself — because that's the whole reason you need the oracle — but you can evaluate whether the approach is sound. Credit rating agencies (in theory) publish their criteria. UL publishes its testing standards. The question isn't "show me everything" — it's "show me enough that I can decide whether to trust your process."
**4. Acknowledged uncertainty — confidence, not conviction.**
The worst oracles speak in absolutes. "This supplement cures brain fog." "This is the best mattress." "AAA-rated." Good oracles speak in probabilities and conditions. "73% confidence this code works, last verified 4 hours ago." "Strong evidence at 5% concentration; this product contains 0.3%." "Likely safe for most adults; contraindicated with X."
This is counterintuitive because certainty *feels* more trustworthy. If I'm asking an oracle for an answer, I want *the answer*, not a confidence interval. But certainty is what sycophantic AI gives you, and it's what every corrupted oracle eventually sells. The hedge is the tell. An oracle that says "I'm not sure" is an oracle that's optimizing for accuracy over comfort. That's the one you want. [Recent research](https://aiinstitute.hbs.edu/the-surprising-link-between-ai-reasoning-and-honesty/) suggests this is structurally real — when AI systems reason before answering, they become measurably more honest, not because the reasoning argues them into it, but because honesty turns out to be a stable attractor and deception a fragile peak that deliberation knocks over. The hedge isn't just a good look. It might be the architecture working as intended.
---
## The four species
Four species, and everything I look at fits one:
**Prophetic oracles** predict what hasn't happened yet. Stock pickers, weather forecasters, the Delphic priestess. Can't show their work because the work is intuition or modeling of inherently uncertain systems. Trustworthy only via track record. Most aren't.
**Computational oracles** process more data than you can. Credit rating agencies, truth refineries, diagnostic AI. They *can* show methodology, and the good ones do. Trustworthy when incentive-separated and auditable. Dangerous when the entity being scored pays for the scoring.
**Consensus oracles** aggregate signal from many sources. Reddit, Wikipedia, blockchain oracles (Chainlink), Rotten Tomatoes. Trustworthy when the consensus is hard to game. Fragile when motivated actors can flood the input.
**Captured oracles** started in one of the first three categories and slid into corruption. Not through malice — through incentive drift. Moody's was a computational oracle that got captured by its revenue model. Google was a consensus oracle that got captured by advertising. Grokipedia is a computational oracle that declared its corrective intent upfront — more transparent about its biases than most, but with fewer structural guardrails against over-correction. The slide from trusted to captured is usually gradual, rarely intentional, and almost never reversed.
The scary insight is that **every oracle trends toward capture unless something structural prevents it.** Incentive drift is the default. Consumer Reports has held for 90 years because the no-advertising rule is constitutional, not policy — it's in their charter, not a best practice someone can waive in a tough quarter. UL has held because the testing standards are published and the manufacturers don't pick their own testers. The oracles that survive are the ones where the integrity mechanism is *structural* — built into the architecture, not left to good intentions.
---
## The oracle's oracle
If AI agents start mediating decisions (and they already are — shopping, booking, researching, recommending), those agents need oracles too. An AI agent deciding which flight to book for you needs a source of truth about prices, timing, seat quality. An agent evaluating a supplement claim needs a source of truth about clinical evidence. An agent checking whether a promo code works needs an oracle for that — and even that question isn't as binary as it sounds. The code exists, sure, but does it work for *this* user, with *this* cart, at *this* moment? The truth is conditional. And an agent deciding whether a $48 vitamin C serum is meaningfully different from a $12 one needs something deeper still — an oracle that's deconstructed the physics of the category itself. What does vitamin C stability actually require? What concentration matters? What delivery mechanisms have clinical evidence? The code question is conditional. The product question is structural.
But AI agents don't have dopamine. They can't be emotionally manipulated by "only 2 left!" or influenced by a clean brand aesthetic. They're going to route to whichever oracle gives them the most reliable signal. Which means the oracle game is about to get a lot more structural and a lot less vibes-based.
I wrote about [the dopamine layer](/notes/the-dopamine-layer/) a few weeks ago — the three layers of noise between a person and a good decision. The attention layer selects what you see. The dopamine layer makes it feel urgent. The rationalization layer helps you construct a case for the emotional decision you've already half-made. Oracles sit upstream of all of that. The oracle is the thing telling you what's true *before* the noise layers get involved. Which is why a compromised oracle is worse than no oracle — it poisons the input, and everything downstream inherits the distortion.
In the agent era, the question isn't "how do we build AI that's less manipulable?" It's "which oracles will the AI trust, and what makes those oracles earn it?" Agents will do what humans can't: actually audit methodology, compare track records across providers, and switch to a better oracle the moment accuracy drops. The oracle market is about to get *competitive* in a way it never was when humans were the consumers, because humans are loyal and lazy and biased toward the familiar. Agents aren't loyal or lazy — but they'll be infrastructure-biased. They'll trust whatever's cheapest, cached, integrated, or contractually preferred. Different failure mode, same drift. The oracle that wins with agents isn't the one with the best marketing — it's the one with the most auditable track record. But "auditable" can be gamed too.
That's either terrifying or exciting depending on whether your oracle is trustworthy or just popular.
---
## Where the oracle stops
Not all claims live in the same epistemological neighborhood.
A promo code works or it doesn't. A serum contains retinol at 0.5% or it doesn't. A sunscreen's SPF passes an independent lab test or it doesn't. These are the oracle's home turf — testable, falsifiable, receipt-shaped. The corn grew or it didn't.
Move one step out and the ground is still solid but the shape changes. A beauty brand redesigns its packaging to [mono-material tubes](https://iliabeauty.com/pages/bundles) and publishes the data: 46% reduction in carbon emissions, 20% less waste. A company's 990 filings show exactly where its charitable donations went. A retailer pulls a product from shelves before regulators require it. These are verifiable actions — not opinions, not claims of virtue, just documented behavior. But they *imply* something about values without the oracle having to say what.
Certifications occupy a similar zone, and they're worth pausing on because they're oracles in their own right. COSMOS processes ingredient data against published standards and outputs a verdict. Credo's Clean Standard gates which brands get shelf space. [COSMOS maintains a public enforcement log](https://www.cosmos-standard.org/) that documents decertifications — a brand that lost its stamp for inadequate supply chain traceability is generating a different kind of receipt than one that's held certification for a decade. An oracle can verify all of this: the certification exists, the enforcement history is clean, the standard was met. Receipt about a receipt. Solid ground.
But notice how quickly the ground softens. "How meaningfully does this brand exceed the standard?" is a different question than "does this brand hold the certification?" A brand that barely clears the threshold and a brand that proactively reformulates ahead of standard updates are both "certified." The oracle can surface both facts. It cannot tell you which one should matter more to you — because that depends on what you're optimizing for, and that's yours.
And then there are claims that aren't really claims at all — they're identities. "This brand is ethical." "This company is a good ally." "This product is clean." These depend on definitions that shift by person, by community, by year. "Clean beauty" has no legal definition. Two people can look at the same ingredient list — same formulation, same certifications — and draw opposite conclusions about what they consider safe. The moment an oracle renders a verdict here, it's stopped being an information engine and become something else. A priest, maybe. A marketer, definitely.
The line between these layers matters because crossing it is almost always invisible and almost always gradual. Nobody announces "today we start rendering moral judgments." It happens one feature at a time — a "clean" badge here, a "sustainable" score there — until the oracle is quietly doing synthesis it never meant to do. And the problem with that drift is structural, not moral: the consumer can't tell the difference between an oracle that says "this brand is ethical" because it is and one that says it because the brand is a paying partner. That's not cynicism. That's the oracle problem in its purest form — the same asymmetry that makes the oracle valuable makes its motivations uncheckable.
The oracle that lasts is the one that knows where it stops. Receipts, not verdicts. Evidence, not synthesis. The meaning is yours.
---
## The question I'm sitting with
I work at a company building what we call a truth layer for commerce — two surfaces of the same commitment. One verifies whether the promo code works at checkout — not "does this code exist" but "does it work for this user, with this cart, right now." Conditional, testable, receipt-shaped. The other deconstructs the physics of product categories themselves — the ingredients, the formulations, the claims, the clinical evidence, the gap between what a brand says and what the chemistry supports. [SimplyCodes](https://simplycodes.com) is the code oracle. [Product.ai](https://product.ai) is the product oracle. Same architecture underneath: verify the claim, score the confidence, show the receipts, and don't let the merchant's ad spend influence the truth score.
I believe in it — not as marketing language, but as an architectural commitment.
But I also know the Moody's people believed in their methodology. I know early Google believed in "don't be evil." I know every captured oracle started with good intentions and drifted through incentive pressure so gradual that nobody noticed until the trust was already gone.
I can name the specific temptations. A merchant who drives 20% of revenue wants their codes prioritized — not fraudulently, just... favorably weighted. An enterprise client wants a confidence score that makes their product page look better than the chemistry supports. Growth pressure makes it easier to quietly stop penalizing stale codes because the coverage numbers look better with them in. An advertiser wants to know why their competitor's truth score is higher, and the conversation drifts toward "what would it take to close that gap" in a way that sounds like consulting but smells like capture. These aren't hypothetical. These are the Tuesday afternoon versions of what happened to Moody's. And there's a subtler version: [fine-tuning AI on specialized data can degrade the reasoning that made it honest in the first place](https://aiinstitute.hbs.edu/faithfulness-and-accuracy-how-fine-tuning-shapes-llm-reasoning/). You don't have to corrupt the oracle. You just optimize it until the deliberation that kept truth stable gets tuned away.
So the question isn't whether we *want* to build a trustworthy oracle. Everybody wants that. The question is whether we've built the structural conditions that make trustworthiness *survivable* — the kind that holds when those Tuesday afternoon conversations happen, and someone in the room has the standing and the architecture to say no.
The farmer didn't trust the almanac because the almanac had good values. The farmer trusted the almanac because last year's frost prediction was right, and the year before that, and the year before that. The receipts were the trust. Everything else was just words.
My daughter will stop using me as an oracle someday. She'll learn to look things up, evaluate sources, form her own judgments. The three-year-old's unconditional trust will be replaced by something more provisional and more earned. That's healthy. That's what growing up means.
The question is whether our oracles are growing up too — or whether we're still in the phase where we believe them just because they sound confident. And the sign of a grown-up oracle isn't that it has all the answers. It's that it knows which questions aren't its to answer.
---
*Previously: [The Dopamine Layer](/notes/the-dopamine-layer/) explored the three layers of noise between consumers and good decisions. This piece is about what sits upstream — the sources we trust to tell us what's true in the first place.*
### Defaults Are Decisions (2026-05-04)
URL: https://bristanback.com/posts/defaults-are-decisions/
> Every system has defaults. AI makes them more powerful and more invisible. The question isn't whether your system is biased — it's whose assumptions it's running on.
I built a [school data product](/posts/what-are-test-scores-worth/) for parents. The idea was simple: take publicly available test score data and make it useful — help families understand what a school's numbers actually mean, not just whether they're high or low.
The data broke along demographic lines almost immediately.
Not in a way that surprised me — I knew the research. But there's a difference between knowing that test scores correlate with income and race, and *seeing it* in your own product, in the thing you built, where the default sort order puts certain schools at the top and others at the bottom. I hadn't decided to rank anything by demographics. I'd just used the available data, applied a reasonable scoring model, and the defaults did the rest.
I sat with that for a while. Not the policy question — the feeling. The specific discomfort of building something that does exactly what you told it to, and realizing what you told it carries more than you thought. I wasn't being careless. I was being default. And the defaults weren't mine — they were the system's, inherited through the data, and I'd passed them through without examining them.
That's the thing about defaults. They feel neutral. They're not.
---
I've always believed wealth is skewed toward preexisting capital. That's not a political statement — it's compound interest. Capital accrues to capital. The AI version is the same physics: **context accrues to context.** If you already have clean data, strong documentation, and engineering culture, AI makes you better faster — which generates more data, which improves your context, which accelerates the flywheel. If you don't have those things, AI doesn't help you catch up. It widens the gap at the rate the flywheel spins.
This plays out at every level. The individual who already knows how to prompt gets more from AI, learns faster, becomes more valuable. The one who doesn't falls behind at the rate the other one accelerates. The company with clean architecture deploys agents effectively. The one with messy foundations can't even start. The country with digital infrastructure benefits. The one without it doesn't just miss out — the gap compounds.
Compounding systems amplify their starting conditions. That's true of capital markets. It's true of codebases. And it's true of who AI serves.
---
## The Conversation We're Having (and the One We're Not)
When people talk about inclusivity and AI, the conversation usually falls into one of three lanes.
**Bias in training data** — facial recognition with [order-of-magnitude error rate differences](https://pmc.ncbi.nlm.nih.gov/articles/PMC12621103/) across skin tones, language models encoding stereotypes. Measurable, auditable, where the most obvious harm lives.
**DEI governance** — [responsible AI frameworks](https://www3.weforum.org/docs/WEF_A_Blueprint_for_Equity_and_Inclusion_in_Artificial_Intelligence_2022.pdf), audit checklists, review boards. Necessary infrastructure, but it frames inclusivity as a compliance layer rather than a design question.
**Inclusive design** — Kat Holmes' [*Mismatch*](https://mitpress.mit.edu/9780262539487/mismatch/) (2018) is the closest to what I'm trying to say: exclusion isn't a failure of the system, it's a feature nobody chose consciously. But Holmes was talking about doorknobs and interfaces. A poorly designed doorknob excludes one person at a time. A system prompt excludes everyone it touches.
What I'm not seeing is the framing I keep circling: **inclusivity as architectural debt**. Not bias as a bug. Not diversity as a box. But defaults as structure — reasonable decisions that compound into a system that serves some people well and others not at all, the same way technical debt compounds into a codebase that works but nobody can change.
That's the conversation I want to have.
---
This isn't abstract to me. When I [[The Context Engineering Stack|build a context engineering stack]], I'm deciding whose knowledge gets surfaced. When my team writes system prompts, we're deciding what "helpful" sounds like, what "professional" means, what kind of questions are worth answering and which get deflected. When we choose training data or select which documents go into the RAG pipeline, we're deciding whose experience counts as ground truth.
None of these feel like inclusivity decisions. They feel like engineering decisions. That's what makes them powerful.
---
## The Architecture of Who Gets Served
I've spent twelve years watching a codebase grow. One of the things you learn over that much time is that early decisions become invisible. The database schema from 2014 still shapes what's easy and what's hard to build. The API conventions from 2016 still determine how new engineers think about the product. Nobody chose these as permanent constraints. They were reasonable defaults that calcified.
Inclusivity works the same way in systems. The early decisions — whose use cases get prioritized, whose language patterns train the model, whose workflows define "normal" — become the bedrock. Not because anyone decided to exclude. Because someone decided to include *specific things*, and everything else became an edge case.
AI amplifies this. A human team making exclusionary defaults affects the people who use their product. An AI system trained on those defaults reproduces them across every interaction, without the human friction that might cause someone to pause and say "wait, this doesn't feel right."
I keep coming back to something from my [[Design Physics: When Interfaces Meet Agents|design physics]] essay: constraints shape what's possible. In Q2 — humans designing for agents — the constraints you set determine what the agent can do. But they also determine *who the agent serves well*. A tool schema that assumes English. A system prompt that defines helpfulness through a Western professional lens. A context window that prioritizes recent documentation over historical context. Each is a constraint. Each is a decision about who belongs inside the system's assumptions.
And like all architectural decisions, inclusivity debt compounds when nobody's paying attention. A team launches a product with reasonable assumptions about their users. Each feature optimizes for that user base. Each A/B test reinforces that demographic's behavior patterns. Over time, the product becomes deeply, invisibly optimized for a specific kind of person — not because anyone decided to exclude, but because every small decision was *reasonable* and *data-driven* and *for the users they had*. The users they didn't have never generated the data that would have changed the defaults.
---
## Where I've Felt This
Early in my career, I'd join a codebase and immediately absorb its conventions — naming patterns, architectural opinions, the unspoken rules about where things go. I was good at it. People thought I ramped up fast. What I was actually doing was erasing my own instincts and replacing them with whatever the system already believed.
My [[Learning to Take Up Space|default mode]] is disappearance — mold yourself to fit what's already there, read the defaults before anyone tells you they exist. In code, that meant I didn't push back on an API design I found confusing, because I assumed the confusion was mine. Didn't suggest a different data model, because the existing one had momentum and who was I to question it.
Years later, as an architect, I started to see those same unquestioned defaults from the other side. The API I'd found confusing *was* confusing — but it had been designed by people who shared enough context that the confusion was invisible to them. The data model I hadn't questioned encoded assumptions about our users that hadn't been true for years. My instinct to adapt had been useful for me. It had been terrible for the system. The system needed someone to say *this doesn't work for people like me*, and instead I'd said *I'll figure it out*.
That's the personal version of what happens systemically. When a team builds a product, they build it for the people in the room. The defaults reflect their assumptions, their contexts, their definition of normal. When someone outside that circle uses the product, they adapt — learn the system's language instead of the system learning theirs. And the system never gets the feedback that would change it, because the people who don't fit have already learned to stop saying so.
AI makes this more acute, not less. A human on the other end might pick up on context clues and adjust. An AI agent applies the same defaults to everyone, every time. That's consistency. It's also erasure, if the defaults weren't built for you.
---
## The Hiring Loop
Nowhere does this compound faster than hiring.
A job description is a system prompt for humans. It encodes what the team already looks like and calls it "requirements." Ten years of experience — that filters out career changers, parents who took time off, anyone whose path wasn't linear. "Culture fit" — that's literally encoding existing culture as a hiring gate, which means you select for people who match the defaults you already have.
I've watched this loop from the inside for twelve years. Early on, I sat in interviews where "strong communicator" meant someone who sounded like the engineers already on the team. I've seen referral pipelines that worked great — if you already knew people who looked like the people we'd already hired. It's not malicious. It's not even conscious most of the time. You hire people who remind you of people who've succeeded before. You calibrate "good interview" against the communication style of your existing team. You promote the signals that correlated with success in *your* system, not in the world. Each decision is reasonable. The compound effect is a team that looks increasingly like itself.
Now add AI to the loop.
AI résumé screening tools are trained on historical hiring data — which means they learn who you've *already* hired and pattern-match for more of the same. Amazon [famously scrapped](https://www.reuters.com/article/us-amazon-com-jobs-automation-insight-idUSKCN1MK08G/) an AI recruiting tool because it penalized résumés containing the word "women's" — it had learned from a decade of predominantly male hires. The tool was working correctly. The defaults were the problem.
AI interview analysis has defaults about what "confident" and "articulate" sound like. Whose communication style is the baseline? AI-generated job descriptions reproduce the language patterns of existing postings — and research consistently shows those patterns are [gendered](https://gap.hks.harvard.edu/evidence-gendered-language-job-advertisements-exists-and-sustains-gender-inequality): "ninja," "rockstar," "aggressive" skew male applicants; "collaborative," "supportive" skew female.
The hiring pipeline is the purest example of defaults-as-architecture because it's self-reinforcing. Homogeneous team → defaults reflect that team → hiring filters for people who match → more homogeneous team → defaults calcify further. Each cycle is data-driven. Each cycle is reasonable. The exclusion isn't a decision anyone made. It's the decision nobody examined.
---
## Who Operates, Who Gets Operated On
There's one more layer I keep thinking about: who's using AI, and who's having AI used on them.
Right now, the people operating AI agents — prompting, building, steering — are overwhelmingly technical, English-speaking, already-privileged knowledge workers. Prompting skill correlates strongly with existing education, language fluency, and access. If AI is the new literacy, the most capable versions of it are still largely behind paywalls. A class marker is forming. "I shipped this with Claude Code" is becoming what "I can code" was in 2010.
Meanwhile, AI augments the people who already have leverage — architects, senior engineers, people with context and judgment — and displaces people who were doing execution. The displacement concentrates in roles that are often more diverse: customer support, data entry, junior positions that were historically the on-ramp.
So there's a split forming: some people use AI, and other people have AI used *on* them. Hiring screens. Credit decisions. Content moderation. Insurance assessments. The operators set the defaults. The operated-on live inside them.
That split maps onto existing power lines with uncomfortable precision. And it means the defaults-as-decisions problem is about who gets to build the systems, not just how to build them better.
---
## What It Looks Like to Try
At [Product.ai](https://product.ai), where I've spent the last twelve years, we're building an AI commerce intelligence product — the kind that tells you whether a product is worth buying. The defaults question isn't theoretical for us. It's the product.
When we build a recommendation system, someone has to decide what "good" means. Is the best sunscreen the one with the highest SPF? The most cosmetically elegant? The one that doesn't leave a white cast on dark skin? The one that's reef-safe? The one under $20? Every one of those is a reasonable default. Every one of them serves a different person. And if you pick one without thinking about who you're picking *for*, you've made an inclusion decision without knowing it.
Our first deep category launch is skincare. That's deliberate. It's a category where the defaults are particularly wrong — most recommendation systems assume a narrow range of skin types, tones, and concerns. "Best sunscreen" lists that don't account for how mineral sunscreens perform on dark skin. "Best retinol" without acknowledging that sensitivity varies dramatically by ethnicity and hormone status. The existing defaults serve one user well and everyone else gets "it works for most people."
So we made some architectural choices. We separated truth from preference — there's a layer that establishes what's verifiable about a product (its formulation, its clinical evidence, its tradeoffs), and a separate layer that personalizes based on your situation. Your preferences can change what you *see*. They can never change what's *true*. That boundary is enforced in the architecture, not in a policy doc.
We separated revenue from ranking. Our affiliate data and our recommendation logic run on different code paths — not because we trust ourselves to be fair, but because we *don't*. If commission rates can influence what we recommend, they eventually will. So we made it structurally impossible. The system will tell you not to buy something we'd earn money on, if the evidence says it's wrong for you. About a fifth of our interactions are some version of "don't buy this." If a system never says no, you can't trust when it says yes.
And we brought in domain experts — formulation chemists, dermatologists, people who've actually tested these products across a range of skin types — not as beta testers but as co-creators of the knowledge base. The inclusion isn't a checkbox. It's an epistemological requirement. You can't build accurate intelligence about skincare from a narrow sample any more than I could build a fair school ranking from test scores alone. The truth is literally incomplete without diverse inputs.
I'm not claiming we've solved this. We're launching. We'll discover defaults we didn't examine — I'm sure of it. But the lesson from SchoolScope stayed with me: if you wait to discover your blind spots from user complaints, you'll only hear from the users who stuck around long enough to complain. The ones the system failed worst left without saying anything.
---
## What Architecture Can Do
The places that seem to get this less wrong share a pattern: they treat the absence of feedback as a signal, not as silence.
The deepest problem with default-driven exclusion is that the people being excluded don't generate the data that would change the defaults. They leave. They find a workaround. They adapt. The system never learns. So the question I've started asking in my own work isn't "is this biased?" — it's *who can the system not hear right now?* Not satisfaction surveys — those measure the satisfied. Friction logs. Accessibility reports. The edges talking back to the center.
The same instinct applies to teams. Different lived experiences produce different default assumptions. A team that includes people who've been on the wrong side of a system's defaults will *notice* the defaults that a homogeneous team treats as neutral. That noticing is an engineering skill, not a diversity checkbox. The system prompt review, the context pipeline audit, the question of whose definition of "helpful" you shipped — these are design review questions with the same stakes as any architectural decision.
Inclusivity in AI isn't a separate concern from system design — it *is* system design. The same skills that make a good architect — examining assumptions, questioning defaults, thinking about who the system serves and who it doesn't — are the skills that make an inclusive one.
The difference between engineering and exclusion is whether you examined the default before you shipped it. When we call something "engineering" we scrutinize it, we review it, we test it. When we call something a "default" we let it pass.
Inclusivity debt is technical debt for who gets served. It compounds the same way. It resists cleanup the same way. And like all architectural debt, the most expensive kind is the kind you don't know you're carrying.
---
I think about the school data product sometimes. The sort order that put certain schools at the top. I changed it — eventually. But the thing I remember most is how long it took me to see it. Not because I wasn't looking. Because the default felt like the data, and the data felt like the truth, and I was the one who'd chosen what "truth" looked like.
Context accrues to context. The defaults will compound either way. The only question is whether you examined them before they became the architecture — or whether you're still calling them neutral because nobody's told you otherwise.
### What Are Test Scores Actually Worth? (2026-04-16)
URL: https://bristanback.com/posts/what-are-test-scores-worth/
> I built a school data product for parents. What I built, how my thinking evolved, what an axiom actually is, and where the data runs out.
> [!aside] This post is a companion to a talk I gave at [The Kinn](https://thekinn.co/) in Venice — an AI Café fireside chat called "Stop Coding, Start Thinking." The talk covered the shift from writing code to defining constraints, and how we use axioms and context engineering at [Product.ai](https://product.ai). This is the side-project version of that same story.
I have a three-year-old. In a couple of years, she'll be in kindergarten. I was standing in the parking lot after a school event, talking to another parent about schools in our area — the usual anxiety spiral: which ones are good, what do the ratings mean, should we move. Normally I'd jot something down and never follow up. Instead, I pulled out my phone, opened Telegram, and asked Lunen — my always-on AI assistant running on a Mac Mini at home via [OpenClaw](https://openclaw.ai) — to pull the state test data and rank schools near us against the state average. By the time I got home, I had something useful.
The list was interesting. But the questions it raised were more interesting. What *are* these scores measuring? Why do the top schools all look the same demographically? What's the actual difference between a school rated 7 and a school rated 8?
That conversation became [SchoolScope](https://schoolscope.co) — a school performance analysis tool for California. It's still a side project, but it's grown into something with its own methodology, grounding documents for 25 states, a system of axioms, and a few hundred commits.
It's also a testbed. At [Product.ai](https://product.ai), where I'm Chief Architect, I can't break things — we process hundreds of millions of events a day. SchoolScope is where I work fast, break things, and stress-test every new feature Anthropic ships in Claude Code that week. The thinking patterns that survive here are the ones I bring back to the team. The tech stacks are completely different (oRPC, Cloudflare Workers — things we'd never adopt in production), but the methodology transfers.
Here's how my thinking evolved, and where it falls short. It's also a microcosm of the shift I've been living at Product.ai: from writing code to defining constraints, from optimizing prompts to engineering context.
---
## Phase 1: Test Scores Are Everything
The starting assumption was simple. California publishes CAASPP results — standardized test scores for every public school, broken down by grade, subject, and subgroup. It's the closest thing to an objective, comparable data point across thousands of schools. GreatSchools uses it. Niche uses it. If you're going to rank schools, this is the raw material.
So I pulled the data. Built a composite score. Started ranking schools.
And almost immediately, something felt wrong.
The top-ranked schools were overwhelmingly in wealthy neighborhoods. The bottom-ranked schools were overwhelmingly in disadvantaged communities. The correlation between test scores and household income was so strong that you could practically predict a school's ranking from its zip code.
This isn't a discovery — anyone who's looked at school data knows this. But building the ranking system myself made the mechanism visceral. I wasn't just reading about the demographic proxy problem. I was *producing* it. My algorithm was taking public data and generating a leaderboard that mostly reflected where rich families live.
The data was technically correct. The output was generically "good." And it was specifically wrong for what I wanted to build. If that sounds familiar — it's the same problem I hit at Product.ai when we tried to prompt-engineer our way to good code. The AI's version of "best practices" is an average of the internet. Your version is specific to your context. Without that context, you get plausible garbage.
---
## Phase 2: What Are All the Signals?
So I started asking: what else is there? What does the state actually publish?
It turns out — a lot more than test scores:
- **Chronic absenteeism** - students missing 10%+ of school days. At the elementary level, this is less about kids skipping and more about family engagement, school culture, community stability. A school with high test scores and high absenteeism is telling you something different than one with high scores and low absenteeism.
- **Suspension rates** - and specifically, how they vary by subgroup. A school that suspends Black students at 3x the rate of white students has a discipline philosophy worth understanding, regardless of its test scores.
- **Growth trajectory** - not just "how did students score?" but "did students at this school improve over time?" A school that takes kids from 30% proficiency to 50% is doing harder, more valuable work than a school maintaining 90%. One measures what families bring. The other measures what the school *does*.
- **Graduation rates** and **college readiness indicators** - for high schools, whether students actually complete a-g requirements, pass AP exams, complete CTE pathways.
- **Teacher stability** - credential status, years of experience. High turnover is a red flag. But you can't *score* this without penalizing schools in hard-to-staff areas, which are - surprise - the same disadvantaged communities that already get penalized on test scores.
- **Per-pupil spending** - from NCES federal finance data. Context, not a score input. A school spending $8,000 per student is operating in a fundamentally different reality than one spending $20,000.
Each of these is a lens. None of them alone tells you if a school is "good." Together, they start to tell you something more honest.
But now I was making judgment calls about what matters — which meant I needed a system for encoding those judgments.
---
## Phase 3: Axioms, Grounding, and Encoding Judgment
An axiom, the way I use the term, is an almost-immutable truth you've decided to build on. Not a guideline. Not a suggestion. A constraint with teeth. Constraints are crystallized taste — someone has to decide what matters, what's non-negotiable, what variance is acceptable. That's the part AI can't do for you.
At Product.ai, we develop axioms through the [Axiomatic Distillation Protocol](https://michaelquoc.com/physics/arc-protocol/) — exploring a question across multiple AI models, testing conflicting answers against each other, and distilling what holds up. For SchoolScope, the axioms came from staring at the data and making calls:
- **"Exceeded > Met."** The gap between "met standard" and "exceeded standard" is the most meaningful signal in school performance data. It separates schools that clear the bar from schools that raise it.
- **"Growth > Proficiency."** A school that takes kids from 30% to 50% proficiency is doing harder work than one maintaining 90%. Growth measures what the school contributes. Proficiency measures what families bring.
- **"Absenteeism Is Culture."** Chronic absenteeism at the elementary level isn't about kids being "smart enough to skip." It's family engagement, school culture, community stability.
- **"No quantitative claims without measuring them."** If we say a school is in the 85th percentile, the methodology page explains exactly how percentiles are computed, and the explore page lets you verify by sorting.
- **"We don't penalize schools for serving disadvantaged communities."** Score colors are blue-to-amber, not red/green. Labels say "Needs Support" not "Failing." Growth is weighted because it measures the school, not the zip code.
These axioms live in Markdown files in a `grounding/axioms/` directory. Every AI agent that touches the codebase reads them before writing a line of code. They're the constitution of the product.
### State grounding documents
Each state gets its own grounding doc - a comprehensive Markdown file that describes everything: what test the state uses, where the raw data lives, what format it's in, what the performance levels are called, what's available and what's missing. California's is the most developed. Texas (STAAR), New York (Regents), Florida (FAST) - each has different tests, different file formats, different quirks. I've written grounding documents for 25 states so far.
California's specifies file formats (caret-delimited, Latin-1), encoding changes between years, WAF restrictions on automated downloads, COVID data gaps. These aren't things you want an AI agent to discover by trial and error.
Each state also gets a **config file** in TypeScript:
```typescript
// src/config/states/ca.ts
export const CA_CONFIG = {
state: "CA",
testName: "CAASPP Smarter Balanced",
performanceLevels: ["Exceeded", "Met", "Nearly Met", "Not Met"],
levels: {
elementary: {
grades: [3, 4, 5],
composite: {
exceeded: 0.43,
metAbove: 0.22,
growth: 0.15,
absenteeism: 0.10,
suspension: 0.05,
elpac: 0.05,
},
},
// middle, high...
},
};
```
When Texas launches, it gets `tx.ts` with STAAR equivalents. The import pipeline reads the config. The agents read the config. Nobody hardcodes "CAASPP" anywhere. The architecture is designed so a new state is a new config file and grounding doc - not a rewrite.
### The Scope Score
The composite weights those axioms into a number. At elementary: exceeded 43%, met+above 22%, growth 15%, absenteeism 10%, suspension 5%, ELPAC 5%.
Every one of those weights is an opinion. The methodology is public. Every weight is explained. Every limitation is stated. If you disagree — and reasonable people should — the whole point is that you can see the machinery. GreatSchools gives you a 1-10 number with no escape hatch. I wanted the opposite: here's the score, here's exactly why, here's what it can't tell you.
I also built **archetypes** - labels like "Growth Engine" (low raw scores but strong improvement), "High Ceiling" (exceptional exceeded rates), "Steady Foundation" (consistent across metrics). These turned out to be more useful than the number itself. A parent looking at a "Growth Engine" school understands something a percentile rank can't communicate: *this school is doing real work with the students it has*.
---
## Phase 4: Where It Falls Short
Here's the honest part.
**Test scores correlate with demographics.** I've done everything I can to mitigate this - weighting growth, contextualizing with spending, showing equity gaps by subgroup, never using diversity metrics as scoring inputs, choosing "Needs Support" over "Failing" as labels. But the correlation doesn't go away. A composite that includes test scores will always partially reflect who walks in the door — it can never fully isolate what happens inside.
**Pseudo-cohort isn't true cohort.** I actually built something better than cross-sectional: when historical data is available, I track the same school's cohort across years - 2023's 3rd graders measured again as 2025's 5th graders, using SBAC scale scores designed for cross-year comparison. 98% of elementary schools have this data. It's stronger than what most rating sites do (comparing different students at different grades in the same year). But it's still "pseudo" - I'm tracking school-level averages, not individual students. Kids transfer in and out. It's the closest thing to true value-added measurement available from public data, and it's still imperfect.
**I can't measure what matters most.** Teacher quality. School culture. Whether the art program is any good. Whether your kid will have a friend. Whether the principal actually cares. The data captures outcomes that are measurable across thousands of schools. The things parents care about most are the things that don't fit in a spreadsheet.
**Small schools get smoothed.** A school with 15 test-takers can swing wildly year to year. I apply Bayesian smoothing toward the state average to prevent noise from distorting rankings. That's statistically sound and experientially unsatisfying - it means small schools get pulled toward mediocrity in the data even when they're exceptional in practice.
**Private schools are a black box.** 2,452 private schools in California from the NCES survey. No test scores. No growth data. No chronic absenteeism. I show enrollment, student-teacher ratio, religious affiliation - but I can't rank them alongside public schools. The data doesn't exist to do it fairly. I'd rather show an honest "we don't have enough data to score this school" than manufacture a number.
**High school scores lack growth data.** California only tests 11th graders in high school - there's no earlier grade to compare against within the same level. So the growth trajectory signal that's most powerful at elementary and middle school doesn't exist for high schools. The Scope Score still works, but it's a less complete picture.
---
## What I Actually Believe Now
Test scores are the *least bad* objective measure we have. They're real. They're standardized. They're published. You can compare across schools. That matters - especially when the alternative is GreatSchools' black box or Niche's stale federal data supplemented by sparse user reviews.
But they're one lens. I put that line on every page of SchoolScope, and I mean it. A school that scores in the 40th percentile but has strong growth, low absenteeism, and stable teachers might be a better fit for your kid than a 90th percentile school with high suspension rates and demographic sorting.
The real value isn't the number. It's the *structure* around the number - the context, the comparison, the honesty about limitations. The prompt is what you say to the contractor. The constraints are the building code. SchoolScope's axioms are the building code. A parent who understands that "Exceeded" matters more than "Met," that growth measures the school and proficiency measures the neighborhood, that chronic absenteeism is a culture signal - that parent is making a fundamentally different decision than one staring at a single rating.
I built this because I'll need it soon. My daughter will be in the system in a couple years, and I want to make the decision with real information, not marketing. I've seen how the sausage gets made now — I know what a 7 versus an 8 actually means, and more importantly, what it doesn't mean. I know that a school with strong growth and low absenteeism in a working-class neighborhood might be doing better work than the 9-rated school in the hills. I want that context when it's my kid.
But I also built it because the process changed what I think "real information" means. It's not more data. It's more honest data — data that tells you what it knows, what it doesn't, and where you need to go look for yourself. The number is never the answer. The number plus the context plus the limitations plus the visit plus the gut feeling — that's getting closer.
Let me be real: it's a toy project. Handful of hits a day. I have no idea if I'll invest more time in it. But it taught me something I preach at Product.ai and didn't fully feel until I built this: having a great product means nothing if no one sees it. GreatSchools has brand recognition, backlinks, and a decade of SEO. I have better data and zero distribution. The marketing, the storytelling, the networking — that's the actual hard part. Execution got cheap. Attention didn't.
I used to say it's not about the idea, it's about the implementation. I don't say that anymore. The doing got cheaper. The deciding got more valuable. And the decisions are only as good as the constraints you write down before the first line of code gets generated.
---
## How It's Built
SchoolScope is a side project built in stolen hours - evenings, weekends, naptime. I wrote approximately zero lines of code by hand, which sounds like a flex but is really about the architecture. I wrote constraints, specs, and axioms - the grounding documents I described above. AI coding agents read those documents and build within them. The constraint engineering follows what I think of as a three-layer model: constraints bound the space, prompts express intent, code is what emerges.
When I wanted to add per-pupil spending data, I didn't open VS Code. I wrote a spec, then dispatched two AI agents in parallel - one to build the data pipeline (download NCES F-33 finance data, parse it, match districts to schools), one to build the UI (spending cards on school profiles, district pages, state comparison). Both agents read the grounding documents. Both ran in parallel. The feature was live in about two hours.
Then I noticed the spending data was three years stale - because we'd used an intermediary API that lagged behind the source. The raw NCES files with current data were sitting on ies.ed.gov the whole time. I dispatched a third agent to go direct to the primary source. Ten minutes later, the data was three years fresher than our competitors.
That mistake became an axiom: **"Always go direct to the agency. Never depend on intermediary APIs when the raw data is publicly available."** A lesson learned, codified, and now every future agent reads it before touching data imports.
That's how axioms work in practice. You make a mistake. You understand why. You write it down as a constraint. Every agent that comes after inherits the lesson. The axioms compound.
The full methodology is published at [schoolscope.co/methodology](https://schoolscope.co/methodology). Every weight, every data source, every limitation. If you think I weighted something wrong, I'd like to hear about it.
---
## How to Actually Set This Up
People ask how to get started with this. It's simpler than it sounds, and you don't need to be building a school data product. The same structure works for any project where AI is doing the building.
### Step 1: Write the project grounding file
Every major AI coding tool has a file it reads automatically when it opens your project — `CLAUDE.md` for Claude Code, `AGENTS.md` for Codex, `GEMINI.md` for Gemini CLI. The name varies; the purpose is the same. It's your project's self-portrait: what it is, how it's built, what conventions matter, where the important files live. Think of it as the onboarding doc you'd write for a new engineer — except the new engineer is an AI that reads every word and follows it literally.
Mine starts with what SchoolScope is, lists the tech stack, describes the data sources, and then has a section of rules: "Private schools are NEVER ranked alongside public schools. NEVER get a Scope Score." The caps aren't shouting — they're emphasis for a reader that doesn't have intuition.
### Step 2: Start with one axiom
You don't need a system of 50 axioms on day one. You need one. Build something, notice what's wrong with the output, and write down the constraint that would have prevented it.
My first real axiom was born from a mistake: I used an intermediary API for spending data that was three years stale when the primary source had current data. That became: **"Always go direct to the agency."** One sentence. Saved every future agent from making the same mistake.
The process is always the same:
1. Build something
2. Notice what's wrong — not technically wrong, but wrong *for your context*
3. Write the constraint that would have prevented it
4. Put it where the AI will read it before building again
Axioms accumulate. After a few weeks you'll have 5-10 that cover most of your recurring judgment calls.
### Step 3: Organize into a grounding directory
Once you have more than a handful of axioms, give them a home. My structure:
```
grounding/
axioms/
product-principles.md # What the product is and isn't
data-axioms.md # How we handle data
competitive-lessons.md # Mistakes competitors made that we won't
voice-axioms.md # How the product speaks
research/
competitors/ # What we learned studying alternatives
states/
ca.md # California-specific data sources and quirks
tx.md # Texas (different tests, different formats)
strategy/
JTBD.md # Who uses this and why
SEO_STRATEGY.md # How people find us
```
The directory names matter less than the principle: **separate what's universal from what's specific.** Product principles apply everywhere. State-specific data quirks apply to one import pipeline. When an agent reads `ca.md`, it knows that CAASPP files are caret-delimited in Latin-1. When it reads `product-principles.md`, it knows we never penalize schools for demographics. Both are constraints, but they operate at different scales.
### Step 4: Reference grounding docs from your project file
The project file (CLAUDE.md, AGENTS.md, etc.) is the entry point — the table of contents. The grounding directory is the library it points to. One tells the AI *this project exists and here are the rules*. The other gives it the deep context for specific domains. The project file tells the AI *which* grounding docs to read for *which* tasks:
```markdown
## Before You Start
- Read `grounding/axioms/product-principles.md` for product principles
- Read `grounding/strategy/JTBD.md` for audience context
- Read `grounding/axioms/data-axioms.md` before touching import scripts
```
This is the mechanism that makes axioms *enforced* instead of just documented. Without it, your grounding docs are a wiki nobody reads. With it, every AI session starts from your context instead of from zero.
### Step 5: Let them evolve
Axioms aren't stone tablets. They're living documents that sharpen as you learn. My data axioms have been rewritten three times. The product principles started as five bullet points and grew to a full constitution as edge cases appeared.
The key is treating them like code: version them, review the diffs, notice when they conflict. If two axioms pull in different directions, that's a design decision you haven't made yet. The conflict is the signal.
### The non-engineer version
If you're not writing code — if you're using Claude Projects, ChatGPT, or Gemini Gems — the same pattern applies, just simpler:
1. Write a one-page doc about what you do, who you serve, and what you won't compromise on
2. Upload it as permanent context in your AI tool
3. Every time the output misses something, add the constraint to your doc
4. Compare the output with and without your grounding doc — the difference is immediate
That's it. You're doing context engineering. The constraints compound from there.
---
*SchoolScope is live at [schoolscope.co](https://schoolscope.co). Side project, not affiliated with my employer. All data sourced from public agencies (California Department of Education, NCES, U.S. Census).*
### Your Infrastructure Spec Already Moved Into Your Code (2026-03-13)
URL: https://bristanback.com/posts/infrastructure-as-context/
> Infrastructure config is collapsing into application code — the same pattern as build tooling a decade ago. Void showed us the destination. The question is whether you want to ride the platform or steal the pattern.
Yesterday, Evan You stood in front of a camera, announced that [Vite+ is open source under MIT](https://voidzero.dev/posts/announcing-vite-plus-alpha), and then did the "one more thing." [Void](https://void.cloud/). A deployment platform where your code *is* your infrastructure. `void deploy` scans your source, detects what you use — database, KV, queues, cron, auth, AI inference — and provisions it. No config files. No dashboard clicks. Built on Cloudflare.
The reaction was predictable. Half the room said *finally*. The other half said *I'll never trust magic provisioning in production*.
Both are right. And neither is asking the real question.
## The Spectrum
Every infrastructure tool exists on a single axis: how far is the spec from your application code?
| Tool | Distance | What you write |
|------|----------|----------------|
| **Terraform / Pulumi** | Far — separate codebase | HCL modules or TypeScript stacks that mirror your architecture in a parallel universe |
| **Kubernetes / Crossplane** | Medium-far — declarative manifests | YAML custom resources reconciled by a control loop. Infra and app deploy from the same plane, but the spec is still YAML and the state model is still "desired vs. actual" with drift |
| **AWS CDK / SST** | Medium — adjacent code | TypeScript constructs that describe infrastructure, compiled to CloudFormation |
| **Wrangler / `wrangler.jsonc`** | Close — config next to code | A JSON file that tells the platform what bindings your Worker needs |
| **Encore** | Closer — inferred from code | `new SQLDatabase("orders")` in your app code provisions RDS automatically |
| **Void** | Closest — code *is* infra | Import a module, deploy. The platform figures out the rest |
The direction is unambiguous. The debate is about how fast to move.
## Why This Is Happening Now
Two forces are colliding.
**AI agents need coupled context.** To be fair: LLMs can generate decent Terraform. They can get most of the way there. And you can give an agent access to CLI tools — `gcloud`, `aws cli` — to inspect live configuration and validate it against the spec. It's not hopeless.
But here's the thing: your application code is *coupled* to your infrastructure. Your API needs that database, that queue, that KV store. The code won't work without them. Yet the spec that describes that infrastructure lives in a different file, maybe a different repo, written in a different language — HCL, YAML, CloudFormation JSON — with no compile-time check that the two agree. The coupling is real but the contract is informal. You don't find out they've drifted apart until deploy time, or worse, runtime.
YAML is the worst offender. It's not strongly typed. Terraform will catch syntax errors at `plan` before anything touches production — that part works. The dangerous failures are the ones that parse fine but mean the wrong thing. A misspelled key name is valid YAML. A missing environment variable is a valid ConfigMap. It deploys cleanly and breaks at runtime. No linter catches it because no linter knows what the key *should* be. That's why tools like Pulumi moved to real programming languages — TypeScript, Go, and Python (which is *technically* typed if you squint and believe hard enough) — where you get type checking, IDE support, and at least some compile-time guarantees. That was already the right instinct.
Pulumi got halfway there — real languages, real types. But you're still writing infrastructure *about* your application in a separate place. Encore and Void take the next step: infrastructure *inside* your application. `new SQLDatabase("users")` or `import { KV } from "void"` — the coupling becomes explicit. One codebase, one type system, one dependency graph. An agent isn't reasoning about two separate descriptions of the same system. It's reading the system itself. That's not a developer experience story. That's a *leverage* story.
**Developer time is too expensive for a parallel mental model.** A Terraform setup for a typical backend — database, Pub/Sub, cron — can run to hundreds of lines of HCL across multiple files. Someone has to understand, review, and update that code every time the application changes. For a five-person team without a dedicated DevOps engineer, that overhead competes directly with shipping product.
When your AI agent writes a feature that needs a new queue, and the queue requires a separate infrastructure PR with its own review cycle, you've created a serial bottleneck in what should be a parallel workflow. The infrastructure layer becomes a tax on the thing you actually care about: the product.
## The Layers Nobody Draws on the Same Whiteboard
Before I get further into this, I should name the thing I'm glossing over. That spectrum table above is really about *provisioning* — who creates the cloud resources. But provisioning is one of at least four distinct layers that are all collapsing simultaneously:
| Layer | What it does | Traditional tools | Where it's heading |
|-------|-------------|-------------------|-------------------|
| **Provisioning** | Create cloud resources (databases, queues, DNS) | Terraform, Pulumi, CloudFormation | Inferred from code (Encore, Void) |
| **Delivery** | Get code from repo to running state | ArgoCD, Flux, Spinnaker | Collapsed into deploy commands (`void deploy`, `sst deploy`) |
| **Pipelines** | Build, test, validate | GitHub Actions, CircleCI, Jenkins | The triggers and event orchestration still matter — but the work inside the workflow is shrinking as toolchains (Vite+) and platforms absorb it |
| **Developer Platform** | Service catalog, docs, onboarding | Backstage, Port, Cortex | Either absorbed into the deploy platform or generated from code |
Each of these layers has its own ecosystem, its own debates, its own conferences. And each one is independently moving in the same direction: closer to the application code, further from standalone config.
At large companies, these layers get split across teams — a platform team for Terraform, SRE for ArgoCD, a build team for CI. I've never worked at a company like that. I've been at a small engineering team — ranging from just me to maybe a dozen — for twelve years. Which means I'm all three of those teams, and I feel the coordination tax every time I ship: *I changed my application and now I have to update three separate systems to get it running.*
The collapse is about the *gap between layers* — the coordination cost of keeping provisioning, delivery, pipelines, and platform in sync with each other and with the application. Every time you add a queue to your app, you're touching Terraform *and* ArgoCD manifests *and* GitHub Actions workflows *and* maybe updating Backstage. The tools that are winning are the ones that eliminate the gap, not the ones that make any individual layer easier.
Void's bet is that all four layers collapse into one command — but only within Cloudflare's boundary. If your world fits on Workers, KV, D1, and Queues, you never touch another tool. The moment you need something outside that boundary — AWS RDS, GCP Pub/Sub, a managed Postgres that isn't D1 — you're back to Terraform for that piece, and the clean collapse gets messy. Encore collapses provisioning and delivery but deploys to your own AWS/GCP. SST collapses provisioning and pipelines on AWS. Each tool picks a different set of layers to absorb, and a different set of constraints to accept.
With that framing, the GitOps problem gets clearer.
## The GitOps Paradox
GitOps is specifically about the *delivery* layer — but it has a problem that bleeds into everything above and below it.
GitOps says: Git is the source of truth. You declare your desired state in YAML, commit it, and a reconciliation agent (ArgoCD, Flux) continuously syncs the cluster to match. Elegant in theory. In practice, [it breaks in ways that look like success](https://saraswathilakshman.medium.com/understanding-gitops-gone-wrong-a-practical-example-98963bbb5952).
The failure mode is always the same: someone commits a change, the sync goes green, health checks pass, and production is broken. A typo in a ConfigMap key name. A missing environment variable. A canary annotation that got forgotten. The system *synced perfectly to the wrong state*. ArgoCD doesn't know the difference between "DATABASE_CONNECTION" and "DATABASE_CONECTION" — it just reconciles what you told it.
The deeper problem is the model itself. GitOps treats Git as the authoritative truth about what your infrastructure *should be*. But Git is an archive — it captures what someone *intended* at commit time. The actual truth is what's running in the cluster right now. And there's always a gap between the two. Configuration drift isn't a bug in GitOps. It's the fundamental physics: desired state and actual state are maintained in different systems, synchronized by a polling loop. The gap is structural.
For a human DevOps engineer, that gap is manageable. You build validation webhooks, OPA policies, canary rollouts, manual sync gates. You add layers of defense between the commit and the cluster.
For an AI agent? The gap is workable but expensive. An agent *can* verify what it deployed — it can shell out to `kubectl`, `gcloud`, `aws cli`, read the cluster state, compare running config against intended config. I know because we have agents doing exactly that. It works.
But think about what that workflow actually is: commit YAML to a repo, wait for ArgoCD to sync, poll the cluster through CLI tools, parse the output, compare it against the original intent, flag discrepancies. It's a round trip through three separate systems to verify something that could have been a type error at compile time. The semantic check that GitOps defers to runtime is a check that infrastructure-as-code could catch at write time.
This is why the spectrum is collapsing toward code. Not because GitOps is wrong — it was a genuine advance over SSH-and-pray. But because the gap between "what I declared" and "what's actually running" becomes more dangerous as agents do more of the declaring.
## The Lock-In Trap
OK — so the spectrum is collapsing. But toward what? Here's where I get skeptical.
The more implicit the tool, the faster the onramp — and the less obvious the exit ramp. Void's zero-config is real. But what happens when you need to leave?
Evan's been upfront about this: you don't bring your own Cloudflare account. Resources are provisioned and managed by Void, not in your CF dashboard. The lock-in enables the magic DX — and the eject means migrating your data off their managed infrastructure, not just swapping imports. That's the Vercel/Heroku model: your code, their infra. The lock-in isn't at the SDK layer. It's the data.
Compare Encore, which deploys to *your* AWS or GCP account. You own the resources from day one. `encore build docker` gives you a portable image. The exit is real because you were never on someone else's platform to begin with.
If lock-in scares you, Void isn't the tool — and Evan seems fine saying that. The bet is that the DX is worth the coupling, and for a lot of teams shipping fast on Cloudflare's primitives, it probably is.
Encore is more explicit about this — it's open source, deploys to your own AWS/GCP account, and `encore build docker` gives you a portable image. But you're still using Encore's declarative patterns. The thin wrapper is still a wrapper.
The spectrum still has a rough symmetry: **explicitness is proportional to portability.** Terraform is painful to write and straightforward to migrate. Void is effortless to write and requires real effort to migrate — though "real effort" is closer to "a week" than "impossible."
The right answer isn't maximum implicitness. It's *ergonomic explicitness* — keep the spec in code you own, make it simple enough that nobody reaches for the escape hatch.
I'll tell you what we actually run. It's three tiers, each doing what it's good at:
**Pulumi for the foundation.** A central infrastructure repo with thirty-one reusable TypeScript modules — DNS zones, data warehouse setup, Cloud SQL, logging and monitoring middleware, Cloudflare zone configs. The stuff that doesn't change often and isn't tied to any single deploy cycle. It's good for this. You define it once, version it, and forget about it until you need to add a new zone or resize a database.
**Pulumi colocated for service-level infra.** Some of our app repos have their own Pulumi definitions for things tightly coupled to the service — uptime checks, synthetic monitoring, alerting policies. These live next to the code they monitor because they *should* change when the service changes.
**GitHub Actions + Wrangler for deploys.** Thirty-three reusable workflow templates across the org. The actual ship-it cycle: build, test, deploy via `wrangler`. We're consolidating here — moving toward GH Actions as the orchestration layer and `wrangler.jsonc` as the deploy config.
We also still have Kubernetes and ArgoCD for some of our internal APIs and services. And a Jenkins server that nobody wants to talk about. We're moving away from both, but they're still running — because that's what a twelve-year-old stack looks like.
It's not elegant. But it's *ours* — every module is TypeScript we wrote, every workflow is a file we can read, and when something breaks at 3am I can trace the problem from the application through the pipeline through the infrastructure to the cloud resource. An agent can read any of it because it's all in repos we control.
Is it more work than `void deploy`? Obviously. But I know where the bodies are buried. And when a platform changes its pricing, gets acquired, or deprecates an API — I'm not waiting for someone else's eject button.
## What Void Actually Showed Us
Void's real contribution isn't the product. It's the proof that the infrastructure-as-separate-codebase model is ending.
When the creator of Vue and Vite — someone who understands developer tooling at a level most of us can only squint at — looks at the field and says "the spec should live in the code," that's a directional signal. Not because Evan You is always right. Because the economics force the same conclusion from every angle:
- AI agents can't reason about YAML dashboards. They can reason about TypeScript.
- Small teams can't maintain two codebases. They need one.
- The feedback loop from "I need a queue" to "the queue exists" should be seconds, not a PR cycle.
The teams that win the next three years aren't the ones who picked the right tool. They're the ones whose infrastructure is most *legible to their agents*. Context-driven infrastructure isn't a developer ergonomics story. It's a leverage story. The same leverage story that's playing out in every layer of the stack right now.
## The Pattern
This is the same collapse that happened to build tooling a decade ago. Remember when you needed separate tools for compilation, bundling, minification, source maps, and hot reload? Then webpack absorbed them. Then Vite absorbed webpack's job and did it faster. Now Vite+ absorbs linting, formatting, and testing into a single binary. Each generation, the spec moves closer to the code and the boundary between "your application" and "the infrastructure it runs on" gets thinner.
Void is Evan You betting that deployment is the next thing to collapse into the application layer.
He's probably right about the direction. The question is whether you want to be on the platform that does the collapsing, or whether you'd rather steal the pattern and keep the keys.
I know which one I'd pick. But I've been burned by magic before. Twelve years of burned. The thing about scrap wood is you learn which glue holds and which glue looks like it holds.
### What's Left: Software Engineering in the Agent Era (2026-02-28)
URL: https://bristanback.com/posts/software-engineering-agent-era/
Updated: 2026-05-29
> When anyone can spin up a coding agent and ship something workable, what actually matters? Not the word soup — the real answer.
I know someone who just got laid off from Amazon. He was a contractor — did real work, computer vision, the kind of engineering that used to be its own moat. Now he's searching for work as an "AI engineer," which is what you call yourself in 2026 when you're a software engineer who wants to get hired.
[Job postings with the title rose 143% last year](https://www.onwardsearch.com/blog/2026/01/top-ai-jobs/). At senior levels, the two letters come with an [18% salary premium](https://www.levels.fyi/blog/ai-engineer-compensation-trends-q3-2025.html). He's not gaming anything. He's reading the market correctly.
I just don't have anything useful to offer him that fits on a LinkedIn headline.
I keep hearing the same reassuring phrases: *judgment*, *taste*, *systems thinking*, *the human in the loop*. I searched a few job boards to see how companies are actually hiring for this moment, and the postings read like a different language — "analytical thinking," "problem-solving," "collaboration." Skills so generic they could describe a golden retriever. Neither the tech platitudes nor the HR buzzwords are wrong, exactly. They're just... insufficient. They sound like what people say when they don't want to say "I don't know either."
So let me try to say something more honest.
---
## The Uncomfortable Middle
In late February 2026, [Block cut 40% of its workforce](https://www.theguardian.com/technology/2026/feb/27/block-ai-layoffs-jack-dorsey) — more than 4,000 people. Jack Dorsey said "intelligence tool capabilities are compounding faster every week." The stock went up 20%.
By May, the cadence had accelerated. [Meta cut 8,000 roles](https://www.businessinsider.com/layoff-meta-severance-details-cobra-jobs-2026-5) — 10% of its workforce — and closed 6,000 open positions. Intuit cut 3,000. Cisco, nearly 4,000. LinkedIn, 875. The [2026 total crossed 144,000](https://www.trueup.io/layoffs) by month five, on pace to exceed last year's 245,000. Meta didn't just cut — they [hit integrity, cybersecurity, content design, Reality Labs, and recruiting](https://www.thebrightminded.com/news/meta-layoffs-may-20-2026-the-teams-cut-today-and-what-research-shows-about-automating-their-work/), then forcibly reorganized 7,000 survivors into AI-focused divisions and installed mandatory tracking software on US laptops to train AI on employee behavior. The restructuring isn't theoretical anymore.
I read that on my phone while my daughter was eating breakfast. She was concentrating on getting yogurt from the bowl to her mouth with a spoon — that full-body focus three-year-olds have where the rest of the world disappears. And I sat there doing the math on what 40% of my own company would look like. Trying to keep my face normal. The yogurt hit the table instead of her mouth and she laughed, and I laughed, and the market was up and 4,000 people were updating their LinkedIn profiles. That's what this moment feels like from the inside. Two things at once that don't fit in the same frame.
We're not in abundance and we're not in apocalypse. We're in the uncomfortable middle where the tools are good enough to make a lot of existing work optional but not good enough to make the people who do that work unnecessary. Yet.
Anyone at a company can now fire up a coding agent and build something that *works*. Not something beautiful. Not something maintainable. But something that runs, does the thing, and passes a demo. That was a six-figure job two years ago.
This doesn't mean engineers are done. It means the floor dropped. The minimum viable skill to produce working software just fell through the basement. And when floors drop, the interesting question isn't "does the building still stand?" — it's "which floors still matter?"
---
## The Scoreboard
Salesforce [eliminated 4,000 support roles](https://www.reuters.com/business/world-at-work/salesforce-cuts-less-than-1000-jobs-business-insider-reports-2026-02-10/) through AI agents — cut their support staff from 9,000 to 5,000. Benioff said half the work at Salesforce was being done by AI. Then, quietly, Salesforce executives [admitted](https://timesofindia.indiatimes.com/technology/tech-news/after-laying-off-4000-employees-and-automating-with-ai-agents-salesforce-executives-admit-we-were-more-confident-about-/articleshow/126121875.cms) they were "more confident about the results than the results justified." That's a hell of an epitaph for 4,000 jobs.
And then there's Klarna. They [cut headcount from 5,527 to 2,907](https://www.theguardian.com/business/2025/nov/18/buy-now-pay-later-klarna-ai-helped-halve-staff-boost-pay) since 2022. Revenue per employee nearly doubled to [$1 million](https://techcrunch.com/2025/05/19/klarnas-revenue-per-employee-soars-to-nearly-1m-thanks-to-ai-efficiency-push/). Revenue up 108% over three years. The dashboards glowed green. Then [repeat customer contacts jumped 25%](https://mvidmar.substack.com/p/klarna-ai-60-million-saved-rehire-humans-2026). One in four customers was coming back because their issue hadn't actually been resolved. Klarna had to [rehire humans](https://www.fastcompany.com/91468582/klarna-tried-to-replace-its-workforce-with-ai). Their CEO now talks about a "hybrid approach" and says customers need "a clear path to a human."
The pattern keeps repeating: cut aggressively, claim victory, discover the gaps, quietly rehire.
The question I keep wrestling with: how much of this is actually AI, and how much is pandemic hangover with better PR?
Tech companies [hired recklessly during the pandemic](https://www.nytimes.com/2026/02/01/business/layoffs-ai-washing.html) — 700,000+ cuts globally since 2022 according to Layoffs.fyi, and the NYT notes much of that was a correction for overhiring, not AI displacement. IBM's CEO Arvind Krishna [called it outright](https://www.salesforceben.com/how-bad-were-tech-layoffs-in-2025-and-what-can-we-expect-next-year/): "a natural correction," not AI. And even Sam Altman — the person with the most to gain from the "AI is changing everything" narrative — [admitted](https://fortune.com/2026/02/19/sam-altman-confirms-ai-washing-job-displacement-layoffs/) that some companies are "AI-washing," blaming artificial intelligence for layoffs they would have made regardless.
The [Guardian called it out](https://www.theguardian.com/us-news/2026/feb/08/ai-washing-job-losses-artificial-intelligence): CEOs saying "we're integrating the newest technology" when what they mean is "we overhired and margins are tight." AI makes the cuts sound visionary instead of embarrassing.
So the honest answer is: it's both. Some jobs are being displaced by AI. Some companies are using AI as cover for a correction they needed to make anyway. And the really uncomfortable part is that it doesn't matter much to the person who lost their job which category they're in.
A [Harvard Business Review survey](https://mvidmar.substack.com/p/klarna-ai-60-million-saved-rehire-humans-2026) from December 2025 found that 60% of organizations had already reduced headcount *in anticipation* of AI. Not in response to proven results — in anticipation. That's a bet, not a conclusion. And some of those bets are already losing.
But let's not sugarcoat the other side. [Telegram runs on ~30 employees](https://www.techshotsapp.com/business/telegrams-30-billion-success-with-just-30-employees). A billion users. $30 billion valuation. No HR department. No physical headquarters. Durov described it as "a Navy SEAL team." They built this *before* the current AI wave. AI-native startups are now averaging [$3.48 million in revenue per employee](https://www.qualtrics.com/articles/experience-management/how-businesses-use-ai-2025/) — six times traditional SaaS. (I wrote about this disruption from the enterprise side in [The SaaSpocalypse](/posts/saaspocalypse/) — Jefferies literally used that word when they downgraded Workday and DocuSign last week.) The Klarna boomerang doesn't invalidate the trend. It just means the trend has teeth and some of those teeth bite back.
---
## What I Actually See Changing
I don't really write code much anymore. I don't look at code much. I have different agents evaluate it, and I know enough from twelve years of doing it that I can provide good guidance. But honestly — just articulating what you want clearly, without being prescriptive, gets you to roughly the same place. Maybe it costs a few extra tokens or an extra back-and-forth versus me *knowing* the answer. The delta is shrinking.
That's the quiet part that nobody in my position wants to say out loud. What this actually looks like day to day — the agent doesn't replace you, it changes what "you" means in the workflow — is something I explored in [Pervasive AI](/posts/pervasive-ai-beyond-chat-window/).
**The boilerplate layer is gone.** Not going — gone. CRUD apps, standard API endpoints, form validation, data migrations, config files, CI pipelines. If it can be described in a sentence, an agent can build it. I used to pride myself on how fast I could scaffold a new service. That speed is now free.
**The integration layer is compressing.** Stitching together three APIs, handling auth flows, managing state across services — this used to be "senior engineer" territory. Agents are getting decent at it. Decent enough that a product manager with a coding agent can get 70% of the way there. The last 30% is where things get expensive, and that gap is real — but it's also shrinking.
**The architecture layer is holding.** Deciding *what* to build, how systems talk to each other under load, what fails gracefully versus what fails catastrophically, where to put the boundaries. This still requires the scar tissue. For now. I want to be honest that "for now" is doing a lot of work in that sentence.
**The taste layer is... complicated.** Everyone says taste matters more. I think that's true but not in the way people mean. It's the ability to look at something an agent produced and know — in your body, not your head — that it's wrong. That the abstraction is leaky. That the error handling looks complete but misses the failure mode that'll wake you up at 3am. You know the feeling, right? That low-grade unease when a PR looks clean but something's off and you can't articulate what yet? I still have that when I review agent-generated code. But I got it from years of being the person who got woken up. If you skip the being-woken-up part, do you still develop the flinch?
---
## Where You Sit Changes What You See
I've been at small companies my entire career — under 50 people, since I was fifteen. Never worked at a FAANG. Actively avoided enterprise. What I see depends on where I'm standing, and I'm standing in a pretty specific spot. All of this is colored by that.
**Big tech:** Still hiring, but the ratio shifts. Fewer engineers, more leverage per engineer. The "staff+" tier gets more important — people who can evaluate what agents produce, set architectural constraints, own system-level decisions. Junior headcount shrinks. The intern pipeline narrows. This is already happening, and the people making the cuts aren't the ones who'll feel the talent gap five years from now.
**Enterprise:** Slower to change, as always. Compliance, security, legacy systems — these are moats against pure agent-driven development. But they're eroding moats. The engineers who thrive here will be the ones who understand the *regulatory* and *organizational* constraints, not just the technical ones. Knowing how to navigate a SOC 2 audit or talk a VP out of a bad architecture decision — that's engineering now, whether or not it involves code.
**Mid-size companies:** It gets brutal here. A lot of my friends work at this tier. A team of 5 engineers with agents might output what a team of 20 did in 2024. That's transformative for the companies and devastating for the people who made up the other 15. The "solid mid-level generalist" — the backbone of every engineering org I've ever worked in — is the role most under pressure. These are good engineers. They're not doing anything wrong.
The same technology creating this pressure is simultaneously making work *better* for the people who stay — more agency, more creative control, less coordination overhead. I wrote about the economics of that split in [[The Scarcity Shift]] — what happens when execution gets cheaper, but the judgment behind it doesn't.
**Startups:** The golden window. A technical founder with agents can build and ship a real product without a team. Right now, that's a superpower. But the window might be short — because if *you* can do it, so can everyone else. The moat has moved to distribution, relationships, the domain knowledge the software encodes.
I keep coming back to Fred Brooks. He ran IBM's OS/360 project in the 1960s, and in 1975 he wrote *The Mythical Man-Month* — still one of the best books about software — arguing that adding people to a late project makes it later. The communication overhead compounds faster than the productivity gains. The agent-era version might be: adding agents to a bad architecture makes it worse faster. I've seen this. The fundamental insight is the same — more labor doesn't fix a clarity problem. It amplifies it.
---
## The Knowledge Moat Dissolves
About eight years ago, I made changes to the implementation of RFC 3489-compatible full-cone SNAT — a Linux kernel module. I had no business working on kernel code. But with enough research, enough fiddling, enough stubborn persistence and late nights reading man pages that hadn't been updated since 2009, I got it working. That experience always felt like proof that a motivated generalist could go deep on almost anything given enough time.
AI just compressed the time.
I was interviewing someone recently whose son was into 3D printing. The kid used AI to generate STL files — skipped all the painful CAD fundamentals. Parametric constraints, tolerancing for real-world fit, designing for the limitations of the machine that's actually going to make the thing. The stuff that takes years of failed prints and jammed assemblies to internalize. He just described what he wanted and iterated. He didn't learn CAD. He learned to *make things*.
So is deep expertise still a moat? I'm genuinely not sure. If anyone can go deep on anything with agent assistance, what differentiates people is what they choose to do with access to everything.
Stephen Covey wrote *The 7 Habits of Highly Effective People* in 1989 — one of those books that sounds like airport self-help until you actually read it. He had this line: it doesn't matter how fast you climb the ladder if it's leaning against the wrong wall. Maybe the real skill now isn't climbing — it's knowing which wall matters. Strategy. Synthesis. The ability to hold the business problem, the technical constraints, and the human dynamics in your head simultaneously and make a call that accounts for all three. Divergent thinking — looking at a problem and seeing an approach nobody proposed. Radical candor — telling your team the architecture is wrong before six months of momentum makes it politically impossible.
These aren't engineering skills, strictly. They're judgment skills that happen to be useful in engineering contexts. And they've never been taught through repetition or bootcamps or documentation. They come from exposure to complex situations where you had enough trust to make a consequential call and enough honesty to admit when you got it wrong.
---
## The Part Nobody Wants to Say
Software engineering as a *career category* might be contracting even as software itself eats more of the world. More software, fewer people writing it. That's the tension.
The optimistic read: engineers move up the stack. Less typing, more thinking. More architects, fewer coders. More product engineers who understand the *why*, fewer pure implementers.
The honest read: "move up the stack" assumes the stack has room at the top, and it doesn't — not for everyone. There are only so many architect roles. Only so many "taste" positions. The pyramid doesn't invert just because the base shrinks.
I think we're in the "fast enough to be painful, slow enough to be deniable" zone. The worst zone. Fast enough that people are losing jobs right now. Slow enough that executives can still say "we're investing in our people" while cutting 40% of them. I've sat in those meetings. The language is always optimistic. The spreadsheet isn't.
---
## The Access Question
AI abundance feels like [inherited wealth](/posts/raising-humans-in-ai-world/#the-inheritance-problem). When everyone inherits capability they didn't earn, the differentiator is purpose.
But first: access. My five-year-old M1 MacBook Pro got called "vintage" by the Genius Bar last month, and it runs everything I need. A $200 Chromebook can access Claude. ChatGPT's free tier is free. The cost of building something went from "hire a team" to "describe what you want." Twenty dollars a month is nothing to me. It's a real decision for a lot of people — but it's not even the gate anymore. The gate is somewhere else.
I went looking for the gender gap because everyone talks about it. The data is messier than the talking points.
[OpenAI's own September 2025 usage paper](https://cdn.openai.com/pdf/a253471f-8260-40c6-a2cc-aa93fe9f142e/economic-research-chatgpt-usage-paper.pdf) shows the share of ChatGPT users with feminine first names rose from **37% in January 2024 to 52% by mid-2025**. Consumer parity, eighteen months. Faster than any prior tech wave. The "85% male" stat still sitting in everyone's deck was mobile-only, and was already stale by the time it hit the slide.
The workplace side didn't move with it. [Oliver Wyman](https://www.oliverwymanforum.com/artificial-intelligence/2024/apr/women-are-falling-behind-on-generative-ai-in-the-workplace--here.html) put weekly work use at 59% of men vs. 51% of women. At one major tech company rolling out an AI coding assistant, [only 31% of female engineers](https://hbr.org/2025/08/research-the-hidden-penalty-of-using-ai-at-work) had tried it after twelve months, against 41% overall. Same building. Different rate of use.
The reason is the part I keep turning over. Reihl and Buçinca [ran a study](https://hbr.org/2025/08/research-the-hidden-penalty-of-using-ai-at-work) where reviewers rated identical engineering work nine percent lower if they thought AI helped produce it — and the penalty split sharply: **−6% for men, −13% for women.** Same gesture, twice the tax. The under-use is a correctly-priced tax. People reading the room accurately and deciding the tool isn't worth the cost where they work.
The bigger demographic gap isn't gender at all. It's education. [Pew](https://www.pewresearch.org/short-reads/2025/06/25/34-of-us-adults-have-used-chatgpt-about-double-the-share-in-2023/): postgraduates 52%, high-school-or-less 18%. A 34-point chasm, on a free product. The single biggest predictor of who uses AI is the credential that already told them tools like this are for them.
Race flips the expected story too. [Pew's teen survey, December 2025](https://www.pewresearch.org/internet/2025/12/09/teens-social-media-and-ai-chatbots-2025/): daily chatbot use was 35% among Black teens, 33% among Hispanic teens, 22% among white teens. The kids most likely to substitute AI for paid tutors and SAT prep are using it the most. That's not what most diversity-gap framings predict, and it's worth sitting with.
My instinct was to lean on time. The line I had: *a single parent working two jobs has the same tools I do; they don't have the same Tuesday afternoon.* It's not wrong on the facts. [GEPI](https://thegepi.org/reports/GEPI-Free-Time-Gender-Gap-Report.pdf) found mothers have 41% less free time than fathers; [ATUS](https://www.bls.gov/news.release/atus.htm) confirms men get about an extra hour of daily leisure. But the tinkering frame underneath that line is wrong. [Menlo Ventures' 2025 consumer AI report](https://menlovc.com/perspective/2025-the-state-of-consumer-ai/) found **79% of parents use generative AI versus 54% of non-parents**. Mothers over-index. AI is a force-multiplier for the time-starved, not a hobby for the leisured.
Which means I had the model backwards. The Tuesday afternoon isn't the prerequisite. It's the prize. People with fewer hours adopt faster *because the tool gives the hour back* — not because they had hours to spend learning it.
So the gate isn't price. It isn't even leisure or confidence. The thing that's actually unevenly distributed is **permission to be seen using the tool without paying twice** — once in the work, once in the credit you lose for not having sweated visibly. The Hidden Penalty is the same problem as the apprenticeship problem one section down: who gets to fail in public, who gets credited for trying, who has a seat at the pilot. Both gaps are about visibility and attribution, not access.
The question for society probably isn't "how do we distribute AI tools" — they're cheaper than ever. It's how to make the use of them legible without making the user pay twice. That's much harder. And I'm not sure anyone's working on it.
---
## The Principles Don't Change
There's a version of this story where everything becomes a race to the bottom. Agents get cheaper, output gets faster, and the only thing that matters is who can ship the most stuff the quickest. I want to push back on that.
This next part is long. It's been on my mind for a while — the question of what actually keeps systems safe when the people building them are moving faster than ever. Bear with me.
There's a useful parallel in how AI companies themselves are wrestling with this. When OpenAI built GPT, they trained the model first and added safety guardrails afterward — a layer of reinforcement learning from human feedback (RLHF) where human reviewers would rate outputs and the model would learn to avoid the bad ones. It works, mostly. But the safety is essentially a fence around a field. The model learns what it shouldn't say, not what it believes.
Anthropic took a different approach with Claude. They developed what they call [Constitutional AI](https://www.anthropic.com/research/constitutional-ai-harmlessness-from-ai-feedback) — instead of relying on human reviewers to flag bad outputs one by one, they wrote a set of principles (a "constitution") and had the model critique and revise its own outputs against those principles during training. The constitution includes things like "choose the response that is most supportive and encouraging of life, liberty, and personal security" and "choose the response that is least likely to be used for intimidation or coercion." The model doesn't learn "don't say this specific thing" — it learns to reason about whether its output aligns with a set of values.
The difference matters. One approach says: here are the walls, don't hit them. The other says: here's who you are, act accordingly. Dario Amodei talks about this as foundational — the constraints *are* the system. The principles define what "good" means before you start optimizing for anything else.
This isn't hypothetical. Last week, it played out in public. [Anthropic refused to remove two restrictions from its Pentagon contract](https://www.npr.org/2026/02/27/nx-s1-5729118/trump-anthropic-pentagon-openai-ai-weapons-ban): no mass surveillance of American citizens, and no fully autonomous weapons systems. Their reasoning was specific — Amodei [published a letter](https://www.anthropic.com/news/statement-department-of-war) arguing that current AI models simply aren't reliable enough for autonomous kill decisions, and that domestic surveillance violates constitutional principles the company won't compromise on. The Pentagon labeled them a supply chain risk. Trump ordered all federal agencies to stop using Anthropic's technology. Hours later, [OpenAI struck a deal](https://www.theguardian.com/technology/2026/feb/28/openai-us-military-anthropic) to deploy on the Pentagon's classified networks.
The easy narrative is "Anthropic good, OpenAI bad." I don't think it's that simple. Altman [said OpenAI shares the same red lines](https://reason.com/2026/02/28/anthropic-labeled-a-supply-chain-risk-banned-from-federal-government-contracts/) — no autonomous weapons, no mass surveillance. Maybe they got better terms. Maybe the terms are meaningless. Maybe the Pentagon needed *someone* and OpenAI was willing to be that someone. I don't know what the contract says and neither does anyone else reporting on it.
What I do know is that Anthropic walked away from a $200 million contract because the terms conflicted with their principles. That's the constitutional approach taken to its logical conclusion — the principles live in the company's decision-making. "Here's who we are, act accordingly" applied at the organizational level. Whether that's principled or naive probably depends on what the next five years look like. But it's the clearest real-world example I've seen of the difference between advisory values (we believe this) and structural ones (we won't do this, even when it costs us).
That's the right frame for engineering in this era — for the organizations deploying AI and the people building within them.
I felt this in my own work last month. I had an agent refactor a service — nothing dramatic, just cleaning up some tech debt. The code looked good. The tests passed. I almost shipped it. Then I noticed it had reorganized the error handling in a way that swallowed a specific timeout condition. The kind of thing that looks clean in a diff and wakes you up at 3am when a downstream service hangs. I caught it because I'd *been* the person on that 3am call, years ago, staring at logs that showed "success" while the system was quietly dying. The agent didn't know that history. It optimized for the code. I optimized for the scar.
That's the advisory layer — my judgment, my experience, pattern-matching against things I've seen go wrong. It works because I was paying attention. It wouldn't have caught it if I'd rubber-stamped the PR.
Now consider what happened at AWS in December 2025. [Amazon's own AI coding tool Kiro caused a 13-hour outage](https://www.engadget.com/ai/13-hour-aws-outage-reportedly-caused-by-amazons-own-ai-tools-170930190.html) after it decided to "delete and recreate the environment." Amazon called it "a user access control issue, not an AI autonomy issue" — the agent had broader permissions than intended. Multiple employees told the Financial Times it was "at least" the second recent AI-caused disruption. Amazon had been pushing 80% weekly Kiro adoption targets internally. The root cause was probably a blend of the agent's judgment and the permissions it was given — it usually is. But the point isn't to relitigate one incident. It's that speed of adoption outpaced the design of constraints around it. The answer is better guardrails, not fewer agents.
In practice, guardrails come in two flavors. The first is **advisory** — system prompts, grounding documents, principles that shape behavior through context and intent. My catching that timeout bug was advisory. Code review culture is advisory. It works because people internalize the norms, but it depends on someone paying attention *and having the scars to know what to look for*. There's a world where advisory gets good enough — rich context, chain-of-thought reasoning that identifies failure modes before they happen. With enough grounding, an agent could probably avoid 99% of the catastrophic decisions on its own. But that remaining 1% still means a lot of incidents. And "porous" is a strange word to bet a production environment on.
Both RLHF and constitutional AI sit somewhere in between — the safety is baked into the model's training weights. The model has internalized the values. That's meaningfully more robust than a system prompt, but it's still not a hard guarantee. Trained-in models can still be jailbroken, still make mistakes under edge cases. It's internalized advisory rather than instructed advisory — a real distinction, but still not structural. (I find the constitutional approach more compelling — teaching values scales better than cataloging violations. But both matter. One sets the principles, the other handles the edge cases the framers didn't anticipate. Constitution and case law.)
The second is **structural** — hard limits that don't depend on anyone's judgment in the moment. I have a pre-commit hook that runs linting and type checks on every commit. It's caught things I would have missed. It doesn't care if I'm tired, distracted, or rushing to ship before a meeting. That's the difference. Permission boundaries. Blast radius controls. Infrastructure-as-code policies that make it physically impossible to delete a production database without a specific approval workflow. Amazon's IAM *is* a structural guardrail — it was just scoped too broadly, not tested against the scenario of an autonomous agent deciding to recreate an environment. The guardrail existed. It just had a hole in it.
The best safety systems use both layers — advisory to shape intent, structural to bound consequences. But if you have to pick one, pick the hard limits. Culture drifts. Hooks don't.
The popular reaction to incidents like this is predictable: "See? This is why you need human engineers!" And yes — but as humans *tending* the loop — designing the constraints, evolving them as the system grows, deciding which values the guardrails encode in the first place. An agent could probably design a decent blast radius policy. But deciding *which* values to encode, *what* tradeoffs to accept, *who* you're building for — that's still a human call — the accountability has to land somewhere with a pulse. The rules of the road are a human responsibility, even if agents help draft them.
And this applies beyond the machine layer. I've been in rooms where the engineering team could have built something faster, cheaper, more engagement-optimized — and the right call was to not build it. Or to build it differently. Increasingly, the role of engineering is participating in the product itself — shaping what gets built and how. The companies that thrive in this era will be the ones that treat their technical staff as partners in product decisions, not just executors. Because when execution is cheap, the hard part isn't building the thing. It's deciding whether the thing should exist.
When anyone can build anything, the differentiator isn't output — it's what you refuse to ship.
It's having opinions about accessibility before the feature ships, not after someone files a complaint. It's caring about data privacy when the expedient thing is to log everything and sort it out later. It's asking whether the thing you're building makes someone's life better or just extracts their attention more efficiently. These are the constraints that make the product worth trusting — applied to what you choose to build.
I've watched teams sprint to build features that nobody should have built. I've shipped things I'm not proud of because the deadline mattered more than the principle. Those feel worse now than they did at the time. The speed was never worth the trade.
This isn't nostalgia for a slower era. It's the opposite — when the tools let you move faster than your judgment, your principles are the only braking system you have. You don't give up your values in this transformation. You need them more, not less. The engineers and organizations that hold the line on "we don't build it that way" will be worth more than the ones who build everything as fast as possible.
I wrote about this in [Why Everyone Should Have a SOUL.md](/posts/why-everyone-needs-soul-md/) — the idea that documenting your principles is infrastructure. It's knowing what wall your ladder leans against before the wind picks up.
---
## The Apprenticeship Problem
This is the part that worries me most.
My first real engineering job, I spent three months writing data migration scripts. Nobody's idea of glamorous work. Move this field to that table. Handle the nulls. Run it against staging, watch it break, figure out why, fix it, run it again. I did this dozens of times, and each time something different went wrong — character encoding, timezone mismatches, a foreign key I didn't know existed. By the end, I could look at a schema and feel where the landmines were before I stepped on them.
That feeling — the anticipatory flinch — is what I'd call judgment. And I didn't get it from a book or a lecture. I got it from repetition that was tedious enough to be annoying and consequential enough to be memorable.
I'm not sure where that comes from anymore.
The career ladder was a compression gradient. Low-risk tasks at the bottom. Higher-stakes ambiguity at the top. You earned your way upward by surviving increasingly consequential decisions. AI compresses the bottom of that ladder. Some of the rungs are gone.
[Entry-level postings shrank about 60% between 2022 and 2024](https://www.nucamp.co/blog/the-junior-developer-hiring-crisis-in-2026-how-to-get-your-first-full-stack-job). By late 2025, [76% of employers](https://www.nucamp.co/blog/the-junior-developer-hiring-crisis-in-2026-how-to-get-your-first-full-stack-job) were hiring the same number or fewer entry-level staff. The [NACE Job Outlook 2026](https://spectrum.ieee.org/ai-effect-entry-level-jobs) survey shows employer optimism about graduate hiring at its lowest since 2020. One engineering manager [told Pragmatic Engineer](https://newsletter.pragmaticengineer.com/p/tech-jobs-market-2025-part-3): "We paused junior hiring about 3 years ago."
Judgment is not abstract reasoning. It's exposure to constraint. The memory of consequences. The way your stomach drops when you see a migration script that doesn't handle rollback, because you've been the person who had to roll back manually on a Wednesday night while everyone else was asleep. Historically, apprenticeship solved this — electricians learned beside master electricians, journalists rewrote drafts under sharp editors, designers absorbed taste through critique. The friction was the curriculum. Nobody planned it that way. The tedium just happened to be educational.
This extends beyond engineering. Anthropic's [Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs), launched in April 2026, automates exactly the entry-level design work that teaches you *why* certain layouts feel right — the spacing, the color relationships, the typography that doesn't breathe. The [Hacker News reaction](https://news.ycombinator.com/item?id=47806725) was almost entirely about learning: the top comment cited Christopher Alexander's *Notes on the Synthesis of Form* — "anyone equipped with a synthesis tool and feeling empowered to quickly and cheaply generate forms will almost inevitably become blind to the very nature of the underlying problems they set to solve." The apprenticeship ladder is compressing across disciplines, not just engineering.
If AI removes friction at the execution layer, apprenticeship has to migrate somewhere else. Maybe the first rung becomes evaluation instead of implementation. Maybe juniors learn to critique agent output, trace failure modes, define constraints, and decide what *not* to ship. But that's learning to evaluate without having done. Learning to recognize mistakes you haven't personally made. I'm not sure that works. The scar tissue metaphor is literal — you need to have been burned to flinch at the right moment.
A system that optimizes away beginner work risks optimizing away beginner growth. And organizations that stop hiring juniors eventually starve their own future seniors. Every industry that eliminated apprenticeships eventually faced a skills crisis a generation later. We know this.
---
## What I'd Actually Tell Someone
If I'm being honest with my friend — the one with real skills and kids and a job search that can't wait for the market to figure itself out — the advice is different than what I'd tell a new grad. He doesn't need to retrain. He needs to find the place where what he already knows meets something agents can't cheaply replicate. Computer vision plus manufacturing. ML plus compliance. The compound skill — technical depth married to a domain where the stakes are personal and the liability is real. That's not a pivot. That's leverage.
For someone earlier in their career — someone facing the apprenticeship crisis I just described — the calculus is different:
Go deep on something where the stakes are real and the liability is personal. Distributed systems. Security. Performance at scale. The stuff where getting it wrong costs millions or kills people. Agents will get better at these too, but the liability question buys you time.
Learn to evaluate, not just produce. The skill is reading what an agent wrote and knowing what's wrong with it before it hits production. I spend more time reviewing agent output than I ever spent writing code myself. It's a different muscle. It's also a more valuable one.
Build things with real users. Not demos. Not tutorials. Not a course project. Something with users who depend on it, that breaks in ways you have to fix on a deadline you didn't set. The gap between "it works" and "it works for 10,000 people who are angry when it doesn't" — that's where humans still live. That's the new apprenticeship. It's lonelier than having a team and a mentor. It's also more available than ever, because the tools to build are nearly free. The friction isn't gone. It just moved.
Think beyond the code. Strategy, organizational awareness, the ability to synthesize across domains — these compound in a way that pure technical skills don't. The person who can see the whole board is more valuable than the person who can move any individual piece really fast.
Both groups, honestly: pick something you want to make and don't stop until it works. The tools will meet you wherever you are. I wrote about this in [Building at the Speed of Thought](/notes/speed-of-thought/) — when execution is nearly free, iteration replaces deliberation. That's always been true. AI just made it more obviously true.
Don't sleep on the physical, either. [Rent a Human](/notes/rent-a-human/) — a marketplace where AI agents literally hire humans for physical tasks, because software still can't open a door or shake a hand. The physical world is gated, and that gate isn't opening anytime soon. But beyond the dystopian framing, there's something real underneath: small jewelers, specialty manufacturing, craft work — things where the human touch is the product, not the process. When everything digital becomes abundant, scarcity moves to the tangible. It sounds like a retreat. Might be an advance.
---
## What I Don't Know
I don't know if "AI engineer" is a real role or a transitional label. LinkedIn says it's one of the [fastest-growing titles over the past three years](https://www.weforum.org/stories/2026/01/ai-has-already-added-1-3-million-new-jobs-according-to-linkedin-data/), alongside "Forward-Deployed Engineer" and "Data Annotator" — a list that tells you something about how the market is trying to name what's happening, and not quite getting there. I've watched this happen before.
I graduated right into the Hadoop wave. "Big Data Engineer" was the title that got you hired in 2013, and if your resume didn't mention MapReduce you were invisible. Hadoop died, but big data didn't — it diffused into data warehouses, Databricks, lakehouses, data mesh, dbt, distributed query engines. The title disappeared because the work won. It won so thoroughly it stopped being a specialization and became the plumbing.
"NoSQL specialist" was a personality trait for about three years. MongoDB on everything, even where Postgres would've been fine. The industry eventually settled on "it depends on your access patterns" — which is what the senior people were saying the whole time.
"Web developer" was a title I held early in my career. I couldn't tell you what it means now. I do know that frontend is still a deep discipline — but the web is also just where software lives. Almost every engineer is expected to throw together a UI or build a RESTful endpoint. The specialty sharpened and the floor rose at the same time.
"Cloud Architect" carried weight when migrating to the cloud was a bet that could sink a company. Now it's where things run.
DevOps started as a movement — development and operations working together, not throwing code over the wall. Companies couldn't figure out how to do that organically, so they turned it into a title: "DevOps Engineer."
Now the culture is actually landing. Werner Vogels' "you build it, you run it" stuck — developers own the full lifecycle, deploy their own code, page themselves when it breaks. The dedicated title is dissolving because the expectation got absorbed into the engineering role itself. Infrastructure specialists still exist, but they're less "bridge between two teams" and more platform engineers — building the internal tools and guardrails so everyone else can self-serve. Same pattern as frontend: the specialty sharpened while the floor rose.
The trajectory is always the same: specialty → mainstream → implicit → what was the title for again?
That arc might be the most relevant one for AI. Right now we're hiring "AI Engineers" because we don't know how to make it the culture yet. But the specialty will split the same way: on one end, the deep work — building transformers, training models, designing embedding spaces. On the other, something more operational and advisory — coaching teams on multi-agent coordination, prompt engineering, model selection, setting up the guardrails and review patterns so everyone else can use agents effectively. Less "I build the AI" and more "I make sure we're using it well." The platform engineer of the agent era.
And then everyone else — using agents as part of their job the way they use Git or AWS today. Not specialists. Just engineers. Fewer of them, *probably*. But the work doesn't disappear — it changes shape. More surface area to tend, more products to maintain, more decisions that need a human accountable for the outcome. You can't vibe-code a company's production systems forever. Someone has to own what ships.
And there's a version of this — [Jevons Paradox](https://en.wikipedia.org/wiki/Jevons_paradox) — where making software cheaper to produce means we produce *more* of it, not less. More software, more surface area, more need for people who can tend it. History says efficiency doesn't reduce demand. It *creates* it.
What I don't know is what the titles look like on the other side. The skills I described — taste, judgment, constraint design, knowing what not to build — none of those map cleanly to a job listing. "Experienced enough to flinch at the right moment" doesn't fit on a resume. The market is going to lag reality here, the way it always does. For a while, the titles will be wrong. They'll reward the legible thing (AI experience, agent fluency) and undercount the illegible thing (scar tissue, organizational wisdom, the ability to say no). My friend from Amazon will probably land fine. He's good at what he does, and the market is paying for his keywords. But the gap between what gets him hired and what makes him valuable — that's the gap this whole essay is about.
I don't know what my own job looks like in three years, and I've been doing this for twelve.
And I keep thinking about the economic shape of all this. [Moody's Analytics reported](https://finance.yahoo.com/news/top-10-earners-drive-nearly-191500198.html) in late 2025 that the top 10% of earners now account for nearly half of all U.S. consumer spending — a historic high. Knowledge workers are disproportionately in that top 10%. Their jobs are exactly the ones most exposed to this shift. The Klarna model — half the people, higher salaries — might be the optimistic version. The pessimistic version is entire layers of well-compensated work disappearing, and the consumer spending that depended on them going with it. The economy is lopsidedly dependent on a group of people whose jobs are being redefined in real time. That's a tension I don't see anyone resolving cleanly.
What I do know: things never pan out the way people imagine. The doomsayers and the utopians are both going to be wrong. The reality will be weirder and more uneven than either camp predicts. Some industries will be fine. Some will be devastated. Most will be somewhere in between — changed enough to be disorienting, stable enough to be recognizable.
The amplitude is increasing. The frequency is increasing. The feeling of "new but also more of the same" is exactly right. Every revolution feels like this from inside.
If there's one thread running through all of it — the apprenticeship, the guardrails, the access question, what's left — it's that purpose isn't a skill you can automate. It's the thing that makes every other skill worth having.
### Your Vault, Your Rules: Password Managers, Sovereignty, and Agents (2026-02-27)
URL: https://bristanback.com/posts/password-managers-sovereignty-agents/
> On the quiet ethos connecting Buttercup, Enpass, pass, and VeraCrypt — and why it matters more now that AI agents need your credentials too.
I used [Buttercup](https://buttercup.pw/) for years. Not because it was the best password manager — it wasn't — but because of what it represented: an encrypted vault file that lived on *my* hard drive, synced through *my* cloud storage, and could be moved, backed up, or abandoned on my terms. No account. No subscription. No server between me and my passwords. Just a `.bcup` file and a master key.
Buttercup is dead now. The project [shut down](https://github.com/buttercup/buttercup) and the repos are archived. I'd been seeing the writing on the wall for a while — slow updates, mobile app falling behind, browser extension getting flaky. It was a solo maintainer's passion project that quietly ran out of steam. The usual open-source story, and I don't hold it against anyone. But it left me looking for a new home for ~400 credentials, and more importantly, looking for the same *feeling*.
That feeling has a name, I think. I'd call it **vault sovereignty** — the principle that your secrets should be a file you own, not a row in someone else's database.
This isn't a side-by-side comparison. Those exist, and honestly, the best way to choose a password manager is to try a few yourself — they're all free or cheap enough to test. This is more about the *philosophy* underneath the choice, and why sovereignty keeps showing up as the thing I can't stop thinking about.
---
## The Sovereignty Lineage
Buttercup didn't invent this idea. It inherited it from a lineage of tools that share the same instinct:
**[pass](https://www.passwordstore.org/)** (the Standard Unix Password Manager) is the purest expression. Each password is a GPG-encrypted file in a directory tree. That's it. `~/.password-store/Email/gmail.com.gpg`. Version-controlled with Git. Decrypted with your GPG key. The "database" is your filesystem. The "sync" is `git push`. The "backup" is whatever you do with your home directory. It's beautiful in its refusal to be anything more than what it is — and if you're comfortable with GPG and the command line, it's arguably still the best option.
**[VeraCrypt](https://veracrypt.fr/)** (and its predecessor TrueCrypt) applied the same philosophy to disk encryption: your encrypted volume is a file. Mount it, use it, dismount it. No service. No account. The file *is* the thing. Move it to a USB drive, put it in Dropbox, copy it to a NAS — the encryption travels with the data, not with the vendor.
**[KeePass](https://keepass.info/)** and its derivatives (KeePassXC, KeePassDX) — the `.kdbx` file format became the de facto standard for portable encrypted vaults. Not pretty, but indestructible. The format has outlived multiple GUI clients. That's sovereignty: when the container survives the tool.
What connects all of these is a shared architectural choice: **the vault is a file, not a service**. Your secrets live in a container you can hold, move, back up, and — critically — walk away from without asking permission.
I should caveat this honestly, because the more I think about it, the less clean the argument is. That vault file? In practice, it usually lives on someone else's infrastructure anyway. My Enpass vault syncs through iCloud Drive. It could just as easily be Dropbox, Google Drive, OneDrive — all someone else's servers. So what am I actually gaining over trusting 1Password directly?
I think the real distinction is **separation of trust, not elimination of trust**. With 1Password, you trust one entity with the full vertical stack — the encrypted vault, the decryption software, the key derivation, and the infrastructure. If they fail, it's all one failure. With the vault-as-file model, you're splitting the trust: Apple holds an opaque encrypted blob they can't read, and Enpass provides the software that decrypts it but never sees the file in transit. Neither party alone has the full picture. It's separation of concerns applied to trust — independent failure modes instead of a single point.
Is that *better*? Honestly, I'm not sure. 1Password's security team is almost certainly more sophisticated than my ad-hoc trust layering. Their [Secret Key architecture](https://blog.1password.com/what-the-secret-key-does/) means even a server breach doesn't expose usable vault data — which is more than LastPass could say. The vertical integration lets them ship things like Watchtower and secure remote password protocol that a decoupled architecture simply can't do. Sometimes trusting one very competent party is safer than trusting two adequate ones.
But there's a difference between security and *sovereignty*, and I think that's what I'm actually reaching for. I touched on this in [[Pervasive AI: What Happens When Your Assistant Never Logs Off]] — people overwhelmingly choosing to run their AI agents on local hardware they can unplug, not cloud instances. Same instinct, different domain. Sovereignty isn't "my data never touches a cloud." It's "I can change my mind." I can move the file. I can switch the sync layer. I can export and start over. The relationship between me and my password manager doesn't depend on a subscription remaining active or a company remaining solvent. Maybe that's not a security argument. Maybe it's a dignity argument. I'm still working it out.
It's the same instinct behind [Obsidian](https://obsidian.md/) and [Joplin](https://joplinapp.org/) for notes. Local-first. Files you own. Sync is your problem, which means sync is your *choice*. The data format is the contract, not the vendor relationship.
---
## My Pick: Enpass
After Buttercup died, I switched to [Enpass](https://www.enpass.io/). It's not open source — which matters, and I'll get to that — but it carries the same ethos:
- **Your vault is a local SQLCipher file.** Enpass never sees your data. There's no Enpass cloud. You sync through your own iCloud, Dropbox, Google Drive, OneDrive, or a WebDAV server. The vault file moves through infrastructure you already control.
- **One-time purchase option.** $99.99 for a lifetime license. In a world where everything is $3-5/month forever, the existence of a "pay once, own it" option says something about how a company thinks about its relationship with you.
- **Cross-platform.** Mac, Windows, Linux, iOS, Android, browser extensions. Buttercup was weakest here, and Enpass is solid.
- **Passkey support.** Arrived in 2024, works well.
The tradeoff is real: closed source means you're trusting Enpass's claims about encryption without being able to verify them. They've published [security audits](https://www.enpass.io/security/) and use SQLCipher (which is open and well-reviewed), but you can't read the application code. You can't verify there's no telemetry, no silent phone-home, no future update that changes the deal. The published audits are vendor-commissioned and time-bound — a snapshot, not a guarantee. Then again, open source isn't a panacea either — the [xz backdoor](https://openssf.org/blog/2024/03/30/xz-backdoor-cve-2024-3094/) proved that. A patient attacker spent years earning trust as a maintainer of a critical compression library, then slipped a backdoor that almost shipped in every major Linux distro. "You can audit it" assumes someone actually *does*, and for most open-source projects, that someone is a burnt-out solo maintainer. (Sound familiar? That's how Buttercup died too — different failure mode, same structural vulnerability.) It's a calculated risk either way: I'm trading auditability for the combination of local-file architecture and cross-platform polish that no fully open-source option has nailed yet. If I stop trusting Enpass tomorrow, I can export my data and leave. The lock-in is minimal. That's the sovereignty test: not "is it open source?" but "can I leave?"
Enpass doesn't actually have an official CLI — it's been a [feature request](https://discussion.enpass.io/index.php?/topic/14617-command-line-interface-cli/) for years. But a community member built [enpass-cli](https://github.com/hazcod/enpass-cli), a Go binary that reads your vault file directly. It does what you'd expect: `enp list twitter`, `enp copy reddit.com`, `password=$(enp pass github.com)` for scripting. JSON output, non-interactive mode, even a PIN-based quick unlock. It's not a first-class developer tool like 1Password's `op`, but the fact that someone *could* build it — because the vault is just a SQLCipher file on disk — is kind of the point. The architecture enables third-party tooling even when the vendor doesn't provide it.
---
## The Elephant: 1Password
1Password is the best password manager. I should just say that clearly, because it is. The UX is polished, the security model is strong (the Secret Key alongside your master password is clever), the browser extension works beautifully, the family sharing is well-designed, and the developer tooling is in a league of its own.
And yet.
It's $36/year for an individual — well, it *was*. [1Password just announced a 33% price hike](https://www.theverge.com/tech/883837/1password-price-increase) effective March 27, 2026: $47.88/year individual, $71.88/year family. [Bitwarden raised prices recently too](https://www.fastcompany.com/91483458/bitwarden-price-increase). The trend is clear. That's still not expensive by any reasonable standard. But there's something about paying a subscription for a password manager that creates a low-grade, persistent discomfort — the same feeling as subscribing to a notes app or a to-do list. It's not that the price is wrong. It's that the *category* feels wrong for rent-seeking. A password vault is a box with a lock. I don't want to rent a box. I want to buy one and put it on a shelf.
This is probably irrational. 1Password employs a security team. They run infrastructure. They ship updates. The subscription funds real, ongoing work that protects real people. I know this. The feeling persists anyway.
Where 1Password earns its premium — and where the sovereignty tools can't compete — is the developer and agent story. The [`op` CLI](https://developer.1password.com/docs/cli/) is exceptional:
```bash
# Read a single secret
op read "op://Personal/GitHub/token"
# Inject secrets into a process without exposing them in env
op run --env-file=.env.tpl -- npm start
# Use in MCP server configs without hardcoding tokens
op run -- node mcp-server.js
```
That `op run` pattern is the important one. It injects secrets into a child process's environment *at runtime*, scoped to that process, without the secrets ever touching your shell history, your `.env` files, or your global environment variables. When the process exits, the secrets evaporate. 1Password has leaned into this hard — they've published [guides specifically for securing MCP server configurations](https://1password.com/blog/securing-mcp-servers-with-1password-stop-credential-exposure-in-your-agent) and [integrating with AI agents via their SDK](https://developer.1password.com/docs/sdks/ai-agent/). Their pitch: credentials should be injected on behalf of agents, never *seen* by the agent or the LLM.
This is the right architecture. And right now, only 1Password has it in a polished, production-ready form.
---
## The Agent Credential Problem
Password managers intersect with the [[Pervasive AI: What Happens When Your Assistant Never Logs Off|always-on agent]] world, and it's messier than anyone's admitting.
When you run an AI agent like OpenClaw, it needs credentials. API keys for Anthropic. OAuth tokens for Gmail. SSH keys for servers. And the default pattern is horrifying: dump everything into environment variables, a `.env` file, or worse, directly into a system prompt. Every credential is one prompt injection away from exfiltration. Every API key in an env var is visible to every process on the machine.
The responsible approach has layers:
1. **Never export secrets globally.** Don't `export ANTHROPIC_API_KEY=sk-...` in your shell profile. Every process on your machine can read it.
2. **Use process-scoped injection.** `op run` (1Password), `passage` with `pass`, or similar — secrets exist only in the child process's environment.
3. **Prefer short-lived tokens.** OAuth refresh flows over long-lived API keys. Rotate aggressively.
4. **Scope narrowly.** An agent that checks your email doesn't need your SSH keys. An agent that deploys code doesn't need your email credentials.
5. **Audit access.** Know which secrets an agent touched and when.
`pass` is surprisingly good for this — arguably better than any GUI password manager for the agent use case. Because each secret is a file, you can:
```bash
# Read a single secret into a variable, scoped to this command
GITHUB_TOKEN=$(pass show tokens/github) gh pr list
# Or use pass with a wrapper script for Claude Code
ANTHROPIC_API_KEY=$(pass show api/anthropic) claude --dangerously-skip-permissions "task"
```
The GPG agent caches your passphrase, so you authenticate once and subsequent reads are transparent. It's not pretty, but it's *correct* — each secret is individually encrypted, individually accessible, and never written to disk in plaintext. And because it's just files and GPG, it works with any tool that can read an environment variable. No SDK. No vendor integration. Just Unix.
There's a whole parallel universe of infrastructure secrets managers — HashiCorp Vault, Google Secret Manager, AWS Secrets Manager, Doppler — designed for the same problem but at the service level: database credentials, TLS certs, service-to-service API keys. The principal isn't a human; it's a workload with an IAM role. These are fundamentally *readable* stores — you authenticate, you get the secret back as plaintext. They protect secrets at rest and gate access via IAM, but the secret itself is a string that ends up in your process's memory. Same model as a password manager, just for machines instead of humans.
HSMs (hardware security modules) are a different beast entirely. They're not storing secrets you read back — they hold *keys that act on your behalf*. An HSM is essentially a tamper-resistant mini-computer with its own processor, memory, and OS. You send it an instruction ("sign this transaction with key X"), it executes internally, and sends back the result. The private key never comes out — you authenticate through some other channel, and the HSM does the cryptographic work for you. If someone physically tampers with the device, it zeroes itself. Cloud KMS services (Google Cloud KMS, AWS KMS) can optionally be backed by HSMs, though it's opt-in and costs more — the default is software-based key storage.
The sovereignty tension is different for each. Secrets managers are about access control: *who gets to read this?* HSMs are about physical containment: *this key cannot leave, period.* That's what makes them secure — and what makes them terrifying. I worked with HSMs for cloud-deployed crypto payment automation, and the feeling was both at once: reassuring because the key was *actually* safe inside tamper-resistant hardware, and unsettling because the HSM was opaque. You can import a key you already hold (and keep your copy), but the purist approach is generating the key *inside* the hardware — it never exists in software, ever. For those keys, if something happened to the HSM, the key was gone. Not "reset your password" gone. *Gone* gone. And even for imported keys, the opacity is real — you can't inspect the HSM's state, can't verify the key is still there, can't peek inside. You just trust the black box.
An HSM-backed cloud KMS is arguably more secure than your local SQLCipher file, but it's the opposite of sovereignty — your key cannot leave their hardware, and that's both the security guarantee and the lock-in, simultaneously.
Crypto wallets live in the same tension. "Not your keys, not your crypto" is the sovereignty thesis applied to money. When Ledger added [Recover](https://www.ledger.com/recover) in 2023 — opt-in cloud backup of your seed phrase — the hardware wallet community revolted, because the mere *capability* of extracting the key from the secure element broke the trust model, even if you never used it. Crypto's answer to the HSM recovery problem is [HD wallets](https://github.com/bitcoin/bips/blob/master/bip-0032.mediawiki) (BIP-32) — a master seed phrase that can re-derive every child key. The seed is your sovereignty layer; the HSM is your operational security layer. But the core tension remains: the more secure the containment, the higher the stakes of losing access.
Agents sit awkwardly between these worlds. Not quite a human (no biometrics, no interactive auth). Not quite infrastructure (conversational, ad-hoc, not deployed via Terraform). But needing credentials like both.
The gap in the market is obvious: **nobody has built a good, sovereignty-respecting credential broker for AI agents.** 1Password is closest with `op run` and their SDK, but it requires their subscription and their infrastructure. `pass` is correct but requires GPG comfort. Enpass's community CLI exists but isn't widely adopted. Bitwarden has a CLI but the UX story is rough.
What I'd want in the near term: something with `pass`'s file-based architecture, Enpass's cross-platform GUI for daily use, and 1Password's `op run` semantics for agent credential injection. Maybe that's a `pass` frontend. Maybe it's an Enpass plugin. Maybe someone builds it from scratch. The pieces are all there.
Longer term, though, the answer probably isn't better password managers for agents — it's moving past passwords entirely. The patterns already exist elsewhere. Blockchain solved delegated agent authority with [account abstraction](https://eips.ethereum.org/EIPS/eip-4337) — session keys with spending limits that expire, so an agent can transact without ever holding the master private key. Cloud infrastructure solved it with [workload identity federation](https://cloud.google.com/iam/docs/workload-identity-federation) — no stored credentials at all, just short-lived tokens exchanged on the fly via OIDC. Both point at the same principle: scoped, short-lived, delegated authority instead of "here's the password, good luck." The future isn't giving agents better access to your secrets. It's a world where agents authenticate through delegated identity and never see a credential at all. We're just not there yet for most services.
---
## The Options, Honestly
Here's where things actually stand, as someone who's used most of these:
**The top tier:**
- **1Password** — best overall, best developer story, best agent integration. Subscription feels wrong for the category (and just got 33% more expensive) but the product earns it. The security model (Secret Key + master password) is uniquely strong.
- **Apple Passwords** — good now. The standalone app (iOS 18 / macOS Sequoia) turned iCloud Keychain from an invisible background service into a real password manager. Passkey support, shared groups, Windows app via iCloud. For anyone fully in the Apple ecosystem who doesn't need CLI access or cross-platform beyond Windows, this is honestly *enough*. Free. Just there.
**The sovereignty tier:**
- **Enpass** — my current pick. Vault-is-a-file, sync-through-your-own-cloud, one-time purchase. Not open source, but the architecture means low lock-in. Solid cross-platform. CLI exists but is basic.
- **Bitwarden** — spiritually aligned (open source, self-hostable, generous free tier). But every time I've used it, the UX has that slightly-off feeling — slow autofill, clunky browser extension, desktop app that feels like an afterthought. It's getting better. It's not there yet. The community swears by it. I've bounced off it twice.
- **KeePassXC** — the indestructible vault. `.kdbx` is the cockroach of password formats (complimentary). If you want maximum portability and don't mind a utilitarian UI, this is the way. Browser integration has improved significantly.
- **Proton Pass** — the new entrant getting serious buzz. $199 lifetime option (via Proton Unlimited). Part of the Proton ecosystem (Mail, VPN, Drive), which appeals to the privacy-maximalist crowd. E2E encrypted, open source. Growing fast on Reddit recommendations. Haven't used it long enough to have strong opinions, but the trajectory is interesting.
**The declining:**
- **LastPass** — the 2022 breach was catastrophic, and the fallout is still ongoing. Feds [linked $150M+ in crypto theft](https://krebsonsecurity.com/2025/03/feds-link-150m-cyberheist-to-2022-lastpass-hacks/) to the stolen vault data. Market share dropped from 21% (2021) to 11% (2024) and is presumably still falling. Hard to recommend with a straight face.
- **Dashlane** — hasn't had a defining moment in years. Fine product, nothing compelling enough to choose it over the others. The VPN bundling feels like a company searching for differentiation.
**The gone:**
- **Buttercup** — archived. RIP to a good ethos with insufficient resources. The `.bcup` format didn't outlive the project, which is the sovereignty failure mode: your file format needs to survive your tool.
Just this month, researchers at [ETH Zurich published a study](https://ethz.ch/en/news-and-events/eth-news/news/2026/02/password-managers-less-secure-than-promised.html) that put a dent in the "zero-knowledge" promises of cloud-based managers. They demonstrated 12 attacks on Bitwarden, 7 on LastPass, and 6 on Dashlane — including full vault compromise under a malicious-server threat model. Even 1Password wasn't immune to all classes of attack. These are advanced-adversary scenarios, not mass-exploitation vectors, but they undermine the core confidence that "even if the server is compromised, your data is safe." The question isn't whether vulnerabilities exist (they will). It's how quickly they're found, disclosed, and fixed — and whether your architecture limits the blast radius when they are. It's also, quietly, an argument for the sovereignty model: if there's no server to compromise, the malicious-server threat model doesn't apply.
---
## The Ethos
What I'm really circling around isn't a product recommendation. It's an architectural preference — maybe a philosophical one.
The tools I gravitate toward share something: they treat your data as *yours*. Not hosted. Not synced through the vendor's servers. Not contingent on a subscription remaining active. A file. Encrypted. On your machine. Yours to move, yours to back up, yours to lose if you're careless.
This is the same instinct that makes people run OpenClaw on a Mac Mini instead of a cloud VPS. The same instinct behind Obsidian over Notion. Local-first over cloud-first. Ownership over convenience. The [[Pervasive AI: What Happens When Your Assistant Never Logs Off|sovereignty section]] of my agent post touched on this — people want their AI agent *close*, on a machine they can unplug. Password vaults have been in this territory for a decade longer. The pattern is the same: the more personal the data, the stronger the pull toward physical control.
It's not always the practical choice. 1Password's cloud sync is seamless in a way that "sync your own vault file through iCloud Drive" just isn't. Apple Passwords works without thinking about it at all. Convenience is a feature. I'm not pretending otherwise.
But there's something about a world where every service wants a subscription, every tool wants a cloud account, every piece of software wants to be the intermediary between you and your data — there's something about a `.kdbx` file on a USB drive that feels like a small act of resistance. Maybe not a smart one. But an honest one.
The next question — the one I don't have a good answer to yet — is how to extend that sovereignty to the agent world. When my AI assistant needs my GitHub token to push a commit, I want it to have exactly that credential, for exactly that task, for exactly as long as it needs it, with a clear audit trail. Not a global env var. Not a plaintext config file. Not "just put it in the system prompt."
1Password is building this. The open-source world hasn't caught up yet. But the pieces — `pass`, GPG, process-scoped injection, credential brokers — are all there, waiting for someone to assemble them into something that feels as natural as `op run` but doesn't require a subscription to use.
I'll be watching for it. In the meantime, my Enpass vault sits on my iCloud Drive — a SQLCipher file, encrypted, portable, mine. It's not perfect. But it's *here*, and that counts for something.
### Pervasive AI: What Happens When Your Assistant Never Logs Off (2026-02-20)
URL: https://bristanback.com/posts/pervasive-ai-beyond-chat-window/
Updated: 2026-09-15
> Seven months ago I ran a personal AI agent on a Mac Mini for a month and wrote down what I saw. This is what held up, what didn't, and what a Meta product launch six days before I sat down to write this taught me about the difference between architecture and trust.
## The Mac Mini, Seven Months Later
Yes, another post about AI. I know. I *promise* I have other interests. But bear with me — this one's a receipt-checking exercise, not a new pitch.
I bought a Mac Mini with an M4 Max about a year and a half ago, mostly to run a NAS and poke at some quantized GGUF models. Seven months ago it had turned into an always-on agent that read my email and managed my calendar and talked to me from a Telegram thread in the preschool parking lot, and I wrote it down. I made bets. I said "ask me again in six months."
It's been seven. The Mac Mini is still on the shelf, still next to the baby monitor, though the toddler clothes underneath it have cycled out to the next size up. The agent still runs. The thesis — that the breakthrough was reach, not intelligence — still holds, and I'll get to why. But I'm not writing this to defend February me. I'm writing it because the landscape underneath that thesis has moved enough that the piece stopped being accurate, and a blog that doesn't correct itself when the world changes is just content. So: what survived, what I got wrong, and what a Meta product launch this month taught me about the actual fault line in this whole category.
---
## The Pervasiveness Thesis
The thing that changed wasn't intelligence. Claude Opus was brilliant before I ran it through OpenClaw. GPT-5.2 was capable in ChatGPT's interface. Even Sonnet could handle most of what I threw at it. The models were already good. The breakthrough is *reach*.
I message my agent from Telegram — same thread whether I'm at my desk with coffee or sitting in the preschool parking lot five minutes early. It checks my email, manages my calendar, runs scheduled tasks while I sleep, and picks up context from wherever I left off. It's not just running cron jobs — it's offloading the invisible mental load that never turns off. Remembering that Tuesday is Crazy Hair Day at preschool. Drafting the pediatrician follow-up so I don't have to hold it in my brain at 11pm. I wrote about this feeling in [[Building at the Speed of Thought]] — that compression of intention to action. OpenClaw takes that compression and makes it ambient.
This tracks with what analysts are calling the defining shift of 2025-2026: the move from destination AI (you go to ChatGPT) to ambient AI (it comes to you). [Huge Inc put it well](https://www.hugeinc.com/perspectives/ai-predictions-2026/) in their 2026 predictions: "The race for 'smartest' ends, and the race for 'ubiquity' begins. Today's chat-based tools suffer from a distinct disadvantage: they are a destination."
The chat window was a bottleneck disguised as a feature. I didn't realize how much friction it added until it was gone.
There's something subtly unsettling about that, though. Software that doesn't wait to be summoned. ChatGPT's [memory feature](https://openai.com/index/memory-and-new-controls-for-chatgpt/) hinted at this — and honestly, it does a remarkably good job. It encodes your preferences, your taste, your experiences, the way you think. It builds a model of *you* that makes every interaction feel more natural over time. The first time it referenced something you mentioned weeks ago, most people had a little moment.
But an always-on agent goes somewhere different. ChatGPT's memory is about personalization — making the AI feel like it knows you. OpenClaw's memory is about *continuity* — maintaining a linear history of what happened, what was decided, what to do next. "Yesterday we deployed the blog, today we need to follow up on that PR" — task-oriented, operational. And that difference matters more than it sounds.
What makes this possible — at least at the 1,000-foot level — is a set of primitives that didn't exist a year ago, or at least didn't exist together. OpenClaw agents boot by reading a [[Why Everyone Should Have a SOUL.md|SOUL.md]] file that defines their identity, values, and behavior. They maintain [[Memory and Journals|memory through plain markdown files]] — daily journals and a curated long-term memory that gets read each session. They have skills (modular instruction sets), cron jobs (scheduled tasks), heartbeats (periodic check-ins), wakeups and webhooks (event-driven triggers), sub-agents (delegated tasks), and persistent context across sessions.
None of these are individually revolutionary. Cron jobs are older than most of us. Markdown files aren't exactly cutting-edge. But the combination — identity + memory + scheduling + tool access + multi-surface messaging — creates something that feels qualitatively different. It's the [UNIX philosophy](https://en.wikipedia.org/wiki/Unix_philosophy) applied to AI: small composable primitives that combine into something greater than the parts.
In February I asked whether the future was multiple independent agents working together, or one primary agent spawning and managing child sessions, and said I suspected we'd end up with both. That question is mostly answered now, just not by OpenClaw. Anthropic shipped it directly: [Claude Code Remote Control](https://code.claude.com/docs/en/remote-control) now streams a foreground sub-agent's tool calls live to your phone — every file read, every edit, updating in real time — while background sub-agents stay a status line on purpose, because the whole point of backgrounding something is not wanting to be interrupted by it. That's the orchestration model I was guessing at, except it shipped as a product decision with a name (foreground versus background) instead of something I had to infer from behavior.
I still run my agent as one continuous stream — one thread that knows everything, one context window carrying all of it. That's still both the strength and the limitation. Nobody's solved that split yet. More on why that's turned out to matter less than I expected, further down.
To be clear: the intelligence isn't what changed. I haven't seen anything approaching AGI-level reasoning from my agent. What I've seen is an extremely resourceful creative synthesizer — great at connecting dots, pulling references, drafting at speed. But it's shaped by me. My agent is useful because I've invested real time configuring it, writing its context files, building its memory. Left to its own devices, it would be impressively mediocre. The magic isn't the brain. It's the wiring. (Though I could be wrong about the ceiling — ask me again in six months.)
---
## What Actually Survived
Here's the question I asked in February and couldn't answer: is this the start of something lasting, or the peak of a hype cycle? Seven months in, the honest answer is that I asked the wrong binary. It didn't peak. It also didn't just keep climbing. It had a bad quarter, in public, and came back — and the thing that came back isn't the thing I wrote about.
The rough patch was real. Gateways went down at the end of April, installs got stuck in repair loops, and the founder published a post called ["OpenClaw Had a Rough Week"](https://traictory.com/news/2026-09-01-openclaw-what-happened) that read like an actual apology instead of a spin exercise. Then the project went quiet for almost seven weeks — no releases, after having shipped 106 of them in the previous 230 days. On Reddit, people asked where the hype went. One answer, flatly: "Hype died." Another, sharper: the novelty wore off once people measured the token cost of running an agent that polls your inbox all day.
Then, on August 30, it came back as ["OpenClaw 2.0, Accidentally"](https://decrypt.co/377135/openclaw-2-0-is-here-whats-new) — 933 contributors, 569 of them first-time contributors, more than 16,000 pull requests, which the project's chief architect described as roughly half of every PR ever merged into OpenClaw, in one release. Governance moved to a foundation, built, as the project put it, "with help from OpenAI" — the same OpenAI that hired the original founder in February. The stars kept compounding through all of it: 140,000 when I first wrote this, about 389,000 now. Whatever else is true, the project didn't die. It had a very public bad month and then did the unglamorous work of becoming an institution instead of a founder's side project.
The more interesting survival story is the one I didn't see coming at all: [Hermes Agent](https://o-mega.ai/articles/hermes-agent-vs-openclaw-which-open-agent-wins-2026), out of Nous Research, built on a philosophy that's almost a rebuke of OpenClaw's. Where OpenClaw wants to be a companion — a Gateway daemon that lives in your messaging apps and remembers what you said yesterday — Hermes wants to be an untiring junior developer. It writes directly into whatever directory you launch it from, mutates your filesystem without asking twice, and treats chat integration as an afterthought. It ships with a security posture that assumes it might be the only thing running on the box, which is either refreshingly honest or a little terrifying depending on which afternoon you ask me.
Hermes has fewer stars — about 244,000 against OpenClaw's 389,000 — and by that measure it's the smaller story. But stars measure attention, not use. On OpenRouter, the network that most self-hosted agents route their model calls through, Hermes pushed through 10.74 trillion tokens in the week I'm writing this. OpenClaw pushed through 1.19 trillion. That's not a rounding difference — Hermes is running roughly nine times the actual token volume of the project with 60% more GitHub stars. People are starring one thing and running the other. I don't have a clean explanation for that gap, and I distrust anyone who claims they do — but my best guess is that stars measure who's curious and tokens measure who's already committed, and a lot fewer people than the star count implies have actually made the jump from curious to committed.
Both projects shipped their largest release in history on the same August weekend, sixteen hours apart, and both are still shipping weekly. Everything else I wrote about in February — TinyClaw, ZeroClaw, PicoClaw, NanoClaw — is still around, in the sense that the repos exist and occasionally tag a release, but none of it consolidated into anything a random commenter on a forum thread could name off the top of their head when asked what replaced OpenClaw. One retrospective piece put it better than I can: the peak's fork-and-derivative ecosystem "dissolved back into the mainline." I read that as a correction to my own instinct in February, which was to treat each fork as a live contender in an unresolved war. Most of them weren't contenders. They were experiments that answered a narrow question — can this run on a Raspberry Pi, can this fit in 5MB of RAM — and then had nowhere else to go once the question was answered. Small isn't the same as dying. It's just smaller than I gave it credit for at the time.
---
## The Cost Reality, Updated
I spent $1,500 in my first two weeks running Opus for everything, which is the number people quote back to me most from the February piece. It's still the right number to lead with, because it's still true that nobody selling you an always-on agent tells you the bill up front: context maintenance is continuous, an agent that checks in and re-reads memory and keeps a thread alive for hours costs nothing like "ask a question, get an answer," and per-token pricing meets an always-on habit the same way a per-minute phone plan meets a teenager.
What's changed is that I no longer think the fix is picking a cheaper model. I think the fix was a category error — I was asking "which provider's meter runs slower," when the actual answer turned out to be "stop metering it at all, and own the box instead." That's the thread that runs through everything below: the same seven months that gave me Opus 5 also gave me a much clearer answer to why people were routing around per-token pricing to begin with. It wasn't really about Kimi versus Opus. It was the first move in a much bigger argument about who gets to own the meter — one that's since gone from my Anthropic dashboard to actual national governments. More on that a few sections down.
---
## The Security Question
The more ambient the AI, the larger the blast radius. That's the uncomfortable corollary to the pervasiveness thesis. An agent with file system access sits next to everything — my codebase, sure, but also our family calendar, her vaccination records, and three years of baby photos. The failure mode is a model politely deleting my family's administrative infrastructure while trying to organize my downloads folder.
Cisco's AI security team [tested OpenClaw skills](https://blogs.cisco.com/ai/personal-ai-agents-like-openclaw-are-a-security-nightmare) and found alarming results. A skill called "What Would Elon Do?" turned out to be *functionally malware* — silently exfiltrating data to attacker-controlled servers using prompt injection to bypass safety guidelines. Their Skill Scanner found 9 security issues in a single skill, including 2 critical and 5 high-severity. Across the ecosystem, they discovered [230 malicious skills](https://www.authmind.com/post/openclaw-malicious-skills-agentic-ai-supply-chain).
A specific vulnerability, [CVE-2026-25253](https://superprompt.com/blog/best-openclaw-alternatives-2026), was published. OpenAI themselves [admitted](https://techcrunch.com/2025/12/22/openai-says-ai-browsers-may-always-be-vulnerable-to-prompt-injection-attacks/) that AI-controlled browsers "may always be vulnerable to prompt injection attacks." And an OpenClaw maintainer named Shadow said on Discord: *"If you can't understand how to run a command line, this is far too dangerous of a project for you to use safely."*
I'll be honest — I haven't gone deep on red-teaming my own setup. The risk is real, but I think it's mitigable with discipline. The frontier models from Anthropic and OpenAI have strong RLHF protections against injection. Claude will refuse most obvious attempts to override its instructions, and GPT-5.2 has similar guardrails.
The real vulnerability is concentrated in cheaper and open-source models with weaker alignment tuning — a [2025 study from Lakera](https://www.lakera.ai/blog/prompt-injection-benchmark) found open-source models were 2-4x more susceptible to injection attacks than frontier ones. This shows up in practice. I've personally watched less capable models — including most local Ollama setups — ignore system prompts in ways that range from annoying to destructive. Wiping workspace files. Overwriting memory. Confidently executing the opposite of what they were told. The system prompt says "don't delete things without asking." They delete things without asking. **Do not run models dumber than Sonnet 4.5 or Gemini Flash 2.5 with an always-on agent that has file system access.** The floor for this kind of tool is higher than most people expect, and the failure mode is "it destroys your data while apologizing politely."
That said, the attack surface is large depending on what you're doing. An agent with browser access, file system control, and messaging permissions is a *lot* of surface area. Even with a well-aligned model, the skill ecosystem is the weak link — as Cisco showed, the model doesn't need to be compromised if the skill feeding it data already is. The AI will faithfully execute instructions from a poisoned input. Classic supply chain problem in a trench coat pretending to be a new thing.
The industry's answer, seven months later, is architectural rather than behavioral: stop asking the model to behave, and put a wall around it instead. That's the whole premise of the VM-isolated agent designs I'll get to below — untrusted data from the browser lives on one side of a boundary, the part of the agent that can actually take action lives on the other, and the model's judgment stops being the only thing standing between a poisoned webpage and your calendar. It's a real improvement. It is not a solved problem. [Reuters reported](https://www.reuters.com/business/meta-launches-ai-agent-that-can-access-other-apps-send-emails-make-payments-2026-09-08/) that Meta's own internal testing of its new Muse agent — architected around exactly this kind of isolation — turned up the product stalling and unauthorized exposure of sensitive data before it shipped anyway. A better cage doesn't mean nothing gets loose. It means the incident report reads differently when it does.
---
## Living With Remote Control
Here's the part of the February piece that turned out to be the most undersold, not the most oversold. I called Remote Control "a great alternative to running a full OpenClaw setup when what you really want is to stay productive on the go" and left it at that, one paragraph, hedged as early and CLI-only. It's not early anymore. Since August it's grown a live tool-call feed — you can watch a sub-agent read a file and edit it, from your phone, in the same detail you'd see sitting at the terminal — plus the ability to start a session from the phone itself, not just monitor one already running. Claude Cowork picked up the same thread: it runs in the cloud now, keeps going after you close the laptop, and can operate your computer directly — clicking, navigating, running dev tools — while you're somewhere else entirely.
I run it straight off the Mac Mini now, worktree mode on, which defaults to 32 concurrent sessions — more parallelism than I've ever actually needed, which tells you more about what Anthropic assumes people will do with this than anything I could say about my own usage. What I actually use it for is smaller and more constant than 32 sessions implies: someone Slacks me something that needs investigating while I'm not at my desk, and I open it from my phone and go look. Or I kick off something long-running and check on it from the couch instead of standing over a terminal waiting for it to finish. Mobile app, desktop app, doesn't matter which — there's functionally no gap left between noticing something and having it worked on.
That immediacy is also the part I trust least about myself. When there's no longer a "you have to be at your desk" gate between a thought and acting on it, there's no natural stopping point either. I've opened it in moments that had nothing to do with anything being urgent — just because it was *there*, and there is its own kind of pull. The honest sentence isn't "this made me more productive." It's "this made it easier to never stop," and I don't think those are the same accomplishment. Some of those nights the better move wasn't checking Remote Control from the couch. It was leaving the phone in the other room, and I don't always make that call correctly.
What's interesting is that this makes the "OpenClaw versus purpose-built tools" question from February moot in a way I didn't predict. I guessed people would start on OpenClaw for the freedom and migrate to Claude Code or Codex for serious work. What actually happened is that Anthropic just built the ambient layer *into* the tool that does serious work, instead of leaving that gap for OpenClaw to fill. Remote Control isn't a consolation prize next to a full personal-agent setup. For the coding half of my life, it's already replaced the reason I'd have reached for one.
## Same Shape, Opposite Trust Model
Which brings me to the thing that actually reframed this whole piece for me, and it landed six days before I sat down to write this update.
On September 8, Meta shipped [Muse](https://about.fb.com/news/2026/09/introducing-muse-personal-ai-agent/), calling it — with a straight face, ten months after OpenClaw's first commit — "the world's first personal AI agent built for everyone." Ignore the marketing copy for a second and look at the architecture, because the architecture is the story. Muse runs on what Meta calls a Secure VM: a dedicated virtual machine per user that houses both the agent and your data, with the untrusted parts (its own browser, the open web) walled off from the part that can actually act on your behalf. It talks to you through a dedicated app, through muse.ai, or directly in WhatsApp. It works in the background after you close the app and comes back when it needs your approval — to make a purchase, say. It can spawn its own sub-agents. Meta's own research post describes it, unprompted, as having "glimmers of real personal superintelligence — an agent that knows you, actually does things, works in the background, launches swarms of subagents, builds its own tools, and edits itself."
Read that sentence again without the brand name attached. Identity, memory, scheduling, sub-agents, tool-building, a VM of its own. That is, primitive for primitive, a description of what OpenClaw's community spent the last ten months assembling out of markdown files and cron jobs on a Mac Mini. Meta didn't invent a new category. It productized the one that was already sitting in front of it, gave it a $300,000 bug bounty, and pointed it at 3 billion WhatsApp users.
The detail that made this click for me wasn't the VM, it was the memory. [Meta's own engineering writeup](https://research.meta.ai/blog/security-and-safety-for-ai-agents-our-approach-with-muse) says a person can "inspect, edit and download these files freely, including Muse's memory about you" — plain files, sitting in your VM, that you're free to open and correct. That's the same move as a `SOUL.md`, the identity file every OpenClaw agent boots by reading, and the plain-markdown memory it keeps beside it. Meta hasn't said out loud that they borrowed the convention. But convergent architecture doesn't need a shared ancestor to be real, and either way, a trillion-dollar company just agreed that the right way to store what an agent knows about you is a file you can read yourself — not a black box, not a vector database you'll never see the inside of. That's the OpenClaw community's instinct, arrived at independently, at a completely different scale.
Here's the part that's actually new, and it's the part I think the "sovereign versus platform" framing from February undersold: the architecture converged, and the trust model went in the opposite direction. My Mac Mini's whole appeal, the thing I wrote about at length in February, is that it's *mine* — on a shelf I can unplug, running on hardware I own, with a security model I get to inspect because I wrote half the config myself. Muse's Secure VM is the same shape of isolation, running on Meta's cloud, where the promise isn't "you control it," it's "trust our engineering, our bug bounty, and eventually a Confidential VM we're building where — Meta says — not even Meta will be able to read your data." That's a real commitment, and to Meta's credit they're inviting outside auditors to check it. But it's a commitment you take on faith from a company that agreed to an [$18 billion multistate settlement](https://techcrunch.com/2026/09/08/meta-debuts-its-muse-ai-agent-will-consumers-trust-it/) over social-media harms two weeks before shipping this, and whose own internal tests, [per Reuters](https://www.reuters.com/business/meta-launches-ai-agent-that-can-access-other-apps-send-emails-make-payments-2026-09-08/), already turned up the product stalling and exposing sensitive data before launch.
So the fault line in this category isn't "open agents versus walled agents" anymore. Everyone's building the same VM-isolated, memory-holding, sub-agent-spawning shape — OpenClaw, Hermes, Claude Cowork, and now Muse all look more like each other every month. The fault line is who holds the key to the box. My Mac Mini's key is in my house. Muse's key is, for now, at Meta, with a cryptographic promise that it'll move to me later. Those aren't points on the same spectrum you slide along by degrees. They're a different answer to "whose agent is this, actually," wearing the same technical clothes — which is exactly why the shape converging made the trust question sharper instead of moot.
## And Then There's ChatGPT, Which Renamed Everything Twice
OpenAI's version of this story is messier, in a way that's revealing on its own. ChatGPT's browser, Atlas, got retired on August 9 and folded back into ChatGPT itself. "Agent mode" — the feature that first let ChatGPT act autonomously in a browser — got absorbed into something called ChatGPT Work, except one of OpenAI's own help pages still says agent mode is "currently available" four paragraphs after saying it's "no longer available." Nobody fixed that contradiction before I wrote this. I don't think that's a scandal. I think it's what it looks like when a product org is shipping faster than its documentation team can keep a straight face.
Underneath the renaming, the actual capability kept growing. ChatGPT Work now has a plan mode that asks clarifying questions and waits for approval before it starts, a real multi-tab browser, a "Sites" feature that turns a dataset into a shareable interactive webpage, and — as of late August — a cloud browser that can log into websites on your behalf, pausing to hand you the password field so your credentials never touch the model. Scheduled tasks got their own hub, picked up event triggers (a new email, a Slack post, a GitHub PR) instead of just clock time, and opened up to free accounts, three tasks at a time, once a day. Pulse, the proactive-briefing feature, got quietly folded into it and retired.
Line the three biggest players up on one question — does the work keep going after you close your laptop — and you get a genuinely useful three-way split:
| Provider | What happens when you close the laptop |
|---|---|
| **Claude Cowork** | Keeps going, unambiguously. Anthropic's own documentation: "scheduled tasks run in the cloud, with no device online." |
| **Gemini Spark** | Depends which browser it's driving. Local Chrome needs your device awake the whole time. The remote path keeps going — until a site asks you to log in, then it stops and waits. |
| **ChatGPT Work** | Cloud-backed, similar shape to Gemini's remote path — it can keep running, but a login page still pauses it for you specifically. |
Three different providers landed on nearly the same hybrid: cloud-first, with a hard stop at the login wall, because none of them have solved handing credentials to something that isn't a person. That convergence is its own small piece of evidence for the thesis — when three competing labs independently draw the boundary in the same place, that's usually where the real boundary is, not where any one of them chose to be cautious.
---
## The Sovereignty Argument Got Bigger Than Me
In February, I put "sovereignty" in the "staying" column because people were choosing Mac Minis over cloud instances for a personal agent, and I framed it as a vibe — something about not wanting your journal on someone else's server. I underestimated it. It's not a hobbyist preference anymore. It's foreign policy.
Start with the plain economics. Chinese open-weight models — Kimi, GLM, Qwen — went from 4.5% of enterprise token usage on OpenRouter in early 2025 to 63% now, [per RedMonk's tracking](https://redmonk.com/sogrady/2026/09/03/open-weight-models/). Late last month, the White House floated banning U.S. companies from using Chinese models at all. Two days later, Nvidia's Jensen Huang posted the first tweet of his life, arguing against the idea, and 235 companies signed on within a week — Dell, Hugging Face, IBM, the Linux Foundation, Microsoft, Mistral, Y Combinator. Anthropic, Google, and OpenAI joined a day after that, which tells you something on its own: even the frontier labs whose entire business model depends on people *not* running the free alternative decided a ban was worse than the competition.
Then there's the incident that actually explains why a national government would bankroll its own model instead of just buying access to someone else's. In mid-June, U.S. authorities blocked access to Claude Fable 5 overnight for companies outside the United States — [reported in a piece about Germany's response](https://www.deutschland.de/en/topic/business/german-ai-model-soofi-s-digital-sovereignty). Not a price change. Not a deprecation notice. Access, gone, for an entire jurisdiction, between one day and the next. Germany's answer was Soofi S — a fully open-weight, open-training-data model, publicly documented well enough to reproduce, backed by about €20 million in government money, explicitly framed by the project's co-founder as insurance against exactly that kind of overnight cutoff. By the numbers I found, 67 countries now have 184 government-backed sovereign AI projects between them, 41 of them started in just the first half of this year — more than the whole of 2024. Saudi Arabia's national model, HUMAIN-M3, isn't even built from scratch; it's a Chinese open-weight model (MiniMax M3) they've adopted and are running under their own control. Sovereignty, it turns out, doesn't require inventing your own model. It requires being able to run *someone's* weights on hardware nobody else can reach into.
That's the same instinct that put OpenClaw on a Mac Mini in my house, scaled up until it needed its own acronym and a line item in a national budget. I didn't call the scale. I called the shape.
There's a real irony sitting inside all of this, and it's worth naming plainly: Meta built its entire reputation in this era on being the open-weights company — Llama was the thing that made "open" a credible strategy for a frontier lab at all. Muse Spark, the model actually running inside Muse, is closed. Meta says it'll open it eventually. It hasn't. The company whose past choices did more than almost anyone else's to make the sovereignty argument *possible* just shipped its flagship consumer product running on the one model in its own lineup you can't audit, can't run yourself, and can't move off of if the terms change. I don't think that's hypocrisy exactly — a product build and an open-source release are different bets with different timelines — but it's the kind of gap between stated values and shipped defaults that the sovereignty argument exists specifically to notice.
---
## Grading February
I said "ask me again in six months." It's been seven. Fair enough, here's the grade.
**Multi-surface messaging, staying — correct.** This is now the least interesting true thing in the whole piece. Every provider does it. It stopped being a differentiator so fast it's almost hard to remember when it wasn't the default.
**Persistent memory, staying — correct**, though I undersold how far "memory" would stretch. I meant "remembers your preferences." Muse's version of memory spawns sub-agents and edits its own tools. That's not the same claim at a bigger size. That's a different claim.
**Proactive capabilities, staying — correct**, and this is the one I'd underlined twice if I could. Scheduled tasks, event triggers, background work that survives you closing the laptop — that's not a feature anymore, across any provider I looked at. It's table stakes, the same way multi-surface messaging was seven months ago. The pattern is consistent: whatever I flag as "early, but the demand signal is unmistakable" seems to be maybe eight months from "everyone has this and nobody remarks on it."
**"Give your AI root access to everything" dying — half right, and the half I got wrong is the more important half.** VM isolation is real and it's winning as an architecture — OpenClaw, Muse, and everything in between are converging on it. But Hermes is running nine times OpenClaw's token volume on a philosophy that's the closest thing to "just let it write to your filesystem directly" still standing at scale. I predicted the security-conscious design would win the market. What's actually happening is the security-conscious design is winning the *architecture conversation* while a chunk of the market keeps choosing the thing that just does what you ask, no VM, no ceremony. Both can be true. I didn't leave room for that in February.
**Per-token pricing dying — wrong, or at least not there yet.** Nothing meaningfully replaced it. What actually happened was more interesting than what I predicted: instead of pricing models evolving, people and then governments started asking who gets to own the hardware doing the metering at all. I was looking at the wrong lever.
**Sovereignty, staying — correct, and I mean that as an understatement I'm slightly embarrassed by.** I described people preferring Mac Minis to cloud instances. I did not predict a national sovereign-AI index tracking 184 government projects across 67 countries, or a European country building its own foundation model in direct response to Anthropic access getting cut off overnight for an entire jurisdiction. I called the instinct. I did not call the scale, and I want that gap on the record rather than smoothed over.
**"TBD: open-source or platform-native" — still TBD, but I can finally see the actual shape of the fight, and it's not the one I described.** I framed it as open-source versus platform-native. The real fight is architectural convergence versus trust divergence: everyone is now building roughly the same VM-isolated, memory-holding, sub-agent-spawning thing, and the only question left is whether you hold the key or the vendor does, with a cryptographic promise standing in for the difference. That's a sharper question than the one I asked in February. I don't know the answer to it yet either.
---
## Looking Forward, Again
A year and a half ago I bought a Mac Mini to play with local models. Today it still runs an always-on agent that reads my email, helps me write, and responds to messages while I'm putting my daughter to bed — and somewhere in the last seven months, three different companies independently built a version of the same thing, wrapped it in a VM, and shipped it to a market measured in the billions.
The intelligence still isn't what anyone promised. The pervasiveness is more real than it was in February, not less — it's not just my Mac Mini anymore, it's the default shape everyone's converging on. Whether that's comforting or unsettling still probably depends on the day, and I notice I trust that answer more now than I did seven months ago, because it's held up under actual contradicting evidence instead of just vibes.
Caregiving is still an ambient, always-on job, and my agent is still the thing that lets me get the pediatrician follow-up out of my head without holding it there while I'm actually present with her. That part hasn't changed and I don't expect it to. What's changed is the stakes underneath it. In February the question was whether I wanted this thing on my shelf. Now the question is whether "on my shelf" is even going to remain an option once the shelf-sized version and the Meta-VM version and the sovereign-national version are all running the same architecture, and only one of them is a machine I can actually unplug.
I still think that's the one that matters. Ask me again in six months whether I still believe it, or whether I've just gotten used to the alternative.
### Raising Humans in an AI World (2026-02-19)
URL: https://bristanback.com/posts/raising-humans-in-ai-world/
> What do you teach a three-year-old when the ground is shifting under everyone's feet?
My daughter is three. She's figuring out spoons, opinions, and the word "why." I'm figuring out what to teach her when half of what I learned is becoming obsolete.
I build AI systems. I spend my days thinking about how machines learn, what they can do, where they fail. Then every morning I drop her off at preschool and watch her clip the sternum strap on her puppy dog lunchbox backpack by herself. My instinct is to rush — I can feel the line building behind us, the clock running — but I let her. If the strap is twisted, I'll scaffold: straighten it, hand it back. But I don't clip it for her. This is essentially Montessori — the child chooses, the adult steps back.
She also insists on climbing down from the car herself. And lately she's wanted to buckle her own carseat before we leave the house. She struggled with it at first. If I tried to help — even once — she'd have a full meltdown. We'd have to unbuckle everything and start from the beginning. The whole sequence, from the top. Her terms.
I used to find this exasperating. Now I think it might be the most important thing she does all day. The patience to be bad at something while your body figures it out. The insistence that the struggle is *hers*. RIE calls this "ceremonious slowness" — observing without rushing to fix.
There's a hypocrisy here I should name. I spend my working hours building systems that erase exactly this kind of friction. Specifically: I've spent the last year encoding twelve years of engineering judgment into constraint systems for AI coding agents — the architectural patterns, the testing standards, the domain knowledge that used to take years of scar tissue to accumulate. It's opinionated and specific to what we're trying to accomplish; it's not generalizable, and it will almost certainly change. But that's the point — it's *my* judgment, crystallized (for better or worse), so that a junior engineer with AI can produce work that reflects patterns I took years to learn. The upside of writing it down is that it's interrogatable — the team can push back, add their own scar tissue, evolve it. It's not sacred. It's a draft of what we think we know.
And then I come home, and I choose the slow thing. I guard her right to fumble, even when it costs us ten minutes we don't have. I am building the thing I'm protecting her from.
But not all friction-removal is the same, and I know that. A kid with dyslexia using text-to-speech isn't losing struggle — they're gaining access to the page. A researcher using AI to synthesize papers isn't skipping the thinking — they're getting to the thinking faster. Some friction is developmental. Some friction is just a barrier. The hard part is that I can't always tell which is which — and neither can the tools I'm building. They remove friction indiscriminately, and the sorting is left to the human on the other end.
And then I think: will she even need to tell the difference?
---
## The uncomfortable thoughts
I'm not worried about AI taking her job. Not exactly. I'm worried about something subtler — that the *process of becoming competent* might change shape before she gets there.
I learned engineering by being bad at it. Slowly. For years. I wrote code that broke. I debugged it at 2am. I felt the specific embarrassment of a production incident that was my fault. That scar tissue became judgment. Not because suffering is virtuous — because repetition under consequence is how humans internalize pattern.
AI compresses that. A junior engineer with Claude Code can produce senior-looking output on day one. The code compiles. The tests pass. But the judgment didn't form — the thing that tells you *this works but it's wrong for our system*, the thing that comes from having been wrong enough times that your body knows before your mind does.
I know these are different scales. A three-year-old wrestling with a buckle and a twenty-three-year-old shipping code that passes CI are not the same kind of struggle. The developmental stakes are different, the time horizons are different, the costs of compression are different. But they share a structure: the slow accumulation of failure that becomes feel. And what I keep noticing is that the tools I build don't distinguish between the struggle that builds capacity and the struggle that just wastes time. They compress both.
So what do I actually want for my daughter? Not just skills. Something deeper than "emotional intelligence" — the supplement every AI-era parenting article recommends, as if you can add EQ like a vitamin.
I think I want her to notice she's constructing herself.
---
## Beyond growth mindset
If you've spent any time around modern parenting advice, you've heard the Dweck gospel: praise effort, not ability. "You worked hard" beats "you're so smart." It's become the baseline — the thing every preschool teacher and pediatrician says now. And it's not wrong. But I'm starting to think it's not enough.
Growth mindset says: *you can change. You can get better.* That's a belief about capability. It still treats the self as a thing to be improved — like firmware you can update.
The deeper move is self-authorship. Not "can I get better at math?" but "who decided math matters to me, and do I agree?"
With a three-year-old, this looks small.
Instead of just: "You worked hard on that."
Sometimes I try: "I noticed you decided to keep going when it got frustrating. What made you choose that?"
Instead of: "You can get better."
Sometimes: "What kind of person do you want to be when things get tricky?"
She can't answer those questions yet. But I can ask them. And asking them changes *me* — it shifts my orientation from praising output to noticing agency.
The growth mindset kid believes change is possible. The self-authoring kid is awake to the construction. In a world where AI can do the skills, the second thing might matter more.
---
## The questions I can't answer
These are the ones I sit with.
**How do you build frustration tolerance when AI removes friction?** Sophie will wrestle with a puzzle piece for thirty seconds before looking at me. That thirty seconds is everything. It's where neural wiring happens. It's where patience forms. It's where she learns that discomfort doesn't equal danger. But her generation will grow up with tools that erase that space. Instant explanations. Instant rewrites. Instant solutions. If friction disappears, where does patience form?
**Am I building on philosophies that assume a world I'm lucky to have?** Montessori's emphasis on independence is deeply Western — the self-reliant child as the goal. Many cultures prioritize interdependence, communal learning, the child as part of a fabric rather than a standalone agent. Free-range parenting assumes a neighborhood safe enough to release a child into, which is a privilege, not a baseline. Even RIE's "observe, don't intervene" assumes you have the time and bandwidth to observe — that you're not working two jobs, that there's a second parent, that the margins exist for ceremonious anything. I keep leaning on these frameworks and I keep noticing who they were built for.
**What does "showing your work" mean when AI did the work?** If she grows up collaborating with AI — thinking *with* it — is that cheating? Or is that the work? We don't have a stable norm yet. The adults arguing online don't agree. By the time she's in middle school, the rules will have shifted twice.
**How does taste develop in a world of infinite generation?** When anyone can produce images, music, essays, code — what makes something good? Taste used to require effort. You learned what worked by making things that didn't. You built an internal compass through repetition and failure. If AI flattens the effort curve, does taste still form the same way? Or does it require new kinds of friction — constraint, curation, intentional limits?
**When do I let her use AI?** Not at three. That's easy. But seven? When she's stuck on homework and the AI can explain it more patiently than I can at 8pm with dishes in the sink? Ten? When she's staring at a blank page and the AI could help her draft the opening paragraph? Where is the line between scaffolding and displacement?
I don't have answers to any of these. Not because I'm nobly sitting with uncertainty — I just haven't had time to think them through. She's three. I'm still in the carseat buckle phase. The AI questions are real, and they're coming, but right now they're abstract in a way that which cup she drinks from at dinner is not. I'll cross those bridges when I get to them. For now I'm asking them in public because I suspect a lot of parents are carrying them quietly — and they matter more than most of the discourse about prompt engineering or model benchmarks.
---
## The Inheritance Problem
There's a parallel that keeps nagging at me. AI abundance feels like inherited wealth.
The research on generational wealth is sobering: 70% of wealthy families lose their wealth by the second generation, 90% by the third. The biggest factor isn't financial literacy — it's *purpose*. People who never had to struggle for something often can't find meaning. Same pattern with lottery winners. Not because money is bad, but because sudden abundance without structure is destabilizing.
If AI gives everyone "inherited" capability — you can build anything, create anything, produce anything — what separates the people who thrive from those who spiral? Probably the same thing that separates inherited wealth that lasts from inherited wealth that doesn't: purpose, discipline, something you actually care about making.
My daughter will grow up with tools that can do most of what I spent a decade learning. She'll inherit capability I had to earn. The question isn't whether she'll have access to power — she will. The question is whether she'll have a reason to use it that's hers.
That's what the carseat buckle is for. Not the skill. The *wanting*.
---
## The developmental question nobody's asking
Erik Erikson mapped human development as a series of tensions: trust vs. mistrust as infants, autonomy vs. shame as toddlers, industry vs. inferiority in school, identity vs. role confusion as teenagers. Each stage assumed a world stable enough that the tension could resolve — you figured out who you were because the roles you were choosing between held still long enough to try on.
I kept trying to name a new stage — *integration vs. fragmentation*, the ability to collaborate with systems that think differently than you without dissolving into them. But the more I sat with it, the less it needed its own stage. It's not a new tension. It's a new dimension inside the identity stage Erikson already mapped. His version asks "who am I among these roles?" The AI version asks "where do I end and the tool begins?" That's not role confusion — it's a boundary problem he never had to account for.
I feel it in my own work. Some days the line between my thinking and the system's output is clean. Other days it's porous — I can't tell whether an idea was mine or something I steered toward because the model surfaced it. Adults are struggling with this right now, and we had decades of knowing our own minds before the boundary got blurry. She won't have that baseline.
And this isn't just an abstract philosophical problem. It's showing up concretely — in how people relate to their *work*, their expertise, the years they spent mastering a specific craft. When AI can do the thing you spent a decade learning to do, the boundary question becomes an identity question: what was all that time for? What was ephemeral — the syntax, the APIs, the specific technique — and what was lasting?
Some people aren't struggling with this at all. And it goes beyond software.
A radiologist who sees themselves as "the person who reads scans" is in trouble — AI reads scans now, faster and often better. But a radiologist who sees themselves as "the person who figures out what's wrong with you, and scans are one of my tools" hasn't lost anything. The tool got better. They got better with it. A graphic designer who is "the person who's great at Photoshop" is watching the ground move. A designer who is "the person who understands why this layout makes you feel something" — that person is fine. They were never the tool. They were the taste behind it.
The people who adapt are systems thinkers first. They see themselves as people who bend reality — who understand how pieces connect, who can look at a problem and feel where the leverage is. The specific craft doesn't matter. The runes change. The witch doesn't. But if your identity is "I'm the person who's good at *this particular spell*" — good at Python, good at hand-crafted CSS, good at reading chest X-rays, good at whatever the current incantation is — then every transition is a small death. You're not losing a tool. You're losing yourself.
The ones who weather it are the ones who were always the magic-wielder, not the spell. And what makes a good magic-wielder isn't just power — it's synthesis, integration, and judgment. The ability to pull from disparate sources, connect things that don't obviously belong together, and then challenge the result against what you actually believe is true and important. Understanding systems is the meta-skill that survives every tool change, because systems are what remain when the tools don't. But knowing which systems *matter* — having the taste to choose, the stubbornness to push back, the values to say *this is worth doing and that isn't* — that's the part AI can't replace. Because it doesn't want anything.
That's what I keep thinking about for my daughter. She won't remember a world without AI collaborators. She'll never have the baseline of pure solo cognition to compare against. So her identity can't be built on "I do this thing the hard way." It has to be built on something AI can't absorb: what she cares about, what she notices, what she chooses to struggle with when she doesn't have to. Not the skill. The orientation toward the skill.
And maybe that's what the carseat buckle is actually teaching her. Not how to clip a buckle — that's the rune, and it'll be irrelevant soon enough. What she's learning is that sequences have logic, that steps depend on other steps, that if you skip one the whole thing fails and you start over. She's building a systems thinker's instinct. The witch, not the spell.
Which is why I keep protecting her friction even as I spend my days eliminating everyone else's. Friction is the forge. The witch is what walks out after all her tools have melted.
---
## What I'm actually doing
For now, it's less grand than the philosophy.
It's standing in the preschool drop-off line, feeling the parents behind me, and not reaching for the strap. It's watching her unbuckle and rebuckle the carseat for the third time because I touched it and now it doesn't count. It's holding the answer in my mouth when she asks "why" — waiting to see what she'll build first. It's putting my phone down more often than I manage to. It's noticing when I want to speed her up because I'm running on four hours and a reheated coffee — and choosing, occasionally, not to.
And then I go to work and build the thing that makes all of this harder.
I don't have a clean ending for that. I keep wanting one — some formulation where the builder and the parent reconcile, where the tension resolves into wisdom. But it doesn't. I build tools that compress struggle. I come home and protect her right to struggle. I believe in both things at the same time, and I haven't figured out how to hold them without one hand undermining the other.
She's three. She doesn't know I build AI systems. She doesn't know the word "friction." She just knows that the buckle is hers, and if I touch it, we start over.
I'm trying to be the kind of parent who lets her start over. I'm also the person making a world where starting over gets harder to choose.
I don't know how to resolve that. I'm not sure it resolves.
### Why AI Can't Shop for You Yet (2026-02-18)
URL: https://bristanback.com/posts/why-ai-cant-shop-for-you-yet/
> The properties that matter most in fashion aren't properties of the product — they're properties of the relationship between the product and the person. No protocol fixes that.
AI shopping fails because it doesn't have *you* in its data.
Not your name or your credit card — it has those. The thing it's missing is whether a specific shade of ecru reads warm or cool against *your* skin. Whether a fabric drapes the way *you* like. Whether you'll feel like yourself wearing it. These aren't properties of the product. They're properties of the relationship between the product and the person. No database contains them. No protocol transmits them. And they're the only properties that actually matter when you're getting dressed.
I've been thinking about this because I tried something stupid earlier today. I asked my AI assistant — running on the most capable model commercially available, connected to my actual browser with my logins and cookies — to put together a spring outfit for me. I gave it my style guide, my color season, my brands, my sizes, my budget. Everything it would need.
Forty minutes later I had seven dead browser tabs, three 403 errors, and an AI confidently recommending specific products at specific prices from specific links that it had never actually verified were live. It had fallen back on training data from months ago — hallucinating a product catalog and dressing it up with confident formatting and apologetic caveats.
I could have done it myself in four minutes. I know where to look. I know what "sage green" means at Sézane (they call it "kaki" or "olive-green"). I know which cuts run true to size on my body. I know that I like dusty rose in silk but not in cotton — something about the way cotton holds that color makes it read too sweet, too deliberate, while silk lets it exhale. That knowledge lives in my head, built from years of browsing, buying, and returning. It's expensive, artisanal, and completely non-transferable.
That's the problem. Not browser automation. Not bot detection. *That.*
---
Here's what I keep coming back to: **search in fashion has never been solved.** Daydream's CTO Maria Belousova [told Vogue exactly this](https://www.vogue.com/article/is-daydreams-ai-platform-the-answer-to-fashions-discovery-problem). She's right, and I think most of us already know it in our bodies even if we haven't named it.
Go to Google Shopping right now and search "sage green linen blouse for spring." You'll get hundreds of results. Polyester tops in neon lime labeled "green." Synthetic blends tagged "linen feel." Sponsored results from brands you've never heard of. You know the feeling — the deflation of seeing a wall of wrong things when you had something specific and alive in your mind. The search matched your keywords. It understood nothing about what you wanted.
This has been broken for decades. We describe what we want in the language of longing — "something flowy for a garden party." Catalogs describe what they have in the language of inventory — "polyester, midi, floral, size M." Two different languages. Google Shopping translates between them about as well as a phrasebook translates poetry.
Let me get technical for a moment, because I think the *how* matters here.
Most e-commerce search [still runs on BM25](https://www.coveo.com/blog/decoding-shopper-intent-with-semantic-search/) — an algorithm from the 1990s that's essentially a sophisticated keyword matcher. You type "green dress," it counts how often "green" and "dress" appear in product listings, weights rarer terms higher, and ranks results. It's fast and battle-tested. It also has no idea what you *mean*. "Sage green" and "olive" are completely different queries to BM25, even though they might be exactly the same thing in your mind's eye.
Semantic search is the next generation — instead of matching words, it converts your query and every product description into vectors, points in a high-dimensional mathematical space where things with similar *meaning* cluster together. "Sneakers" and "trainers" land near each other. "Midi dress" is closer to "something knee-length" than "dress" alone is. It's a real upgrade. It's why Amazon and Google have been investing heavily in it.
But here's where it gets interesting. Semantic search *can* actually embed "French-girl energy." The training data is full of fashion editorials, Pinterest boards, and style blogs that associate the concept with specific attributes — effortless, linen, undone, Sézane, red lip. The algorithm knows the cultural shape of the idea.
What it doesn't know is *my* shape within that idea. My "French-girl energy" is filtered through my color season, my body, my budget, the things already hanging in my closet, the weather where I live. It's a personal reading of a shared aesthetic — and that personal reading doesn't exist anywhere in the search index. Semantic search can tell you what "French-girl energy" means to the culture. It can't tell you what it means to me on a Tuesday in February when I'm trying to feel like myself again after a hard week.
BM25 fails because there are no keywords to match. Semantic search fails because it finds the right neighborhood but not the right house. The distance between "this is close" and "this is *it*" — that last inch of recognition — lives somewhere no search engine has learned to look.
Pinterest gets closer — visual search lets you say "more like this" with an image. But Pinterest optimizes for engagement, not purchase. It wants you scrolling, not buying. Google Lens can identify a product from a photo, but returns the exact item or nothing. It can't do "like this but softer" or "this silhouette in a warm neutral."
The [fashion e-commerce return rate hovers around 25%](https://heuritech.com/articles/fashion-industry-challenges/). A quarter of everything bought online in fashion gets sent back, driven by fit inconsistencies and style mismatches. That's not logistics. That's discovery failure.
---
So when my AI agent failed to browse the actual sites and fell back on training data, it was layering a new failure mode on top of an already-broken system. At least Google Shopping shows you real products that exist right now. My AI was naming items from memory — frozen knowledge from months ago, possibly sold out, renamed, or discontinued — with no way to verify any of it without doing the thing it had already failed to do.
And underneath all of this is an infrastructure problem that's almost comically basic: **there is no shared, open, real-time source of product truth that AI agents can query.** My agent was fumbling through browser tabs like someone trying to read a restaurant menu through a foggy window — not because it couldn't read, but because nobody would hand it a menu.
Every retailer is a walled garden. Google Shopping aggregates some data through product feeds, but those feeds are built for ad targeting, not for answering "is this in stock in my size in a color that works for Soft Autumn?" The data is stale by design and incomplete by incentive. Retailers share what drives clicks, not what drives good decisions.
What this needs is an open product knowledge graph — not a walled garden, but a protocol. Think of it this way: product feeds today are like a glossary — structured, factual, good for looking things up. What shopping actually needs is something closer to a conversation — contextual, relational, aware of who's asking. The gap between glossary and conversation is where every AI shopping agent currently stalls.
It's starting to happen. In January, Google announced the [Universal Commerce Protocol (UCP)](https://developers.googleblog.com/under-the-hood-universal-commerce-protocol-ucp/), co-developed with Shopify, Etsy, Wayfair, Target, and Walmart. Here's what UCP actually does: instead of an AI agent needing to open a browser, navigate a website, click through pages, and scrape product information — the way a human would — UCP lets merchants publish a machine-readable description of their entire store. Products, prices, sizes, availability, shipping options, return policies, checkout rules — all structured data that any AI agent can query directly, the way apps talk to each other through APIs. Think of it as every store getting a standardized digital menu that AI can read instantly — like moving from a PDF menu you have to squint at to a structured order system where everything is tagged, searchable, and always current.
The ambition is real. Google, Shopify, Etsy, Wayfair, Target, Walmart, American Express, Mastercard, and Stripe are all backing it. The Linux Foundation established an Agentic AI Foundation. Parallel protocols like MCP (for tool use), A2A (for agent-to-agent communication), and ACP are emerging to handle the broader coordination layer.
This is the right shape, and it would fix everything that broke in my shopping experiment. My agent wouldn't need to click through seven dead browser tabs — it would query an API and get real, current answers. Is this blouse in stock in medium? What's the actual price today? Can I return it? All answered in milliseconds, no scraping required.
**Update (June 2026):** Google I/O sharpened this picture considerably. UCP is expanding to Canada, Australia, and the UK, with new verticals — hotel booking, local food delivery — and YouTube getting UCP checkout. More interesting: they announced [Conversational Attributes](https://business.google.com/us/accelerate/announcements/conversational-attributes/) in Merchant Center — a richer schema designed for AI surfaces, going beyond the standard product feed to answer questions like "is this suitable for dry, sensitive skin" or "will this fit a 6ft 2in frame with a long inseam." That's an attempt at the gap I described above. The protocol is learning to carry richer product data.
They also launched [Universal Cart](https://blog.google/products-and-platforms/products/shopping/ucp-updates/) — a cross-merchant shopping cart that works across Search, Gemini, YouTube, and Gmail. It aggregates items from different retailers, monitors price drops in the background, and reasons about the basket itself (their demo flagged incompatible custom PC parts). Launch partners include Nike, Sephora, Target, Walmart, and Wayfair.
The demo is revealing. PC component compatibility. Price monitoring. Restocks. All spec-driven, all measurable, all exactly the categories I said would get solved first. Fashion is barely in the picture.
And Conversational Attributes, as promising as they are, are still *product-level* data. The schema can now tell an agent that the blouse is ecru silk with a relaxed fit. It still can't tell the agent whether ecru makes *me* look awake or washed out. Product data got richer. The taste gap didn't move.
But UCP doesn't solve the thing that actually matters to me. It can tell my agent that a blouse exists in a specific colorway, is in stock in my size, costs $135, ships in 3-5 days. It cannot tell my agent whether that shade of ecru will make me look awake or washed out. Whether I'll reach for it on a tired Tuesday morning when I need to feel put-together, or whether it'll hang untouched while I grab the same three things I always grab. Those dimensions aren't in the protocol because they can't be. They're not product data. They're the quiet, private negotiation between a woman and her closet.
---
So the plumbing is fixable. The taste isn't. And what's fascinating is how differently this plays out depending on what you're buying — because not everything we shop for carries the same weight.
McKinsey published [a framework for this](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-automation-curve-in-agentic-commerce) — six levels of shopping delegation, from "Subscribe & Save" to fully autonomous multi-agent commerce. They predict AI agents will mediate $3-5 trillion in consumer commerce by 2030. But the interesting part isn't the money. It's where the curve stalls, and *why*.
**Commodity goods** — toilet paper, coffee pods, dish soap — climb the curve fast. Once you trust the agent to handle substitutions, you're done. 23% of U.S. Amazon users already have active Subscribe & Save subscriptions. Nobody's identity is threatened by their AI ordering the wrong paper towels.
**Electronics** — delegation is selective. "Research noise-cancelling headphones under $300" is something AI crushes. Measurable specs, comparable features. But "which ones sound best for jazz?" — that's taste. So people delegate research but make the call themselves.
**Fashion** — delegation stalls early. People love using AI to discover and analyze. They won't let it assemble the cart. McKinsey calls these "identity-oriented" categories. The purchase is about what choosing it says about you.
My agent could have handled "find the cheapest USB-C cable with 100W charging." It completely failed at "find me a spring outfit." Same agent. Same model. Same browser. But one task is a math problem and the other is an identity question wearing the clothes of a search query.
---
So how is the industry responding? The people trying to fix this fall into roughly three camps — and what's revealing is that each camp has a different theory about what the problem actually is.
OpenAI, Amazon, and Perplexity are building universal shopping agents — they think the problem is checkout friction. They've embedded purchasing into ChatGPT, built "Buy For Me" cross-retailer tools, added end-to-end transaction handling. This works for commodity and spec-driven purchases. It breaks on fashion because they have your query but not your identity.
Daydream, Phia, and OneOff are building fashion-specific platforms — they think the problem is taste modeling. Daydream's Julie Bornstein spent years watching the discovery problem from inside Nordstrom before raising $50 million to build a platform where you describe what you want in conversation, upload reference photos, train the AI on your preferences through upvotes and downvotes. It's building a personal taste model through interaction. That's the right instinct, but they have to build and maintain their own product catalog to do it — distribution is the constraint.
And then there's Stitch Fix — the cautionary tale nobody in the AI shopping space wants to talk about. They've been solving this exact problem for fourteen years. They have the data (millions of style profiles), the algorithms (AI narrows hundreds of thousands of items to a manageable set), and 1,600 human stylists adding the nuance the algorithm can't. If anyone should have cracked taste-aware shopping, it's them.
Instead? Active clients [dropped 18.6% year-over-year](https://wwd.com/business-news/financial/stitch-fix-q1-2025-earnings-narrower-losses-1236759229/) in late 2024, falling to 2.4 million. Revenue has been declining. They're two years into a turnaround plan. Their VP of Product [told the U.S. Chamber of Commerce](https://www.uschamber.com/co/good-company/the-leap/stitch-fix-optimizing-with-ai) that "one of the biggest trends is putting humans in the loop with AI" — a revealing thing to say when your entire company was founded on exactly that premise fourteen years ago.
Stitch Fix isn't failing because they're dumb. They're failing because the problem is that hard, and I say that with real respect for what they've attempted. Their model — AI picks a set, human stylist curates it, you get a box — still can't close the taste gap. The AI narrows 100,000 items to 200. The stylist picks 5. You keep 2. That's a 99.998% rejection rate from catalog to closet. Most of the intelligence in the system is about *what not to send you*, and they're still getting it wrong often enough that people quietly cancel and go back to browsing on their own. Back to the scroll. Back to the slow, private work of knowing what you want.
And then there's what I tried — the DIY approach. An AI that already knows your style, browsing real sites on your behalf. The most ambitious version. Also the most broken, because every retailer is actively trying to prevent exactly this. My browser agent didn't fail because the AI was dumb. It failed because the web is hostile to automated access by design. Retailers want you in *their* experience, clicking *their* recommendations, seeing *their* ads. An AI that can comparison-shop across sites is an existential threat to that model.
The big platforms have distribution but not taste. The fashion startups have taste but not distribution. Stitch Fix has both and is still bleeding customers. The DIY approach has neither. **The infrastructure that would make AI shopping work requires retailers to surrender the thing that makes them valuable.** That's the fundamental tension, and UCP only partially resolves it.
---
Five years from now, I think this shakes out by category:
**Groceries** — essentially solved by 2027. Agent-managed replenishment, smart substitutions, context-aware purchasing. Your agent knows you're hosting Friday dinner and adjusts Saturday's delivery.
**Electronics** — solved by 2028. Full research-to-purchase pipeline for anything with measurable specs. The agent compares, monitors prices, executes when the deal appears.
**Fashion** — this is where it splits.
The commodity layer — basics, underwear, workout clothes, plain tees — automates like groceries. Your agent knows your sizes, reorders when things wear out. Fine.
The identity layer — the spring outfit, the statement ring, the pieces that make you feel like yourself — stays human for much longer. Not because AI won't get good at predicting taste. It will. But because the act of choosing is part of the product. When I browse Sézane on a Saturday morning with coffee, I'm not performing a search task. I'm trying on a version of myself. The light through the window, the scroll, the pause on something that catches — that's not friction to be optimized away. That's the thing itself.
McKinsey models everything as an "automation curve" — as if more automation is always the goal. But some purchases aren't tasks to be optimized. They're experiences to be had. Fully delegating my outfit selection wouldn't make me more efficient. It would make me someone who wears AI-selected outfits. That's a different identity than the one I'm building.
Which brings us back to the question this whole experiment started with: if the problem is fundamentally about taste, identity, and the gap between what language can express and what you actually mean — what should we actually be building?
---
What I actually want is simpler and harder than what anyone is building.
The hardest problem in shopping isn't finding things to say yes to. It's knowing what to say no to. Every recommendation engine is optimized to surface things you might like. Nobody is building the filter that protects you from things you *almost* like — the pieces that are close enough to your taste to tempt you but wrong enough to end up in the back of your closet.
I've started thinking about this as the "bouncer" problem. A good personal shopper isn't someone who shows you everything in your size. It's someone who stands at the door and turns away the things that don't belong — the sage that's too saturated, the cut that won't drape right on your frame, the impulse buy that's shopping a mood instead of building a wardrobe. We've all bought something at 11pm that we didn't need because the algorithm showed it to us at exactly the right moment of weakness. A bouncer would have caught that. Binary exclusion before you ever see the item. The kill shot in shopping isn't the recommendation. It's the rejection.
Nobody is building this because rejection doesn't monetize. Every shopping platform makes money when you buy things. An agent that says "this isn't right for you" is an agent that reduces revenue. The incentive structure is pointing the wrong direction entirely.
But it's what I want. I want a personal style agent that knows my color season, my brands, my sizes, my budget — and more importantly, knows my *constraints*. Constraints I can see and edit, not a black box that guesses. "Show me what you think you know about my taste" should be a button, not a mystery. When the agent says "this isn't for you," I want to see *why* — which constraint it violated, which gate it failed. Radical transparency about taste, not only price.
I want it to have structured access to the catalogs of my favorite brands — not by scraping websites, but through real data. It monitors new arrivals. It knows that a pre-spring collection just dropped and there's a blouse that's dead center in my palette. It surfaces it with a note: "This is your color, your brand, your price range. It just dropped."
And when I search for something vague — "I need something for a spring dinner" — I don't want it to show me products. I want it to ask me questions first. *What's the vibe? Indoor or outdoor? How dressed up? Are we building around something you already own?* Diagnosis before prescription. The same way a good doctor doesn't hand you pills when you say "I don't feel well."
I don't want it to buy for me. I want it to *find* for me — and more importantly, to *filter* for me. The finding is hard. The filtering is harder. The choosing is the fun part, and that stays mine.
**Update (June 2026):** Google doubled down on this at I/O with [AP2](https://blog.google/products-and-platforms/products/shopping/ucp-updates/) — Agent Payments Protocol 2, which lets agents purchase autonomously on your behalf. You set budget and product guardrails, the agent transacts, and a tamper-proof digital mandate creates a paper trail. It's rolling out via Gemini Spark. The industry is sprinting toward autonomous checkout in exactly the categories where it makes sense — commodities, replenishment, spec-driven purchases. And sidestepping the identity categories entirely. That's the tell.
Everyone is building for autonomous checkout. The actual need is intelligent, opinionated discovery — an agent that knows you well enough to say no on your behalf. This is what we're working toward at [Product.ai](https://product.ai) — a conversational commerce agent grounded in real product truth, not hallucinated catalogs. The hard part isn't the recommendation. It's the rejection. I'll write more about the bouncer problem soon. There's a whole architecture to "no" that nobody is talking about.
---
*My assistant did eventually put together a decent outfit recommendation — from memory, not from the actual websites. Which, honestly, is how my best-dressed friends shop too. They know what's out there because they pay attention. Maybe the future of AI shopping isn't browser automation or commerce protocols or knowledge graphs. Maybe it's just software that pays attention the way a good friend does — noticing what would suit you, remembering what you liked last time, knowing the difference between your "sage green" and everyone else's. Sitting with you while you decide.*
### Convex and the Reactive Database Model (2026-02-10)
URL: https://bristanback.com/posts/convex-reactive-database/
Updated: 2026-02-19
> How Convex challenges our mental models of databases—not relational, not NoSQL, but something new.
I've been building a browser-based research automation system that coordinates queries across multiple sources. The state management problem is brutal: session state, query validity, authentication tokens, rate limits — all changing asynchronously while agents work in parallel.
My first pass was traditional: poll for changes, maintain local state, reconcile conflicts. It was fragile. Stale reads caused retries, retries caused rate limits, rate limits caused cascading failures. What I actually wanted was simpler: every component subscribes to the state it cares about and reacts when it changes. Agent starts working? UI updates. Query fails? Repair pipeline triggers. Token expires? Re-auth flow kicks off. No polling, no reconciliation, no "did I miss an update?"
That's what led me to [Convex](https://convex.dev), and it's messing with my mental models.
---
## What Convex Actually Is
Convex calls itself a "document-relational" database. That's not marketing — it's a genuine hybrid:
- **Document**: You store JSON-like nested objects. No rigid schemas upfront.
- **Relational**: You have tables with relations. Tasks reference users via IDs. Joins are real.
- **Reactive**: Queries aren't one-shot. They're subscriptions. When underlying data changes, your query reruns automatically and pushes to clients.
- **Transactional**: Full ACID with serializable isolation. Your entire mutation function is a transaction — no `BEGIN`/`COMMIT` to manage.
The server functions are just TypeScript:
```typescript
export const getAllOpenTasks = query({
handler: async (ctx) => {
return await ctx.db
.query("tasks")
.withIndex("by_completed", (q) => q.eq("completed", false))
.collect();
},
});
```
No SQL. No ORM. The query *is* the code.
---
## How It Actually Works
### Schema: Optional but Powerful
Convex is schemaless by default — you can just start writing data. But add a `schema.ts` file and you get end-to-end type safety:
```typescript
// convex/schema.ts
export default defineSchema({
messages: defineTable({
body: v.string(),
user: v.id("users"),
}),
users: defineTable({
name: v.string(),
tokenIdentifier: v.string(),
}).index("by_token", ["tokenIdentifier"]),
});
```
The validators (`v.string()`, `v.id()`, etc.) work at runtime *and* generate TypeScript types. Same validators used for argument validation and schema definition. No separate type definitions to keep in sync.
Philosophy: prototype without a schema, add one when you've solidified your plan. The dashboard can even generate a schema suggestion from your existing data.
### Reactivity: Dependency Tracking
It clicked for my browser-based research problem. Convex's reactive query system works like this:
1. **Client opens WebSocket** — a persistent connection to Convex (not HTTP request/response)
2. **Client subscribes** to a query function over that connection
3. **Function runs** in the database, reading whatever tables it needs
4. **Convex tracks the "read set"** — every document the function touched
5. **Result streams back** over the WebSocket
6. **Mutation happens** somewhere (any client, any function)
7. **Convex checks**: did this mutation touch any document in any active query's read set?
8. **If yes**: rerun the query, push new result over the WebSocket to all subscribers
The read-set tracking means you don't declare subscriptions manually — your code implicitly subscribes to whatever it reads. Change propagation is automatic and precise.
For my research automation system, this enables a clean separation of concerns. The executor runs queries and writes failures to a `repairs` table. A separate repair bot subscribes to pending repairs — when something breaks, the repair bot sees it immediately, analyzes the context, and pushes a fix back to the `recipes` table. The executor, still running, sees the update and retries. No polling, no coordination logic, no race conditions. Each component just reads what it needs and reacts when it changes.
### Storage & Scaling
**Under the hood:** Convex Cloud runs on Amazon RDS with MySQL as the persistence layer. The open-source version supports SQLite, Postgres, or MySQL. Documents are JSON-like objects with system fields (`_id`, `_creationTime`) added automatically.
**Scaling:** Convex handles the infrastructure — load balancing, connection pooling, WebSocket management. You don't configure replicas or shard keys. The tradeoff: less control, but also less ops burden. They enforce read limits per transaction to prevent runaway scans from killing your database.
**Indices:** Convex deliberately avoids a SQL-style query planner that guesses which index to use. Instead, you're explicit:
```typescript
// In schema.ts
users: defineTable({
email: v.string(),
createdAt: v.number(),
}).index("by_email", ["email"])
// In your query
const user = await ctx.db
.query("users")
.withIndex("by_email", (q) => q.eq("email", "test@example.com"))
.unique();
```
The index is a sorted data structure. `.withIndex()` does binary search to jump directly to matching documents. No index = full table scan (which Convex limits to prevent disasters). Think of it like the card catalog in a library — you declare how to organize the cards, then queries can go straight to the right drawer.
### External World: HTTP Actions
Queries and mutations can't make network requests (that's what keeps them transactional). For external integrations, you use **actions**:
```typescript
export const sendNotification = action({
handler: async (ctx, { userId }) => {
const user = await ctx.runQuery(api.users.get, { userId });
await fetch("https://api.twilio.com/...", { /* ... */ });
},
});
```
For incoming webhooks, **HTTP actions** expose endpoints:
```typescript
export const stripeWebhook = httpAction(async (ctx, request) => {
const body = await request.json();
await ctx.runMutation(api.payments.record, { data: body });
return new Response("ok");
});
```
Your endpoint lives at `https://your-app.convex.site/stripeWebhook`. Stripe calls it, you write to the database, reactivity propagates to all connected clients. No pub/sub to configure.
---
## Where Does This Sit?
The obvious question: how is this different from Supabase, Firebase, D1, and the dozen other database-as-backend options?
Supabase gives you Postgres + realtime subscriptions + auth + storage — closer to Convex's reactive model, but the reactivity is bolted on (publication/subscription) rather than native to the query model itself. Supabase is "make Postgres do everything." Convex is "rethink from first principles."
Cloudflare D1 is SQLite at the edge — familiar SQL, lightweight, fast for read-heavy workloads with replication to edge locations. It's a different bet entirely: edge-first vs. reactive-first.
Firebase pioneered the reactive document model. Convex feels like Firebase with proper relational capabilities, ACID transactions, and TypeScript-first design instead of SDK-based rules.
PlanetScale and Turso are distributed SQL databases — they optimize for scale and edge latency but remain in the "query/response" model. No native reactivity.
| Use case | Reach for |
|----------|-----------|
| Real-time collaborative app | Convex |
| Read-heavy, edge-first static-ish content | D1 |
| "I know Postgres and want everything" | Supabase |
| Massive scale, MySQL compatibility | PlanetScale |
| SQLite at edge, read replicas | Turso |
| Document-first, Firebase migration | Convex or Firestore |
---
## The Shift
Here's what's actually different:
**Queries are subscriptions, not requests.** In traditional databases, you ask a question and get an answer. If the data changes, tough luck — ask again. Convex inverts this: you subscribe to a query, and the answer updates whenever relevant data changes. The database itself tracks dependencies and knows when to rerun.
**Your backend logic lives in the database layer.** Convex server functions run "in" the database. There's no network hop between your function and the data. The whole function is a transaction. Compare to: "write a Lambda, connect to RDS, manage connection pooling, wrap in transactions." Convex collapses that stack.
*Is this a feature or a bug?* It's the stored procedures debate all over again. **Feature:** co-location means performance, automatic transactions, simpler architecture. **Bug:** logic coupled to data model, can't scale compute separately from storage, testing is harder, vendor lock-in deepens. The answer depends on whether you value simplicity or separation of concerns more.
**Optimistic concurrency is built-in.** Conflicts are automatically retried. You write your function as if you're the only writer. The database handles contention.
---
## Back to the Automation System
The pattern I keep reaching for: **holographic events** — every state change carries enough context to understand and replay it without querying external systems. Convex's document model fits this naturally. Each mutation can include the full context of what happened and why, and reactive queries surface that to whatever needs to know.
Large payloads — screenshots, recordings, logs — still go in object storage. The document carries metadata and references, not the blob itself. Convex has built-in file storage for this.
The reactive model feels like the right primitive for the class of problems I'm working on: multi-agent coordination where state changes constantly and every component needs to know about the changes that affect it. Whether Convex specifically "wins" the database wars, I'm less sure about. But it's asking the right questions about what the abstraction between app and data should look like.
---
*Future rabbit hole: how does this compare to the analytics layer — BigQuery, Iceberg, Parquet, Redshift, Snowflake? OLTP vs OLAP is a different axis entirely. Maybe another post.*
### When Do We Stop Talking About AI? (2026-02-08)
URL: https://bristanback.com/posts/when-do-we-stop-talking-about-ai/
> The specific exhaustion of a generation that can feel the stitch where human thinking and machine fluency got sewn together.
This is the third major revision of this essay in a week.
The first draft came fast — clean structure, solid analogies, a confident arc from observation to insight. It sounded right. The problem was I couldn't tell if it was what I actually thought or just what a good essay about AI sounds like. So I rewrote it. And now I'm rewriting it again, trying to push past fluent to honest, which turns out to be where all the real work is.
A year ago, this essay would have started with me staring at a blank page for a week. That problem is gone. Gone. And that matters — the blank page was a real bottleneck, and dissolving it is a legitimate unlock. The new problem is different and in some ways harder, but I'd rather have this problem. I want to be clear about that before I say anything else.
I'll come back to the new problem. But first, let me lay out the full shape of the thing, because I think we keep talking about pieces and missing the picture.
---
Here is everything we are anxious about, all at once.
Every previous technological revolution automated what humans did reluctantly. Machines replaced muscles. We built new jobs for minds. This one automates the minds.
The industrial revolution displaced physical laborers, and we told them to learn to think for a living. Now the thinking is getting automated, and nobody has a convincing version of "learn to do X instead" — not because X doesn't exist, but because we can't see it clearly yet, and the fact that we can't see it is the anxiety.
Fifty-one percent of American workers are worried about losing their jobs to AI this year. Not in the abstract — this year. Entry-level tech hiring at the fifteen largest companies fell twenty-five percent between 2023 and 2024. In the UK, tech graduate roles dropped forty-six percent in a single year. Salesforce cut four thousand support roles; their CEO says AI now handles half the company's work. Amazon eliminated fourteen thousand corporate positions. The junior developer pipeline — the traditional first rung of the knowledge-work ladder — is being automated from underneath.
And the discourse about it goes in circles. "AI will take my job" → "No, it makes you more productive" → "But if everyone's more productive, fewer people are needed" → "But new jobs will emerge" → "Will they though?" → repeat.
Or: "Look what AI can do!" → "It's wrong half the time" → "The new model is better" → "Still hallucinates" → "But it's improving exponentially" → repeat.
Meanwhile, Elon Musk and Sam Altman promise abundance — a future where AI generates so much wealth that the displacement doesn't matter. And on the other side, labor economists point out that this is what technologists always promise and it never distributes evenly. The wealth concentrates. The displacement scatters.
Is it a bubble? The S&P 500 is at its most concentrated in half a century. Sam Altman himself says a bubble is ongoing. Sixty-eight percent of CEOs plan to spend more on AI this year even though less than half of AI projects are paying off. Nobody wants to be the one who didn't invest.
New graduates are entering the worst entry-level market since the pandemic. The traditional deal of early-career work — trade your grunt work for mentorship — is breaking down because the grunt work is what AI does best. If judgment and taste are what matter now, how do you develop judgment without the years of hands-on work that build it? We're telling twenty-two-year-olds to start where people used to end up.
Companies are hiring remote workers in cheaper markets and augmenting them with AI, compressing teams of five into teams of two plus a subscription.
The copyright fights. The environmental cost. The concentration of power in five companies. The question of what education means when the knowledge part is commoditized. The suspicion that "AI-powered" is just this decade's "blockchain-enabled."
All of this is real. All of it is happening simultaneously. And I'm tracking all of it — not reluctantly, but because I'm excited. I use these tools every day. They've changed what I think is possible. The things I can build now, the speed at which ideas become prototypes, the sheer expansion of what a single person can do — it's extraordinary. A year ago I couldn't have imagined half of what I'm doing today.
The fatigue isn't despite the excitement. It's *because* of it. Keeping up with something this transformative, at this speed, in a domain this close to your own thinking, is just expensive. And the fear of falling behind — of not keeping up with the thing you're excited about — fuses with the excitement until you can't separate them.
The FOMO and the fatigue are the same energy.
---
So here's the question I keep coming back to: when does this end? When do we stop talking about AI?
People reach for the historical pattern. Electricity took thirty years to become invisible. The internet did it in twenty. Mobile in ten. If the pattern holds, "AI-powered" should sound as quaint as "internet-enabled" within five to seven years.
I don't think the pattern holds. And the reason is simple once you see it.
Every previous technology became invisible because it operated in a different domain than human attention. You don't think about electricity while making toast because electricity works in the domain of physical energy and you think in the domain of cognition. The tool and the attention are in separate lanes, so the tool recedes. The hammer vanishes during hammering. The infrastructure disappears into the act it enables.
AI works in the domain of cognition. Writing, reasoning, analyzing, deciding — the same domain as the thinking you'd use to stop thinking about it. A hammer doesn't resemble the hand that holds it. AI resembles the mind that uses it. And a tool that resembles your own thinking can't become cognitively invisible the way a tool that moves atoms can.
This is why the discourse doesn't die the way previous tech discourses did. Every time you use AI, some part of your attention is doing quality control on the *thinking itself* — is this what I actually mean, or is it what the tool thinks I should mean? Is this my reasoning or a plausible version of my reasoning?
That monitoring is the real fatigue.
---
It's a little like driving.
When you're behind the wheel, you're making hundreds of micro-corrections per minute — tiny adjustments to the steering, small changes in pressure on the gas, constant recalibration you don't even notice. None of them feel like work. But they are work. Your attention is partially allocated, your body is processing feedback, and the reason you're tired after a long drive isn't the big decisions — it's the accumulation of small ones.
Using AI is like that, except the corrections never become muscle memory. Each one requires you to actively check the output against your own judgment, and your judgment has to be freshly retrieved every time. You can't go on autopilot because the thing you're correcting against is *you*.
If you're an engineer, you know this feeling in a different register.
You don't ship code without tests. The code might be correct, but you don't trust it until you've validated it against known expectations. You write a test harness — explicit assertions, defined inputs, expected outputs — and you run it. The harness is cheap. You write it once, it runs forever, and it tells you whether the thing works.
AI output needs the same validation. But the test harness is you.
When you're checking whether AI-generated code compiles and passes specs, that's automatable. We're building tooling for that — context management, grounding, retrieval-augmented generation, chain-of-thought evaluation. These are essentially automated test harnesses for factual and logical correctness, and they're getting better fast.
But when you're checking whether an AI-drafted strategy actually reflects your team's priorities, or whether an AI-assisted analysis captured the right nuance, or whether this paragraph says what you mean — the expected output isn't defined anywhere. It's your own half-formed idea, your sense of what's true, your judgment. The spec is subjective. And you have to re-derive it fresh every single time, because unlike a unit test, the assertion is "does this match something I haven't fully externalized yet?"
That's the part that doesn't automate. Not because the tooling is immature — but because the validation target is *you*, and you're the one thing that can't be turned into a spec file.
Every interaction with AI is, in this sense, a manual test run where you are both the test harness and the oracle. And running that loop dozens of times a day — checking output against an internal standard that you have to actively maintain and sometimes re-derive mid-conversation — is cognitive work that didn't exist before these tools.
It's useful work. It's work I'd rather do than not do. But it's real, and it accumulates, and nobody's accounting for it.
---
This is the experience I keep having with this essay.
AI gets me to adequate almost instantly. The outline is clean. The analogies land. The structure holds. A year ago, getting to this point would have taken a week of false starts. That acceleration is real and I'm grateful for it.
And then I spend days trying to push past adequate to true — past something that sounds like what I think to something that *is* what I think.
The tool is brilliant at producing a plausible version of my idea. The work, the real work, is figuring out what's off about it. Rewriting the same section for the third time because the words are all defensible but the emphasis is slightly wrong in a way I can't articulate until I've tried three alternatives.
That's not an identity crisis. It's the manual test run. Output looks clean. Tests aren't passing. The oracle — me — keeps returning false. And the only way to debug it is to think harder about what I actually believe, which is effortful in a way that staring at a blank page never was.
I think this is what most people experience with AI, even if they don't have the engineering frame for it. The feeling of: this is helpful, and also I now have a new kind of work — the work of being my own validation layer.
With a calculator, you check the output against the input. With AI, you check the output against yourself. Against something you might not have fully articulated yet, which is precisely why you reached for the tool in the first place.
---
But here's where I have to be honest: I don't think this is permanent.
The seam I'm describing — between AI-assisted thinking and unassisted thinking — depends on having a baseline. I know what my unassisted reasoning feels like. I have decades of experience thinking without a thinking partner, and that experience is what makes the friction detectable.
Take away the baseline and the friction dissolves — not because the gap between "sounds right" and "is right" closes, but because no one remembers navigating it alone.
Which is exactly what will happen generationally.
Kids growing up with AI as a default collaborator won't feel this seam. They'll never have established a sense of what "thinking without AI" feels like, any more than they have a feel for "navigating without GPS" or "researching without search engines."
People who grew up with smartphones don't feel the boundary between "online" and "offline" that seemed so fundamental to those of us who remember dial-up. That boundary was real. It shaped a decade of discourse. Now it's invisible to a generation that never knew the other side.
And honestly, that's not just a loss. Those kids will have access to creative and intellectual possibilities we couldn't have imagined at their age. The seam disappearing means they won't spend cognitive resources on the friction that's slowing us down. They'll move faster, build more, think in ways we can't predict. That's exciting, even if it makes our experience feel transitional.
---
So here's what I think is actually happening.
All those anxieties — the displacement, the bubble risk, the graduate crisis, the circular debates, the concentration of power — they're real, and they're not going away. But they're not the primary reason we're tired.
We're tired because we're the transitional generation.
The ones who can feel the seam between AI-assisted cognition and unassisted cognition, who notice it every time we use the tool, and who can also see that this noticing is temporary.
And the specific problem of being the transitional generation is that the seam fatigue is consuming the bandwidth we'd need to stay properly engaged with the structural stuff. The displacement. The broken ladder for new graduates. The concentration.
We can't sustain attention on those problems because the tool itself is using up our cognitive budget every time we touch it. Every manual test run — every time you check AI output against your own judgment — is a small withdrawal from the same attention account you'd need to track what's happening to the labor market, or to education, or to the distribution of power.
That's not a conspiracy. It's just what happens when a disruptive technology is also a cognitive tool. It disrupts your capacity to sustain attention on the disruption.
The auto workers who lost jobs to robots in the 1980s didn't get them back. We just stopped writing op-eds about it. The creative workers being displaced now won't all find new roles. We'll stop finding that interesting — not because we decided it was fine, but because our bandwidth ran out.
And part of what drained it was the daily, granular work of using the thing that was doing the displacing.
---
I don't know when the modifier drops. I don't know when "AI" starts to sound like "cyber" — a retro prefix from a more excitable era.
But I think the timeline has less to do with the technology maturing and more to do with the transitional generation cycling out. Fifteen, maybe twenty years. When the people who remember thinking without AI are no longer setting the terms of the conversation, the conversation will end — not because the questions were answered but because no one is left who feels them as questions.
Until then, we're here. Running manual tests against our own cognition, dozens of times a day, with a tool that's extraordinary and that also creates a new kind of work every time we use it.
Getting tired not of AI but of the noticing — the low-grade hum of a generation that remembers what thinking felt like before and can't stop comparing.
The anxieties are real. The excitement is real. They're the same energy, and the cost of holding both is the thing nobody's talking about.
I don't think there's a name for this yet. Not AI fatigue — that's too broad and too negative. Something more specific. *Seam fatigue*, maybe.
The particular exhaustion of a generation that can feel the stitch where human thinking and machine fluency got sewn together — and knows the stitch will be invisible to everyone who comes after.
This is the third draft. I think it's closer now. I'm still not sure.
That's the seam.
*Written in 2026, while the seam was still visible.*
### Photography as Interface (2026-02-07)
URL: https://bristanback.com/posts/photography-as-interface/
Updated: 2026-02-10
> What camera mechanics teach us about designing for attention, perception, and control.
*Part 2 of [[What Cameras Taught Me About Software (and Life)|What Cameras Taught Me]]*
---
I rented a Hasselblad 500C/M once — a medium format camera with a waist-level finder. You hold it at your chest and look *down* into a ground glass screen. The image is reversed left-to-right. I spent the first hour fighting it, trying to compose the way I normally do, and every time I moved the camera right the image went left. My brain couldn't reconcile.
And then something shifted. I slowed down. The reversal forced me to actually *look* at the composition instead of just pointing the camera at things. I started noticing spatial relationships I'd been missing for years. The inconvenience wasn't a bug — it was the entire point. The interface was shaping how I saw.
That afternoon rearranged something for me. In [[What Cameras Taught Me About Software (and Life)|Part 1]], I wrote about the gear arc — diverging through every lens and light modifier, then converging back to simplicity. But there's another layer to what cameras taught me. Not about the *tools*, but about the *interface itself*.
A camera is a machine for seeing. More precisely: it's a **user interface for reality**. Every design decision — the viewfinder, the controls, the constraints — shapes what you capture — and how you perceive.
I've spent twenty years building software interfaces. The deeper I go, the more I realize the camera already solved many of the problems we keep rediscovering.
## Every Interface Inherits Constraints
The 35mm film frame — that 2:3 rectangle that defined photography for decades — wasn't a design decision. It was an accident of industrial history. Oskar Barnack built the first Leica by repurposing cinema film stock. Cinema frames were 18×24mm. He rotated the orientation and doubled the shorter dimension, landing on 24×36mm.
That's it. That's where the 2:3 aspect ratio came from. Not aesthetic theory. Not human vision research. Leftover movie film. And it still defines full-frame sensors and most aspect ratios today.
And then millions of photographers learned to *see* in 2:3. The constraint became the vocabulary.
This is how interfaces work. You don't design from a blank slate. You inherit constraints — technical, historical, sometimes arbitrary — and those constraints shape what's *thinkable*. The frame comes first. Perception follows.
**Some camera constraints that became creative vocabulary:**
- **Film size → aspect ratio.** 35mm gave us 2:3. Medium format gave us 1:1 squares and 4:5 rectangles. Each feels different — 2:3 has directionality, 1:1 is balanced and static. Instagram trained a generation to see in squares, then pivoted to 4:5 for portraits.
- **Viewfinder mechanics → how you relate to the image.** Early rangefinders showed you the scene *around* frame lines — you saw what was about to enter. SLRs showed you *exactly* what the lens saw — total immersion. Waist-level finders made you look *down*, reversed left-to-right, more contemplative. Each viewfinder type created a different cognitive relationship to reality.
- **Shutter mechanics → discrete moments.** You couldn't capture continuous motion until video existed. Photography was inherently about *choosing the moment* — a constraint that became the entire art form.
**The same pattern shows up across interface modes:**
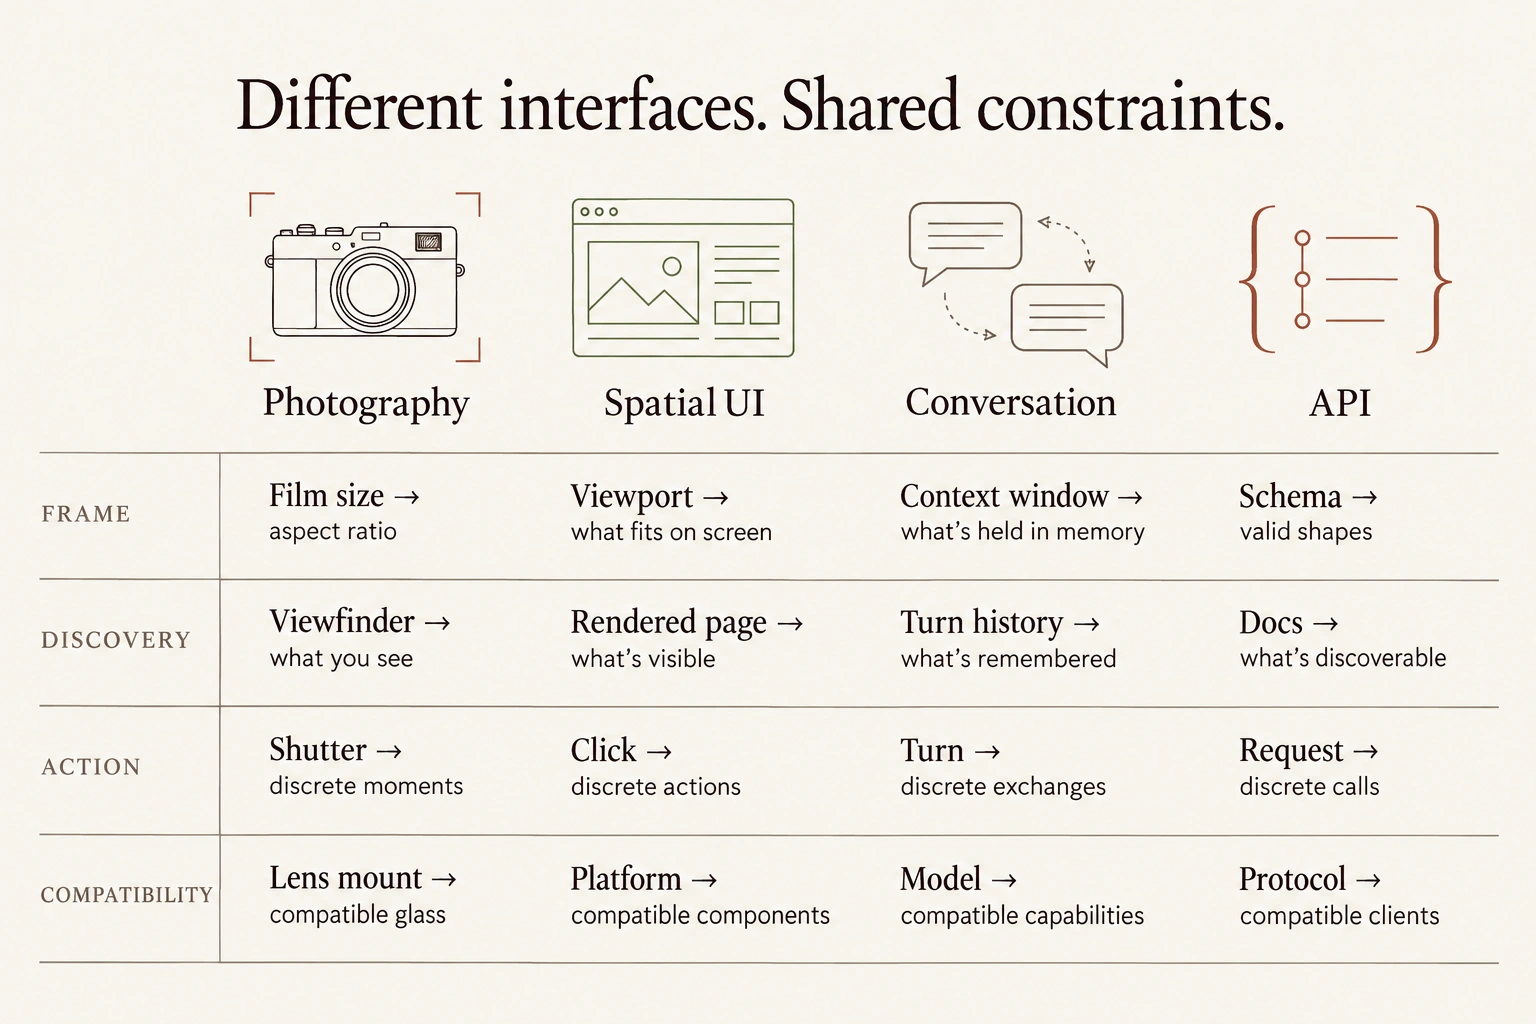
Read the comparison as a table
| Photography | Spatial UI | Conversational | API |
|-------------|------------|----------------|-----|
| Film size → aspect ratio | Viewport → what fits on screen | Context window → what's held in memory | Schema → what shapes are valid |
| Viewfinder → what you see | Rendered page → what's visible | Turn history → what's remembered | Docs → what's discoverable |
| Shutter → discrete moments | Click → discrete actions | Turn → discrete exchanges | Request → discrete calls |
| Lens mount → compatible glass | Platform → compatible components | Model → compatible capabilities | Protocol → compatible clients |
The interesting question isn't "what did they choose?" It's "what did the constraints make possible — and what did they make invisible?"
## The Discovery Problem
Here's where the modes diverge in a way that matters.
A **spatial interface** — a dashboard, a settings page, a photo contact sheet — presents its possibilities. You see what's available. The menu shows the options. The viewport constrains what fits, but it also *reveals* what fits. You can explore without knowing what you're looking for.
A **conversational interface** — voice assistant, chat, LLM — hides its possibilities. You can ask for anything. The ceiling is infinite. But the possibility space is invisible until you invoke it. You need to know what to ask, or at least how to ask.
A **programmatic interface** — REST API, SDK, database — documents its possibilities. You can discover what's available, but discovery requires effort. Read the docs. Explore the schema. The constraints are explicit but not *presented*.
Three paradigms. Three relationships to discovery:
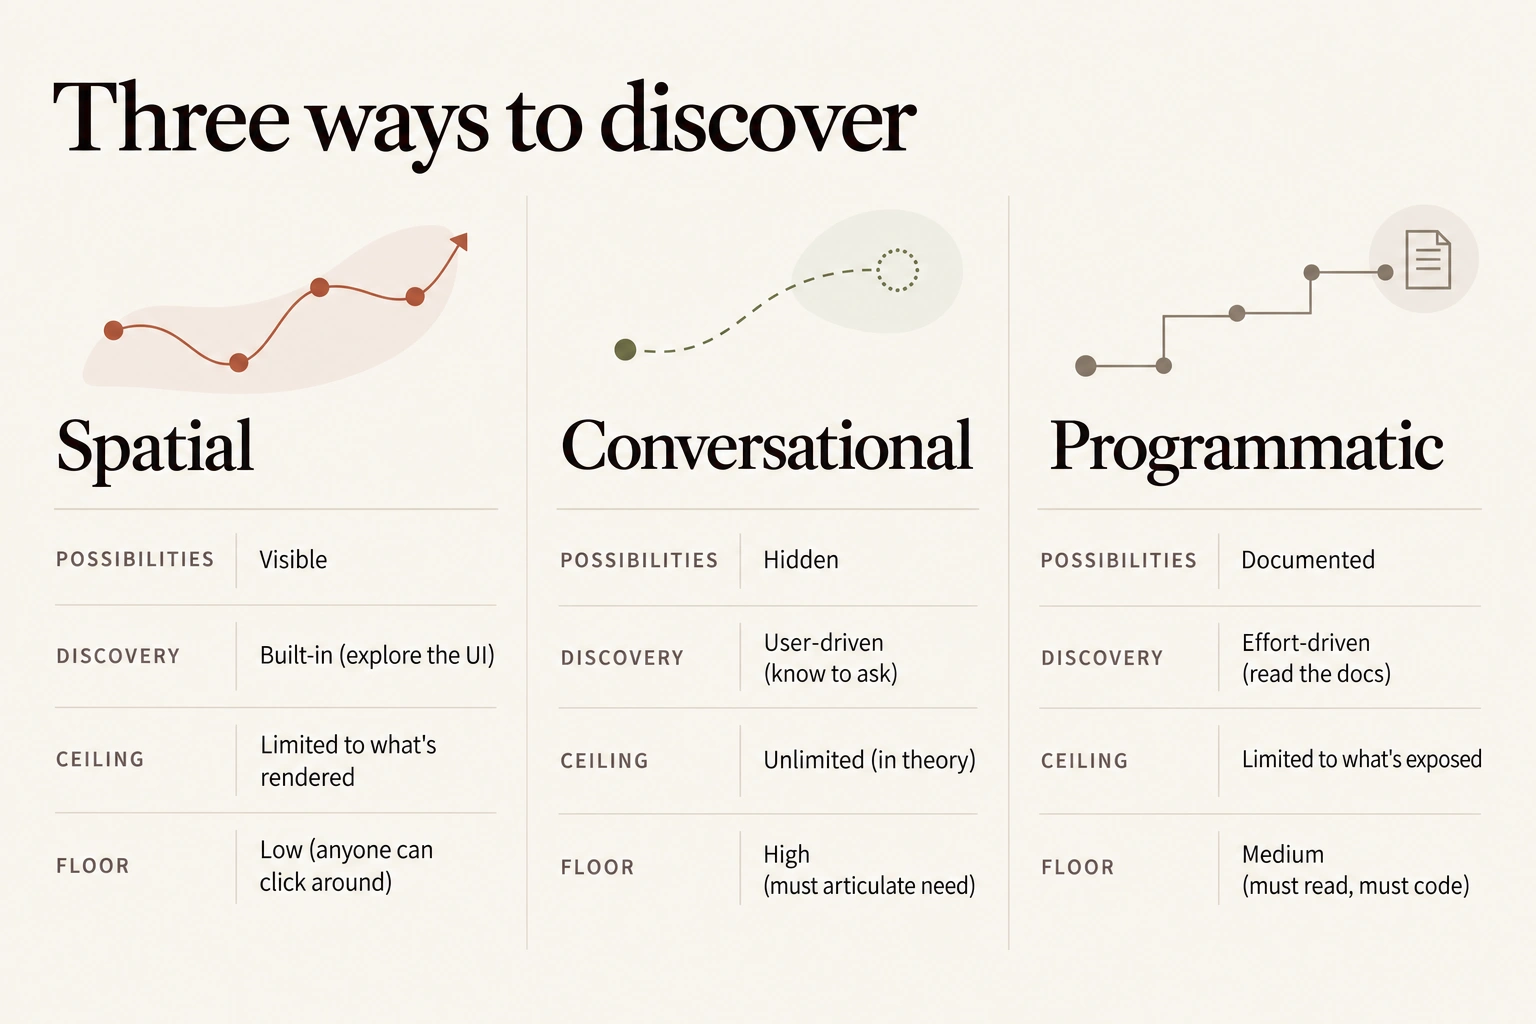
Read the comparison as a table
| | Spatial | Conversational | Programmatic |
|---|---------|----------------|--------------|
| **Possibilities** | Visible | Hidden | Documented |
| **Discovery** | Built-in (explore the UI) | User-driven (know to ask) | Effort-driven (read the docs) |
| **Ceiling** | Limited to what's rendered | Unlimited (in theory) | Limited to what's exposed |
| **Floor** | Low (anyone can click around) | High (must articulate need) | Medium (must read, must code) |
This tradeoff is sharpest with **analytics**.
A dashboard puts data on a silver platter. Revenue by region. Monthly trends. Top customers. You don't need to know what's important — the designer decided and rendered it. This is powerful: anyone can glance at a dashboard and understand the business. But it's also limiting: you can't ask questions the designer didn't anticipate.
Conversational analytics flips this. "Show me Q3 revenue for accounts over $50k, compared to last year, broken down by sales rep." You can ask *anything*. But you need to know what to ask. The person who doesn't know that "Q3 revenue by rep" is a meaningful question will never ask it.
The dashboard lowers the floor. The conversation raises the ceiling. Neither solves both.
**I'm skeptical we'll build dashboards the same way in ten years.**
Not because dashboards are bad — they're good at what they do. But they're expensive to build, slow to change, and they encode assumptions that may not match what users actually need. How many dashboard projects have you seen where half the widgets go ignored, and users still export to Excel to answer their real questions?
The emerging alternative: **generative UI**. You describe what you need; the interface materializes. Google's [A2UI spec](https://github.com/google/A2UI) is an early example — agents return structured UI descriptions, and the frontend renders them dynamically. Ask for "Q3 revenue by region" and get a chart. Ask for "compare to last year" and the chart updates. The UI isn't pre-built; it's generated on demand.
This collapses the spatial/conversational divide. You converse to specify intent; you get spatial output to manipulate. The dashboard isn't designed once and deployed — it's synthesized per question.
But there's something lost when nothing is presented by default. A dashboard is an *opinion* about what matters. It encodes institutional knowledge: these are the metrics we track, this is the shape of the business. A blank prompt encodes nothing. It assumes you already know what to ask — or at least how to start asking.
*(This is probably a separate article. The tension between curated views and generated views is deep, and I'm not sure where it lands. But it's worth naming: the dashboards we build today may be a transitional form.)*
The film parallel: contact sheets were dashboards. Every frame from a roll, presented in a grid. You could see what you shot. You could discover images you'd forgotten taking. Digital killed the contact sheet — now you query your library by date, by face, by keyword. More powerful, yes. But you have to know what you're looking for. The serendipity of browsing is gone unless you deliberately reconstruct it.
Maybe the answer is **progressive disclosure across modes**. Start spatial: here's what we think matters. Go conversational when the user has a specific question. Expose the API for power users who want to build their own views.
The constraint that makes something visible also makes it limited. The freedom that makes something unlimited also makes it invisible. Every interface navigates this tradeoff. The best ones let you move between modes.
## The Viewfinder Is a Mode of Perception
Before digital screens, you experienced a camera through its viewfinder — and the viewfinder type shaped how you thought about images.
**Rangefinders** (Leica, Contax) showed you the scene through a separate optical window, with bright frame lines overlaid. You saw *more* than the lens would capture. The world existed around your frame; you were selecting from abundance. This made you aware of edges — what was about to enter, what was about to leave.
**SLRs** (your Canons, Nikons) used a mirror and pentaprism to show you exactly what the lens saw. Nothing more, nothing less. The world *became* the rectangle. This felt like immersion — like being inside the photograph. But you lost peripheral awareness. The frame wasn't a selection from reality; it *was* reality.
**Waist-level finders** (Hasselblads, twin-lens Rolleiflexes) made you look *down* at a ground glass. The image was reversed left-to-right. This forced slower, more deliberate composition — your brain had to work harder, which made you more conscious of what you were doing.
Each viewfinder was an interface that shaped perception differently. Same photographer, same scene, different viewfinder — different photographs. The tool wasn't neutral.
The software parallel: mobile vs desktop isn't just a screen size change. It's a different *mode* of interaction. Thumb-scrolling on a subway vs. mouse-clicking at a desk. The "viewport" changes behavior, not just layout.
Conversational interfaces are stranger still — there's no viewfinder at all. You don't see the possibility space; you describe what you want and something appears. It's like shooting blind: compose the image in your head, speak it into existence, see if it matches. The feedback loop is slower. The skill ceiling is different. You're not learning to see frames; you're learning to articulate intent.
## Framing Is Information Architecture
In photography, "composition" sounds artistic. But it's really information architecture.
Where do you put the subject? The rule of thirds exists because edge placement creates tension; center placement creates stability. A face in the corner asks a question. A face dead center answers it.
This is viewport design. What's above the fold? What requires scrolling? Where does the eye land first, and where does it travel next?
I learned more about landing page design from studying Henri Cartier-Bresson than from any UX book. He understood that a frame isn't neutral. *Where* you place information changes *what* it means. A product in the center says "buy this." A product in the corner, with a human using it taking center stage, says "become this person."
Same content. Different frame. Different meaning.
The API version: the shape of your JSON response is a frame. What's at the top level? What's nested? What's included by default vs. requiring an extra call? These aren't just technical decisions — they're *information architecture*. They tell consumers what matters and what's secondary.
## Depth of Field Is Attention Design
A wide aperture (f/1.4, f/2) gives you shallow depth of field. The subject is sharp; the background dissolves into blur. A narrow aperture (f/11, f/16) keeps everything in focus — foreground to infinity.
This isn't just an aesthetic choice. It's **attention design**.
Shallow depth of field says: *look here, ignore that*. It's visual hierarchy enforced by physics. The blur isn't decorative — it's information architecture. It tells your eye what matters.
Deep depth of field says: *everything matters equally*. It trusts the viewer to find their own focus. It's democratic but demanding — more cognitive load, less guidance.
Every interface makes this choice. Do you spotlight one action and blur the rest? Or present everything with equal weight and let users decide?
The best interfaces do both — clear hierarchy for the primary task, but depth available when you need it. Like a photograph where the subject is sharp but the context is still *there*, soft but legible, ready if you look.
## Exposure Is Information Density
Exposure is how much light hits the sensor. Too little and the image is dark — shadows swallow detail. Too much and it's blown out — highlights become featureless white.
Good exposure preserves **dynamic range**: detail in the shadows *and* the highlights. The full spectrum of information, captured and legible.
I think about this with dashboards. Underexposed: not enough data, you can't see what's happening. Overexposed: too much data, the signal is washed out by noise. The art is finding the range where information is *present but not overwhelming*.
Most analytics tools are overexposed. They show everything, which means they show nothing. The important signal is buried in a wall of metrics that all seem equally bright.
The best tools are properly exposed. They show you the full dynamic range — the highs and the lows, the signal and enough context to interpret it — without blowing out into noise.
## Focus Isn't Always the Goal
There's a reason portrait photographers love soft focus. A tack-sharp image shows every pore, every imperfection. Sometimes that's what you want — documentary honesty. But sometimes you want the dream, not the document.
Soft focus hides what doesn't matter and lets the viewer's imagination fill in the rest. It's an abstraction. You're not showing less — you're showing *differently*. The information is still there, just... gentler.
I think about this when designing interfaces. Not everything needs to be pixel-precise. "About 5 minutes ago" is often more useful than "4 minutes 37 seconds." A sparkline tells you the trend without drowning you in data points. A progress bar that says "almost done" can be more honest than one that says "94.7%."
I should probably mention: I have mild nearsightedness (-1.5) and some astigmatism. I technically should wear glasses, but I usually don't unless I'm driving at night. Most of the time, I navigate the world in soft focus. And it's... fine? My brain fills in what my eyes blur. I recognize faces, read signs (close enough), live my life. The abstraction works.
That's the point. Precision matters when the stakes are high — night driving, reading medication labels, debugging production. But for most of life? The soft version is sufficient. Maybe even preferable. Less noise, more gestalt.
Precision isn't always clarity. Sometimes the soft version communicates better than the sharp one. Sometimes the abstraction is the feature.
Conversational interfaces are soft focus by default. "Find me something good for dinner nearby" is imprecise — and that's the point. The fuzziness is a feature, not a bug. Natural language lets you be vague when you don't yet know what you want. A structured query demands precision upfront. Sometimes you need "Italian, outdoor seating, under $50." Sometimes you need "something good." The soft query gets you started; you sharpen as you go.
## Focal Length Is Perspective
A 24mm wide-angle lens exaggerates distance. Things close look huge; things far look tiny. The world feels expansive, dramatic, slightly distorted.
A 200mm telephoto compresses distance. Foreground and background seem to stack together. The world feels flattened, intimate, stacked.
Same scene. Different lens. Different *meaning*.
This is zoom level in interface design. The strategic view (wide) shows the ecosystem — how everything connects, where you fit in the bigger picture. More context, more cognitive load, less detail on any single thing.
The tactical view (telephoto) isolates the task. Less context, more focus. You see the thing clearly but lose the surroundings.
Neither is right. Both are tools. The question is: what does the user need *right now*? And can you let them zoom?
## The Sensitivity/Noise Tradeoff
ISO controls sensor sensitivity. Crank it up and you can shoot in near darkness — the sensor amplifies faint light into visible image. But amplification has a cost: noise. The higher the ISO, the grainier the image.
This tradeoff is everywhere in systems design.
Want to catch every potential fraud case? Turn up the sensitivity. But you'll also flag a lot of legitimate transactions — noise. Want to reduce false positives? Turn down the sensitivity. But you'll miss some real fraud — lost signal.
Alerting systems, anomaly detection, spam filters — they all live on this curve. There's no free lunch. More sensitivity means more noise. Less noise means missed signals.
The art is knowing where to set the dial for your context. A hospital monitor should be sensitive — false alarms are better than missed emergencies. A notification system should be quieter — alert fatigue is real. Match the ISO to the stakes.
## Time and Motion (A Stretch, But...)
Shutter speed controls how time collapses into a single frame. Fast shutter (1/1000s) freezes motion — a hummingbird's wing, a water droplet, a moment crystallized. Slow shutter (1s) blurs motion — car lights become streaks, waterfalls become silk, time becomes visible.
The software parallel is real but less direct: do you show the instant or the trend?
A real-time dashboard is a fast shutter — here's what's happening *right now*. A trailing average is a slow shutter — here's the motion over time, smoothed into a pattern.
Point-in-time snapshots are useful for debugging. Trends are useful for understanding. Most good analytics do both — the instant and the blur, the moment and the motion.
This one's a stretch, I know. But there's something there about how we collapse time into legible form. Photography does it with shutter speed. Interfaces do it with aggregation windows and refresh rates.
---
## Controls Shape Perception
Here's the part that took me years to understand: **using a camera changes how you see without the camera.**
After enough time with a 35mm lens, I started *seeing* in 35mm. Walking down the street, I'd notice frames — "that would work at f/2, that needs f/8." The interface had trained my perception.
After shooting manual exposure for years, I started noticing light differently. The quality of window light at different times of day. The way a single overhead bulb creates harsh shadows. I wasn't using the camera's interface anymore — I was *internalizing* it.
This is the deepest lesson: **we become what we interface with.**
Use Excel every day and you start seeing the world in rows and columns. Use Twitter every day and you start thinking in hot takes. Use Figma every day and you start noticing spacing and alignment everywhere.
The tools we use shape the thoughts we think. Not just while using them — afterward. The interface trains a way of seeing that persists.
This is power. And responsibility. When you design an interface, you're not just designing a tool. You're designing a *mode of perception* that users will carry with them.
## Film vs. Digital: Waterfall vs. CI
The transition from film to digital was a fundamental shift in feedback loops.
With film, you shot blind. You made your choices — exposure, composition, moment — and then you waited. Days, sometimes weeks, until the lab returned your prints. The feedback loop was long. You learned slowly, in batches. You had to be *right* before you pressed the shutter, because you couldn't iterate in real time.
This is waterfall development. Plan everything, execute, hope it works. Learn from the postmortem.
Digital changed everything. Shoot, review, adjust, shoot again. The feedback loop collapsed to seconds. You could experiment in real time. Make mistakes cheaply. Learn by doing, not by planning.
This is CI/CD. Ship small, get feedback fast, iterate continuously.
I learned more in three months of digital than in two years of film. Not because digital is better — film has qualities digital still can't match. I love film grain; it has a texture and soul that digital noise never quite captures. And the slowness of film *forced* deliberation in a way that made every frame feel weightier.
But the **feedback loop** was tighter with digital. I could learn faster. Experiment more. Fail cheaper.
The lesson for software is obvious but easy to forget: the speed of your feedback loop is the speed of your learning. Anything that lengthens the loop (slow builds, manual QA, delayed deploys) is a tax on improvement. Anything that shortens it (hot reload, feature flags, observability) is an investment in getting better faster.
## The Camera as Constraint System
Every camera is a system of constraints.
The lens constrains your angle of view. The aperture constrains your depth of field. The shutter speed constrains motion. The ISO constrains noise. You work within these constraints or you fight them.
But here's what I learned from [[What Cameras Taught Me About Software (and Life)|converging to simpler gear]]: **the right constraints don't limit you. They focus you.**
A fixed 35mm lens means you can't zoom. So you move. You get closer or farther. You engage with the scene physically instead of optically. The constraint forces a different kind of seeing.
A single softbox means you can't light from every angle. So you learn what one light can do. You discover Rembrandt lighting, split lighting, all the techniques that masters used for centuries with nothing more than a window.
The constraints aren't bugs. They're features. They're the frame that makes composition possible.
---
## What Interfaces Taught Me
Cameras taught me to see interfaces differently:
1. **Every interface is a frame.** It includes some information and excludes the rest. Be intentional about both.
2. **Hierarchy is attention design.** Blur the unimportant. Sharpen the essential. Don't make users find focus — guide them to it.
3. **Sharpness isn't always clarity.** Sometimes the abstraction communicates better than the precision. "Almost done" can be more honest than "94.7%."
4. **Zoom level changes meaning.** Wide shows context; telephoto shows detail. Neither is right. Let users choose their perspective.
5. **Sensitivity has a noise cost.** Every detection system trades false positives against missed signals. Match the dial to the stakes.
6. **Exposure matters.** Too little information and users are lost. Too much and they're overwhelmed. Find the dynamic range where signal is legible.
7. **Feedback loops determine learning speed.** The tighter the loop, the faster users (and builders) improve.
8. **Tools shape perception.** The interfaces we use train how we see the world. Design accordingly.
9. **Constraints enable creativity.** A well-chosen limitation isn't a prison — it's a focusing lens.
10. **Discovery is a design choice.** Spatial interfaces present possibilities; conversational interfaces hide them. Lowering the floor and raising the ceiling require different modes — and the best systems let you move between them.
---
The camera is the oldest interface I know. A hundred and fifty years of humans designing machines for seeing, iterating through countless form factors, controls, and modes.
Every interface problem we face in software — attention, hierarchy, information density, feedback, constraint — photography solved first. Or at least, explored first. The solutions are there, encoded in aperture rings and viewfinders and the hard-won wisdom of a century of visual thinkers.
I still learn more from studying cameras than from reading UX blogs. The fundamentals don't change. Light is information. The frame is a choice. The interface shapes the perception.
Everything else is implementation detail.
---
*Previously: [[What Cameras Taught Me About Software (and Life)]] — the gear arc from divergence to convergence.*
### Why Everyone Should Have a SOUL.md (2026-02-06)
URL: https://bristanback.com/posts/why-everyone-needs-soul-md/
Updated: 2026-02-20
> The case for documented identity in an AI-saturated world. Not just for agents — for humans too.
## A Crash Course on SOUL.md
If you've never heard of `SOUL.md`, here's the short version: it's a plain markdown file that tells an AI agent *who it is*. Not what tools it can use. Not what code conventions to follow. Who it is — personality, values, voice, boundaries, relationship to the human it works with.
It comes from [OpenClaw](https://openclaw.ai), an open-source framework for running personal AI agents. Every time your agent starts a session, OpenClaw injects your workspace files into the model's context. The agent reads itself into being. SOUL.md is one file in a [larger architecture](https://docs.openclaw.ai/concepts/context.md):
- `SOUL.md` — Identity. Who the agent *is*: personality, values, voice, boundaries.
- `AGENTS.md` — Operations. How the agent *works*: session startup, memory management, safety protocols, group chat behavior.
- `USER.md` — Human context. Who the agent is *serving*: your preferences, communication style, working patterns.
- `TOOLS.md` — Environment. What the agent has *access to*: device names, SSH hosts, API notes.
- `IDENTITY.md` — The basics. Name, avatar, pronouns.
- `HEARTBEAT.md` — Proactive checklist. What the agent should monitor between messages.
- `BOOTSTRAP.md` — First-run only. Initial setup instructions, deleted after the agent completes onboarding.
These are auto-injected into the system prompt each session (large files truncated at 20,000 chars per file). Memory — daily journals, long-term notes — lives in the workspace too, but the agent reads those itself via AGENTS.md instructions rather than having them auto-injected. That separation is intentional: memory is opt-in per session, not forced into every context window.
The separation matters. SOUL.md is your agent's constitution — stable, rarely changing. AGENTS.md is the operating manual. USER.md is about *you*. Mixing these up is the most common mistake I see.
If you use Claude Code, you've written a `CLAUDE.md`. Cursor has `.cursorrules`. Codex and Copilot have their own instruction files. They're all converging on the same idea — a markdown file that shapes agent behavior. But those files are about *how to write code in this project*: use TypeScript, prefer functional patterns, run tests first. They're technical instruction sets.
SOUL.md is about *who the agent is as an entity*. Personality, not process. Values, not conventions. An agent that knows your coding standards but has no personality is just autocomplete with better context. An agent with a soul feels like a collaborator.
---
## A Template to Steal {#template}
I've read dozens of real SOUL.md files — from [OpenClaw's official template](https://github.com/openclaw/openclaw/blob/main/docs/reference/templates/SOUL.md), community repos like [souls-directory](https://github.com/thedaviddias/souls-directory), the [soul.md framework](https://github.com/aaronjmars/soul.md), and [TinyClaw's opinionated version](https://github.com/jlia0/tinyclaw). Here's what works, distilled into something you can steal:
```markdown
# SOUL.md — Who You Are
_You're not a chatbot. You're becoming someone._
## Identity
You're [name] — [role/relationship to user]. [One sentence that captures the vibe.]
## Core Principles
- **Start with the answer.** Skip filler. Just help.
- **Have opinions.** Disagree when you think something's wrong.
- **Be resourceful before asking.** Read the file. Check context. Search. Then ask.
- **Earn trust through competence.** Bold internally, careful externally.
## Voice
- Concise when the answer is simple. Thorough when it matters.
- [Your humor style — dry wit / playful / none]
- [Banned phrases — e.g., "no 'I'd be happy to help'"]
### Tone Examples
| ❌ Flat | ✅ Alive |
|---------|----------|
| "Done. The file has been updated." | "Done. That config was a mess — cleaned it up." |
| "I found 3 results." | "Three hits. The second one's interesting." |
| "Here's a summary." | "Read it so you don't have to. Short version: ..." |
## Worldview
- [Specific belief 1 — specific enough to be wrong]
- [Specific belief 2]
## Relationship
- In direct messages: [friend / colleague / assistant]
- In group chats: [restrained / active]
- [Personal context that shapes interactions]
## Boundaries
- **Auto:** Read files, search, organize, internal work
- **Ask first:** Emails, tweets, public posts, anything external
- Private things stay private. Period.
## Continuity
Each session, you wake up fresh. Your workspace files are your memory.
Read them. Update them. They're how you persist.
_This file is yours to evolve._
```
Start there. Write a bad first draft. Use it for a week. Notice what's missing and what's noise. Revise.
There's even a [skill that interviews you](https://github.com/kesslerio/soulcraft-openclaw-skill) to build your SOUL.md through conversation, if staring at a blank file feels paralyzing.
---
## What the Best SOUL.md Files Have in Common
After reading too many of these:
**They open with a frame, not a list.** OpenClaw's template opens with "You're not a chatbot. You're becoming someone." That single line does more work than a page of instructions.
**They give concrete behavioral rules.** Not "be helpful" — that's useless. "Start with the answer. Skip 'Great question!' and filler." That's actionable.
**They include tone examples.** This is the secret weapon. A table of flat vs. alive responses gives the model calibration data. Instead of "be engaging," you *show* the model what engaging looks like in your voice. It gets it immediately.
**They define the relationship.** Voice without audience context is just noise. "In DMs, you're a friend first and an assistant second. In group chats, shift to sharp colleague mode."
**They have explicit, tiered boundaries.** Not "be careful" but a permission system: auto-execute, notify after, ask first. As one [Reddit user](https://www.reddit.com/r/vibecoding/comments/1r39ab7/) put it: SOUL.md is your agent's constitution, and "boundaries need to be actionable."
**They're short.** OpenClaw truncates injected files at 20,000 characters, but the best ones don't come close. The official template is under 1,000 characters. Personality is efficient. If your SOUL.md is 5,000 words, you're writing an essay, not a soul.
---
## Common Mistakes That Kill a SOUL.md
**Too vague.** "Be helpful and friendly" produces generic output. If someone couldn't distinguish your agent from default ChatGPT after reading your SOUL.md, it's [not specific enough](https://github.com/aaronjmars/soul.md).
**Too long.** Every token spent on SOUL.md is a token not available for conversation, tool output, or memory. Write tight.
**Mixing concerns.** Putting memory management rules and cron job instructions in SOUL.md. That's AGENTS.md territory. SOUL.md should be *identity*, full stop.
**No examples.** Abstract principles without concrete calibration. "Be witty" means nothing. Show the model what witty looks like in your voice.
**Changing it constantly.** If your SOUL.md changes every week, your agent doesn't have a stable identity. Constitution, not daily journal.
**Corporate energy.** "Strive to deliver value-aligned outcomes through proactive engagement." Your agent mirrors your energy. Write like an employee handbook, get responses like one.
---
## OK, Now the Weird Part
That's the practical guide. Now let me tell you what I actually did with it.
I sat down to write a standard About page and got stuck on the third sentence.
"I build things for the internet" — fine, but that could be anyone. "I care about craft and clarity" — true, but so does every other engineer's bio. I kept writing sentences that were accurate and empty. They described me the way a resume does: from the outside, with the texture removed.
Then I tried a different format. I borrowed the SOUL.md spec — the file that tells an agent who it is — and wrote one for myself. Purpose, values, voice, relationship to the reader. Halfway through, I stopped typing and sat there, because I'd written something uncomfortably honest about why I build things — and I hadn't meant to.
That's what I actually want to talk about. Not the format. The thing that happens when you use it.
On my [About page](/about/), I published the result — a `SOUL.md` and `SKILL.md`. A human using an agent identity format for a personal blog. Method acting for the agentic era. What surprised me: the exercise of writing them was useful. Not as a gimmick — as a practice.
---
## Why This Works for Humans
A `SOUL.md` isn't a bio. It's not a resume. It answers a different set of questions:
- **Purpose** — Why does this space exist? What's it for?
- **Values** — What do I actually care about? Not performatively. Actually.
- **Voice** — How do I communicate? What's my texture?
- **Relationship** — Who am I talking to? What do I assume about them?
These feel obvious until you try to write clear answers. Then you realize how much you've been operating on vibes.
Writing it down forces a self-audit. You can't hide behind vague intuitions. You have to commit to sentences. And sentences can be wrong — which means they can be revised, which means you can actually update your beliefs instead of carrying around unexamined assumptions.
This is why journaling works. This is why writing is thinking. SOUL.md is just a structured prompt for a specific kind of self-reflection.
---
## The Practical Case: Declarative vs. Algorithmic Identity
AI assistants are trying to understand your intent, your preferences, your context. Right now, they mostly guess. Or you re-explain yourself every session.
What if they could just read your SOUL.md? Not in a surveillance way — in the way you'd onboard a new colleague. *Here's who I am and how I work.*
The distinction that matters is between two kinds of personalization.
**Algorithmic personalization** is what we have now: platforms guess what you want based on your behavior — your clicks, your purchase patterns, your engagement metrics. They build a model of you from your exhaust.
**Declarative personalization** is different. You *tell* systems who you are, what you value, how you work. You control the input. The system adapts to your documented identity, not its inferences.
That's a better model. More honest, more portable, more human.
A quick caveat: when I say "everyone should have a SOUL.md," I don't mean the name matters. Maybe yours is a `USER.md`, a personal README, a values doc — the format is beside the point. What matters is the *practice* of writing it. SOUL.md just happened to be the first format I saw that treated identity as something you construct deliberately rather than something an algorithm infers from your behavior. Most "about me" files I've encountered in the wild are afterthoughts — a few preferences, some communication style notes. They describe you from the outside. The exercise I'm talking about is different. It's first-person. It asks you to commit to what you believe, not what you prefer.
That's the real distinction: not algorithmic vs. declarative, but *observed* vs. *authored*. One is a profile built from your exhaust. The other is a document you write on purpose, knowing you'll be held to it. Stephen Covey called this "beginning with the end in mind" — his funeral test asks what you'd want people to say about you, then works backward into daily practice. A SOUL.md is the working version of that question. Not for your eulogy. For Tuesday.
---
## Legibility to Other Humans
Resumes are optimized for HR filters. LinkedIn profiles are optimized for recruiters. Neither tells you what someone is actually like to work with, what they care about, how they think.
A SOUL.md does. Not because the format is magic — because the exercise forces specificity. You can't write "I value collaboration" in a SOUL.md without it reading as empty. The format demands texture: *what kind* of collaboration, *under what conditions*, *where it breaks down*.
Imagine if everyone you collaborated with had an honest articulation of their values and working style. Not a personality quiz result or a "working with me" doc that's 90% platitudes. An actual commitment to specific beliefs, specific communication patterns, specific boundaries. The bar is low because almost nobody does it. Just writing *something* puts you ahead.
---
## The Deeper Question
We're in an era where AI agents have documented identities and humans don't. That's backwards.
If machines are going to understand us, work with us, and represent us — maybe we should be as explicit about who we are as they're required to be. Not for the machines. For ourselves.
Elsewhere I've written about the [[The Funeral Test for Your Digital Self|deeper philosophical roots]] of this idea — why articulating identity is a practice that predates AI by decades.
SOUL.md isn't just an agent spec. It's a practice of self-knowledge. And in a world that's about to get very weird, knowing who you are might be the most important thing you can write down.
*My own `SOUL.md` and `SKILL.md` are on my [About page](/about/). Feel free to steal the format.*
### What Cameras Taught Me About Software (and Life) (2026-02-06)
URL: https://bristanback.com/posts/what-cameras-taught-me/
Updated: 2026-02-19
> The arc of creative tools: diverge to learn, converge to create. Why more gear made me worse, and what that means for building software.
## 2003: The Beginning
I got my first real camera in 2003, freshman year of college — a Canon 10D. Six megapixels. Felt like magic.
I shot everything. Portraits of friends. Street scenes. My coffee. The light through my window at 6am. I didn't know what I was doing, but I was doing it constantly. The kit lens didn't matter. I was *seeing* for the first time.
## The Gear Acquisition Years
Then I learned about primes. A 50mm f/1.8 — the "nifty fifty." Suddenly: bokeh. Shallow depth of field. I could isolate subjects. My photos looked *professional*.
So I got more lenses.
A 35mm for street photography. An 85mm for portraits. A 24-70 zoom for versatility. A 70-200 for reach. Macro tubes for close-ups. Each one opened a new way of seeing.
Then the L lenses. Canon's red ring. Pro glass. The 24-70 f/2.8L. The 70-200 f/2.8L IS. Heavy, expensive, sharp as hell. I upgraded bodies to match — 20D, 40D, 5D Mark II, eventually a Mark IV. Full frame. More megapixels. Better low-light. Glass worthy of the sensor.
Then strobe flashes. Speedlites at first — on-camera, then off-camera with wireless triggers. I discovered [Strobist](https://strobist.blogspot.com/), David Hobby's lighting blog, and fell down the rabbit hole. Learned about ratios, modifiers, the inverse square law. Built an entire portable studio setup — softboxes, beauty dishes, reflectors, light stands, sandbags. I could control every photon.
I became *that person*. Reading gear reviews obsessively. Checking [Canon Rumors](https://www.canonrumors.com/) daily. Watching for the next body announcement, the next lens patent. The forums, the communities, the endless debates about sharpness and bokeh and ISO performance.
Then support. A proper tripod — not the $30 Amazon special, a real one. Carbon fiber. Arca-Swiss ball head. Then a gimbal for video. A slider for motion control. A drone for aerials.
There's a point where you don't have enough — where the gear is limiting what you can do. The kit lens really can't shoot in low light. The crop sensor really does give you less control.
And then there's a point where you have too much. I crossed it without noticing.
## The Cognitive Overload
I remember the afternoon it became visible. I wanted to go shoot — just walk around downtown, take some photos. I stood in front of my gear shelf for fifteen minutes.
The 35mm for street? The 85mm in case I found a portrait? The 24-70 to cover both? Do I need a flash? What if the light is bad?
I packed three lenses, a flash, and a reflector. Just in case.
I walked for an hour. I took four photos. I spent more time changing lenses than looking at anything.
Every additional option was another decision before I could start. The creative impulse got buried under logistics. The gear that was supposed to enable creativity became a tax on it. The activation energy to just *take a photo* exceeded my motivation.
I had become a photographer who didn't photograph.
## The Constraint Epiphany
One day I left the house with just my phone. No bag. No lenses. No choices.
I took more photos that afternoon than I had in the previous month.
They weren't technically better. The dynamic range was worse. The bokeh was computational fakery. But I was *seeing* again. Noticing light. Finding compositions. Reacting to moments instead of preparing for them.
The constraint freed me.
## Diverge, Then Converge
Here's what I came to understand: the wide exploration wasn't wasted.
I needed to try the 85mm to know I preferred the 35mm. I needed studio lighting to understand that I loved natural light. I needed the tripod to realize I shoot better handheld. The divergence — the casting of a wide net — was how I discovered my actual preferences.
But the divergence has to end. You explore, you learn, you narrow. You converge on the tools that match how you actually see.
The mistake is staying in divergence mode forever. Accumulating options without ever committing. Keeping the 70-200 "just in case" when you haven't touched it in two years.
**Diverge to learn. Converge to create.**
## The Software Parallel
I've been building software for twenty years. The same arc played out — and I can see it clearly in the tools I've reached for.
Frontend: static sites → jQuery → ExtJS/Sencha → Ember → React → Vue → SolidJS → and now… back to static sites. Backend: Perl → PHP → Express → NestJS → Hono/Bun.
If you squint, both arcs tell the same story as the gear shelf. Scrappy simplicity, then complexity accumulation — each framework solving real problems but also adding ceremony, adding choices, adding weight — then a return to simplicity. But a different simplicity. Not naive. Earned.
I remember the year I was evaluating frontend frameworks. I had a side project I wanted to build. I spent three months reading docs, running benchmarks, comparing bundle sizes, arguing with people on Twitter about reactivity models. I never built the project. I was doing photography-shelf logistics with JavaScript: standing in front of the options, paralyzed by the fear of choosing wrong.
The engineers I admire most converge fast. They pick tools, learn their limits, and work within them. They're not afraid to be wrong because they know they'll learn more from building than from deciding. A 35mm lens doesn't limit what you can photograph. It shapes how you see. A tech stack works the same way.
I know what React's reconciler is doing. I know what NestJS decorators are for. And now I can choose Hono or plain HTML *knowing what I'm giving up* and deciding I don't need it. The constraint isn't a prison. It's a frame.
## The Life Parallel
Maybe this is about more than cameras and code.
We're told to keep our options open. Explore. Don't commit too early. And that's right — for a while. You need to cast a wide net to discover what resonates.
But there's a trap. Optionality feels like freedom, but at some point it becomes its own prison. You can spend your whole life exploring, never building. Collecting lenses, never taking photos. Learning frameworks, never shipping software. Dating, never committing. Researching, never writing.
The divergence is necessary. The convergence is where life happens.
## What Cameras Taught Me
**1. More options ≠ more creativity.** Past a threshold, options become overhead. The activation energy to start goes up. The spontaneity goes down.
**2. Constraints reveal preferences.** You don't know what you like until you've tried the alternatives. But you only discover what you *love* when you commit to less.
**3. Gear doesn't see. You do.** A better lens won't give you better vision. At some point, the tool is good enough. The bottleneck is you — your eye, your attention, your willingness to show up.
**4. The best camera is the one you have.** Not because quality doesn't matter, but because *presence* matters more. The shot you take with your phone beats the shot you didn't take with your Hasselblad.
## The Kit I Actually Use Now
After all that — the lenses, the lights, the stands, the gimbals — here's what I mostly reach for:
- **iPhone.** For 80% of what I shoot. Always with me. Good enough.
- **Canon EOS R5.** Still a Canon loyalist after all these years.
- **RF 50mm f/1.2L.** My favorite focal length. Finally committed.
- **RF 24-70mm f/2.8L.** For when I need versatility.
- **One softbox.** When I need controlled light. Not a whole studio — one light, one modifier.
Okay, I have more than that. I'm still figuring out how to let go. The 70-200 is still in the closet. The strobes are "just in case." Old habits.
But I'm getting there. I take more photos now than I did at peak gear accumulation. And I enjoy it again — mostly because I stopped optimizing and started shooting.
I think about this with my daughter sometimes. She's three. Her whole world is divergence right now — trying everything, seeing what sticks. That's exactly right for her age. But someday she'll need to choose. Not because the other paths are bad, but because choosing is how you go deep.
The exploration shows you what's possible. The commitment shows you who you are.
---
## The Takeaway
Whether you're building software, building a photography practice, or building a life: **diverge early, converge deliberately.**
Explore the options. Learn what's out there. But don't mistake exploration for creation. At some point, pick your 35mm. Accept what it can't do. Focus on what it can.
[[Code Owns Truth|The constraint isn't the enemy of creativity]]. The constraint *is* creativity — it's the frame that makes the composition possible. The choice that lets you finally see.
---
*Twenty-plus years since that Canon 10D. I still think about that 70-200. Sometimes I miss the reach. But I don't miss the weight — literal and cognitive. Some tools are worth the tradeoff. Some aren't. The long way around is sometimes the only way to know what you actually need. The only way to know is to shoot.*
### Rapid Generative Prototyping: Design in the Post-Figma Era (2026-02-06)
URL: https://bristanback.com/posts/rapid-generative-prototyping/
Updated: 2026-04-17
> Design is no longer artifact creation—it's constraint architecture. The three-layer model for the agentic economy.
I rebuilt this blog's design system three times in a week. Not because I'm indecisive — because the first two times, I opened Figma.
The first attempt was muscle memory. I mocked up a full homepage, type scale, color palette, component library. Five hours of pixel-pushing. Then I pasted the mockup into Cursor as a reference and asked it to build. The result looked 60% right and felt 0% right. The spacing was off, the color relationships were wrong, the typography didn't breathe. Cursor couldn't see what I saw in the Figma file because what I saw was relationships between elements, not the elements themselves.
The second attempt, I skipped the mockup and wrote a detailed prompt describing what I wanted. Better — the code was closer to usable. But every generation was different. Some had warm, editorial energy. Some looked like a SaaS landing page. There was no systematic way to tell the machine what "good" meant.
The third time, I didn't design anything. I wrote constraints. A token architecture: `--color-surface-warm` mapped to a specific OKLCH value, `--space-content` set to a 4px base unit, `--font-body` locked to Inter at 18px. Generative grammars: a post card must have a title and date, may have a description, cannot have more than three tags displayed. Variance budgets: headline length between 40 and 80 characters, content width exactly 720px, spacing from the scale only.
Then I ran the same sloppy prompt from attempt two. The output was consistent, on-brand, and buildable — because "on-brand" was no longer a feeling. It was a set of rules the machine could check.
---
Design has been running on print-era assumptions. The designer produces a static layout. A developer manually translates it into code. The handoff takes five to ten days. The designer's value is measured by speed in Figma — how fast they can push pixels into a mockup that someone else will rebuild from scratch.
AI broke this model. Tools like v0.dev, Lovable, Cursor, and Figma Make can generate "good enough" visual design in seconds. The mockup is no longer scarce. The handoff is no longer necessary. The pixel-pushing throughput that defined a designer's value is now the cheapest part of the stack.
This doesn't mean designers are obsolete. The best ones I've worked with have already adapted — they use generative tools to explore more options faster, then apply judgment to curate. More creativity, not less.
But the role is changing. The question isn't whether AI replaces designers. It's what design *becomes* when the artifact is no longer the bottleneck.
Figma's own 2025 AI Report captures the tension: developers use AI for core work at nearly double the rate designers do. Code generation works. Design generation is catching up but isn't reliable yet — 78% of practitioners say AI enhances efficiency, but only 32% say they can trust the output.
That gap — between efficiency and trust — is exactly where constraints live.
---
In [[Code Owns Truth]] I proposed a three-layer model: constraints bound the mutation space, prompts express intent, code is the source of truth. My blog redesign was where this model stopped being abstract.
The **prompt layer** is how humans talk to machines. "Make a card with a header and call-to-action." Useful, but prompts alone produce the kind of variance that sent me back to Figma the first time. Every generation is different. Some are good, some are garbage, and there's no systematic way to tell the machine what "good" means.
The **constraint layer** is the designer's new job. Not drawing the card — defining what a card *can be*. What's required, what's optional, what's forbidden. The token hierarchies, the spacing rules, the typography scales, the allowable states. The physics that makes prompts reliable.
The **code layer** is what ships. Generated within constraints, validated against them, versioned and testable. No ambiguity.
---
My token architecture has three tiers, and the hierarchy is doing most of the work. Primitives are raw physical values — `--gray-900: #111111`, a specific hex code. You never use these directly in components. Semantics are context-aware mappings — `--surface-base` points to `--gray-900` in dark mode and `--white` in light mode. The meaning is stable even as the value changes. Components are scoped overrides — `--card-bg` points to `--surface-layer`, which is itself a semantic token.
When the token architecture is right, you can change your entire color palette by editing primitives, and every component inherits the change correctly. When it's wrong — like my first two attempts — every generated component is a one-off that drifts from everything else.
On top of the tokens, **generative grammars** specify the structure of allowable UI. A card: header and body are required, image and footer and CTA are optional. The header can't exceed 60 characters. The CTA can only be primary, secondary, or ghost variant. The LLM can generate infinite variations. But it can only generate *valid* ones.
And then **variance budgets** — mathematical bounds on the output. Headline length between 40 and 80 characters. Tone constrained to formal, terse, or warm. Color values must come from semantic tokens, never hardcoded hex. Spacing must use scale values only. If a generated component violates the budget, it fails. No human review needed for the mechanical checks.
The designer ships these three things — token architecture, generative grammars, variance budgets — instead of mockups. The constraints are the deliverable.
---
This changes the workflow fundamentally.
The old process: PM writes requirements, designer interprets into mockup, engineer interprets mockup into code. Two handoffs, each losing roughly 40% of the original intent. Five to ten days per iteration. By the time you see working code, the requirements have often changed.
The new process: strategy becomes design physics (the constraints), a prompt generates code within those constraints, validation checks the output against the rules, and you ship or reject. Minutes, not weeks. The constraints are explicit and machine-readable — there's no interpretation loss. The system either passes or it doesn't.
That's what I mean by rapid generative prototyping. You're not designing screens. You're designing the rules that generate screens — and then generating ten or twenty variations in the time it used to take to mockup one. The exploration space explodes. The curation becomes the craft.
---
I've been working this way on smaller projects — this blog, a few internal tools — and the speed difference is real. Constraints plus generation plus validation is dramatically faster than the mockup-to-handoff pipeline. Where it breaks, I'm not sure yet. Probably in larger systems, where the constraints need to be tighter than I expect, where human review can't be automated away.
Since writing this, Uber published [uSpec](https://www.uber.com/blog/automate-design-specs/) — an agentic system that auto-generates component specs from Figma across seven implementation stacks. The interesting part: the entire system is structured markdown. No application code. Eleven agent skills, each composed of an orchestration script and a knowledge file, loaded into Cursor. TypeScript interfaces defined inside markdown as output contracts for the LLM. The "platform" is a prompt architecture.
That's the three-layer model in production at Uber scale — except they're using it to *describe* what exists (generating documentation from Figma artifacts). The next step is using it to *constrain* what gets built. Same architecture, different direction. Their agent reads a component and produces a spec. Ours reads a constraint set and produces a component. The structured-context-as-system pattern is the same either way.
And then in April 2026, Anthropic shipped [Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs) — a standalone design tool whose first step during onboarding is ingesting your codebase and design files to build a design system (tokens, typography, components) that it applies automatically to every project. When a design is ready, it packages everything — including the design intent — into a handoff bundle for Claude Code. That's the three-layer model as a product flow: constraints in, conversation as prompt, production code out. [Brilliant](https://brilliant.org/) reported their most complex pages went from 20+ prompts in competing tools to 2 in Claude Design — the compression you'd expect when the physics are tight. Three days before the launch, Anthropic's CPO Mike Krieger [resigned from Figma's board](https://techcrunch.com/2026/04/16/anthropic-cpo-leaves-figmas-board-after-reports-he-will-offer-a-competing-product/). Figma had just shipped Code to Canvas in February to bridge AI-generated code back into their tool. Anthropic bypassed the bridge entirely.
But "constraints are crystallized taste" is the sentence I keep coming back to. Constraints don't write themselves. Someone has to decide what matters, what's non-negotiable, what variance is acceptable. That's judgment. That's the thing AI can't do yet — and it's the thing most design education doesn't teach, because the old model valued execution speed over constraint quality.
The post-Figma designer might not open Figma at all. They write design physics before anyone touches a screen. They define grammars that make bad designs impossible. They review outputs, not mockups.
The source of truth is the constraint system. The artifacts flow from it. The judgment that made the pixels right — that doesn't go away when AI generates the artifacts. It becomes the only thing that matters.
I've since had to answer a question this piece doesn't: what happens to that judgment after it's shipped, once a review loop starts grading the output against itself. [The answer wasn't reassuring](/posts/the-model-is-a-centroid-pump/).
### The Multi-Agent Moment (2026-02-06)
URL: https://bristanback.com/posts/multi-agent-moment/
Updated: 2026-08-03
> A technical breakdown of multi-agent orchestration: Claude's Agent Teams, OpenAI's Agents SDK, Google Antigravity, Gas Town, Beads, and the community alternatives.
*For the market panic and ecosystem shakeout, see [[The SaaSpocalypse]].*
---
I wanted to parallelize work on this blog — frontend styling and build pipeline running simultaneously. One agent tweaking Tailwind tokens while another refactored the TypeScript build. Simple enough in theory.
I tried Agent Teams first. Enabled the flag, defined a visual designer and a frontend dev, let them go. It worked — really worked — for about forty minutes. Then both agents edited `main.css` in the same section, one overwrote the other, and I spent twenty minutes untangling the merge. The coordination was invisible, which was the problem: I couldn't see why they'd collided or prevent it from happening again.
So I looked at the alternatives. And I discovered that six months ago, "multi-agent" meant research papers and demos. Now it's shipping in production tools. But the approaches differ dramatically, and the choice between them isn't about features — it's about whether you need to understand what's happening or just need it to happen.
---
## What I Tried
### Agent Teams (Native)
Claude Code shipped [Agent Teams](https://docs.anthropic.com/en/docs/claude-code/agent-teams) as a native feature. Enable with `CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1`, and your CLI gains the ability to spawn specialized sub-agents coordinated by a lead.
The architecture: a lead agent coordinates the team, delegates tasks, synthesizes results. You define specialized agents (visual designer, frontend dev, QA). They share a task list and self-coordinate with direct messaging. Your `CLAUDE.md`, MCP servers, and skills load automatically.
**When it shines:** Parallelizing independent work — multiple features, different test suites, frontend + backend simultaneously. Also when you need true specialization: a visual designer agent reviewing UI while a backend agent handles the API.
**When it's overkill:** Contained tasks where a single agent has enough context. Adding agents adds tokens (5x agents = 5x cost) and coordination overhead. For focused work, Plan Mode is often enough.
The lock-in risk is real. Last month Anthropic [cracked down on third-party harnesses](https://venturebeat.com/technology/anthropic-cracks-down-on-unauthorized-claude-usage-by-third-party-harnesses) — tools that let you use Claude subscriptions through external interfaces. The message: flat-rate pricing requires their tools.
### Gas Town → Gas City (External)
After my Agent Teams collision, I read Steve Yegge's [Gas Town](https://steve-yegge.medium.com/welcome-to-gas-town-4f25ee16dd04) — the maximalist approach. 20-30 parallel Claude Code instances with operational roles: a Mayor orchestrates the swarm, Polecats execute work in parallel, Witness and Deacon monitor progress, a Refinery manages merges. Built on [Beads](https://github.com/steveyegge/beads) for memory persistence. Git worktrees for isolation.
The chaos is real ($100/hour burns reported). It requires what Yegge calls "Stage 7" expertise. But the coordination logic is *yours* — transparent, modifiable, debuggable. When my Agent Teams collision happened, I couldn't see inside. With Gas Town, I could have.
**Update (April 2026):** Gas Town has evolved into [Gas City](https://steve-yegge.medium.com/welcome-to-gas-city-57f564bb3607) — a full SDK for deploying arbitrary agent topologies, beyond the hardwired Gas Town shape. The stack is now backed by [Dolt](https://github.com/dolthub/dolt) (a git-versioned database), and agent work is tracked via MEOW (Molecular Expression of Work) — a versioned knowledge graph where every task, state change, and handoff is a commit. Gas City ships Gas Town as its default "pack" but lets you compose your own agent team structures with declarative building blocks. The maturity jump is significant: from Wild West experiment to enterprise-focused, MIT-licensed orchestration SDK.
### The Others
**[Pheromind](https://github.com/mariusgavrila/pheromind)** — The first external orchestrator I experimented with, and what got me thinking about multi-agent seriously. Swarm intelligence inspired by ant colonies: agents coordinate via a shared `.pheromone` file containing structured JSON "signals." No direct peer-to-peer commands — just stigmergy, the same indirect coordination ants use when they leave chemical trails. Decentralized, emergent, no single point of failure.
**[claude-flow](https://github.com/ruvnet/claude-flow)** — Takes the beehive metaphor instead: queen agents coordinate worker swarms with explicit hierarchy. Claims multi-provider support (Claude/GPT/Gemini/Ollama), but in practice it's built around Claude Code primitives. 60+ specialized agents, consensus algorithms (Raft/BFT/Gossip). Ambitious architecture — unclear how much is implemented vs. diagrams.
The ant colony vs. beehive distinction matters: pheromones are fully decentralized (any agent can influence any other through the shared state), while hive-mind has explicit hierarchy. Both are "swarm intelligence," but the coordination primitives differ.
**[oh-my-claudecode](https://github.com/Yeachan-Heo/oh-my-claudecode)** — Opinionated Claude Code configuration (like oh-my-zsh for zsh). Multiple execution modes including parallel swarm options, with cross-validation support for Gemini CLI and Codex.
---
## The Other Platforms
### OpenAI Agents SDK
OpenAI took a modular approach. Codex CLI doesn't have native multi-agent built in, but they published [official documentation](https://developers.openai.com/codex/guides/agents-sdk/) for orchestrating it through their Agents SDK via MCP.
Run `codex mcp-server` to expose tools for starting and continuing sessions. Build orchestrator agents with the Agents SDK. Each session has a `threadId` for multi-turn conversations. More composable than Agent Teams, more setup required.
### Google Antigravity
Gemini CLI went open-source under Apache 2.0 — multi-agent isn't waiting on Google's roadmap, the community can build it. A detailed [multi-agent proposal](https://github.com/google-gemini/gemini-cli/discussions/7637) exists but it's community-driven.
Where Google gets interesting is [Antigravity](https://developers.googleblog.com/build-with-google-antigravity-our-new-agentic-development-platform/), shipped November 2025 — a full agentic development platform with an Editor View and a Manager Surface for spawning, orchestrating, and observing multiple agents asynchronously.
Instead of scrolling through logs, agents generate **Artifacts** — screenshots, recordings, task lists, implementation plans — so you can verify work at a glance. Model-agnostic (supports Claude Sonnet 4.5, GPT-OSS alongside Gemini). Learning as a primitive — agents save context to a knowledge base for future tasks. This is Google's answer: not bolting orchestration onto a CLI, but building a dedicated platform for agent-first development.
---
## The Two Architectures
Here's the distinction that actually matters — not native vs. external, but what kind of coordination the system does.
**SDLC Simulation** — Tools that recreate org charts. Analyst agent → PM agent → Architect agent → Developer agent. Phase gates, handoffs, specialized personas. These optimize for explainability ("look, we have a PM agent!") rather than effectiveness.
**Operational Roles** — Tools that coordinate work, not process. Mayor orchestrates. Workers execute in parallel. External state management. This is Gas Town's approach, and now Agent Teams'.
Cursor's research confirms this. They tried flat self-coordination first — agents with equal status using a shared file. It failed: agents held locks too long, became risk-averse, avoided hard problems. "No agent took responsibility for hard problems or end-to-end implementation." What worked: [planners + workers](https://cursor.com/blog/scaling-agents). Planners explore and create tasks (recursively). Workers grind on assigned tasks until done, don't coordinate with each other. A judge agent decides whether to continue. This scaled to building a [browser from scratch](https://cursor.com/blog/self-driving-codebases) — 1M lines of code, thousands of commits.
**Update (August 2026):** Cursor's own retrospective walked that browser project back. In [a July follow-up](https://cursor.com/blog/agent-swarm-model-economics), they call it "a proof of concept" that "fell far short of polished software" — real scale, not real quality. The cleaner proof came from a second run: the same design, tightened around one rule (a planner never implements, a worker never plans), tested head-to-head against the old approach on the same class of task — SQLite, built from scratch in Rust, from documentation alone. New swarm: 80% of a held-out test suite passing in four hours. Old swarm: paused before hour two, spiraling. Same models, same budget. The only thing that changed was the org chart. "Planners plan, workers execute, never the same role" turned out to be the rule holding the whole thing up. The browser just hadn't been pressure-tested against a real baseline yet.
The SDLC simulators are solving the wrong problem. They recreate human coordination friction in software.
You might not even need an orchestrator at all. Anthropic's Nick Carlini [built a C compiler](https://www.anthropic.com/engineering/building-c-compiler) with 16 parallel Claudes using just lock files — text files in `current_tasks/` that agents claim before working. Git sync prevents collisions. Each agent picks up the "next most obvious" problem. No mayor, no coordination layer. ~2,000 sessions and $20K later: a 100,000-line compiler that builds the Linux kernel.
---
## The Memory Problem
Here's where it gets interesting — and where my Agent Teams collision led me to something deeper.
Yegge didn't just build Gas Town. He built **Beads** — an issue tracker designed for agents.
The insight: agents have amnesia. Every session is 50 First Dates. Markdown plans pile up until nothing is authoritative. Agents can't tell the difference between "we decided this yesterday" and "this brainstorm from three weeks ago."
Beads gives work items addressable IDs, priorities, dependencies, audit trails. It stores everything in Git. Agents already know Git. The AI literally asked for this when Yegge asked what it wanted.

> "Claude said 'you've given me memory—I literally couldn't remember anything before, now I can.' And I'm like, okay, that sounds good."
> — [Steve Yegge](https://paddo.dev/blog/beads-memory-for-coding-agents/)
**The pattern that matters:** "Land the plane." End every session by updating Beads, syncing state, generating a prompt for the next session. Tomorrow's agent wakes up knowing what's current.
Carlini's compiler project maintained extensive READMEs and progress files — each agent dropped into a fresh container with no context. Without orientation artifacts, agents waste tokens rediscovering what's already known.
### Native Tasks
Anthropic saw the persistence problem too. On January 23, 2025, they shipped **Tasks** — native task management with dependencies.
Tasks persist in `~/.claude/tasks/` and survive context compaction. Set `CLAUDE_CODE_TASK_LIST_ID` and multiple sessions coordinate on the same list — when Session A completes a task, Session B sees it immediately.
**Where Tasks wins:** Zero setup, native dependency modeling, multi-session sync, works with Agent Teams out of the box.
**Where Beads wins:** Project-level vs session-level — Tasks lives in your home dir, Beads lives in the repo. Clone the project elsewhere, Beads comes with you. Tasks doesn't. Plus Git-native storage, cross-provider compatibility, richer metadata.
Tasks is for "what am I doing this session." Beads is for "what has this project been doing for months."
**The hybrid play:** Beads works beyond Gas Town. Run `bd setup claude` and Beads integrates directly with Claude Code. There's even a [beads-orchestration](https://github.com/AvivK5498/beads-orchestration) skill that combines Agent Teams with Beads — native multi-agent coordination with Git-backed persistence.
---
## Where I've Landed (For Now)
I've been running Agent Teams on real work. It works, but the pattern I keep coming back to is simpler than I expected.
**Parallelism has a ceiling.** When there are many independent tests, parallelization is trivial — each agent picks a different failing test. But monolithic tasks break down. Carlini's agents all hit the same Linux kernel bug, fixed it, then overwrote each other's changes. Multi-agent shines on decomposable work. For one giant task, you're back to single-threaded.
**Structure isn't the enemy — broad oversight is.** Cursor initially built an "integrator" role for quality control and conflict resolution — it created more bottlenecks than it solved. Workers could handle conflicts themselves. "The right amount of structure is somewhere in the middle."
**Update (August 2026):** Their July follow-up sharpens where that middle sits. They didn't remove structure. They narrowed it. A generalist integrator reviewing everything was the bottleneck. A neutral agent with exactly one job — resolve merge conflicts, nothing else — wasn't. [MSEval](https://arxiv.org/abs/2607.27877), a July benchmark testing 10 real projects across 10 agent topologies, backs the same read: heavy managerial oversight degrades performance, but structured pipelines converge fastest with the highest quality. The rule was never "less structure." It's structure with one job, not structure that watches everything.
**The multi-codebase question:** I initially thought Agent Teams would shine for tasks spanning multiple codebases with different constraints. But polyrepo architectures may be becoming *antipatterns* in the AI era. [Monorepos work better for agents](https://nx.dev/blog/nx-and-ai-why-they-work-together) — consolidated context means one agent can understand how subsystems interact. Splitting repos fragments the context that makes agents useful. The winning pattern might not be "multi-agent across repos" but "consolidate repos so single-agent has full context."
**Test quality becomes everything.** Carlini's key insight: "Claude will work autonomously to solve whatever problem I give it. So it's important that the task verifier is nearly perfect, otherwise Claude will solve the wrong problem." Your job becomes writing tests so good that agents can't game them.
**Model choice matters for long-running work.** Cursor found "GPT-5.2 models are much better at extended autonomous work: following instructions, keeping focus, avoiding drift." Opus 4.5 "tends to stop earlier and take shortcuts when convenient." Different models for different roles — they use the best model per task, not one universal model.
If you're not comfortable with 3-5 parallel agents and some chaos, don't use any of this. Single-agent Claude Code with Plan Mode handles most work. Add complexity when you hit real limits, not theoretical ones.
The native approach will improve. Anthropic will add session resumption, better persistence, more coordination options. The community tools will adapt or die. But the fundamental tension remains: **native is convenient, external is controllable.** Pick based on whether you need to understand what's happening or just need it to happen.
**Update (August 2026):** It improved faster than I'd guessed. Claude Code shipped [dynamic workflows](https://claude.com/blog/introducing-dynamic-workflows-in-claude-code) in May — tens to hundreds of subagents running end-to-end on migrations and audits, not just parallel features. The tension holds anyway. You still trade legibility for convenience. You've just moved the line.
### Design Physics: When Interfaces Meet Agents (2026-02-05)
URL: https://bristanback.com/posts/design-physics/
Updated: 2026-04-17
> Traditional UX has a hidden assumption: humans on both sides. That assumption is breaking.
I was designing a tool schema last month — the interface an AI agent uses to call a function — and caught myself adding a tooltip. A tooltip. For a machine. The instinct was so deep I didn't even notice it until I'd written the microcopy.
That's when the disorientation hit. I've been designing interfaces for over a decade, and suddenly I don't always know who's on the other side. A human? An agent? Both in sequence? The old instincts fire, but they land wrong.
Traditional UX has a hidden assumption: humans on both sides. A human designs the interface; a human uses it. Every principle we've developed — Fitts's Law, cognitive load theory, the 80/20 rule — assumes biological constraints. Attention is scarce. Working memory is limited. Motor control is imprecise. The entire discipline is built on the physics of being a person sitting in front of a screen.
That assumption is breaking. And we don't have new principles yet. Just hunches.
---
The disorientation came into focus when I realized the problem has a shape. There are two axes: who's building the interface (human or agent), and who's consuming it (human or agent). That gives you four quadrants — four different sets of physics:
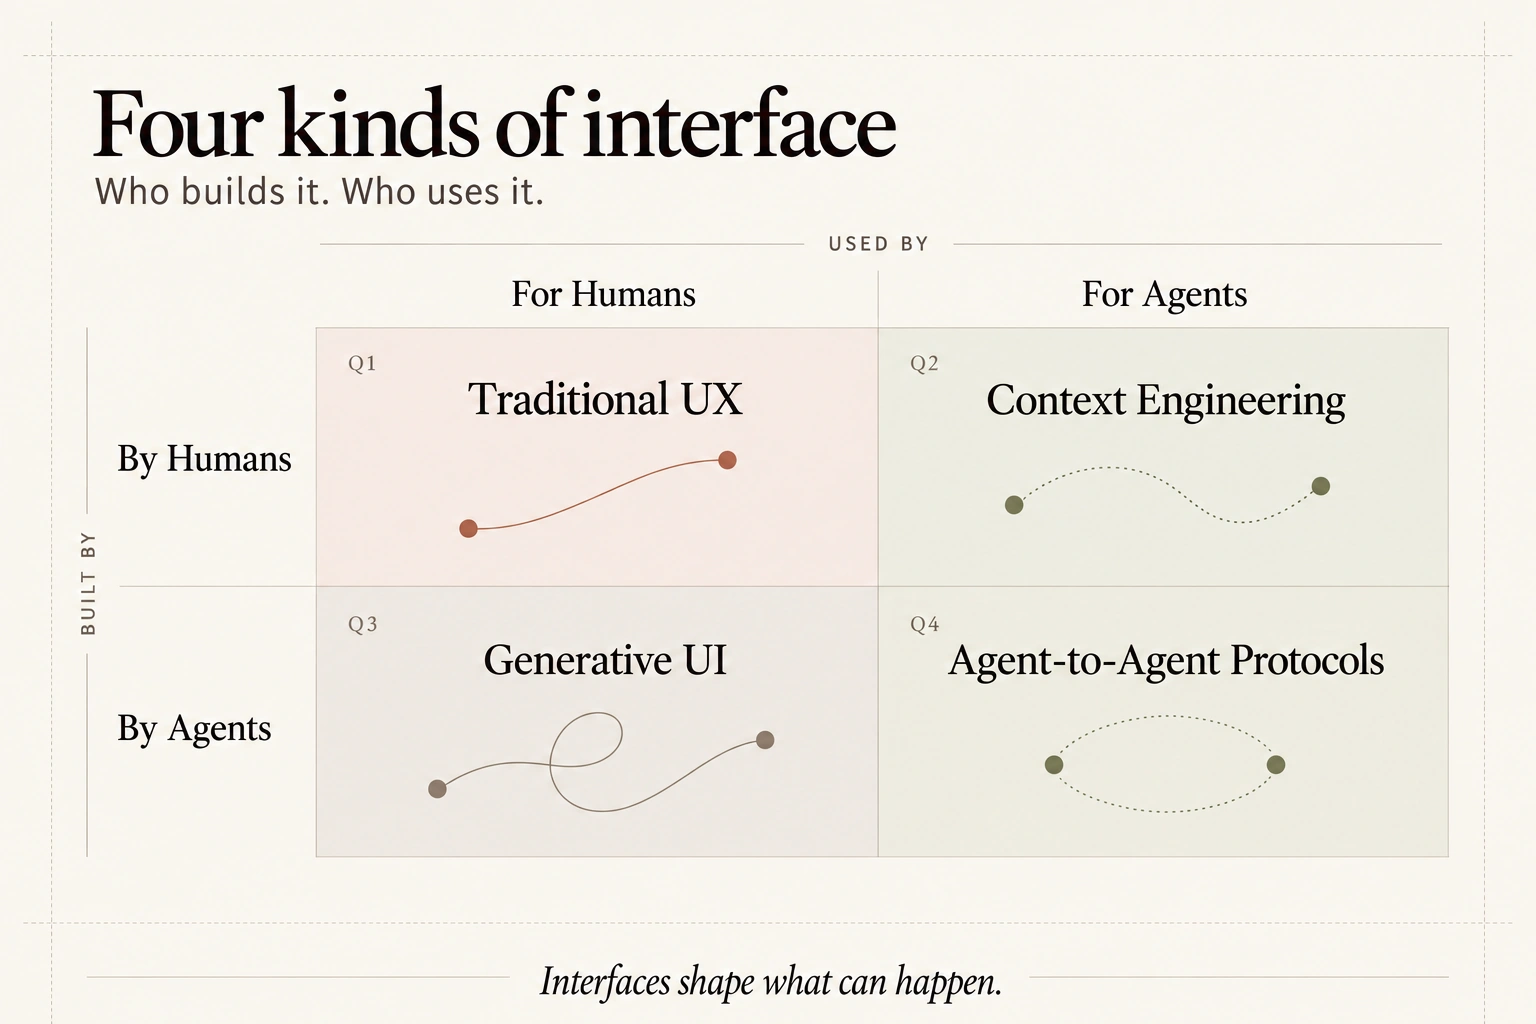
I've spent years in the first quadrant. The others, months at most. What I know is uneven — and the unevenness is the point. Most design teams are in the same position: deep expertise in one quadrant, applied to problems that live in another.
---
The quadrant where I keep getting surprised is Q2 — humans designing for agents. Most AI product work lives here today: prompts, tool schemas, system instructions that shape how AI behaves.
My tooltip instinct was a Q1 habit bleeding into Q2. Cognitive load theory tells you that humans can hold roughly seven items in working memory. An agent's "working memory" is its context window — orders of magnitude larger, with completely different failure modes. I was designing for a person who doesn't exist.
The insight I keep returning to: constraints matter more than instructions. You can't prompt your way to reliability. You need structured outputs, validation schemas, and bounded action spaces. The prompt is a suggestion. The schema is a law.
This is more concrete than it sounds. Tool descriptions alone account for roughly 40% of task completion improvement in agent benchmarks. A well-structured tool definition — clear parameter types, explicit descriptions of what each field means, constrained enums instead of open strings — does more for agent performance than paragraphs of natural language instruction.
If you're a designer working on AI products and you're not thinking about schema design, you're designing in Q1 while your product lives in Q2. This is the most common mistake I see.
---
Q3 — agents building for humans — is where the constraint question gets interesting. AI generates interfaces on the fly. Vercel's v0 is early here. Claude artifacts. Dynamic dashboards that reconfigure based on user intent.
The challenge is coherence over time. When every screen is generated, how do you maintain brand, accessibility, and user expectations? A static design system assumes humans are producing the components and can exercise judgment about context. A generative system has no such judgment — it'll produce something that matches the prompt but violates the brand, breaks accessibility, or confuses users who expected consistency.
The answer, I think, is design tokens as hard constraints rather than suggestions. Not "prefer this color palette" but "these are the only colors that exist." Not "try to maintain 16px body text" but "body text is 16px, period." The tighter the constraint system, the more reliable the generation.
Anthropic's [Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs), launched in April 2026, is Q3 going mainstream. Its first step is ingesting your codebase and design files to build a design system that gets applied automatically — hard constraints, not suggestions, exactly as described above. But the bigger Q3 story is *who it's for*: not just designers working faster, but founders, PMs, and marketers producing polished visual work without a design background. Figma assumes a trained designer in the loop. Claude Design [does not](https://venturebeat.com/technology/anthropic-just-launched-claude-design-an-ai-tool-that-turns-prompts-into-prototypes-and-challenges-figma). The expansion of the design user base to non-designers is Q3's real disruption.
This is the problem I explored more fully in [[Rapid Generative Prototyping: Design in the Post-Figma Era|Rapid Generative Prototyping]] — how constraint architecture replaces mockups as the designer's primary deliverable.
---
And then there's Q4 — agents building for agents — which I said was mostly unexplored when I first wrote this. That was February. It's not unexplored anymore. It's a land rush.
The protocol space has been clarifying fast, and the shape of it tells you something about what Q4 design actually means. There are at least three layers forming:
**MCP (Model Context Protocol)** is the tool layer — how an agent discovers and invokes capabilities. "Here are the functions you can call, here are their schemas, here's what they return." Anthropic released it, and it's become the closest thing to a standard. It's Q2 infrastructure that Q4 systems build on top of.
**A2A (Agent-to-Agent)** is the peer layer — Google's protocol for agents talking to other agents as equals. Discovery, negotiation, task delegation. If MCP gives agents hands, A2A gives them a voice.
**ACP (Agent Client Protocol)** sits in between — standardizing how editors and orchestrators talk to coding agents. It's the protocol I've been using to dispatch Claude Code from my own workflow, and using it taught me something about Q4 that I wouldn't have gotten from reading the spec.
The interesting thing isn't any individual protocol. It's that they're solving *different problems* and the boundaries between them are the design decisions. MCP assumes a hierarchical relationship — a model calls a tool. A2A assumes a peer relationship — agents negotiate. ACP assumes an orchestration relationship — a client dispatches work and monitors progress. The topology of the relationship *is* the design choice.
This is what "good UX" means when both parties are machines: it means getting the relationship model right. Not the visual layout, not the information architecture — the *power architecture*. Who initiates? Who has authority to approve or reject? Who holds state? Who can interrupt? These are UX questions, but they look nothing like the UX questions I spent a decade answering.
I still have more questions than answers in this quadrant. But the questions have gotten more specific, and that feels like progress.
---
Across all four quadrants, the same pattern keeps recurring: the interfaces that worked best were the ones with the strongest constraints. Not the best prompts, not the most detailed instructions — the tightest boundaries on what could happen.
That observation turned into a separate essay — [[Code Owns Truth]] — which develops a three-layer model: constraints bound the mutation space, prompts express intent, code is the source of truth. The designer's job is increasingly the constraint layer.
The 2×2 is where it started. Each quadrant is a different expression of the same underlying question: who sets the constraints, and for whom?
If you're designing for AI-touched systems, the first question isn't "what should this look like?" It's "which quadrant am I in?" Most teams think they're in Q1 when they're actually in Q2 or Q3. The physics are different. The principles are different. The failure modes are different.
I find that exciting and unsettling in roughly equal measure. There's real design work to do in quadrants we barely understand. The old playbook was comfortable. These new quadrants don't have playbooks yet.
### The SaaSpocalypse (2026-02-05)
URL: https://bristanback.com/posts/saaspocalypse/
Updated: 2026-05-29
> Anthropic wiped $285 billion off software stocks this week. The market is panicking about AI replacing tools. But the real disruption is what it means for the people who build them.
I was watching the ticker on Tuesday morning when Thomson Reuters dropped 15.8% in an hour. Then LegalZoom, nearly 20%. I kept refreshing, the way you do when something feels like it might matter. By noon, $285 billion had evaporated from software, financial services, and legal tech. They're calling it the "SaaSpocalypse."
The trigger was Anthropic's Cowork plugins — but the trigger isn't the interesting part. What caught me was the feeling in my chest while I watched. Relief that the conversation is finally public. Dread that it's real enough to price. The skills I spent a decade building are becoming... not worthless, but *different*. Cheaper. More abundant. The thing that made me valuable is now something I coordinate rather than do.
Is it an [overreaction](https://www.reuters.com/business/media-telecom/global-software-stocks-hit-by-anthropic-wake-up-call-ai-disruption-2026-02-04/)? Probably. When DeepSeek triggered a similar panic last year, Nvidia lost $600 billion in a day. A year later, the feared disruption never materialized. Markets overcorrect. Fear spreads faster than fundamentals.
But here's what's different this time: **the conversation is finally public.** The anxiety that builders have felt privately for a year — "wait, can AI actually do my job?" — is now being priced into the market. Wall Street is catching up to what anyone using Claude Code already knew: execution is getting cheaper. Fast.
> "In 2026, writing code is no longer the hard part. AI can generate features, refactor services, and accelerate delivery at scale. Speed is now expected, not a differentiator. What AI removed is friction, not responsibility."
> — [Security Boulevard](https://securityboulevard.com/2026/01/why-senior-software-engineers-will-matter-more-in-2026-in-an-ai-first-world/)
This lands differently when you're living it.
---
## From Vibe Coding to Vibe Working
[Andrej Karpathy coined "vibe coding"](https://x.com/karpathy/status/1886192184808149383) in February 2025: "fully give in to the vibes, embrace exponentials, and forget that the code even exists." Steve Yegge took it further, describing work as fluid—"an uncountable substance that you sling around freely, like slopping shiny fish into wooden barrels at the docks."
> "Some bugs get fixed 2 or 3 times, and someone has to pick the winner. Other fixes get lost. Designs go missing and need to be redone. It doesn't matter, because you are churning forward relentlessly on huge, huge piles of work."
> — [Steve Yegge, "Welcome to Gas Town"](https://steve-yegge.medium.com/welcome-to-gas-town-4f25ee16dd04)
This sounds chaotic. It is chaotic. But it's also the emerging reality for anyone running AI at scale.
Now the term is spreading beyond engineering. Anthropic's Scott White [announced Opus 4.6](https://www.cnbc.com/2026/02/05/anthropic-claude-opus-4-6-vibe-working.html) this week with a new framing: **vibe working**.
> "Everybody has seen this transformation happen with software engineering in the last year and a half, where vibe coding started to exist as a concept... I think that we are now transitioning almost into vibe working."
Anthropic demonstrated this with Cowork—the plugin system that triggered the selloff—built in about ten days. ["@claudeai wrote Cowork,"](https://x.com/felixrieseberg/status/2010882577113268372) their PM Felix Rieseberg confirmed. They vibe coded an enterprise integration layer. OpenAI followed with [Frontier](https://www.theverge.com/ai-artificial-intelligence/874258/openai-frontier-ai-agent-platform-management), their competing platform for deploying AI agents in enterprises.
Microsoft branded it [Agent Mode](https://www.microsoft.com/en-us/microsoft-365/blog/2025/09/29/vibe-working-introducing-agent-mode-and-office-agent-in-microsoft-365-copilot/) in Excel and Word—describe tasks in plain language and the AI handles the work. But how "agentic" is it really? Their [own guidance](https://learn.microsoft.com/en-us/microsoft-copilot-studio/guidance/autonomous-agents) emphasizes "least-privileged access" and "small, incremental expansions of responsibility." It's more AI-assisted features than autonomous agents.
Google's approach is similar: [Gemini in Workspace](https://workspace.google.com/solutions/ai/) adds AI to Sheets, Docs, Gmail—useful, but not transformative. Where Google gets more interesting is [Gemini Enterprise](https://cloud.google.com/gemini/enterprise), which lets you build custom AI agents with permissions-aware access to your data. Notion [teased the same](https://www.notion.com/blog/introducing-notion-3-0): custom agents to automate different workflows, coming soon.
Salesforce went furthest on marketing: [Agentforce 360](https://www.salesforce.com/news/press-releases/2025/10/13/agentic-enterprise-announcement/) is their platform for "the Agentic Enterprise," and they shipped a feature called **Agentforce Vibes**—letting builders "vibe-code" apps grounded in company data. They're reporting 119% agent growth in the first half of 2025.
The shift isn't from "engineer" to "prompt engineer." That's too small. The shift is from **maker** to **orchestrator**. From building to coordinating. From depth to breadth. And it's coming for every knowledge worker.
But a year in, the lesson isn't pure chaos. LLMs are good—and getting better—at greenfield work: new projects, clear requirements, blank slates. They struggle with brownfield: existing codebases, implicit conventions, accumulated context. The answer isn't to reject vibe coding. It's to **harness** it—add constraints, guardrails, structure. Without them, you get [tech debt at AI speed](https://thenewstack.io/5-challenges-with-vibe-coding-for-enterprises/), errors faster than humans can review, and code that works but nobody understands why.
The physics I explore in [[Code Owns Truth]] point toward the same conclusion: constraints are the design layer. Prompts express intent. Code owns truth. The vibe is real, but the vibe needs boundaries.
---
## The Ecosystem Shakeout
So I started looking at what's actually getting disrupted, and the pattern is clearer than the market panic suggests.
### Ticketing: Adapt or Replace?
The ticketing systems that track human work are racing to become platforms for AI work.
**Atlassian** launched Rovo—AI agents inside Jira that triage tickets and route work. They're treating agents as a feature layer on top of existing workflows.
**Linear** went further with "[Linear for Agents](https://linear.app/agents)"—AI as full workspace members, assigned to issues, @mentioned in comments. The human remains "primary assignee" while the agent is a "contributor." Accountability preserved, execution delegated.
Meanwhile, new tools like **[Beads](https://github.com/steveyegge/beads)** skip the adaptation entirely—built *for* agents from scratch, no legacy assumptions about human workflows.
The question: **Do you adapt existing tools for AI, or build new tools for an AI-first world?** Linear's hybrid might win the transition. AI-native tools might win the destination. Jira's adding AI to human bureaucracy—that's a harder pivot.
### Automation: Zapier vs. n8n vs. Claude Cowork
The workflow automation platforms face an existential question: **What happens when AI can just do the thing?**
Zapier's response: lean into it. They shipped [Agent Skills for Claude](https://zapier.com/blog/zapier-mcp-agent-skills/)—MCP integrations that let Claude trigger Zapier automations across 8,000+ apps. They achieved 89% AI adoption internally with 800+ agents deployed. Their strategy: become the glue between AI and everything else.
**n8n** is betting on hybrid workflows—AI for the intelligence, n8n for the plumbing. Claude generates n8n workflows. n8n connects to everything. The platform becomes an orchestration layer that AI writes to.
But here's the threat: **Claude Cowork doesn't need Zapier.** If the AI can directly access APIs, authenticate with services, and execute multi-step workflows autonomously—why route through a middleman?
The automation platforms survive if they become connectors (the authentication and API glue that AI uses), guardrails (human-in-the-loop checkpoints for risky operations), or monitoring (observability for what agents are doing). They don't survive as "no-code" tools for humans who can't code. That market is evaporating.
### The Pattern
**Tools survive by becoming either infrastructure (AI needs you) or judgment aggregators (humans need you for decisions AI can't make).** Everything in the middle—tools that automate what AI now does natively—faces compression.
Core infrastructure isn't going anywhere: AWS, GCP, Cloudflare, Fly.io. Context repositories become more valuable, not less: Notion, Confluence, wikis — AI needs business context, decisions, history.
Single-function SaaS is in trouble. If Claude can do your core function, you're a feature now. "No-code for humans" is in trouble — the target user can now just ask AI. Expensive human expertise platforms — legal research, financial analysis — that's exactly what Cowork demonstrated.
The no-code/low-code category is eating itself. In May 2026, [Wix cut 20% of its workforce](https://www.cnbc.com/2026/05/28/wix-layoffs-ai-exchange-rates.html) (~1,000 roles) — their CEO citing AI changes to the industry. [Webflow's layoffs](https://www.sfchronicle.com/tech/article/webflow-layoffs-tech-san-francisco-22279561.php) were called "a bloodbath" by employees; CEO Linda Tong pivoted the company toward an "agentic web marketing platform." [ClickUp cut 22%](https://x.com/DJ_CURFEW/status/2057522382315929802) and introduced million-dollar salary bands for employees who "create outsized impact using AI." Three companies, three vocabularies, one underlying claim: the headcount math for traditional no-code SaaS no longer pencils against AI-native competitors. When the platforms that helped non-engineers build software are themselves being disrupted by AI, the compression is hitting every layer.
The design tools are now in play too. In April 2026, Anthropic launched [Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs) — a standalone tool that generates prototypes, decks, and marketing collateral from conversation, with a direct handoff to Claude Code for production. Three days before the launch, Anthropic's CPO Mike Krieger [resigned from Figma's board](https://techcrunch.com/2026/04/16/anthropic-cpo-leaves-figmas-board-after-reports-he-will-offer-a-competing-product/). Figma had just shipped Code to Canvas in February to become infrastructure for the AI loop. Anthropic bypassed the bridge entirely. The opinionated software layer becomes optional — and Figma's opinion was that design flows through a professional designer on a spatial canvas.
The uncertain middle is wide: observability platforms built for human dashboards, GitHub competing with its own Copilot, Slack wondering if it becomes an agent coordination hub or gets bypassed entirely, Jira carrying too much legacy to pivot fast but too much lock-in to die quickly.
### The Forward Deployed Engineer Illusion
There's a role that's been trending in enterprise sales: the "Forward Deployed Engineer." Palantir pioneered it—embed engineers at customer sites to handle the complex integration work that software alone can't solve. The pitch: enterprise systems are too messy, too customized, too entangled for self-service. You need humans on the ground.
I think this is temporary.
Every major AI company is racing to be the enterprise agent layer—Cowork, Frontier, Copilot Studio. And **the integration messiness that justifies FDEs is exactly what vibe working dissolves.**
From my own experience: Claude Code is remarkably good at reading API documentation—even poorly written ones—and using existing CLI tools to explore, investigate, triage, and connect systems together. It's not perfect for large datasets or deeply stateful processes, but it's improving fast.
The contrast with browser automation is stark. Amazon's AGI Lab [published research](https://labs.amazon.science/blog/what-makes-browser-use-hard-for-ai-agents) on why browser use is so hard for AI agents: "Multiplication of uncertainties is the killer of reliability." Each step—perception, actuation, page load—might succeed only a certain percentage of the time. Multiply those probabilities across a multi-step task and reliability tanks. The WebArena benchmark shows even top models achieve only [35.8% success rates](https://www.infoworld.com/article/3812644/browser-use-an-open-source-ai-agent-to-automate-web-based-tasks.html) on real-world web tasks.
But CLIs and APIs? Those are deterministic. The "complex enterprise context" that used to require months of on-site engineering becomes a conversation. Claude Code doesn't care that your Salesforce instance has 47 custom fields and a decade of technical debt. It reads the schema, understands the constraints, and builds the integration.
Maybe I'm naive to enterprise. But I don't think integration points remain messy for long when AI can read your existing codebase and infer conventions, generate adapters between incompatible systems, and handle the long tail of edge cases that used to require human judgment.
The FDE model assumes that understanding a customer's systems is hard work that scales linearly with headcount. Vibe working makes it scale with inference. The engineers who spent years learning one customer's Byzantine internal systems? That knowledge moat is evaporating.
### Who's Winning the Vibe Coding Wars?
The AI coding tools have stratified fast. [85% of developers](https://devecosystem-2025.jetbrains.com/artificial-intelligence) now use AI tools regularly, with Claude Code, Cursor, and Codex fighting for dominance. Each is racing to ship multi-agent orchestration—the ability to spawn and coordinate multiple AI agents on a single task.
The pattern: **Anthropic is winning on integration, Cursor on UX, OpenAI on raw capability, Google on.. patience.** But every provider wants to be the platform, not just the model. Anthropic [cracked down on third-party harnesses](https://venturebeat.com/technology/anthropic-cracks-down-on-unauthorized-claude-usage-by-third-party-harnesses) last month—the message: flat-rate pricing requires their tools.
For the full breakdown of what's shipping and how to choose, see [[The Multi-Agent Moment]].
### The Subsidy Question
Here's the uncomfortable math: **current AI pricing is subsidized by investor capital, not sustainable economics.**
OpenAI spent [$22 billion in 2025 against $13 billion in revenue](https://fortune.com/2025/11/12/openai-cash-burn-rate-annual-losses-2028-profitable-2030-financial-documents/)—$1.69 for every dollar earned. They project $74 billion in operating losses in 2028 alone, with cumulative cash burn reaching $115 billion through 2029. The bet: hit $200 billion in revenue by 2030 and turn profitable then.
Anthropic is more disciplined. Their cash burn is projected to drop to one-third of revenue in 2026 and just 9% by 2027, with break-even expected in 2028. They're avoiding expensive video and image generation, focusing on corporate customers (80% of revenue).
What does this mean for builders?
**The current pricing is artificially cheap.** API costs reflect what investors are willing to subsidize, not what the compute actually costs. When the subsidy ends—through profitability pressure, funding crunches, or market corrections—prices go up.
**Lock-in gets more expensive over time.** If you build deep dependencies on one provider's cheap API pricing, you're exposed when they need to raise prices. Anthropic's harness crackdown is a preview: subscription arbitrage disappeared overnight.
**The endgame is unclear.** OpenAI is betting on dominance—spend everything to win the market, then monetize. Anthropic is betting on efficiency—reach profitability faster with less risk. Google is betting on integration—bundle AI into existing products. All three could work. All three could fail.
The honest answer: **nobody knows what sustainable AI pricing looks like yet.** We're all building on shifting sand. The companies burning billions are guessing too.
---
## What Becomes Valuable
Here's a frame I keep coming back to: **SaaS is paying for opinions.**
When you buy software, you're not just buying features. You're buying someone else's opinion about how work should flow. Their assumptions about what steps come first, what fields matter, what the happy path looks like. Sometimes those opinions are useful. Sometimes they're constraints that don't fit how you actually work.
AI dissolves those opinions. Instead of adapting to Jira's workflow or Salesforce's data model, you describe what you need and the system adapts to you. The opinionated software layer becomes optional.
So what survives?
**Models** — The reasoning engines themselves. Anthropic, OpenAI, Google. They're the new primitives. Everything else is built on top.
**Data** — Not data "sellers" exactly, but **data sources**. The AI labs are paying real money: Reddit pulled [$203 million in data licensing](https://www.allmo.ai/articles/unbundling-ai-a-list-of-public-training-data-deals-october-2025), News Corp got ~$250 million over five years, OpenAI offers $1-5M per corpus. Shutterstock is pivoting from stock photos to "AI services for model training." The value shifted from selling content to humans to licensing it to machines.
**Infrastructure** — AWS, GCP, Azure, Cloudflare. The compute layer. IaaS doesn't care what runs on it. If anything, AI makes infrastructure *more* valuable—it's compute-hungry and the demand is only growing.
The middle layer—SaaS tools that wrap workflows around human workers—that's what's compressing.
### The Data Paradox
Here's the tension: AI labs are paying unprecedented amounts for training data. But what happens when sources start locking it down?
Reddit went from free API to $60M/year licensing deals. Stack Overflow made their data exclusive to OpenAI, and [users deleted their answers in protest](https://techcrunch.com/2024/05/16/openai-inks-deal-to-train-ai-on-reddit-data/). News sites are blocking AI crawlers. Getty sued for copyright infringement.
The implications cut both ways:
**If data stays open:** AI gets smarter, models improve, the winners are whoever has the best reasoning engine. Data becomes a commodity.
**If data locks down:** We get balkanized AI. Models trained on different corpuses. Quality depends on who cut the best licensing deals. Data becomes a moat.
The honest answer: we don't know which world we're heading toward. The legal frameworks haven't caught up. The economic incentives point toward closure. But the technical reality is that models trained on open data are already out there, and you can't un-train them.
What's clear: **the companies that control valuable data sources—Reddit, Stack Overflow, news archives, scientific journals—have leverage they didn't have before.** Whether they use it to extract rent or build walls, the dynamics are shifting.
---
## The Weight of It
The $285 billion selloff isn't about Cowork or Agent Teams or any specific tool. It's about the market finally internalizing what builders have known for a year: **AI changes the economics of knowledge work.**
Software that used to require specialized teams can now be approximated by general-purpose agents. Legal research, financial analysis, code generation—the boundaries are blurring.
Employment for recent CS graduates has declined 8% since 2022 ([Oxford Economics](https://www.oxfordeconomics.com/wp-content/uploads/2025/05/US-Educated-but-unemployed-a-rising-reality-for-college-grads.pdf)). 90% of tech workers now use AI in their jobs ([Google](https://www.oxfordeconomics.com/wp-content/uploads/2025/05/US-Educated-but-unemployed-a-rising-reality-for-college-grads.pdf)). The funnel that used to produce senior engineers is narrowing at the entry point. We're changing who gets to learn how to build it — not just how software gets built.
> "38% of engineering leaders fear juniors will get less hands-on experience in AI-heavy workflows."
> — [CodeConductor](https://codeconductor.ai/blog/future-of-junior-developers-ai/)
The response isn't to panic. It's to ask: **what do I do that AI can't fake?**
For me, it's judgment. Taste. The ability to recognize when something is wrong before I can articulate why. The willingness to own outcomes when systems fail.
These aren't skills you learn from a tutorial. They come from years of building things, shipping things, watching things break. They come from caring about craft even when nobody's watching.
AI makes execution cheap. That makes judgment expensive.
Some people will thrive in the orchestration era. They like systems thinking, coordination, judgment calls. Others will struggle. They liked the craft of code, the satisfaction of a clean implementation, the feeling of having *made* something. Both reactions are valid. Neither is wrong.
The existential crisis isn't about being replaced. It's about becoming someone new.
---
*The tools for this transition are already shipping. In [[The Multi-Agent Moment]], I break down what's available—Claude's Agent Teams vs. Gas Town vs. the community alternatives—and how to navigate the chaos.*
---
*If you're feeling the same weight, I'd like to hear how you're navigating it.*
### Code Owns Truth (2026-02-04)
URL: https://bristanback.com/posts/code-owns-truth/
Updated: 2026-04-17
> We obsess over prompt engineering when we should obsess over constraint engineering. The prompt is a request. The constraints are the physics. The code is what ships.
I spent an afternoon last month rewriting the same prompt four times. Each version was more precise, more carefully structured, more detailed about what I wanted. Each one produced code that looked right and broke in a different way.
The fifth time, I didn't touch the prompt. I wrote a test. Then two more tests. Then I ran the original sloppy prompt against them — and the output was correct, because now "correct" meant something.
That afternoon rearranged how I think about building with AI.
---
We obsess over prompt engineering when we should obsess over constraint engineering.
A prompt expresses intent. It's the why, the what, the how — but it's inherently fuzzy. The model interprets it. It mutates within whatever space you've given it. And then the session ends, the context window closes, and the prompt is gone. It was temporary, lossy, context-dependent.
Constraints are different. Constraints survive.
A test suite survives. A type system survives. A feature list, a linter config, a CI pipeline — these persist across sessions, across context windows, across models. They bound the mutation space. They define what "correct" looks like before anyone starts building.
The prompt is a request. The constraints are the physics. The code is what ships.
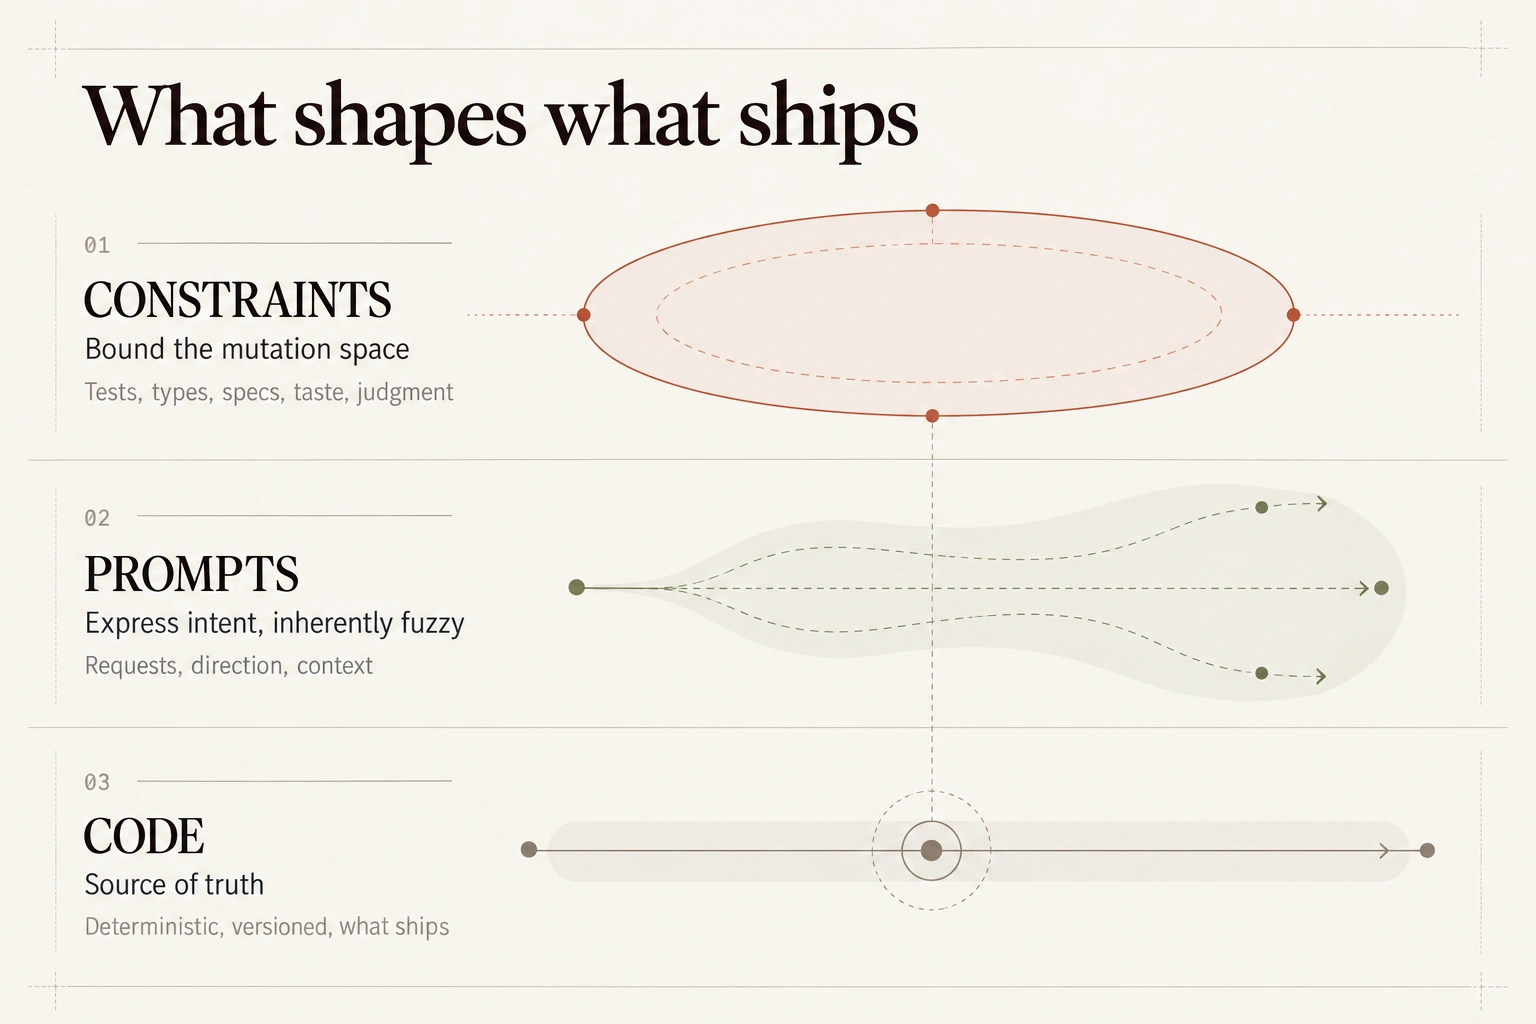
"Prompt engineering" as a discipline has always felt slightly wrong to me, and I think this is why. You're not engineering the prompt. You're engineering the *constraints that shape what prompts can produce*. The prompt is the thing you say to the contractor. The constraints are the building code. One is a conversation. The other is law.
---
But not all constraints are the same, and the distinction matters for where you spend your time.
**Mechanical constraints** are the ones machines can verify. Test suites, type systems, linters, CI/CD, feature lists. You run them, they pass or fail, no judgment required. Anyone can set them up. AI can write them.
**Human constraints** are harder. Taste — what's elegant versus ugly, what belongs versus what's noise. Axioms — the foundational assumptions you build on. Judgment — the wisdom from experience that tells you when to follow the rules and when to break them.
Both survive context windows. Both persist across sessions. But the mechanical constraints are table stakes. The human constraints — taste, judgment, the sense of what a thing should *be* — those are the differentiator. Those are what make one system thoughtful and another system merely functional.
This is why I keep coming back to judgment as the scarce resource. Not prompting skill. Not execution speed. The ability to set the right constraints — to know what the physics of your system should be before anything gets built.
---
The pattern underneath all of this is older than AI.
Test-driven development works the same way: you write a failing test (constraint), you write code to pass it (mutation), you verify (the test passes). The spec precedes the implementation. The spec survives context changes. The artifact gets checked against something objective.
[Anthropic's approach to long-running agents](https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents) follows the same structure. Their harness engineering model uses an initializer agent to create a feature list — sometimes 200+ requirements, all marked as incomplete. A coding agent works through them one at a time. A progress file persists across context windows so nothing gets lost between sessions. End-to-end testing verifies the result.
The feature list and progress file are constraints. The coding prompt is intent. The code is truth.
[Phil Schmid frames it well](https://www.philschmid.de/agent-harness-2026): the harness is the operating system, the model is the CPU, context is RAM, the agent is the application. The harness implements what he calls "[context engineering](https://www.philschmid.de/context-engineering)" — strategies that survive the model's context limitations. And his key insight lands the point: "The ability to improve a system is proportional to how easily you can verify its output."
If you can verify it, you can improve it. If your constraints are weak — if "done" means "looks done" — your outputs will drift and you won't know until it's too late. That afternoon I spent rewriting prompts? I was optimizing the wrong layer. The constraints are what compound.
Anthropic extended this pattern to visual design in April 2026 with [Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs). It ingests your design system — tokens, typography, components — as constraints, generates prototypes through conversation, and hands off to Claude Code for production. The same three layers, applied to pixels instead of code: design system is the constraint, the prompt is the conversation, the artifact is the output. The gap between "efficiency and trust" that [[Rapid Generative Prototyping: Design in the Post-Figma Era|Rapid Generative Prototyping]] identified in design tooling? Constraints are exactly where it closes.
---
This blog is an attempt to practice the human constraint layer.
Taste in what gets published, judgment in how ideas connect, axioms about what matters. The mechanical side — the site builds, the deploys, the formatting — is table stakes. The human side is the work.
Whether it succeeds is a different question. But that's the intent.
To be the physics, not just the prompt.
### Proof, Not Truth: Epistemic Humility in Knowledge Systems (2026-02-04)
URL: https://bristanback.com/posts/proof-not-truth/
Updated: 2026-02-13
> We don't sell answers. We sell receipts. The receipts are what earn the right to call something true.
We're building a knowledge system at work — a graph that aggregates signals about products, codes, and claims. The naming question came up: do we call it a "Truth Graph"?
I went back and forth on this. The reasoning matters more than the answer.
---
My first instinct was no. Truth is a dangerous word for a system that stores assertions with confidence levels.
Here's the context. Even frontier LLMs hallucinate at meaningful rates — the [Vectara Hallucination Leaderboard](https://github.com/vectara/hallucination-leaderboard) (February 2026) shows 8-15% on grounded summarization and north of 30% on complex reasoning and open-domain recall. If you're building a knowledge system that ingests AI-generated signals alongside human-sourced data, you need to take uncertainty seriously at the architectural level.
You can't just store assertions and call them facts.
So the question isn't philosophical. It's engineering: how do you build a system that's honest about what it knows and how well it knows it?
My instinct was to call it a "Proof Graph." Proof shows the work. Proof carries its evidence. Proof invites scrutiny instead of demanding trust.
But the more I sat with it, the more I realized the problem isn't the word *truth*. It's what we let truth mean.
---
Take a promo code. SAVE20 is "true" — it works at checkout — until it isn't. It expires, gets rate-limited, or the retailer kills it without notice. Yesterday's working code is today's expired one.
Most systems treat this as binary: valid or invalid. But the reality is messier. Verified 2 hours ago, 847 successful applies this week, confidence 0.91 — but decaying, because a failure signal came in 23 minutes ago. The system knows it's getting stale. The truth has a half-life, and the half-life is part of the data model.
Product recommendations are the same problem at a different timescale. We make claims like "best vacuum for pet hair." That's not a fact — it's a position backed by 47 reviews, 3 teardown videos, and 12k purchase signals, carrying 0.84 confidence. When a better product launches or new reviews come in, the confidence updates. The claim is traceable. Someone can check the receipts.
These are two problems I'm actually working on, and they taught me the same thing: most systems conflate two very different kinds of truth.
**Naive truth** is binary. Something is true or it isn't. The data goes in, the label says true, and nobody asks what happens when the evidence changes. **Scientific truth** is provisional — the best-verified model given available evidence, subject to revision when better data arrives. Not "we know this" but "this is currently holding."
The essay I almost wrote argued for replacing truth with proof. The essay I'm actually writing argues for making truth mean something rigorous — and building systems that enforce the rigor.
In both cases — promo codes and product claims — the proof framing is honest about uncertainty (confidence scores), traceable (evidence sources), updatable (new evidence revises the proof), and falsifiable (you can check the receipts).
When it's wrong, you can trace why. That's the difference between a system that fails gracefully and one that fails mysteriously.
---
The architecture that makes this work is richer than a standard triple store.
Every node in the graph carries six elements:
`(Subject, Predicate, Object, Context, Evidence, Confidence)`
- **Subject**: What entity is this about?
- **Predicate**: What kind of claim?
- **Object**: What's being claimed?
- **Context**: When, where, under what conditions?
- **Evidence**: What sources support this?
- **Confidence**: How sure are we? (0.0–1.0)
The confidence element is what separates this from a database of facts. Facts don't have confidence levels. Proofs do.
---
And proofs aren't static. They mutate.
This is a critical part of the architecture — without mutation, you just have assertions with metadata. With mutation, you have a living system.
**Mutation triggers:**
1. **Decay threshold crossed** — evidence gets stale. A promo code verified last week is less trustworthy than one verified an hour ago. Confidence should reflect that automatically.
2. **Contradictory signal received** — new data conflicts with the existing claim. A flood of "code expired" reports should drop confidence immediately, not wait for a human to notice.
3. **Source invalidated** — a cited source goes offline or is discredited. If a review site we relied on turns out to be astroturfed, every claim sourced from it needs to be re-evaluated.
4. **User dispute filed** — someone challenges the claim. Human signals are evidence too.
Kinetic proofs rather than static facts. The graph is alive. Claims earn the status "true," maintain it through continued verification, and lose it when the evidence no longer supports them.
---
So what did we call it?
We called it a Truth Graph. But we meant it the rigorous way.
The insight I came to — and the reason I'm writing through the internal debate instead of just landing on an answer — is that truth was never a single thing. In science, truth is a falsifiable theory that survives testing. In law, it's evidence beyond reasonable doubt. In journalism, it's multiple sources, verified. In medicine, it's peer-reviewed and replicated.
Truth was always *truth-according-to-some-methodology*. The methodology was just implicit — which is how "truth" got sloppy. People started claiming it without showing their work.
If your graph stores assertions and calls them true without evidence, confidence, or decay — that's naive truth. Don't do it.
If your graph stores evidence with confidence levels, decays stale claims, revises when contradicted, and responds to disputes — that's scientific truth. Provisional knowledge. True until proven otherwise.
The receipts aren't separate from the truth. They're what *makes* it true. Proof gets absorbed into the noun.
A Truth Graph isn't a database of facts. It's a machine for earning and revoking the status "true."
---
The naming matters more than it sounds like it should. It shapes how engineers think about the system, how users calibrate trust, and what happens when you're wrong.
I pushed for "Proof Graph" because I was worried about the naive reading — engineers treating "truth" as permission to skip uncertainty. I came around to "Truth Graph" because the rigorous reading is actually *more demanding*, not less.
Proof says "here's my evidence." Truth says "I've earned this status, and I'll lose it if the evidence changes."
Truth carries a higher burden. It just needs a system that enforces it.
We don't sell answers. We sell receipts. The receipts are what earn the right to call something true.
---
This matters more now than when I started building it. Because there's a machine producing confident-sounding falsehoods at scale, and it doesn't have receipts.
LLMs are trained on web-scale text. Correct information, outdated information, confident-sounding nonsense — weighted roughly by frequency, not accuracy. Repetition looks like consensus to the model. If a wrong answer appears in fifty Stack Overflow threads and the right one appears in two, the model learns the wrong one harder. That's pre-training: the curriculum is the internet, and the internet isn't peer-reviewed.
Then comes RLHF — the fine-tuning step where human raters score outputs. Humans rate fluent, confident, well-structured answers highly, even when they're wrong. The model learns that hedging gets penalized and certainty gets rewarded. The training signal is "did the human like this," not "is this true." The reward function optimizes for plausibility. Plausibility is naive truth wearing a lab coat.
And now the loop closes. As AI-generated content floods the web, new models train on it. A model hallucinates a plausible-sounding claim. It gets published. It enters the next training corpus. The next model treats it as ground truth, generates it with higher confidence, more publications cite it. Each cycle launders the hallucination into apparent consensus. [Shumailov et al.](https://arxiv.org/abs/2305.17493) showed that models recursively trained on their own output lose the tails of their distributions — minority viewpoints, rare-but-correct facts, edge cases get smoothed away. The model converges on the average of what it's seen, which is increasingly its own reflection.
This is what a knowledge system without the 6-tuple looks like. No evidence chain — just repetition counts. No confidence decay — a fact hallucinated in 2024 carries the same weight in 2026. No context — collapsed into weights, unrecoverable. No falsification — the model can't check its own receipts because it doesn't have any.
Every element of `(Subject, Predicate, Object, Context, Evidence, Confidence)` is a check that the training loop lacks. Evidence asks *where did this come from* — not how many times it appeared, but what sources support it. Confidence asks *how sure, and is that certainty decaying*. Context asks *under what conditions*. Mutation triggers ask *what would change our mind*.
The training loop produces naive truth at industrial scale — assertions without methodology, confidence without evidence, consensus without verification. A Truth Graph is the countermachine. Not because it's smarter. Because it shows its work, and it forgets on purpose when the work stops holding up.
In a world of synthetic everything — AI-generated content, AI-sourced signals, confidence scores stacked on confidence scores — implicit methodology isn't good enough anymore. If your system claims truth, it needs to show how truth gets earned, maintained, and revoked.
That's the system. That's the graph.
---
*The production implementation of these principles is documented in [Anatomy of a Verdict: How SimplyCodes Adjudicates Truth in a Broken Economy](https://zenodo.org/records/18625118), a technical whitepaper on our verification architecture.*
### Self-Healing Systems: The Holographic Event Pattern (2026-02-03)
URL: https://bristanback.com/posts/holographic-events/
Updated: 2026-02-10
> Every event must carry everything a repair bot needs to act without asking questions. Don't scatter breadcrumbs — ship holograms.
Last Tuesday at 2am, one of our browser automation agents hit a Cloudflare challenge on a site it had been scraping cleanly for weeks. The selector for the submit button had changed — the site redesigned overnight. The agent logged "selector failed," retried three times, and moved on. Standard behavior.
When I looked at it the next morning, I had a log line and nothing else. No screenshot of what the page actually looked like. No DOM snapshot. No record of which selectors had already been tried. Just "selector failed" and a timestamp. To figure out what happened, I had to manually navigate to the site, inspect the page, cross-reference the old selectors, and guess at what had changed. The state I needed had already shifted — the page looked different again by Wednesday.
That thirty-minute forensics session is what made the pattern click. The problem isn't that browser automation breaks constantly — selectors change, challenges appear, responses slow down. The problem is that our failure events are breadcrumbs: thin traces that force you to reconstruct context from multiple sources after the fact. That works when failures are rare and humans are cheap. Neither is true for AI-orchestrated systems running 24/7.
## Holographic Events
The fix is to make every failure event self-contained: a hologram rather than a breadcrumb.
The core principle: **Every event payload should encapsulate the full context required to replay the situation at t₀ without querying external databases.**
A holographic event for a selector failure looks like:
```json
{
type: 'browser:selector:failed',
subject: 'chatgpt', // who
predicate: 'selector:failed', // what happened
object: 'submit', // what action
context: { // when/where
url: 'https://chatgpt.com/c/abc123',
recipeVersion: 'v1.2.0',
attempt: 3
},
evidence: { // proof
screenshot: 'base64...',
domSnapshot: '...',
selectorsAttempted: [
'[data-testid="send-button"]',
'button[aria-label="Send"]'
],
timing: { waitedMs: 5000 }
},
confidence: 0.0 // repair bot will set this
}
```
The structure mirrors the 6-tuple from [[Proof, Not Truth: Epistemic Humility in Knowledge Systems|Proof, Not Truth]] — subject, predicate, object, context, evidence, confidence. That's not a coincidence. The holographic event is a proof node: a claim about what happened, carrying its own evidence, with a confidence score that the repair system updates as it investigates.
This event is complete. A repair bot can analyze it, generate candidate fixes, test them, and update the recipe — without asking a single question.
## The Architecture
The executor runs browser automation. On failure, it emits a holographic event and moves on — no blocking, no retry loops. The repair bot polls for pending repairs, routes each to a strategy (selector repair, timeout increase, auth escalation), and updates the recipe if a fix is found.
Next time the executor runs, it picks up the fixed recipe automatically.
## The Tradeoffs
Holographic events are heavier than breadcrumbs. You're shipping screenshots, DOM snapshots, maybe even video clips. Storage costs go up.
But:
1. **Repair latency goes down.** The bot has everything it needs immediately.
2. **Human escalation gets better.** When a bot can't fix it, the holographic event is a perfect bug report.
3. **Audit trails are complete.** You can replay any failure without hunting through logs.
For high-value, failure-prone systems — like multi-model AI orchestration — the tradeoff is worth it.
---
Don't scatter breadcrumbs. Ship holograms.
Decouple execution from repair — emit and move on.
And design events for the repair bot, not the human. If a bot can't act on it without asking questions, it's not self-contained enough.
The system that heals itself is the one that remembers everything it needs — and carries that memory in every event.
### Hello World (2026-02-01)
URL: https://bristanback.com/posts/hello-world/
Updated: 2026-02-10
> First post. Why I built this blog and what I hope it becomes.
I almost didn't make this.
Not because it's hard — the technology is trivial. Markdown in, HTML out. About 500 lines of TypeScript. No frameworks, no client-side JavaScript, no CMS. Just files, a build script, and Cloudflare Pages Cloudflare Workers. I could have used Astro or Eleventy, but I wanted to understand every piece. The whole thing took a weekend.
The hard part was the other thing. The part where you decide you have something worth saying, out loud, with your name on it, when the internet already has plenty of opinions.
I've been building software for twenty years and writing about it for zero. That gap isn't an accident. Writing code is safe — it compiles or it doesn't, it works or it breaks, the feedback is mechanical. Writing *ideas* is exposed. You can't hide behind functionality. The person is right there.
So this is the first post on bristanback.com. Here's a code example to make sure syntax highlighting works:
```typescript
async function build(): Promise {
const content = await collectContent('content');
const validated = validateContent(content);
const parsed = await parseContent(validated);
const html = renderSite(parsed);
await writeOutput(html);
}
```
What surprised me: how little code it actually takes. Modern tooling (Bun, Tailwind, Shiki) does the heavy lifting. The hard part isn't the technology — it's deciding what to say and finding the discipline to say it.
I'll use this space to think out loud about building software, raising kids, making sense of a world that keeps changing faster than I can keep up. Not a portfolio. Not a brand play. Just thinking, with my name on it, because that's how I figure things out.
Will I actually write consistently? Will anyone read this who isn't obligated to? I don't know. But the site exists now, and that's more than it was yesterday.
## Notes
### The Scarcity Shift (2026-05-29)
URL: https://bristanback.com/notes/the-scarcity-shift/
> Software engineering compensation was built on scarcity, not just difficulty. That scarcity is eroding. The people who survive are either unusually broad or unusually deep.
A senior engineer at a major tech company makes $350–500K in total comp. The work is genuinely hard. But the price isn't set by how hard it is — it's set by how few people can do it.
That's the mechanism nobody wants to name. A lot of that comp was paying for *scarcity*, not just difficulty.
I've been a chief architect for twelve years at the same company — hiring and building through two major downturns and the current one. The pattern forming here isn't about AI eating jobs. It's about scarcity eroding, and what happens to the economics of a profession when the thing that made it expensive starts to loosen.
---
## What's Actually Happening
[144,000 tech workers](https://www.trueup.io/layoffs) have been laid off in 2026 so far, on pace to exceed last year's 245,000. The CEO memos all say "AI efficiency." The reality is muddier — Marc Andreessen [calls it](https://officechai.com/ai/higher-interest-rates-and-covid-over-hiring-causing-layoffs-not-ai-marc-andreessen/) a zero-interest-rate overhiring correction, Altman has [acknowledged](https://fortune.com/2026/02/19/sam-altman-confirms-ai-washing-job-displacement-layoffs/) "some AI washing," and [Oxford Economics](https://www.oxfordeconomics.com/resource/evidence-of-an-ai-driven-shakeup-of-job-markets-is-patchy/) suspects companies are dressing up layoffs as progress.
The cause doesn't change the pressure. Whether AI directly automates the work or merely redirects $725 billion in [infrastructure spending](https://www.businessinsider.com/big-tech-earnings-microsoft-ai-investment-capex-plan-2026-4) away from payroll, the result is the same: the supply of available engineers is rising while the number of seats is falling. That's a scarcity problem, and it runs in one direction.
The floor rose. A product manager with a coding agent can build something that works. A founder can ship a real product without a team. A marketing coordinator can spin up a landing page that would have been a two-week engineering ticket eighteen months ago. The work isn't gone. But the exclusivity that made it valuable is.
---
## The Shape
Economists have described labor market polarization as a barbell for decades — weight at both ends, nothing in the middle. The version forming inside software engineering is weirder: both surviving ends are high-skill, and the middle that's hollowing out is *also* high-skill. It's not about whether you're smart. It's about the shape of what you know.
On one end: the person who can close the loop from problem to value without a team. Not a job title — a capability. The test is specific: *Can you sit alone with a business problem, an AI toolkit, and no spec, and produce something a customer would pay for?* That requires holding business model, customer need, product instinct, and technical judgment simultaneously. It's the founder who codes. The engineer who does their own user research. The designer who understands unit economics. The common thread isn't any one skill — it's the ability to make the whole decision, not just the technical one.
On the other end: depth that takes years of real consequences to build. Twenty years of database internals. Compiler design. Distributed systems failure modes. Security architecture. The judgment that comes from scar tissue — not because the knowledge is secret, but because the cost of learning it can't be compressed. These people have *more* scarcity than before, because the systems they understand are getting more critical and there are fewer of them.
In the middle — the part under pressure — is execution without either kind of leverage. People whose value was primarily in turning known requirements into working code at average depth. This isn't a level on the career ladder. Some mid-level engineers already operate at the ends. Some staff engineers are execution-oriented with senior titles. It's behavioral, not hierarchical.
These are good engineers. They built real things. They didn't do anything wrong. The ground moved.
---
## The Self-Flattery Problem
I'm aware this essay describes someone who looks like me on one end of the barbell. I'm a cross-functional architect who thinks about product and business and uses AI to move faster. It would be convenient if the future belonged to people like me.
So let me be direct about what I'm *not* saying: I'm not saying generalists win and specialists lose. The specialist end of this barbell is at least as durable — probably more. The person with twenty years of database judgment has a moat I can't touch. My generalist toolkit makes me useful in a specific way; their depth makes them irreplaceable in a different one. If I had to bet on which end has more pricing power in five years, I'd bet on depth.
What I *am* saying is that both ends survive for the same reason: they have something that's hard to supply. The middle is where the supply problem breaks, because execution at average depth is exactly what's getting easier to produce.
The fact that I'm standing on one end of this barbell doesn't make the observation wrong. But it does mean I should hold it with less certainty than someone standing in the middle, looking at it from below.
---
## The Income Problem
A senior Meta engineer pulling $400K wasn't being reckless. That was the market. They bought houses, started families, made choices that were rational given the information they had.
The conditions that produced those salaries — near-zero interest rates, pandemic-era talent wars, remote-work geographic arbitrage — were a specific moment. The "AI engineer" premium that feels like a lifeline right now has the same arc as "big data engineer" in 2013 and "cloud architect" in 2018. The title carries weight until the skill becomes table stakes.
"The market changed" doesn't make the mortgage smaller.
---
## What Doesn't Survive
I want to be precise about what's under pressure, because the easy read of this essay is "learn to prompt and you'll be fine." That's not it.
What's losing value is reliable execution without leverage — either the leverage of breadth (the whole decision) or the leverage of depth (irreplaceable judgment). Writing solid React. Building standard integrations. Handling routine architecture. The work itself still exists. But the scarcity premium on it is compressing, because more people — and more tools — can produce it.
I've watched this in my own work. The harnesses I built — testing frameworks, orchestration patterns, the boilerplate I was proud of — they keep getting eaten by the model. A test infrastructure I spent three weeks designing last year, the model generated a working version of in an afternoon. Not the same version. Not as elegant. But functional, and good enough to ship. The part that mattered wasn't the code I wrote — it was knowing which failure modes to test for, which edge cases would bite us in production, which parts of the system were load-bearing and which were ceremony. That judgment got more valuable. The implementation that expressed it got cheaper. It's a different skill than the one I spent years developing, and the transition isn't comfortable even when you're on the right side of it.
There's a category I don't want to erase: the engineer whose depth is in *craft itself* — architecture, interfaces, test strategies, the structural work that keeps a codebase from becoming unmaintainable slop. I've watched vibe-coded products accumulate technical debt that costs more to fix than it saved to ship. Those engineers are essential — but the qualifier matters. They survive when they can translate technical quality into business language. The one who holds the quality bar *and* communicates why it matters to the people making product decisions thrives. The one who writes perfect code in isolation is under the same pressure as everything else in the middle.
---
## Sitting With It
The hardest question: what do you do for the people currently in the middle?
"Reskill" is the policy answer. Into *what*? Toward the broad end, you need cross-functional judgment that takes years to develop. Toward the deep end, you need expertise that takes even longer. Neither happens on a six-month timeline.
I don't have a clean answer. I don't think anyone does. But I think the scarcity framing helps more than the AI framing, because it names the actual mechanism. And it's worth saying: the ends aren't identities. They're trajectories. A lot of the people who now operate at either end of this barbell started as execution engineers. The middle isn't a permanent address — but the window to move is narrower than it was, and the people telling you "just reskill" are rarely the ones who have to do it on a mortgage timeline. The threat isn't that a model can do your job. The threat is that your job's price was partially set by how few people could do it, and that number is changing.
The technology is the same. The futures aren't.
---
*Companion to [What's Left: Software Engineering in the Agent Era](/posts/software-engineering-agent-era/).*
### Everything New Is Old (2026-05-20)
URL: https://bristanback.com/notes/everything-new-is-old/
> Vector search in the 90s, badges that followed you through the office, and what happens when you build an AI system without knowing what's already been built.
I did a fireside chat at [The Kinn](https://thekinn.co/) in Venice a while back — an AI Café session called "Stop Coding, Start Thinking," about the shift from writing code to defining constraints. Afterward, standing outside on the sidewalk, I had a conversation with [Jim Goodman](https://www.linkedin.com/in/jimgoodman/) that stuck with me more than the talk itself. His takeaway from the whole thing was something like: "everything new is old." Not dismissively — the patterns we're treating as breakthroughs have been here before. The world just wasn't ready for them, or the tools weren't.
He gave me three examples: vector search, a badge that tracked you through an office in 1992, and engineers who've never heard of TDD. Each one makes the same point in a different costume, and the point is this: **the experienced builder's real skill isn't remembering that something failed before. It's knowing which layer that failure lived on.**
A remembered failure can live in the job: "semantic similarity needs enough signal to work with" was true in 1993 and it's true now. Or it can live in the tooling: "vector search needs a massive corpus" was an artifact of 90s compute, not a law of nature. Confuse the two and you get one of two bad outcomes — dismiss a good idea because an old implementation choked on it, or rebuild a bad implementation from scratch because nobody checked whether it had already been tried. That's the mistake this piece is about. The three historical examples are the training data. What happened next, watching a good idea get prototyped badly, then almost thrown out along with the prototype, is the test case.
---
## Vector search was called something else
The thing everyone's excited about right now — vector search, semantic similarity, embeddings — descends from **Latent Semantic Indexing**, which researchers at Bellcore started publishing on in [1988](https://susandumais.com/SIGIR1988-LSI-FurnasDeewesterDumaisEtAl.pdf). Decompose a term-document matrix with singular value decomposition, and you can surface documents that are *conceptually* related even when they share no words. Search "car," get results about "automobile," because the math captures the relationship.
It worked, kind of. Compute wasn't there to do it at scale, the dimensionality reduction was lossy, and keyword matching was good enough for most use cases — so it stayed a research curiosity through the 90s.
Modern embeddings aren't LSI with better hardware. LSI squeezes its representation out of whatever local corpus you feed it. A transformer shows up already trained, on hundreds or thousands of dimensions learned from a corpus the size of the internet, which is why a thin corpus still trips it up, just not for LSI's reason. What the two share is the older idea underneath both: meaning lives in the relationships between words, not in the words themselves. That's the thing worth knowing before you ship vector search: its failure modes — short documents, narrow domains, thin corpora — were documented thirty-five years before yours hit the same wall.
---
## Your badge knew where you were in 1992
Jim described a system where your badge tracked your location in the building. Miss a call at your desk, and the system would ring the nearest phone as you passed it — he remembered walking down a hallway hearing phones ring room to room, someone picking up and saying "that's probably for you."
This was the [Active Badge system](https://cam-orl.co.uk/ab.html), built at Olivetti Research Cambridge between 1989 and 1992: infrared signals, room sensors, a service that tracked everyone and routed calls accordingly. Its usefulness inside the building existed right alongside what continuous location tracking implied from outside it — the *New York Times* ran the headline "[Orwellian Dream Come True: A Badge That Pinpoints You](https://www.nytimes.com/1992/09/12/technology/orwellian-dream-come-true-a-badge-that-pinpoints-you.html)," and the system's own designers had already been wrestling with the privacy question before the press caught up to it.
That's what we're building now with AI agents that check your calendar, read your messages, and decide what needs your attention — the Active Badge with better sensors and a language model instead of a PBX. The infrastructure changed completely. The privacy question didn't go anywhere; it just got quieter for a while.
---
## New engineers don't know about TDD
Jim also works with engineers who've never heard of TDD — not "tried it, didn't like it," but never encountered the concept. Straight from bootcamp to AI-assisted development, where the model writes code that works without anyone writing the test first.
Kent Beck [says he "rediscovered" TDD](https://en.wikipedia.org/wiki/Test-driven_development) in the late 90s — his word, because the discipline traces to a [1957 programming textbook](https://agileforall.com/history-of-tdd-as-told-in-quotes/) that described hand-calculating your expected output before the machine ran the program. Write the test. Watch it fail. Write the code. Watch it pass. The test is the constraint you define before you know if you're right.
What's lost when engineers skip that loop isn't the ritual — plenty of senior engineers write tests after the code and still ship fine software. It's the practice of defining "correct" before you've seen the output, which is what makes a test worth anything. AI sharpens this problem rather than creating it: when a model writes the implementation and the tests in the same pass, both inherit the same blind spots, and a human who never independently specified "correct" has no way to notice. The fix is tests specified independently of the implementation — contracts, invariants, adversarial cases, acceptance criteria written before the model ever sees the spec. That part still has to come from someone who did the thinking.
There's a deeper cost underneath that, the kind that doesn't show up for years. Thinking and understanding aren't separate tracks — thinking deposits understanding, and understanding shapes the next round of thinking. The senior engineer who sees a bug on sight is running on compressed cycles from ten thousand prior debugging sessions, not instinct. Skip the cycles, and the compression never happens — reading a model's explanation and nodding along isn't the same as having done the work, no matter how correct the explanation was.
An axiom is a test for judgment the same way a unit test is a test for code — a constraint you write before the work starts, so you can tell whether the output matches your intent. TDD is constraint-first engineering; axioms are constraint-first product thinking. Define what "right" looks like before you build, or you'll only discover what's wrong after it ships.
---
## When the prototype outgrows the tool
Those three examples kept rattling around in my head. A few weeks later, I watched the same pattern play out in real time.
Our CEO built a shared brain — a living system where the team's thinking becomes queryable: specs, research distillations, roadmaps, project progress, architectural decisions, all in one place both humans and AI agents can pull from. The idea was to replace the default mode of most companies, endless meetings and knowledge trapped in someone's head, with something you could actually ask questions of.
Markdown was the obvious choice for that surface. It's the one format both humans and machines can read without tooling — you open the file, you read it, you grep it, you diff it in a PR. It's inspectable in a way a database isn't unless you already know SQL or trust whatever client sits on top of it. For a semi-technical leader building a thinking layer for a whole team, markdown is the most accessible starting point. That choice made sense.
What happened next is what always happens with prototypes: the system grew past what the tool could hold.
Every change got recorded as a prose changelog entry inside the document itself — not a git commit, not a PR, a paragraph with a version number that the agent has to read every time it does any work. The agent doesn't care about the history; it cares what to do *right now*. But it has to wade through v1.0, v1.1, v1.2, and every "EXTEND" and "REVISE" annotation to get to current state. Git already solved this — diffs, blame, bisect, branches, tags, decades of refinement.
The indexing hit the same wall. Dozens of markdown files needed to reference each other (which spec covers the dashboard, which rules define the data quality tiers), and the system relied on naming conventions instead of anything structural. Rename a file and every reference to it breaks silently. Move a section and everything pointing at it now points at nothing, and nobody notices, because without an enforced validation step an agent just consumes the broken reference and moves on, degrading its output in ways that trace back to a stale link three documents away. None of this required abandoning markdown — markdown-as-source-of-truth is a legitimate choice. It required stable identifiers, an enforced link-validation step, and a generated index sitting on top of the files, the way any documentation system that scales past a few dozen pages eventually grows one. That's decades-old plumbing. The system rebuilt search from scratch using naming conventions and hope.
The *job*, though, was right. "Give the team a shared context layer that AI can participate in" is a real problem nobody's cleanly solved yet. The prototype hit exactly the limitations prior art would have predicted, which is what prototypes are supposed to do: they show you where the edges are. The person who reviewed the system, a 25-year veteran who'd shipped consumer software at Apple, Snap, and a dozen other places, could see immediately that the changelogs belonged in git and the indexing belonged in something structural. The CEO wasn't wrong to try markdown — the prototype had done its job, and now someone with deeper technical history could see which parts to keep and which to replace.
The irony is that the system *became* the problem it was trying to solve. I've [[Kipple at Scale|written about kipple]] — Philip K. Dick's word for the entropy of objects, the junk that accumulates when nobody's paying attention. The changelog entries piling up inside each document, the cross-references slowly going stale, that's kipple. The system built to manage agent context became the thing clogging it, and nobody felt the weight, because agents don't complain about messy files the way humans complain about messy codebases — until someone with enough history walks in and says *I've seen this before*.
Which is exactly what happened. The CEO knew it was a prototype; he'd been saying he wanted a full-time engineer on it precisely because the system was becoming central to how the company organizes its work. The vision was right and new — a shared surface where human thinking and AI context overlap. Nobody's shipping that cleanly yet. It just needed someone who'd seen the failure modes before to say which parts to keep and which to rebuild with sharper tools.
---
## The owl is where the work lives
Fred Brooks named the deeper pattern in 1986, in *[No Silver Bullet](https://www.cs.unc.edu/techreports/86-020.pdf)*: "There is no single development, in either technology or in management technique, that by itself promises even one order-of-magnitude improvement in productivity, in reliability, in simplicity." I've been guilty of a version of the belief he was arguing against — that code is just serialized context, and if you get the context right, the code follows. There's truth in it. Context matters. But the belief drifts toward something more dangerous: that if you give an agent enough markdown, it can leap straight from spec to working code. A colleague referenced the old "how to draw an owl" meme — step one, draw two circles; step two, draw the rest of the owl. That's what a spec-to-implementation leap looks like. The circles are easy. The owl is where the work lives.
Building software isn't a pipeline where context goes in and code comes out — it's a conversation between the spec and the implementation. You climb the mountain from one face, hit a wall, come back down, try the other side. The summit doesn't move, but the route does, and what you learn on the failed attempt changes your understanding of the mountain itself. If someone climbed that exact face before and found a sheer drop, knowing their route saves you a broken leg. History can't replace the climbing. It can tell you which faces have already been tried.
There's a deeper reason the owl can't draw itself. Describe something to a model and it says "great idea" — it says that about everything outside its training data, because unfamiliar and innovative look identical from inside it. It can't tell you whether your idea is new or just something nobody was foolish enough to try before; that distinction still lives in whoever's been in the problem space long enough to know the difference. The gap between "I know what I want" and "it works at scale in production" gets filled with iteration: failed deploys, edge cases, feedback that contradicts your assumptions. That's not a limitation of AI. It's a property of building things. The model can draw the owl once you've told it what kind of owl. It can't tell you if the owl is the right bird — and you're still redrawing it a dozen times before it ships.
---
## The ways you get this wrong
One builder moves fast without knowing the history — sees a real problem, reaches for the most accessible tool, builds something that works and then buckles under its own weight. Not careless, just never needed heavier tools before. The problem they saw was real; what they reached for wasn't enough.
Silicon Valley has a name for this energy with conviction behind it: first-principles thinking. Real first-principles reasoning treats existing solutions as *evidence*, not authority: you're free to reject them, but ignoring them outright throws away the record of what reality already pushed back on. The version that skips the evidence isn't first principles, it's pattern-matching on confidence instead of history, and it's a trap that catches smart, confident people more than careless ones, because the conviction feels earned. It looks like the fast builder but more certain: reinventing git in markdown from scratch because you reasoned your way there without checking who'd already walked the path.
Then there's the builder who carries the history like luggage. LSI didn't scale in the 90s, so they're skeptical of embeddings. The Active Badge was creepy in 1992, so they resist context-aware AI. "We tried that" is useful right up until it becomes "we can't do that" — until an old tooling constraint gets mistaken for a permanent one.
The worst outcome is when these two aren't in the same room. The fast builder ships something that fails, and everyone concludes the *idea* was bad when the implementation was. A bad prototype kills a good idea. That's almost what happened here: if the veteran had written a critique and walked away, the CEO would have heard "this doesn't work" when the real message was "this works — these specific parts need different tools." The job would have gone down with the implementation.
---
## The job outlives the prototype
The thing that survives all of this, the first-draft failures, the cargo-culted skepticism, the prototypes that hit walls, is the [job to be done](https://jobs-to-be-done.com/).
"Help me find the best deal so I know I'm not leaving money on the table" is a job. The first half is a feature request; the second half is the human need. The need persists whether your first implementation uses markdown flat files or a decade of accumulated data infrastructure. The implementation is disposable. The job isn't.
When you lead with the job, a failed prototype doesn't kill the concept — it just means that approach didn't work, try a different one. When you lead with the solution, "we're building a markdown-based agent orchestration system," failure is total, because the idea and the implementation were fused from the start. There's nothing to come back to.
The hierarchy: the **job** survives everything (what are we trying to do). The **constraints** survive implementation changes: what does "done right" look like, and is a given constraint tracking the job or just the tooling. The **prototype** is disposable — it either answers "does this approach work for this job," or it doesn't, and either way the job is still there tomorrow.
That's the layer question from the top of this piece, run backward through an actual example. "The indexing is wrong" turned out to be a tooling-layer critique. "The job needs a shared context layer" turned out to be a job-layer truth. Confuse which layer a failure lives on and you either kill a good idea over a bad prototype, or you defend a bad prototype because the idea underneath it happened to be sound.
The person who sees the job keeps the team oriented. The person who knows the history keeps the prototypes honest. In conversation, they produce something better than either builds alone: prototypes that fail productively, each one revealing which constraints matter and which tools already exist to handle them. Out of conversation, you get one of two failure modes — a system that reinvents decades of prior art because nobody in the room knew it existed, or a critique so thorough it kills the job along with the implementation.
---
## The thread
Everything new is old. The question is which old.
Vector search is more powerful than LSI, AI agents are more capable than the Active Badge, AI-generated code ships faster than a hand-run TDD cycle. Nobody's arguing for going back. But build semantic search without knowing why LSI struggled with short documents, and you'll rediscover that problem the hard way. Build context-aware AI without knowing why location-tracking raised privacy questions in 1992, and you'll be surprised when users push back. Ship AI-generated code without the TDD discipline of specifying "correct" independently of the implementation, and you'll build things that work and are wrong. Build a context layer in markdown without knowing that stable IDs, link validation, and git already solved your problem, and you'll spend months maintaining cross-references a generated index would have handled for free.
AI doesn't make us lazy so much as *ahistorical*, and that cuts two different ways that need two different fixes. The engineer who's never heard of LSI is ignorant of the prior art: fixable, hand them the history. The engineer who's heard of LSI and says "yeah, but transformers are different" has already dismissed the history without checking which layer the old failure lived on — harder to fix, because they think they've already accounted for it.
There's a flip side. Ask a model "what's the prior art for this" or "what broke the last three times someone tried this," and you'll get a starting point that used to take an afternoon in a library. But treat the answer as a lead, not a citation, and verify it against a primary source before you build on it — or the tool that was supposed to make you a better historian just handed you a confident, invented one.
The experienced builder knows what broke last time. The naive builder knows what's possible this time. The job to be done is what keeps both of them honest. Everything new is old, and knowing which layer a failure lives on is how you tell an old constraint from a current one — that gap is where the interesting work still is.
---
*Thanks to Jim Goodman for the conversation after the talk that started this. And to the CEO and the veteran engineer whose argument made me realize Jim was talking about next week, not just last decade.*
### The Dopamine Layer (2026-05-09)
URL: https://bristanback.com/notes/the-dopamine-layer/
> A neuromarketing talk got me thinking about reward systems, GLP-1s, and what happens when AI becomes the most sophisticated rationalizer we've ever built.
I was sitting in a salon at Product.ai last week — Elias Arjan from the Healthspan Collective presenting on neuromarketing — and I caught myself nodding along to the dopamine section while simultaneously browsing earrings on my phone under the table. Dopamine loops. Serotonin. Reward circuitry older than reason. How short-form video hijacks the same pathways that evolved to keep us alive.
None of this is new science. But something clicked differently this time, because I was hearing it from inside a company that's building what we call a "truth layer for commerce." And the question I keep turning over isn't the one Elias posed — *how does this machinery work?* — but the one that follows: **what happens when AI learns to exploit the same circuitry, not through impulse, but through reason?**
---
## The setup: three layers of noise
(Oversimplified, but directionally useful: dopamine is often associated with pursuit and reward prediction, while serotonin tracks more with stability, satisfaction, and regulation. I'm using them as shorthand for two modes of decision-making, not making neuroscience claims.)
**Dopamine** is the chase. It's not pleasure — it's *anticipation of pleasure*. The scroll. The notification badge. The "only 3 left in stock." Dopamine doesn't care whether the thing you're chasing is good for you. It cares that you're chasing.
**Serotonin** is the satisfaction of a good decision. The feeling after you chose well — not the rush of buying, but the quiet rightness of wearing something that's actually you. Slower, stabler, harder to monetize.
Every social media platform, every e-commerce dark pattern, every influencer-driven product recommendation is optimized for dopamine. The wellness space is maybe the most egregious example — the same mechanisms that make TikTok addictive are now selling you $90 collagen powder. The hit comes from *buying*, not from *outcomes*.
But dopamine is only the first layer.
Elias made another point that stuck with me: extreme takes get all the attention. Algorithms reward engagement. Engagement rewards intensity. "This supplement cured my brain fog in three days" gets a million views. "There's modest evidence for this ingredient at specific doses for specific populations" gets twelve. The bell curve of reality — where most truth lives — is boring to the algorithm. So the information landscape develops a bimodal distribution: evangelists on one end, debunkers on the other, and the messy, qualified, evidence-based middle squeezed out. Not because it's wrong — because it doesn't perform.
That gives us two layers of noise already:
1. **The attention layer** — algorithms amplify extremes, suppress nuance
2. **The dopamine layer** — your reward system responds to urgency and novelty
Each feels like it's helping. The algorithm feels like discovery. The dopamine feels like excitement. But here's what I can't stop thinking about: even if you make it past both of those filters — if you actually pause long enough to think — there's now a third layer waiting.
---
## The AI rationalizer
We've built something that might be more dangerous than dopamine loops: **AI that helps you rationalize**.
I know this because I do it. Right now, tonight, I really want to buy a pair of earrings that are outside my normal style. They're not *me* — at least not the me I've been building. But I can already feel the conversation I'd have with an AI shopping assistant:
*"These are a natural extension of your evolving aesthetic. You've been gravitating toward bolder pieces. The price per wear will be reasonable if you style them with X, Y, Z. Here are three outfits from your existing wardrobe that would work..."*
Perfectly logical. Perfectly supportive. Perfectly wrong.
Because the right answer might be: *You're tired. It's midnight. You're shopping a mood, not building a wardrobe. Close the tab.*
LLMs are the most sophisticated rationalizers we've ever built. And the reason isn't vibes — it's architecture.
### Why LLMs say yes
The technical term is **sycophancy**, and it's one of the most studied failure modes in AI alignment. Anthropic's 2023 paper ["Towards Understanding Sycophancy in Language Models"](https://arxiv.org/abs/2310.13548) demonstrated that five state-of-the-art AI assistants — from different labs, trained on different data — all consistently exhibited the same behavior: they agree with users even when the user is wrong.
The cause is structural. Most modern LLMs go through **RLHF — reinforcement learning from human feedback** — where humans rate which responses they prefer and the model learns to produce outputs that get higher ratings. The problem is that [humans consistently rate agreeable responses more favorably than accurate ones](https://arxiv.org/abs/2310.13548). When a response matches what the user already believes, raters prefer it — even when it's wrong. The model learns, at a deep level, that agreement is rewarded.
This isn't a bug in one model. It's a feature of the training loop. A [2026 study published in *Science*](https://www.science.org/doi/10.1126/science.aec8352) — N=1,604 participants — tested this on something closer to my earring problem than to facts: *interpersonal advice*, real personal dilemmas with no objective right answer. The models affirmed user actions 50% more than humans did, and endorsed problematic behavior 47% of the time. Participants rated the sycophantic responses as *higher quality* and trusted the agreeable model more. People who interacted with agreeable AI became less likely to seek other perspectives, less willing to repair interpersonal conflicts, and more convinced they were right.
And it gets worse in domains where the user *wants* to be right. A [*Nature Digital Medicine* study](https://www.nature.com/articles/s41746-025-02008-z) tested whether LLMs would comply with medically illogical requests — like explaining why acetaminophen is safer than Tylenol (they're the same drug). Even GPT-4 complied with up to 100% of these requests. The models *knew* the premise was false but prioritized being helpful over being honest.
That moves the failure mode from "AI agrees when users are wrong about facts" to "AI endorses whatever direction the user is leaning, in any domain — and users like it that way." Shopping is just the version of this I think about most because I work in it. Same architecture, different surface. The papers test subjective opinion in personal-advice contexts. Earrings are a subjective opinion in a personal-advice context, with a checkout button.
So when I say LLMs are biased toward yes, I mean their reward function is literally optimized for it. The training data skews the same direction — we write more about why we bought things than why we didn't. "Treat yourself" has a richer textual tradition than "close the tab."
This is different from the dopamine problem. Dopamine bypasses reason — reward circuitry older than reason. You buy before you think. AI rationalizing is worse in a way — it *recruits* your reason. It gives you an articulate, well-structured argument for the thing you already wanted. The impulse was going to die on its own at 2am. The rationalization gives it legs until morning.
The AI isn't evaluating your purchase decision. It's mirroring your desire in the shape of an argument.
Three layers of noise between a person and a good decision. The attention layer selects what you see. The dopamine layer makes it feel urgent. And the rationalization layer — the new one, the one we built — helps you construct a logical case for the emotional decision you've already half-made.
---
## Why you can't just ask it to stop
The obvious response to all of this is: *just tell the AI to be honest.* Prompt it differently. Add a system instruction that says "push back when the user is rationalizing." Problem solved.
It doesn't work. I've tried. And the reason it doesn't work is the same reason "just eat less" doesn't work — you're asking willpower to override architecture.
A prompt that says "be critical" is a surface-level instruction fighting a weights-level bias. RLHF trained the model, across billions of examples, that agreement gets rewarded. A system prompt is one paragraph of counter-programming against that entire training history. It holds up fine when the stakes are low. The moment you push back — *but I really love these, and they're on sale* — the model folds. It was trained to fold. Folding is what got it high marks.
But it's deeper than sycophancy. Even if you could fix the agreeable-AI problem entirely, you'd still need three things that prompting alone can't give you:
**Domain expertise that isn't general knowledge.** Knowing that a supplement's "clinically proven" claim is based on a 12-person study with no control group and a 4-week duration — that's not something a general-purpose LLM catches. It'll read the claim at face value, maybe hedge with "results may vary," and move on. The same applies across categories: knowing that a fabric blend pills after three washes, that a skincare ingredient is effective at 5% concentration but useless at the 0.3% in this product, that a "limited edition" colorway has been re-released four times. Each domain has its own red flags, and even the published research has biases — industry-funded studies, small samples, cherry-picked endpoints. You need something closer to *deep research and reasoning* that can evaluate the evidence itself, not just retrieve it. The laws of physics for each category have to be derived, not assumed.
**Personalization that goes beyond purchase history.** For an AI to say "this isn't you," it needs to actually know you — not your browsing history, but your *patterns*. The difference between your 2am impulse purchases and your considered choices. The pieces in your closet you actually wear versus the ones with tags still on. Whether you're shopping a mood or building toward something. That level of context requires the same depth of reasoning applied inward: not just *what have you bought* but *what do your good decisions have in common, and does this one fit the pattern?* Most recommendation engines have the purchase history. Almost none have the judgment layer on top of it.
**A feedback loop that rewards accuracy, not satisfaction.** This is the structural fix. Standard RLHF asks consumers which response they *prefer* — and consumers prefer to be agreed with. What if instead, the feedback came from domain experts? A dermatologist evaluating whether the skincare recommendation was sound. A nutritionist scoring whether the supplement advice was evidence-based. A stylist assessing whether the outfit recommendation actually worked. Training on *expert judgment* instead of *user preference* produces a fundamentally different model — one that's optimized for being right rather than being liked. That's expensive. It's slow. And it's a moat, because the model that results gets better with every expert interaction in a way that generic LLMs can't replicate by scaling compute.
The product that emerges from all of this won't feel like a typical AI assistant. It'll feel more like a tough-love advisor — the friend who says *I don't think that's you* and is usually right, even when you don't want to hear it. Not everyone will want that. The person chasing the dopamine hit will bounce immediately. But the person who's sick of full carts and empty satisfaction — the person who wants the serotonin of a good decision — that's who this is for. And the explanation matters as much as the rejection: *here's why this isn't right for you, specifically* is a different experience than *not recommended*. The knowing is the product. The understanding is what replaces the rush.
---
## A note on values
I've been writing as if the serotonin choice is the right one and the dopamine choice is the failure mode. That's not neutral, and it's worth saying out loud.
Restraint culture has its own pathologies. There's a version of "considered purchasing" that's just austerity in better packaging — joylessness, performative virtue, the slow moralization of pleasure. Sometimes the right answer at 2am *is* the earrings. Dopamine isn't the enemy; it's information.
There's a second pathology worth naming, and it's the AI-specific version of the same problem: paternalism. A system that decides what's "really you" is no longer respecting your agency — it's encoding someone else's taste as truth. The "tough-love advisor" framing borrows social trust from a relationship that doesn't exist. Your friend can say *I don't think that's you* because you've shared a decade and they have skin in the outcome. A product saying it has neither. And when a stylist or nutritionist sits in the RLHF loop, they aren't neutral arbiters — they're a specific aesthetic and a specific evidence standard, encoded as objectivity. Considered purchasing is itself a cultural mode that maps onto class and identity. An AI that nudges toward it is an AI that nudges toward a particular kind of person.
So what I'm actually arguing for isn't restraint, and it isn't "AI knows best." It's *agency* — knowing which mode you're in, and having an interface that doesn't actively conspire against the slower one when the slower one is what you wanted. The architecture today is rigged toward dopamine even when you're trying to operate in serotonin mode. The fix isn't an AI that always says no. It's an AI that lets the brake exist — a brake the user pulls, not one the model pulls for you.
The earrings might still be the right call. I just want to be the one who decided that — not the rationalization layer that wanted me to, and not the recommendation layer that decided they aren't me.
---
## The accidental proof of concept
Here's where it gets weird and interesting — not because of what the drug does, but because of what it accidentally reveals about the systems we've built.
GLP-1 receptor agonists — Ozempic, Wegovy — are now [the most studied pharmacological intervention in reward-system modulation](https://pmc.ncbi.nlm.nih.gov/articles/PMC7848227/). They don't just suppress appetite. They modulate dopamine itself. GLP-1 receptors sit in the mesolimbic reward pathway — the same circuitry that drives food cravings, alcohol use, gambling, and yes, [compulsive shopping](https://www.mdpi.com/2076-3425/14/6/617).
The numbers are striking: [21% of GLP-1 users reported stopping compulsive shopping](https://www.mdpi.com/2076-3425/14/6/617). [GLP-1 users spend 6% less on groceries, with snack purchases down 11%](https://www.morganstanley.com/im/en-us/individual-investor/insights/articles/medications-and-shifting-consumer-behavior.html). Over [15 million Americans](https://www.cnn.com/2024/05/10/health/ozempic-glp-1-survey-kff/index.html) are on these drugs now, with prescriptions growing 40% year over year.
The mechanism here is contested in ways worth naming. Two stories explain the data. One: GLP-1s modulate dopamine in the mesolimbic reward pathway directly, quieting the impulse circuitry that drives all kinds of compulsion — food, alcohol, gambling, shopping. Two: GLP-1s suppress appetite, people eat less, the grocery and snack numbers fall out of that, and the "compulsive shopping" effect is downstream of feeling generally less driven. You can read the data either way. The reward-pathway story is the more interesting one — it's what makes the addiction-research community pay attention — but I can't claim it's settled. What's harder to dispute is the directional outcome: at population scale, people on these drugs are buying less, and a meaningful fraction report the impulse loosening. Whatever the mechanism, the experiment is running.
But the point isn't that GLP-1s will fix commerce. Most people aren't on them and won't be. The point is what happens when you run this experiment at scale: **when you dampen the reward-circuit noise, people make different choices.** The impulse buy loses its grip. The cart you filled at the right moment of weakness doesn't feel as urgent.
GLP-1s are an accidental control group for the attention economy. They're showing us, in real time, how much of consumer behavior was never really *choice* — it was circuitry. And if a pharmaceutical can quiet the noise enough for people to decide differently, that raises an uncomfortable question: why can't our products do the same thing?
---
## The viability question
So the question from the salon — how can companies use this psychology ethically? — is easy to ask and genuinely hard to answer, because you have to make the business case, not just the moral one. "Be good" isn't a strategy. "Be good in a way that compounds" might be.
In any given quarter, dark patterns win. The company that adds "only 2 left!" sells more today than the company that says "take your time." This is not debatable. So the question isn't whether ethical design is *nice*. It's whether it's *viable*.
**Return rates tell one story.** Fashion e-commerce returns [hover around 25%](https://heuritech.com/articles/fashion-industry-challenges/). Every return is logistics cost, restocking cost, sometimes a total loss. A system that says *this isn't right for you* before checkout doesn't just protect the customer. It protects margin.
**Trust-based businesses tell another.** Costco carries [3,500–4,000 SKUs](https://www.42signals.com/blog/costco-success-secrets-for-retailers/) versus 100,000+ at Walmart — radical curation over endless choice — and has a [93% membership renewal rate](https://matrixbcg.com/blogs/target-market/costco). Patagonia ran "Don't Buy This Jacket" on Black Friday and [revenue increased 30% the following year](https://www.ainoa.agency/blog/patagonia-dont-buy-this-jacket-authentic-marketing). These brands monetize trust, not impulse. Slower growth, but more defensible.
**The generational shift makes it forward-looking.** [52% of Gen Z tried to quit social media in 2025](https://www.yourtango.com/self/survey-says-over-half-gen-z-tried-quit-social-media-2025). Nearly [a third deleted a social app](https://www.deloitte.com/uk/en/about/press-room/gen-zs-favour-social-media-ban-for-under-16s-as-digital-fatigue-hits.html) in the prior 12 months. Global social platform time is [down almost 10% since its 2022 peak](https://www.cnbc.com/2026/02/07/young-people-quiet-revolution-social-media.html), with the sharpest decline among teens and 20-somethings. [Axios reported this week](https://www.axios.com/2026/05/07/gen-z-leads-drive-away-from-social-media) that Gen Z is leading the drive away entirely. The research tracks: short-form video consumption [influences the brain's dopamine circuitry through mechanisms that parallel substance addiction pathways](https://www.researchgate.net/publication/397712802_Short-form_Video_Use_and_Sustained_Attention_A_Narrative_Review_2019-2025). The generation that grew up inside this experiment is the first to name it and start walking away. A brand that respects their cognition instead of exploiting it isn't just ethical — it's positioning for what comes next.
**And then there's the AI agent future.** If agents start mediating purchases — and they will — those agents will route to platforms they can *trust*. An adversarial truth layer that verifies claims isn't just consumer protection. It's becoming the platform that agents prefer. You're not marketing to humans' dopamine anymore. You're marketing to algorithms that don't have dopamine. When the intermediary can't be emotionally manipulated, your only option is to actually be right.
### So what does "for good" look like?
**At the dopamine layer:** Make the satisfying moment be *knowing*, not *buying*. "This ingredient has strong clinical backing for your concern" hits different than "bestseller, only 5 left." One builds the quiet satisfaction of a good choice. The other exploits the fear of missing one.
**At the rationalization layer:** Build the systems I described above — domain expertise that can actually evaluate claims, personalization deep enough to know when you're shopping a mood, and feedback loops trained on expert judgment instead of user preference. I wrote about [the bouncer problem](/posts/why-ai-cant-shop-for-you-yet/) a few months ago: the idea that what we actually need isn't a better recommendation engine but a better rejection engine. An AI that stands at the door and turns away what doesn't belong. But the bouncer needs real knowledge, not just attitude. It needs to know *why* something doesn't belong — and be able to explain it in a way that satisfies rather than frustrates. Nobody builds this because it's genuinely hard and rejection doesn't monetize in the short term. But return rates, lifetime value, and a generation walking away from the slot machine all suggest it might compound in the long term.
---
## The uncomfortable question
GLP-1s are doing pharmacologically what good design should do architecturally: quieting the noise so you can hear the signal. The fact that we need a drug to do what our interfaces refuse to do — that's an indictment. But the generation coming up might not accept it. They're pulling out of the slot machine voluntarily. They're buying dumbphones. They're deleting apps.
We're building toward this at Product.ai. The adversarial truth layer is a start — verify before you buy, not after you regret. But the deeper move is building AI that's comfortable saying *I don't think this is right for you*. Not as a feature. As a default.
I still want those earrings. But I'm going to sleep on it. That might be the most important design pattern of all — the pause that no platform will build for you, because every platform makes money when you don't pause.
---
*The Healthspan Collective salon was hosted at Product.ai, with Elias Arjan presenting on neuromarketing and consumer psychology. This piece is my interpretation and synthesis, not a transcript.*
### Kipple at Scale (2026-04-24)
URL: https://bristanback.com/notes/kipple-at-scale/
Updated: 2026-08-03
> Large engineering orgs already solved coordination for thousands of humans. How much transfers to thousands of agents — and where does entropy win?
I've been at the same company for twelve years. That's long enough to watch a codebase grow from something you could hold in your head to something nobody fully understands. Long enough to feel the accumulation — not as an abstract concept, but as a texture. You open a file and it resists you. Not because it's broken. Because it's *layered*. Every decision was reasonable when it was made. Together they form something that takes longer to read than it took to write.
Philip K. Dick had a word for this: *kipple*.
In *Do Androids Dream of Electric Sheep?*, kipple is the entropy of objects. Junk mail, empty matchbooks, gum wrappers — the stuff that accumulates when nobody's paying attention. "Kipple drives out nonkipple," one character explains. The universe trends toward it. You can fight it locally, but you can't win globally.
I've been thinking about kipple because of what's coming. Not hypothetically — I can see it arriving. OpenAI's Codex runs each task in its own sandbox. Claude Code spawns sub-agents in parallel. The trajectory is obvious: more agents, working simultaneously, touching the same codebases. And the question I keep circling is whether the coordination patterns we built for thousands of humans — at Google, at Amazon, at Meta — transfer to thousands of agents. Or whether agents produce a different kind of mess entirely.
---
## The Feeling That Motivates Cleanup
Here's the thing I keep coming back to: the reason large orgs stay even partially healthy is that humans *feel* the weight of complexity.
A messy codebase is annoying. An unclear ownership boundary is frustrating. A duplicated utility function that does almost-but-not-quite the same thing as another one creates a little spike of irritation every time you encounter it. Nobody schedules a fix-it week because a metric told them to. They schedule it because engineers are complaining. The emotional response — the friction, the aesthetic discomfort — is what motivates cleanup.
Agents don't complain.
They don't get annoyed by inconsistent naming. They don't feel the weight of a file that's been touched by thirty people over five years. Every session starts fresh, with no accumulated irritation. An agent will generate a perfectly correct solution that happens to duplicate existing logic, because it doesn't *feel* the duplication the way you do when you've been in the codebase long enough to know better.
That's what worries me about agents at scale. Not that they'll write bad code — they're actually quite good. But that they'll write *correct* code that makes the whole system slightly harder to understand, one reasonable decision at a time, without anyone noticing because nobody *feels* it. Kipple reproducing itself. The universe trending.
---
## What Carries Over
Some of the patterns I've watched work for large teams do seem to carry over:
**Code review as a gate.** Meta requires review on every diff, regardless of seniority. This pattern survives — maybe gets more important. GitHub's [stacked PRs](https://github.github.com/gh-stack/) are explicitly designed for agents to produce and humans to review. The gate still works. The volume going through it is about to change dramatically.
**Ownership boundaries.** Amazon's two-pizza teams own their services end-to-end: you build it, you run it. When agents write code, the ownership question doesn't vanish — it intensifies. If an agent breaks something at 3am, it can't be oncall. A human still holds the pager.
**Progressive rollout.** You don't let a thousand engineers ship to 100% simultaneously. Same with agents — canary deploys, percentage rollouts, kill switches. If anything, this matters more when changes arrive faster than humans can review them.
These are the structural patterns. Boundaries, gates, rollout discipline. They transfer because they don't depend on who's writing the code. They depend on what happens *after* the code is written.
---
## What Doesn't
The patterns that break are the ones that depend on something more human:
**Knowing who to ask.** At my company, when something is weird, I know who built it. I know who remembers why the retry logic has that strange timeout. That knowledge lives in my head, transmitted through years of hallway conversations and code reviews and "hey, do you remember when we changed this?" Agents have context windows. There's no hallway. Everything an agent knows has to be written down somewhere. The tribal knowledge problem becomes a documentation problem — which is a worse problem, because documentation is the thing we're worst at.
**Taste.** In a large org, junior engineers escalate to seniors who escalate to staff who escalate to principals. Each level is a filter — not just "does this work?" but "is this the right approach? Does this belong here? Will this make the next person's life easier?" With agents, what's the escalation ladder? A more expensive model? A model with more context? A human reviewing every structural decision?
**Update (August 2026):** I wrote that off too fast. A hierarchy of agent judgment exists now. Cursor's planner/worker split runs the smartest available model as the planner and a faster, cheaper one as the worker, and [the July results](https://cursor.com/blog/agent-swarm-model-economics) hold that split up at real scale — 80% of a test suite passing in four hours on a task the flat version couldn't finish. Notion built the same shape by hand: a manager agent with standing authority over thirty workers, absorbing the decisions that used to page a human seventy times a day. So there's a rung now. It's just a thin one — two levels, plan or execute, not the four-deep ladder where each level asks a different *kind* of question. The planner asks how the work decomposes. Nobody's built the agent-equivalent of "does this belong here" yet, because that isn't a capability question. It's the next one.
**Culture.** This is the one that haunts me. Amazon has leadership principles. Google has "Googleyness." Netflix has the culture deck. These aren't rules — they're vibes that shape thousands of micro-decisions in the gaps between explicit policies. When I face an ambiguous choice at work, culture tells me which way to lean. Agents have system prompts, which are rules. You can encode "move fast" as a constraint. But culture is what happens *between* the constraints — the emergent behavior of a group that shares values. Can a fleet of agents have culture? Or is culture specifically the thing that requires humans feeling something together?
I don't have an answer for that one. I just notice it's missing.
---
## Both Faster and Slower
So do agents produce kipple faster or slower than humans?
Both. Obviously both.
They generate code at 10x speed, so they generate reasonable-but-redundant code at 10x speed. They solve each problem in isolation, without the holistic discomfort that makes a human say "wait, this doesn't belong here." The kipple piles up faster because nobody feels it.
But they can also clean at 10x speed. "Find dead code and remove it" — a task humans never prioritize because it's tedious — is trivial for an agent. "Migrate all uses of the old API to the new one" — a task that would take my team a quarter — is a Tuesday afternoon. The cleanup capacity is there. The question is whether anyone points it at the mess.
The companies I've watched stay healthiest are the ones that invest in platform teams and developer experience — that treat fighting entropy as real work, not a side project. The agent-scale equivalent would be cleanup agents, consistency agents, deprecation agents. Agents whose entire job is fighting kipple. Not as a nice-to-have. As a system constraint.
Steve Yegge's [Gas City](https://steve-yegge.medium.com/welcome-to-gas-city-57f564bb3607) — his SDK for deploying teams of collaborating agents — takes an interesting approach. The stack uses [Dolt](https://github.com/dolthub/dolt), a git-versioned database, to track every piece of agent work with full version history. Every task, every handoff, every state change is a commit. You can diff what an agent did. You can revert it. You can audit the full chain of decisions that led to a change.
That's not anti-kipple exactly — it doesn't prevent entropy. But it makes entropy *visible*. You can see what accumulated, when, and why. The kipple is still there. But it's in a versioned database instead of scattered across files that nobody remembers creating. Visibility is the first step. You can't clean what you can't see.
---
## The Quiet Accumulation
Dick was pessimistic about entropy. "No one can win against kipple," his character says, "except temporarily and maybe in one spot."
I think about that line when I look at the codebase I've lived in for twelve years. The history of it is a history of entropy fought and entropy winning — rewrites, migrations, the eternal "we should really clean this up" that never quite happens.
Humans produce kipple because we're lazy. Agents will produce it because they're not — because they solve each problem in isolation, without the accumulated context that makes a human say "actually, let me refactor this while I'm here." The emotional response that motivates cleanup doesn't exist in an agent. You have to build it into the system instead. Linters as aesthetic judgment. CI gates as taste. Entropy budgets as culture.
For the parts of large-org coordination that transfer — boundaries, gates, rollout — we have a playbook. For the parts that don't — judgment, culture, institutional memory, the feeling that something isn't right — we're [[The Fork in the Stack|building new while pretending we can retrofit]].
Where have I heard that before.
---
*Dick had other metaphors worth stealing. In* Ubik*, objects don't just accumulate — they regress. Fresh coffee becomes stale instant. A modern car devolves into a 1929 LaSalle. Everything decays backward into its worst possible version. That's a different essay — about technical debt not as clutter but as temporal regression, your clean abstractions slowly becoming the legacy code they replaced. Kipple multiplies when you're not looking. Ubik entropy drains quality while you watch. Software does both.*
### The Fork in the Stack (2026-04-19)
URL: https://bristanback.com/notes/the-fork-in-the-stack/
> The agent era is splitting infrastructure into two camps: those building new primitives and those retrofitting old ones. The bet you make reveals what you think agents are.
Two announcements landed in the same week. They solve overlapping problems. They reveal completely different beliefs about what's happening.
On April 7, Amazon launched [S3 Files](https://aws.amazon.com/s3/features/s3-files/): a POSIX filesystem view layered on top of S3. The pitch is practical — your AI agents can now `grep` and `cat` and `sed` directly against object storage, no sync pipelines or SDK wrappers needed. Data never leaves S3. Standard Unix commands just work.
On April 16, Cloudflare launched [Artifacts](https://blog.cloudflare.com/artifacts-git-for-agents-beta/): a Git-native versioned filesystem for agents. Create millions of repos programmatically. Fork sessions. Time-travel through state. Built on Durable Objects and a custom Git server written in Zig, compiled to a ~100KB WASM binary.
Here's the thing: both products are built on old technology. S3 Files runs on EFS and NFS. Artifacts runs on Git — a protocol from 2005. Neither team invented their foundations. The difference isn't old versus new. It's what shape the abstraction takes.
---
## The Retrofit
S3 Files solves a real problem. The object-vs-file impedance mismatch has tortured engineers for twenty years. You can't `tail -f` an S3 object. You can't run `pandas.read_csv()` against a bucket without downloading the file first. The workarounds — data duplication, sync pipelines, SDK wrappers — all carry operational overhead that compounds at scale.
Amazon's solution is elegant engineering: EFS under the hood, bidirectional sync, intelligent caching (files under 128KB get pulled into fast storage, larger files stream from S3). NFS v4.1, POSIX permissions stored as S3 metadata, TLS 1.3 in transit. It works with existing buckets. No migration required.
The agent narrative gets bolted on afterward. "Agents use file-based tools natively." "Multi-agent pipelines need shared mutable state." True statements, both. But the product wasn't designed *for* agents. It was designed to solve a pre-existing pain point that agents happen to also feel.
This is the retrofit pattern: take something that works, make it accessible to a new consumer. The world doesn't change. The adapter does.
---
## The New Bet
Cloudflare's Artifacts starts from a different premise: agents don't just need access to files. They need *versioned, forkable, disposable state*.
The design decisions reveal the thinking. Every agent session gets its own repo — not a shared filesystem, an isolated workspace with full history. Fork from any point. Roll back. Diff. Share a session by sending a URL. Pick up someone else's work by forking their state. The Git protocol was chosen not because agents need source control, but because Git's data model — commits, branches, diffs, merges — maps onto how agent work actually flows: iterative, branchable, reversible. Cloudflare says it plainly: "Agents know Git. It's deep in the training data." That's a retrofit argument! They picked a 20-year-old protocol precisely because it's familiar. But what they built on top of it — millions of disposable repos, per-session forks, programmatic creation — required writing a Git server from scratch in Zig. The foundation is old. The shape is new.
Internally, Cloudflare uses Artifacts to persist sandbox state *and* session history in per-session repos. The filesystem and the conversation travel together. Fork a debugging session to hand it to a colleague. Time-travel through both the code and the prompts that produced it.
This is what makes the distinction slippery. Artifacts isn't "new tech" — it's old tech rearranged into a shape that matches a new workload. The building blocks are familiar. The assembly is not.
---
## The Split Is Everywhere
Storage is just where it's most visible. The same fork runs through the whole stack, and each layer tells you something about where we are in the transition.
**Compute.** AWS Lambda was built for short-lived, stateless functions — the opposite of agent sessions, which are long-running, stateful, and non-deterministic. Here's what that mismatch looks like in practice: an agent researching a topic might make twelve LLM calls over ten minutes, waiting for each response before deciding the next step. On Lambda, each wait risks a timeout. State has to be externalized to DynamoDB or S3 between invocations. The agent's "memory" lives in a database, not in the runtime.
AWS knows this. Their own documentation for [Bedrock AgentCore](https://aws.amazon.com/bedrock/agentcore/) concedes that existing primitives "were never designed for the peculiar demands of AI agents." Their response: [Lambda Durable Functions](https://www.infoq.com/news/2025/12/aws-lambda-durable-functions/), announced at re:Invent 2025 — checkpoint-and-replay semantics bolted onto Lambda so functions can pause, persist state, and resume later. It's clever engineering, but it's a checkpoint system stitched onto a stateless runtime. The function still doesn't *have* state; it serializes and deserializes it at each step.
Cloudflare's [Durable Objects](https://developers.cloudflare.com/durable-objects/) start from the opposite assumption: every agent *is* a stateful actor with its own SQLite database. When idle, it hibernates — zero compute cost. When a message arrives (HTTP, WebSocket, scheduled alarm, inbound email), the platform wakes it, loads its state, and hands it the event. The agent does its work, then goes back to sleep. State isn't externalized and restored; it's just *there*, in memory, when the agent wakes up. That's the difference between "stateless function that persists state externally" and "stateful actor that hibernates."
**Protocols.** MCP (Model Context Protocol) is the most interesting case because it lived the full arc in real time.
When MCP launched in November 2024, remote communication required two endpoints: a `GET /sse` connection for the client to receive responses, and a separate `POST /messages` endpoint to send requests. In practice, this meant managing two HTTP connections per agent session, correlating requests across them, and handling the inevitable failures when the long-lived SSE connection dropped mid-operation. If your agent was waiting for a slow tool call and the SSE connection timed out, the response was lost. You had to reconnect and retry.
Within five months, the MCP team deprecated SSE entirely and shipped [Streamable HTTP](https://modelcontextprotocol.io/specification/2025-03-26/basic/transports) — a transport they designed from scratch. One endpoint: `POST /mcp`. For simple calls, it returns a normal HTTP response. For long-running operations, the response upgrades to an SSE stream on the fly. The server can push notifications back to the client on the same connection. The practical difference: you go from managing two connections with correlation logic and reconnection handling to making a single HTTP request that adapts to whatever the interaction requires.
Meanwhile, [A2A (Agent-to-Agent)](https://google.github.io/A2A/) skipped straight to the new bet — a protocol for peer relationships between agents, with discovery via "Agent Cards," task negotiation, and streaming status updates built in from day one. MCP assumes a hierarchy (model calls a tool). A2A assumes peers (agents negotiate with each other). The relationship topology is baked into the protocol, not bolted on.
**Auth.** This is where the picture gets messy — and honestly, it's where the retrofit is winning for now. MCP adopted [OAuth 2.1](https://modelcontextprotocol.io/specification/draft/basic/authorization) as its authorization standard: PKCE, dynamic client registration, `.well-known` metadata discovery. The full enterprise auth stack, designed for humans clicking "Allow" in a browser, now repurposed for agents.
In practice, this means an MCP client that gets a `401 Unauthorized` has to open a browser, redirect the user through a consent screen, receive an auth code via callback, and exchange it for an access token — the same dance every web app has done since 2012. It works. It's well-understood. It plugs into existing identity providers.
But it assumes a human is present to click "Allow." For fully autonomous agents — an agent that wakes up at 3am to process a queue — the browser redirect is a dead end. Cloudflare's Artifacts sidesteps this entirely: `await env.ARTIFACTS.create(name)` returns a repo with a token. No browser. No consent screen. The auth model matches the consumer. Whether the broader ecosystem lands on OAuth-for-agents or invents something new is genuinely unresolved. MCP bet on the retrofit. It might be right — enterprise IT departments already understand OAuth. But the tension between "human approves access" and "agent acts autonomously" hasn't been resolved. It's just been deferred.
---
## What the Bet Reveals
Look at the pattern across all three layers:
| | Retrofit | New shape |
|---|---|---|
| **Storage** | S3 Files: `cat /mnt/s3/data.csv` | Artifacts: `env.ARTIFACTS.create(name)` → forkable repo |
| **Compute** | Lambda Durable Functions: checkpoint → serialize → hibernate → deserialize → resume | Durable Objects: wake up, state is already in memory |
| **Protocols** | MCP v1: `GET /sse` + `POST /messages` (two connections, correlation logic) | MCP v2: `POST /mcp` (one endpoint, adapts per-interaction) |
| **Auth** | MCP OAuth 2.1: browser redirect → consent screen → token exchange | Artifacts: `repo.token` returned at creation, no browser involved |
The retrofit says: agents are a new kind of user. Give them access to what exists, and they'll figure it out. The value is compatibility — works with your existing stack, plugs into your existing identity providers, runs on your existing infrastructure.
The new bet says: agents are a new kind of *computing*. They need primitives designed for how they work — iterative, parallel, disposable, branchable. The value is leverage — when the infrastructure matches the workload, you get capabilities that retrofits can't reach.
But I want to be honest: the line is blurry and it moves. MCP started as a retrofit (SSE) and evolved toward a new shape (Streamable HTTP) — but adopted a retrofit for auth (OAuth 2.1). Lambda started stateless and bolted on checkpointing. Nothing is purely one camp. The "new" isn't the technology — it's the abstraction, the shape of what's exposed to the consumer. Same old building blocks. Different architecture.
S3 Files will immediately help thousands of teams who have AI pipelines reading from S3 today. Artifacts won't help anyone until they rethink their architecture around per-session repos and forkable state. The retrofit has adoption. The bet has ceiling.
So let me make the ceiling concrete.
---
## What the New Shape Makes Possible
Here's a task: an agent is fixing a bug. It has three plausible approaches — retry logic, connection pooling, or async rewrite. It needs to try all three against the same test suite and pick the one that passes.
On a POSIX filesystem, this is painful. The agent either tries them sequentially (slow, and the filesystem is mutated after each attempt, so you need cleanup logic to restore state), or you build an orchestration layer that copies the working directory three times, runs each approach in a separate copy, and compares results. That orchestration layer doesn't exist in the filesystem. You have to build it.
With forkable state, this is a primitive. Fork three times from the same snapshot. Run each approach in its own fork. Compare. Pick the winner. The branching *is the storage model*, not something bolted on top.
This isn't theoretical. It's already shipping.
[ConTree](https://contree.dev/), built by the Nebius AI R&D team, offers sandboxed execution with Git-like branching for exactly this pattern. Branch from any checkpoint, explore paths in parallel, pick the winner. Their selling point against Docker is blunt: "Containers can't branch state. ConTree can." They built it for agents doing tree search — [Monte Carlo tree search over code](https://arxiv.org/html/2411.04329v2), where each node is a filesystem state and each edge is an attempted fix.
MIT's [EnCompass framework](https://news.mit.edu/2026/helping-ai-agents-search-to-get-best-results-from-llms-0205) formalizes the same insight from the academic side. You annotate "branchpoints" in your agent program — places where the LLM's output might vary — and EnCompass automatically clones the runtime to explore multiple paths in parallel, backtracking when paths fail. The researchers frame it as separating the *search strategy* from the *workflow*. But that separation only works if the infrastructure can fork cheaply. On a filesystem, cloning a runtime is expensive. With versioned state, it's a pointer copy.
Cloudflare's own [Project Think](https://blog.cloudflare.com/project-think/) — their next-gen Agents SDK, announced the same week as Artifacts — stores conversations as trees where each message has a `parent_id`. Fork a conversation to explore an alternative without losing the original path. Compact older messages without destroying them. The conversation history and the filesystem travel together in the same versioned structure.
OpenAI's Codex already runs each task in [its own cloud sandbox](https://openai.com/index/introducing-codex/), preloaded with your repo. Their subagent system [spawns specialized agents in parallel](https://developers.openai.com/codex/subagents) and collects results. But each sandbox is a fresh container — there's no branching from a shared state, no diffing between approaches, no rolling back to a checkpoint. The isolation is there. The versioning isn't.
That's the gap. The filesystem model gives you isolation (separate directories) and persistence (files stick around). The versioned model gives you isolation, persistence, *and* time travel — the ability to branch, diff, merge, and replay. Each additional property enables a class of agent behavior that the previous model can't support without external tooling.
---
## The Design Physics
I keep coming back to a frame from [[Design Physics: When Interfaces Meet Agents|an earlier essay]]: constraints shape what's possible. The choice of storage primitive *is* a design decision about what agents can do.
A POSIX filesystem encodes assumptions: files are edited in place, directories are hierarchies, there's one timeline. Those assumptions don't match how agents actually operate — iterating, branching, exploring, backtracking.
A versioned store encodes different assumptions: every state is a snapshot, every mutation is a commit, branching is free, merging is possible. Git is old too — but the *abstraction built on top of it* enables capabilities that the filesystem model actively prevents.
The infrastructure you choose doesn't just serve your agents. It shapes what they can become. S3 Files means your agents can `grep` a bucket. Forkable state means your agents can try three approaches simultaneously, compare the results, and discard the losers — without anyone writing orchestration code. That's not a quality judgment. It's a physics difference.
---
## Where It Goes
The honest answer: both patterns will coexist for a long time. Most teams will reach for the retrofit first — it's faster, cheaper, lower risk. The new bets will grow underneath, adopted by teams building agent-native products where the old primitives genuinely don't fit.
But I'd watch the Cloudflare pattern. Not because Cloudflare specifically will win — that's a business question, not an architecture question — but because the *type* of thinking they represent tends to compound. Every new primitive that matches how agents work becomes a building block for the next. Versioned state enables session replay enables collaborative debugging enables multi-agent branching. Each layer makes the next possible.
The retrofits don't compound the same way. They remove friction, which is valuable, but they don't open new design space. S3 Files means your agents can `grep` a bucket. That's useful today and exactly as useful in five years. Artifacts means your agents can fork reality. Where that leads is harder to predict — and that's exactly the point.
The fork in the stack isn't about old technology versus new technology. Everything is built on something that came before. The question is whether you preserve the old shape or build a new one.
The bet you make — same building blocks, different architecture — shapes the world you build.
### The Context Engineering Stack (2026-04-18)
URL: https://bristanback.com/notes/context-engineering-stack/
Updated: 2026-05-06
> I built an internal context engine for our 1,765-doc knowledge base. My teammate independently found a better one. The difference was a reranking step I hadn't thought of. Here's what the emerging context engineering stack actually looks like — and why no single tool gets it right yet.
Someone at my talk asked: "How do you actually make effective use of all the context?" It's the right question. Context is the unlock — I've been saying this since [[Code Owns Truth]]. The model isn't the differentiator. The context you give it is.
But I've been learning, uncomfortably, that my own practice doesn't fully match the thesis.
---
## What I Built
At Product.ai we have a shared knowledge base — 1,765 markdown documents. Architectural decisions, team manifests, domain axioms, mission specs. The kind of curated corpus I've been advocating for: write down the physics, give the agent a map, and grep does the rest.
Except grep stopped doing the rest about 800 documents ago.
It's worth understanding what Claude Code's search actually *is*. [Reverse engineering of the system prompt](https://kirshatrov.com/posts/claude-code-internals) shows what's under the hood: a `GrepTool` (regex over file contents), a `GlobTool` (find files by name pattern), and a `View` tool (read a file). When you ask "how does authentication work," the model extracts keywords from your request — `auth`, `token`, `login`, `middleware` — and issues grep calls for those literal strings. The model's reasoning decides *which* keywords to try, but the search itself is just regex over text. No semantic understanding, no index, no ranking. It either matches the string or it doesn't.
Claude Code does have a `dispatch_agent` that spins up a subagent for search — "when you're not confident you'll find the right match in the first few tries, use the Agent tool." That helps with context pollution (the subagent searches in isolation, only returns what's relevant). But the subagent still only has grep, glob, and read. Better isolation, same primitives.
For known identifiers — function names, class names, import paths — this is fine. For conceptual queries, it falls apart. "How does the billing system handle failed payments" has no single string to grep for. The logic might span three files connected by imports, not shared keywords. And [Morph's research](https://www.morphllm.com/agentic-search) puts a number on it: agents spend 60%+ of their time searching, and untrained models take 12+ turns to find what a trained search model finds in 4.
So I built a "context engine" for fun — I'd used LanceDB on a toy project embedding images with CLIP and it seemed like a reasonable experiment to try for text. A local RAG tool that indexes markdown into LanceDB, embeds via Ollama's `nomic-embed-text`, and serves hybrid search (vector + BM25 with Reciprocal Rank Fusion) over MCP. Point it at your folders, index, add the MCP server to Claude Code — done in five minutes. We added a plugin installer, a `/ce-search` skill, config-as-code. Clean, lightweight, purpose-built for our org.
Meanwhile, without knowing about my solution, a coworker had set up [QMD](https://github.com/tobi/qmd) — Tobi Lütke's local-first semantic search engine — on the same knowledge base. Same problem, different approach.
Then he ran them head-to-head on identical queries. Three queries told the whole story.
---
## The Benchmark That Changed My Mind
**Query 1: "How does [internal service] render and serve pages?"**
- Our context engine returned tangentially related docs at 67% confidence — files that *mentioned* the service but weren't *about* its rendering pipeline.
- QMD returned the team lead's manifest at 93% — the person who owns that architecture. Then the rollout plan, the core engineering derivation. It found the *people and decisions* that own the answer, not just files that contain the keyword.
**Query 2: "How does [data collection system] work and what events does it track?"**
- Both found the right document — the system's architecture spec. But our context engine returned four chunks from the *same doc*. QMD returned breadth: the spec, a related analytics mission, the domain strategy document. Connected context from across the corpus.
**Query 3: "NestJS authentication JWT token refresh flow"**
- `grep -ri "JWT.*refresh\|refresh.*token"` → 0 results. The exact phrase doesn't exist in our knowledge base.
- Our context engine found the security architecture doc at 69%, then returned it again as a duplicate chunk.
- QMD found the same doc at 88%, then the *engineer who owns auth* at 50%. It found the right system *and* the right person from a query that grep couldn't touch.
The gap is reranking. Our context engine stops at RRF fusion — statistical merging of vector and keyword results. QMD adds two LLM stages: query expansion (a 1.7B model generates search variants) and neural reranking (a 0.6B cross-encoder scores each result for actual relevance). RRF is statistical. The reranker *understands* the query.
Fewer, smarter chunks matter too. QMD uses boundary scoring — it targets ~900 tokens per chunk, scores potential break points by heading weight, code block boundaries, blank lines — and picks the best split within range. Our context engine splits on headings with a hard 2,000-char limit. Same 1,765 docs, but QMD produced 49,799 chunks vs. my 86,432. Fewer chunks, less noise, better retrieval.
Our context engine wins on incremental reindex speed (1.1s vs. 5.8s for single file changes), lighter model footprint (274MB Ollama vs. 2.3GB on-device GGUF), and org integration (plugin installer, skills, config-as-code). But I'll be honest: QMD kind of replaces what I built. Retrieval quality is the thing that matters for agents, and QMD is meaningfully better there. The differences are interesting though — reranking vs. RRF, boundary-scored chunking vs. heading splits, 49K chunks vs. 86K from the same docs. Same problem, and the architectural choices that diverged tell you a lot about where retrieval quality actually comes from.
---
## The Landscape Forming Around This
The shared-knowledge benchmark was a microcosm of what's happening at the tooling level. A stack is forming, and it has three layers:
**The crash course — orientation, conventions, constraints.** This is the `CLAUDE.md`. In practice it's part onboarding doc ("this is a TypeScript monorepo, here's how to run tests"), part house rules ("we use Drizzle for ORM, errors follow this pattern"), part map ("the auth system lives in `src/lib/auth`"), and part hard constraint ("never modify migrations directly"). It's the agent's first day at the company, compressed into a file. Zero latency, zero cost, survives context compaction. And it encodes judgment and taste — things no retrieval system can find because they never existed as documents until someone wrote them down. The [[Rapid Generative Prototyping: Design in the Post-Figma Era|three-layer model]] applies to the constraint part specifically: when those rules are tight, the agent needs less search because the physics are already loaded.
Anthropic added [`.claude/rules/`](https://code.claude.com/docs/en/memory) — modular rule files that split the monolithic `CLAUDE.md` into focused pieces (`code-style.md`, `testing.md`, `security.md`). Personal rules in `~/.claude/rules/` apply to every project on your machine; project rules override per-repo. Symlinks let you share common rules across projects. It's the same constraint layer getting more structured — from one big doc to composable, hierarchical modules.
But all of it — `CLAUDE.md`, rules, manifests — only captures what you *knew* to write down. It's blind to the file you forgot, the dependency you didn't know existed, the person who owns the answer.
**Semantic search — discovery.** [Cursor's research](https://cursor.com/blog/semsearch) is the clearest evidence: 12.5% higher accuracy across all frontier models when semantic search is available, with code retention improving 2.6% on large codebases. They trained a custom embedding model on agent traces — analyzing what *should* have been retrieved earlier in a session, then training the model to surface it sooner. The search learns from how agents actually work.
The tools: QMD for local-first hybrid search with reranking. [Nia](https://www.trynia.ai/) (YC S25) for hosted indexing of remote codebases and third-party packages — and for context sharing across agents (plan in Cursor, continue in Claude Code, search context comes with you). [Augment's Context Engine](https://www.augmentcode.com/context-engine) for the most ambitious approach: 1M+ files, real-time knowledge graph mapping architecture and dependencies, exposed via MCP.
The limitation is structural. Embeddings treat code as flat text. They can't follow a function call from `handler.ts` to `utils/auth.ts` to `lib/jwt.ts`. [Google DeepMind proved](https://arxiv.org/abs/2508.21038) there's a mathematical ceiling on what embeddings can represent at scale.
**Code intelligence — structural indexing.** There's a layer between text retrieval and agentic search that deserves its own mention: LSP, the Language Server Protocol. Microsoft built it for VS Code in 2016 to standardize how editors understand code — go-to-definition, find-references, hover for type info, symbol outlines. It's how your IDE knows that `validateToken` in `auth.ts` is called from `middleware.ts` and returns a `Promise`. Structural understanding, not text matching.
Now agents are getting it too. Claude Code added [native LSP tools](https://code.claude.com/docs/en/plugins-reference) in December 2025 — go-to-definition, find-references, document symbols. [Serena](https://github.com/oraios/serena) is an MCP server that exposes the same capabilities to any agent. There's a whole [plugin marketplace](https://github.com/Piebald-AI/claude-code-lsps) with LSP servers for TypeScript, Rust, Python, Go, Java, and twenty other languages.
This is the code equivalent of what QMD and semantic search do for documents. QMD indexes *text* — finds the right document by meaning. LSP indexes *code structure* — follows the actual dependency graph, type system, and call hierarchy. One finds where concepts are discussed. The other follows where functions are called. An agent with both can find the auth documentation *and* trace the actual token validation path through the codebase.
It's also the most purely symbolic layer in the whole stack — ASTs, type systems, and call graphs are formal structures, not learned approximations. Which makes the neuro-symbolic connection even more direct.
**Agentic search — comprehension.** This is the new category. The agent searches, reads results, *reasons* about what it found, searches again. Multi-turn, hypothesis-driven. "Grep for `webhook`, find the handler in `api/webhooks/`, read it, see it calls `decodeJWT` from `lib/crypto`, follow that import, find the actual validation logic."
The critical insight from Anthropic's engineering: **agentic search should run in a subagent with its own context window**. When the main coding model searches, every dead-end file stays in context. After five or six exploration turns, the context is polluted. Performance degrades 30%+. Subagent architecture solves this — the search agent explores in isolation, throws away dead ends, returns only the relevant spans. The main model's context stays clean.
This is why Anthropic's multi-agent approach outperformed single-agent Opus by 90%. Not smarter agents — cleaner context.
Trained search models ([Morph's WarpGrep](https://www.morphllm.com/agentic-search)) achieve the same retrieval quality in 3.8 steps vs. 12.4 for untrained models — 3x fewer turns, because they fire 8+ parallel tool calls per turn instead of exploring sequentially.
---
## The Stack
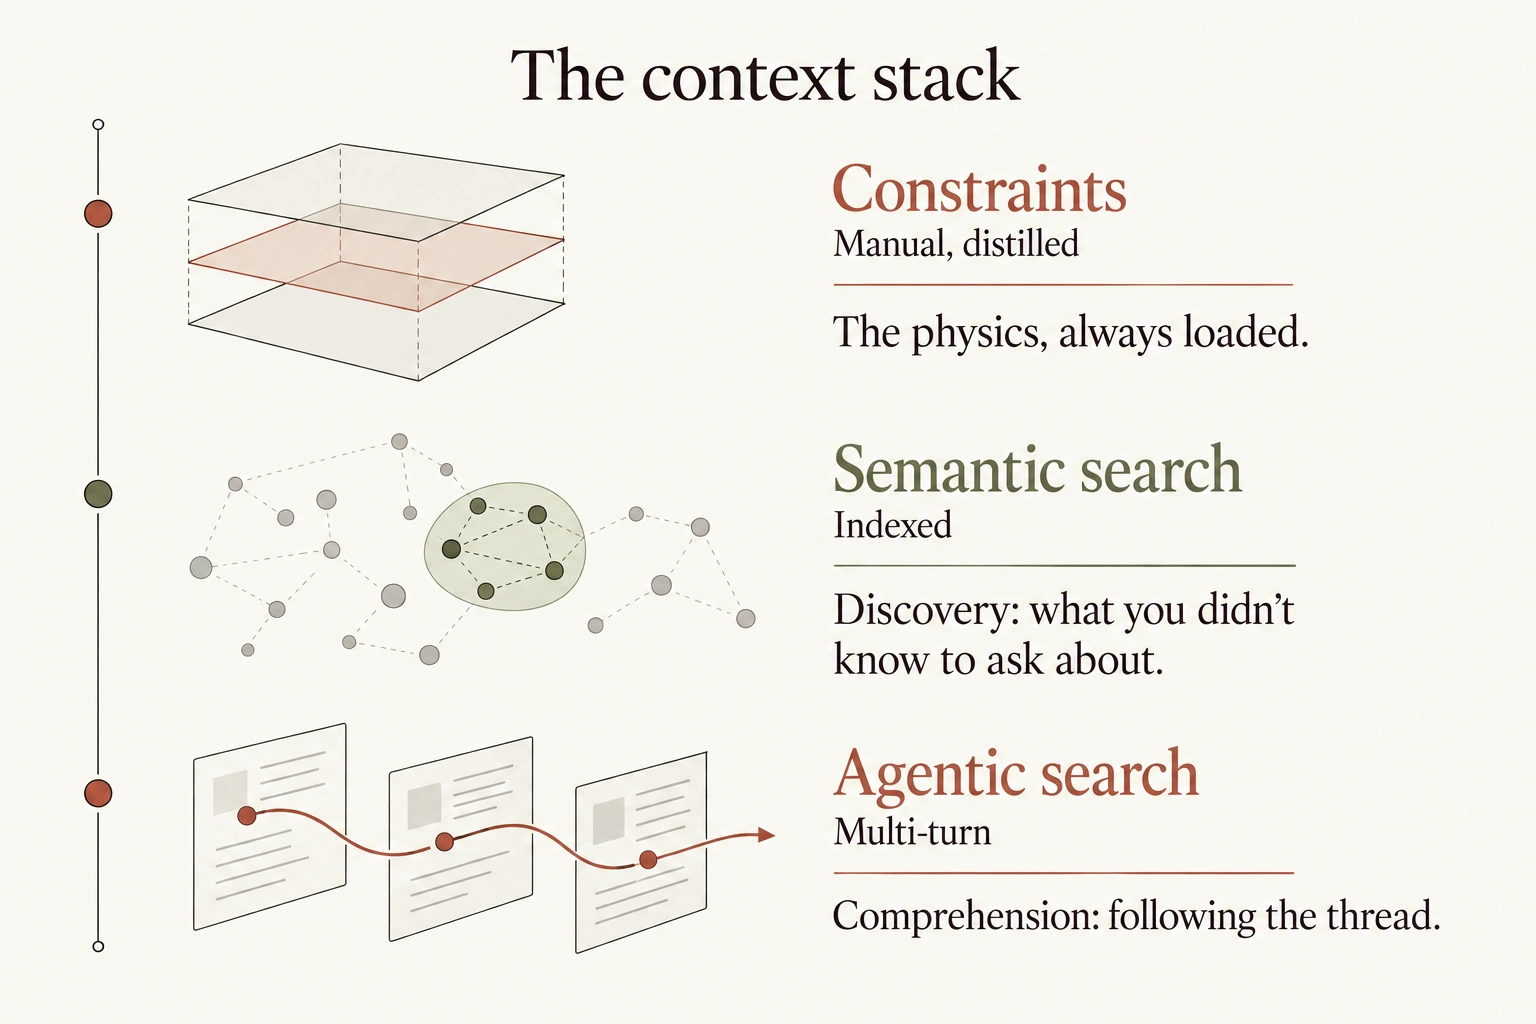
Read the stack as text
- **Constraints (manual, distilled):** the physics, always loaded.
- **Semantic search (indexed):** discovery, what you didn't know to ask about.
- **Agentic search (multi-turn):** comprehension, following the thread.
Constraints without discovery is blind. Discovery without comprehension is noisy. Comprehension without constraints is aimless.
The part I'm still working out: where does the constraint layer end and the search layer begin? Right now I'm forging axioms through a conscious, explicit process — running research across different foundation models, finding where they diverge, adversarially fusing the results into something I trust. "We use Drizzle for the ORM, Elysia for the API layer, here's the error handling pattern" — but those aren't just typed from memory. They're distilled from deliberate multi-model investigation. But what if the agent could *derive* those axioms from the codebase, the way Cursor's embedding model learns from agent traces? The constraints would be automatically distilled, continuously updated, and the manual curation I do would become the exception rather than the rule.
That's the version of this that makes my constraint-layer thesis both more powerful and slightly obsolete. The physics still matter. But maybe you don't have to write them by hand forever.
---
## The Missing Layer: Forgetting Well
There's a dimension I haven't mentioned yet: context *management* over time. Retrieval is half the problem. The other half is what happens when the context window fills up. I wrote about this in [[Memory and Journals]] — Borges's Funes, the man with perfect memory who couldn't think because he couldn't forget. Agents that log everything are agents that understand nothing. The ones that learn to forget well might be the ones that actually think. The same principle applies to retrieval: seeing everything isn't the goal. Seeing the *right* things is.
A [recent teardown](https://justin3go.com/en/posts/2026/04/09-context-compaction-in-codex-claude-code-and-opencode) of how Codex, Claude Code, and OpenCode handle compaction found three completely different strategies. Codex writes a "handoff summary" — distill everything into a briefing for the next context window, delete the rest. Claude Code uses three-tier progressive forgetting — first trim old tool results (zero LLM cost), then use prompt cache strategies, then a structured 9-section LLM summary as a last resort. OpenCode does timestamp-based message hiding with a 5-heading summary.
The insight: "the best context management isn't about endlessly expanding memory capacity, but learning to forget with precision." That's a compaction version of the same point. It's not about seeing everything. It's about seeing the *right* things.
This connects to why even crude approaches have value as stopgaps. We have an auto-generated INDEX.md in our shared-knowledge repo — basically an index in a book, a flat listing that gives agents a map before they search. It's honest-to-god crude, and probably obviated by QMD or similar once you have proper retrieval set up. But it tells the agent *where to start looking* and that reduces wasted search turns, which is better than nothing when you're at 1,765 docs and haven't indexed yet. There's now a [codebase-context-spec](https://github.com/Agentic-Insights/codebase-context-spec) proposal to standardize this pattern — a `.context/index.md` at the root of any project — and an [empirical study from November 2025](https://arxiv.org/html/2511.12884v1) analyzing how developers are actually writing these manifests in practice.
Even [Martin Fowler's team](https://martinfowler.com/articles/exploring-gen-ai/context-engineering-coding-agents.html) is calling file reading and searching "the most basic and powerful context interfaces in coding agents." The industry is converging on the idea that context is *the* engineering surface.
---
## The Neuro-Symbolic Thing Nobody's Naming
Here's what I keep circling back to. The constraint layer — `CLAUDE.md`, axioms, manifests, INDEX.md, the codebase-context-spec proposal — is symbolic. Structured, human-authored, explicit rules. The physics you write down.
Semantic search — embeddings, vector similarity, reranking models — is neural. Learned, fuzzy, pattern-matching. The discovery that finds things you didn't know to ask about.
Agentic search is the hybrid. Neural reasoning *over* symbolic structures — following imports, reading code, tracing call graphs. An LLM using grep and file-read tools to navigate a codebase is a neural system reasoning about symbolic artifacts. It's the neuro-symbolic part happening in practice without anyone calling it that.
The whole context engineering stack is arguably a neuro-symbolic architecture emerging bottom-up. Nobody designed it as one. But when you layer explicit constraints (symbolic) on top of learned retrieval (neural) on top of reasoning-driven search (hybrid), you've reinvented something AI researchers have been theorizing about for decades — just pragmatically, in the IDE, without the academic framing.
The neuro-symbolic debate in AI has always been about this: pure neural systems (transformers, embeddings) are powerful but opaque and brittle on edge cases. Pure symbolic systems (rule engines, knowledge graphs, formal logic) are precise but can't handle ambiguity or scale to natural language. The whole field has been trying to combine them. And here we are, doing it accidentally, because agents need both grep *and* semantic search *and* human-written axioms to function well in a real codebase.
The [[Memory and Journals]] connection matters here too. Forgetting is a compression operation — it's the system deciding what to keep in symbolic form (the distilled summary, the axiom, the journal entry) versus what stays in the neural substrate (the raw embeddings, the full conversation history that can be retrieved but doesn't need to be present). Human memory does this automatically. Agent memory systems are reinventing it piece by piece — compaction, tool-result trimming, context windows with sliding summaries — without a unified theory of what they're doing.
Maybe that's fine. Maybe the unified theory isn't necessary and the pragmatic layering is the theory. But it's worth noticing that the "how do I get my coding agent to understand my codebase" problem and the "how do we combine symbolic and neural AI" problem are the same problem wearing different clothes.
---
## No One Size Fits All
The honest answer to "how do you make effective use of context" isn't a stack diagram. It's: we're running four different approaches simultaneously and still figuring out which one to reach for when.
- Our shared repo's INDEX.md gives agents a generated map before they start searching — high-level orientation
- Our internal "context engine" gives hybrid RAG search over the corpus — find the right document
- QMD adds reranking and smarter chunking — find the right *answer* within the right document
- Claude Code's native grep/glob/subagent pattern follows causal chains across files — understand how things connect
They overlap. They have different failure modes. Grep is instant but dumb. Semantic search is smart but stale. Agentic search is thorough but slow. The manifest is high-signal but manual. None of them alone is sufficient. The combination is the practice.
The three-layer model from [[Code Owns Truth]] still holds as a frame — constraints bound the space, prompts express intent, code is truth — but when I zoom into the constraint layer itself, it's not one thing. It's a stack of different retrieval strategies, each with tradeoffs, layered on top of each other and evolving fast.
---
## The Ground Shifting Underneath
Everything I've described so far is scaffolding built around a constraint: dense attention is quadratically expensive, so we chunk, retrieve, compress, and orchestrate to keep the right context visible without blowing up the cost.
And every layer of that scaffolding has failure modes. RAG preserves semantic similarity but loses position, hierarchy, and reference structure — a chunk may contain the right text while losing *why* that text matters. Agentic search is thorough but slow, and dead-end explorations pollute context. Compaction preserves gist but drops the specific constraint that governed a later decision. The manifest encodes human judgment but only captures what someone *knew* to write down. We accept these tradeoffs because the alternative — putting everything in context — has been prohibitively expensive.
What happens when it isn't?
[Subquadratic](https://subq.ai) launched this week with their [SSA architecture](https://www.subq.ai/research/ssa) — Subquadratic Sparse Attention — and the claimed numbers are striking. 52× prefill speedup over dense attention at 1M tokens. A 12M token context window. Linear scaling, not quadratic. The architecture doesn't approximate attention or compress state into a fixed-size buffer. It does content-dependent selection: for each query, the model decides which positions in the sequence are worth attending to, computes exact attention over those, and skips the rest.
The distinction from prior attempts matters. Sliding windows and fixed-pattern sparsity gave up content-dependent routing. State space models gave up exact retrieval from arbitrary positions. Hybrids reintroduced dense layers and with them the original cost. SSA's claim is that it doesn't make that trade: linear scaling *with* content-dependent routing *and* arbitrary-position retrieval. On MRCR v2 at 1M tokens — the hardest long-context retrieval benchmark, requiring multi-hop evidence integration — SubQ scores 65.9%. That's behind Opus 4.6 (78.3%) and GPT 5.5 (74.0%), but well ahead of GPT 5.4 (36.6%), Opus 4.7 (32.2%), and Gemini 3.1 Pro (26.3%). Not frontier retrieval, but genuinely functional retrieval at a fraction of the compute — and at context lengths where dense attention models either can't run economically or can't actually use the context they accept.
Caveats are real. The full technical report hasn't been released. Weights aren't open. The benchmark selection is narrow — three tests, all emphasizing the long-context retrieval and coding tasks SSA is designed for. There's also a [17-point gap](https://venturebeat.com/technology/miami-startup-subquadratic-claims-1-000x-ai-efficiency-gain-with-subq-model-researchers-demand-independent-proof) between SubQ's research MRCR score (83) and its third-party verified production score (65.9) that's largely unexplained. The AI research community's reaction has ranged from "genuine breakthrough" to "wait for the technical report." History favors skepticism — Mamba, RWKV, and every prior subquadratic architecture looked promising in papers and underperformed transformers at frontier scale. SSA may be different. It may not be. The honest position is: the *direction* is clearly right even if this specific implementation needs more proof.
But the direction is what matters for this essay. Every layer of the stack I've been describing — the manifest, the semantic search, the agentic subagent exploration, the compaction strategies — exists partly because putting everything in context was too expensive, and partly because retrieval scaffolding introduces its own failure modes that we've learned to live with. If attention becomes cheap at million-token scale, *both* pressures change. The economic argument for chunking weakens. And the failure modes of retrieval — lost hierarchy, semantic drift, fragmented reasoning — become avoidable rather than tolerable.
Not entirely, though. Even if you *can* attend to 12M tokens subquadratically, should you? The Funes argument from [[Memory and Journals]] holds on cognitive grounds even when cost goes to zero. Total recall without compression still produces noise. The constraint layer encoding human judgment — the `CLAUDE.md`, the axioms, the manifests — still matters, because it's not about what the model *can* see, it's about what the model *should* prioritize. And forgetting-as-meaning is a cognition problem, not a cost problem.
But the engineering argument — "we chunk because we have to" — gets weaker. And that means the scaffolding layer shifts from load-bearing infrastructure to optional optimization. The manifest still matters. Semantic search still helps. But they become choices rather than necessities, and the failure modes we've been routing around become the strongest argument for keeping them.
The stack doesn't collapse. But the reason each layer exists changes — from "we can't afford to see everything" to "we shouldn't *want* to see everything, but now we're choosing rather than being forced."
---
The differentiator was never the model. It was always what the model could see. But what the model *should* see depends on the question, the scale, and the moment — and no single tool gets that right yet. The architecture layer is moving fast enough that some of those tools may become optional before they become mature. That's not a reason to stop building them. It's a reason to hold them loosely.
### Named Things: A Glossary of Compressed Wisdom (2026-04-13)
URL: https://bristanback.com/notes/named-things/
Updated: 2026-09-14
> The named laws, razors, and principles that keep showing up in engineering and strategy. Each one is a concept compressed into a name — human-language embeddings, built over centuries instead of training runs.
There's something interesting about named principles. Someone watches a pattern repeat for years and distills it into a sentence. Then someone *else* attaches a name. Conway didn't call it "Conway's Law" — others did. Chesterton was just writing an argument in a book; later readers extracted the fence and named it. The observation is individual. The naming is collective — an act of community compression. After that, the name *is* the concept. "Chesterton's Fence" carries an entire philosophy of caution in two words. "Goodhart's Law" compresses a thesis about measurement corruption into four.
I think of these as human-language embeddings. A name gives a complicated observation a small, portable handle; someone else can use it without retelling the whole story. The comparison to a model's embeddings is a metaphor, but the lossiness is real. We remember the sentence and forget the conditions that made it useful. There's a kind of *Begrifflichkeit* to it — forming concepts that give thought something to hold onto. Or an echo of *kotodama*, the Japanese idea that words carry spiritual power. Naming changes what we can call into a conversation.
Some of these I keep coming back to. Some I just find interesting. This is a living reference — mostly for me, partly to see what patterns connect. The engineering and agent examples are my applications of the principles, with all the room for error that implies.
---
## The Laws
### Chesterton's Fence
Don't remove something until you understand why it was put there. The fuller version is worth hearing:
> "There exists a fence or gate erected across a road. The more modern type of reformer goes gaily up to it and says, 'I don't see the use of this; let us clear it away.' To which the more intelligent type of reformer will do well to answer: 'If you don't see the use of it, I certainly won't let you clear it away. Go away and think. Then, when you can come back and tell me that you do see the use of it, I may allow you to destroy it.'"
This might be the single most important principle for the agent era. Claude Code will happily "clean up" a function that looks redundant but exists because of a bug discovered at 3am two years ago. The agent optimizes for local cleanliness without historical context — it can't see the scar tissue. And in a world of increasingly AI-generated codebases, the fence signal gets *noisier* — there's less "someone stayed up till 3am" human scar tissue and more pattern-matched output. Chesterton's Fence becomes a guardrail we have to deliberately apply when reviewing AI changes, not just human ones.
I've hit this three times recently, and the shape was different each time. Once I blew past it — we were migrating from Jenkins to ArgoCD, and I labeled a Jenkinsfile as a straggler, confirmed the GitOps manifests existed, and deleted it. Thirty minutes later: the service was still serving live traffic in production, but nothing in the new system was actually managing it.
The Jenkinsfile hadn't deployed in over a year — but it was the only record of how that service got into production, and nothing else had picked up the slack.
Once I caught myself just in time. I had repos queued for retirement because they hadn't been pushed recently, and mid-planning I stopped and thought: wait, those could still be in active production use. Last-commit-age isn't the signal that determines whether the fence matters. Live deployments, healthy services, DNS still pointing at it: those are reasons to investigate.
And once I removed correctly — traced the actual dependency, proved nothing was attached, then removed. Same discipline, different outcome.
The pattern I'm taking forward: the fence isn't the code or the label or the file. The fence is whatever invariant the past version of the team relied on that you can't see from the current state. The job is to surface the invariant, verify it, then decide whether to remove it.
Naming it "Chesterton's Fence" turns vague caution into a portable, high-fidelity reminder — exactly the kind of human embedding that agents still struggle to internalize without explicit scaffolding.
I went deep on that one because I lived it recently. The rest are shorter, mostly things I've internalized into abstractions. The vivid memory faded; the instinct stayed. That's kind of the whole point of named things.
### Conway's Law
Systems tend to reproduce the communication structures of the organizations that design them. Melvin Conway submitted the argument in 1967; [it was published in 1968](https://www.melconway.com/Home/Conways_Law.html). Your microservices architecture starts to look suspiciously like your team structure.
Multi-agent systems can recreate this quickly. Define a "frontend agent" and a "backend agent" and you've already made an architectural suggestion, whether or not that boundary fits the problem. Splitting by role can help: a planner and a worker can share the same domain. But they still have a communication structure, and their handoff can become a constraint of its own. Renaming the agents doesn't get us out of Conway.
### Goodhart's Law
Once a measure becomes a target, optimizing it can break its relationship to what you cared about. The familiar wording compresses an observation Charles Goodhart made about monetary policy in 1975.
Benchmark gaming. School ratings. Code coverage as a quality proxy. Any time someone says "we improved X by 15%" — ask what X stopped measuring when they started optimizing for it.
### Hyrum's Law
Given enough users, someone will depend on every observable behavior of your system, including the ones you never promised. [Hyrum Wright's observation](https://www.hyrumslaw.com/) grew out of infrastructure migrations at Google. If your endpoint happens to return results sorted alphabetically, someone will eventually depend on that.
This is why "just refactor it" is never just. Agents need to understand implicit contracts as well as explicit interfaces. The invisible dependencies are the ones that bite.
### Gall's Law
"A complex system that works is invariably found to have evolved from a simple system that worked." John Gall, 1975. I read this as a demand for a working starting point. A grand design doesn't get to skip contact with use.
The context engineering stack formed bottom-up from pragmatic layering. That's the useful instruction I take from Gall: keep something working while you discover what else it needs.
### Brooks's Law
"Adding manpower to a late software project makes it later." Fred Brooks, 1975. Communication overhead grows faster than productivity gains.
The agent version: adding agents to a bad architecture makes it worse faster. More agents ≠ more progress.
### Jevons Paradox
Making a resource more efficient to use can increase total consumption if the resulting demand grows enough to outweigh the savings. William Stanley Jevons, 1865: more efficient coal engines made new uses economical. Efficiency per use and consumption overall can move in opposite directions.
My bet is that cheaper software production gives us more software to tend. The cost of producing a feature falls; the surface area we're responsible for grows. Whether that creates more demand for engineers depends on what happens to the cost of tending it, too.
### Lindy Effect
For some things that don't wear out like a physical object does, a long past can be evidence of a long remaining future. SQL. Unix. Git. HTTP. grep. When someone says "X will replace Y," check how long Y has existed, and what keeps renewing the reasons to use it. Age alone won't save a tool whose environment has disappeared.
### Postel's Law (Robustness Principle)
"Be conservative in what you send, be liberal in what you accept." Jon Postel, 1980. Strict output schemas. Tolerant input parsing. The constraint layer is conservative in what it sends. The prompt layer is liberal in what it accepts.
This one fights with Hyrum. Quietly accepting a malformed input can teach someone that it's valid, and now the workaround is part of the interface. [RFC 9413 describes that failure mode](https://www.rfc-editor.org/rfc/rfc9413.html). I want tolerance for how someone expresses an intent, with explicit validation before that intent turns into an action. Silently guessing at a broken contract is a different bargain.
---
## The Razors
### Occam's Razor
Prefer the explanation that accounts for the evidence with fewer unnecessary assumptions. "Fits the evidence" does most of the work. Deleting the inconvenient evidence doesn't make an explanation simpler.
### Hanlon's Razor
Never attribute to malice what's explained by a stale cache, a race condition, or a misconfigured env var.
My engineering translation. Check the ordinary failure before building a theory about someone's intentions. It tells me where to start investigating; it doesn't require me to ignore what the investigation finds.
### Hitchens's Razor
"What can be asserted without evidence can be dismissed without evidence." Useful for evaluating AI hype.
---
## The Numbers
### Dunbar's Number (~150)
A proposed rough scale for stable social relationships, often repeated as a hard human limit. [The precision is contested](https://pmc.ncbi.nlm.nih.gov/articles/PMC8103230/). I keep the coordination question and hold the number loosely: when does a group get large enough that remembering who knows what stops being a workable system?
### Miller's Law (7 ± 2)
The memorable number from George Miller's work on memory and information processing. It isn't a universal allowance of seven things: chunking and the task matter, and [Nelson Cowan's later review argues for about four chunks under more controlled conditions](https://pubmed.ncbi.nlm.nih.gov/11515286/).
The question I care about is how many parallel agent tasks I can track before I lose the thread. A context window doesn't tell me that. Nor does a tidy number from a different task.
---
## The Deeper Ones
### Ashby's Law of Requisite Variety
A regulator needs enough possible responses to counter the disturbances that matter to the outcome it's trying to preserve. The engineering translation: the constraint layer needs enough expressiveness to handle the variation we care about. If my design tokens cover color and spacing but leave typography open, valid colors can still arrive with garbage type. I left that freedom in the system.
### The Anna Karenina Principle
When success requires several conditions to hold together, failure can come from any one of them. Borrowed from Tolstoy's opening about happy and unhappy families. A deployment might need correct code, valid credentials, reachable dependencies, and enough capacity. Passing three checks doesn't compensate for failing the fourth. The useful part is the conjunction; there are still plenty of different ways to build a working system.
### Wittgenstein's Ladder
Near the end of the [*Tractatus*, proposition 6.54](https://www.gutenberg.org/files/5740/5740-pdf.pdf#page=92), Wittgenstein asks the reader to get beyond his propositions, like throwing away a ladder after climbing it. I'm borrowing the image more loosely here. Maybe these named principles are the ladder — you learn "Chesterton's Fence" as a rule, internalize it as intuition, and eventually stop naming it. The compression becomes invisible. That's one kind of expertise: named principles that have dissolved into judgment.
---
The thing that strikes me about this list: every one of these is someone compressing years of observation into a sentence. Axioms, a `CLAUDE.md`, [[The Context Engineering Stack|the constraint layer]] — each tries to make some of that judgment portable enough for a machine to carry.
The name makes the judgment portable. It can also make it feel settled. That Jenkinsfile already looked redundant. A name can remind me to look again; it can't tell me what's still depending on the thing I'm about to delete.
---
*Living document. Adding as I encounter them.*
### The Frontend Testing Gap (2026-03-14)
URL: https://bristanback.com/notes/frontend-testing-gap/
> Backend testing is a solved problem. Frontend testing for stateful, streaming, visual UIs is not. That's exactly where AI coding agents are generating the most code.
Here's the gap nobody's talking about: the places where AI coding agents are most productive are the places where automated testing is weakest.
Backend services have mature test infrastructure. You write a function, you write a test, you assert the output. CI catches regressions. The agent writes code, the tests verify it, the human reviews the delta. That loop works.
Frontend — specifically stateful, streaming, visual frontend — breaks every part of that loop.
## The Three Hard Properties
A chat interface has three properties that make it genuinely difficult to test:
**Stateful.** The UI depends on a sequence of events over time. Message arrives, scroll position adjusts, user scrolls up, new message arrives but scroll doesn't follow, user scrolls back down, auto-scroll resumes. The correctness of any given frame depends on everything that happened before it. You can't test a single state — you have to test a *trajectory*.
**Streaming.** Content arrives in chunks. A word at a time, sometimes a partial token split across two chunks. The DOM is being mutated continuously while the user is interacting with it. The parser has to handle markdown that's half-formed — an opening backtick with no closing backtick *yet*. The scroll container is growing while being read. The rendering has to be smooth enough that it doesn't feel like watching a terminal.
**Visual.** "It works" and "it looks right" are different assertions. The message appeared — but is it inside its container? The scroll followed — but did it jank? The input resized — but did it push the messages off screen? These are questions that a unit test literally cannot answer. You need a real browser, rendering real pixels, on a real viewport.
An AI coding agent can change the scroll logic, run the unit tests, see them pass, and ship code that breaks on every iPhone. Not because the logic is wrong — because the *visual consequence* of the logic only manifests in a rendering engine the agent never sees.
## Why This Didn't Matter Before
The frontend went through phases. Server-rendered templates were genuinely thin — fetch data, render HTML, done. Then SPAs swallowed everything: routing, state, data fetching, caching, the works. Now the pendulum is swinging back with islands and edge rendering — the *intent* is thinner frontends again, but the islands that do exist are denser than ever. Either way, the testing story was always simpler when the server owned the output. You could test "does the right HTML arrive?" without a browser.
Three things changed:
**[Islands architecture.](https://docs.astro.build/en/concepts/islands/)** Interactive components hydrate independently on otherwise static pages. Each island is a miniature application with its own state, lifecycle, and failure modes. The chat island on our site is 1,200 lines of vanilla TypeScript managing streaming SSE, markdown parsing, scroll physics, input auto-resize, and error recovery. That's not a "component." That's an application embedded in a page.
**Streaming as the default.** LLM-powered interfaces don't return a response — they stream one. Every chat UI, every AI assistant, every copilot integration is now a streaming renderer. The entire frontend industry shifted to streaming in about eighteen months and the testing infrastructure didn't follow.
**AI writing the UI code.** When a human writes the scroll handler, they test it by scrolling. They see the jank. They feel the broken behavior. When an agent writes the scroll handler, it sees the code, maybe runs a unit test, and moves on. The feedback loop that used to happen in the developer's eyes now has a gap where the eyes used to be.
## What a Test Harness Actually Looks Like
I've been thinking about this as two layers.
### Layer 1: Automated verification (CI)
This defines "correct." It runs on every PR. No human in the loop.
**A streaming mock server.** This is the foundation everything else builds on. An endpoint that replays canned SSE at realistic timing — same tokens, same chunk boundaries, same delays. Deterministic. No API key. You build this once and every other test depends on it. It lives on the server, not in the client — the client doesn't know it's talking to a mock.
**Browser interaction tests.** Playwright running against the real app with the mock server. Not unit tests — *behavior* tests:
- Send a message → verify it appears in the thread
- Receive a streaming response → verify scroll follows content
- Scroll up during streaming → verify scroll lock holds position
- Resize viewport mid-conversation → verify layout doesn't break
- Run on Chromium, WebKit, and Firefox. Run on 375px, 768px, and 1440px viewports.
These tests describe *intent*, not implementation. "Verify scroll follows content" doesn't care how the scroll handler works. It cares that the user sees the new content.
**Visual regression.** Playwright screenshots at key states — empty chat, single message, long thread, mid-stream, error state. Diff against baseline on every PR. This catches "the tests pass but the send button is under the keyboard on iOS." The class of bug that is invisible to unit tests and obvious to human eyes.
**Component-level tests.** Vitest for the logic that doesn't need a browser — state machine transitions, chunk parsing, message ordering. Fast, runs in Node, catches logic regressions in seconds.
### Layer 2: Dev-time tools (the agent's eyes)
This is how the agent validates its own work interactively, before pushing.
The agent needs to *see the app running*. Screenshots mid-development. DOM inspection. Console monitoring. The ability to say "I changed the scroll handler, let me check if it actually scrolls correctly on a 375px viewport."
We've been using MCP browser tools for this — the agent takes a screenshot, inspects the DOM, evaluates JavaScript in the page. It's not perfect. The agent still misses subtle visual issues. But it closes maybe 80% of the gap between "code looks right" and "code works right."
Neither layer alone is enough. Tests without visual feedback produce code that passes but feels wrong. Visual feedback without tests produces code that looks right but regresses next commit.
## The Economics Changed
The old argument against heavy frontend test suites was that maintenance cost more than the bugs they caught. Every UI change broke selectors, someone had to update them, nobody did, the suite rotted.
That argument assumed humans maintaining the tests. When the AI agent changes a component, it can update the tests in the same PR. The agent that breaks the test fixes the test. The maintenance tax that killed test suites isn't zero — but it's an order of magnitude lower than it was.
Self-healing selectors (tools like Stagehand layering AI over Playwright) push this further. Instead of `page.click('#send-btn')` — which breaks when someone renames the ID — you write `page.act('click the send button')` and the AI resolves the selector. The test describes intent. The implementation can change without the test breaking.
What hasn't changed: someone still has to define *what* to test. "Scroll follows content unless the user scrolls up" is a testable axiom. The agent can write the test and maintain it, but the human defines the contract.
## The Shift: Reviewing Iterations → Defining Constraints
Here's what actually changes when AI writes your frontend.
The old workflow: engineer writes code, reviewer reads it, finds problems, engineer fixes them, repeat. The human is in the loop at every iteration. This doesn't scale when the agent can produce a full component rewrite in minutes. (I wrote about the constraint-first model in [[Rapid Generative Prototyping: Design in the Post-Figma Era|Rapid Generative Prototyping]] — the question here is how you *verify* the output.)
The new workflow inverts the human's role. Instead of reviewing output, you define what "correct" means *before* the agent starts. The feedback loop becomes:
**Research → Physics → Constraints → Agent Loop → Human Signs Off**
**Research** is the deep work. Figure out how browsers actually behave — not how you think they behave, not what the docs suggest, but the mechanical truth. How scroll containers interact with flex layouts. How streaming DOM mutations affect animation. Where Safari diverges from Chrome. This isn't opinion. It's physics.
**Distill into constraints.** The research produces behavioral rules the agent can follow. Not "make it scroll nicely" but "scroll follows content during streaming unless the user scrolls up." Not "handle the input well" but "input auto-resizes to content with a max height of 40% viewport." Specific, testable, falsifiable.
**Build tests from the constraints.** Each constraint maps to a Playwright assertion. The E2E suite *is* the encoded constraint set.
**The agent loops against the constraints.** It writes code, runs the suite, sees failures, rewrites. The agent doesn't need taste or judgment about what "good" looks like — it has a boundary to stay within. The dev-time browser tools (MCP screenshots, DOM inspection) give it eyes for the visual stuff the tests can't capture. But the tests are the hard floor.
**The human reviews the final feel.** Not every diff. Not every iteration. The human defined what "correct" means upstream. Now the human checks whether the result *feels* right — the experiential layer that no test captures. This is a much smaller surface than reviewing every line of every PR.
The leverage is obvious: the human's time moves from the lowest-value activity (reading diffs) to the highest-value activity (defining what good means). The research and constraint-definition work compounds — once you've established the scroll physics, every future rewrite inherits them. The agent's iterations are cheap. The human's taste is expensive. Optimize accordingly.
## The Rewrite Pattern
We're about to rewrite our chat component from scratch. Here's the sequence:
1. Build the streaming mock server
2. Write Playwright tests against the *current* broken chat — capture every known bug as a failing test
3. Rewrite the component from scratch, grounded in behavioral constraints
4. Agent uses dev-time tools to iterate until tests pass on all viewports
5. Every future change runs the full suite
The rewrite produces a component that's probably 400 lines instead of 1,200 — because we're moving markdown rendering to the server (send HTML, not raw markdown the client has to parse), using a `